
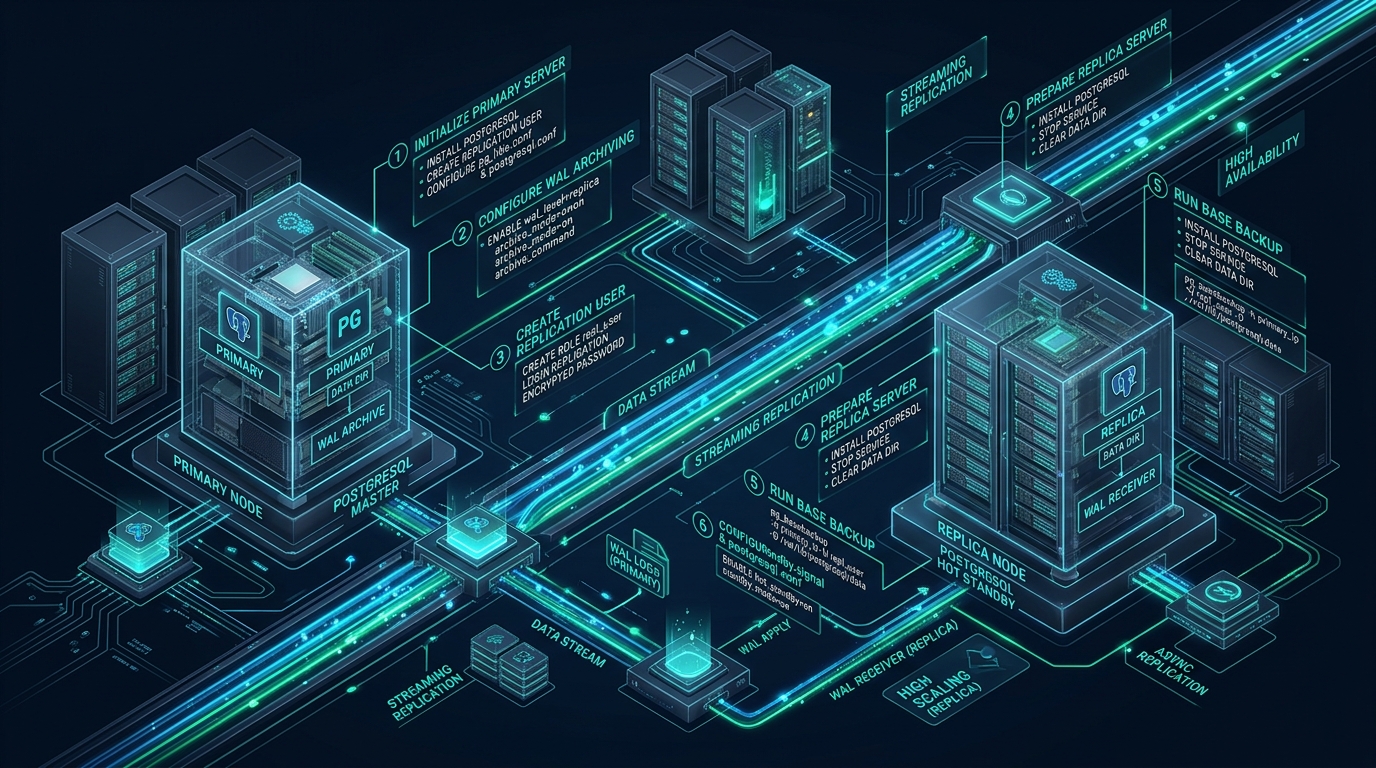
Scaling database infrastructure beyond a single compute node is a milestone every systems engineer faces when read concurrency saturates system I/O and CPU queues. In mission-critical Linux deployments, relying on a standalone database instance creates a critical single point of failure (SPOF) where unplanned hardware failure, kernel panics, or maintenance windows lead directly to catastrophic downtime. While staging environments on platforms like CpanelFree allow developers to safely prototype distributed applications, setting up enterprise-grade PostgreSQL primary-replica streaming replication is the gold standard for high availability, zero-downtime read scaling, and disaster resilience.
How PostgreSQL Streaming Replication Works
Direct Answer: PostgreSQL primary-replica streaming replication functions by continuously streaming Write-Ahead Log (WAL) records from a primary read-write node to one or more read-only standby replicas over TCP port 5432. The replica’s WAL receiver process buffers these transactions and applies them immediately to disk, providing sub-millisecond replication lag, horizontal read scaling, and near-instant failover capability.
PostgreSQL streaming replication relies on physical block-level replication using the database engine’s Write-Ahead Log (WAL). Whenever a client executes an INSERT, UPDATE, or DELETE transaction on the primary node, PostgreSQL writes the change to WAL buffers before committing the data to table heaps on disk. In streaming replication, a background process on the primary called the WAL Sender (walsender) transmits these WAL bytes over an authenticated TCP connection directly to the standby node’s WAL Receiver (walreceiver) process.
Once received by the standby replica, the Startup process reads the incoming WAL stream and applies the exact disk page modifications in memory and to storage. Because physical streaming replication operates below the SQL parser and execution layer, it synchronizes the entire database cluster byte-for-byte, including system catalogs, indices, sequences, and table structures. When configured with Hot Standby mode enabled, the replica accepts concurrent read-only queries while continuously replaying changes streamed from the primary.
Architecture Note: Physical streaming replication synchronizes the entire PostgreSQL cluster (all databases within the instance). If your workload demands selective table filtering or bidirectional writes, logical replication is required instead. However, for high availability, disaster recovery, and generic read-replica pools, physical streaming replication provides superior raw throughput, minimal CPU overhead, and automated binary integrity.
Architectural Matrix: Default vs. Tuned Production Replication
Default PostgreSQL installations out-of-the-box are deliberately tuned for minimal memory footprints and conservative system settings. Operating a high-throughput production replication cluster requires modifying Linux kernel limits, network socket buffers, and PostgreSQL concurrency handlers. The comparative matrix below outlines key differences between standard default parameters and enterprise-tuned replication architectures.
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Latency / Overhead | Baseline | Optimal |
| Replication Mechanism | File-based WAL Archiving (Delayed) | Physical Streaming Replication + Slot |
| Replication Lag (P99) | 16MB file boundaries (seconds to minutes) | < 5 ms (continuous byte stream) |
| WAL Retention Risk | WAL recycled if standby disconnects | Guaranteed retention via Replication Slots |
| Read Query Conflict Handling | Queries canceled on WAL replay conflict | Managed via max_standby_streaming_delay |
| Network TCP Keepalives | OS Default (7200s silent disconnect) | Aggressive (idle=15s, cnt=5, intvl=5s) |
| Failover RTO (Recovery Time Objective) | 15–45 minutes (manual restore) | < 10 seconds (pg_ctl promote / automated) |
Step 1: Linux Kernel and OS-Level Performance Tuning
Before launching database processes, the underlying Linux operating system must be tuned to prevent network buffer bottlenecks, out-of-memory kernel kills, and file descriptor starvation. On both the primary and replica servers (assumed Ubuntu 22.04/24.04 or Debian 12 running PostgreSQL 16), create a dedicated kernel parameters file at /etc/sysctl.d/99-postgresql.conf.
# /etc/sysctl.d/99-postgresql.conf - Production Kernel Tuning for PostgreSQL
# Virtual Memory & Memory Management
vm.swappiness = 10
vm.overcommit_memory = 2
vm.overcommit_ratio = 80
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Network TCP Socket Buffers for High-Throughput WAL Streaming
net.core.somaxconn = 4096
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216
net.ipv4.tcp_max_syn_backlog = 8192

# Fast TCP Connection Liveness & Dead Peer Detection
net.ipv4.tcp_keepalive_time = 60
net.ipv4.tcp_keepalive_intvl = 10
net.ipv4.tcp_keepalive_probes = 5

# Shared Memory and IPC
kernel.sched_migration_cost_ns = 5000000
kernel.sched_autogroup_enabled = 0
Apply the kernel configuration immediately without rebooting by executing:
sudo sysctl --systemNext, configure systemd resource limits to ensure PostgreSQL is never throttled by default system limits. Create a systemd drop-in override directory and configuration file at /etc/systemd/system/postgresql.service.d/override.conf:
# /etc/systemd/system/postgresql.service.d/override.conf
[Service]
LimitNOFILE=1048576
LimitNPROC=524288
LimitMEMLOCK=infinity
TasksMax=infinity
TimeoutSec=300
Reload the systemd daemon to register the unit changes:
sudo systemctl daemon-reloadStep 2: Configuring the Primary PostgreSQL Node
Assume our production environment has two dedicated nodes on an isolated private VPC network:
- Primary Server IP:
10.0.10.50(Hostname:pg-primary.internal) - Replica Server IP:
10.0.10.51(Hostname:pg-replica-01.internal)
1. Create the Dedicated Replication User
Log in to the primary database server as the postgres administrative user and open the psql console. Create a dedicated role granted the REPLICATION attribute with a secure, hardened password using modern scram-sha-256 authentication:
sudo -u postgres psql

-- Within PostgreSQL interactive shell:
CREATE ROLE replicator WITH REPLICATION LOGIN ENCRYPTED PASSWORD 'StrongAuthPassphraseSecure2026!';
\q
2. Configure Client Authentication (pg_hba.conf)
PostgreSQL strictly controls network access using pg_hba.conf. Open /etc/postgresql/16/main/pg_hba.conf on the primary server and add an explicit rule authorizing the replicator user to stream WAL transactions from the replica’s private IP subnet:
# /etc/postgresql/16/main/pg_hba.conf - Replication ACL Rule
# TYPE  DATABASE        USER            ADDRESS                 METHOD
host    replication     replicator      10.0.10.51/32           scram-sha-256
3. Tune Primary Engine Parameters (postgresql.conf)
Open /etc/postgresql/16/main/postgresql.conf and verify or append the following streaming replication parameters. These settings instruct PostgreSQL to retain sufficient WAL logs, bind to internal network adapters, and allocate dedicated sender worker processes:
# /etc/postgresql/16/main/postgresql.conf - Primary Replication Settings
listen_addresses = 'localhost,10.0.10.50'
port = 5432

# Write-Ahead Log Configuration
wal_level = replica                  # Minimal level required for physical streaming
max_wal_size = 16GB
min_wal_size = 2GB
checkpoint_completion_target = 0.9
checkpoint_timeout = 15min
wal_buffers = 64MB

# Streaming Replication Allocation
max_wal_senders = 10                 # Maximum concurrent walsender processes
max_replication_slots = 10           # Maximum active replication slots
wal_keep_size = 4096MB               # Retain minimum 4GB WAL on disk for lag tolerance
track_commit_timestamp = on          # Helpful for conflict detection and lag auditing

# Standby Read Feedback & Keepalives
wal_sender_timeout = 60s
tcp_keepalives_idle = 15
tcp_keepalives_interval = 5
tcp_keepalives_count = 5
Save the file and restart the PostgreSQL service on the primary node to apply the new networking and WAL allocation directives:
sudo systemctl restart postgresql
sudo systemctl status postgresql
Architecture Note: Always verify your firewall rules before proceeding. Ensure the replica node (
10.0.10.51) can communicate with the primary on TCP port5432. If using UFW, execute:sudo ufw allow from 10.0.10.51 to any port 5432 proto tcp comment 'PostgreSQL Replication'.
Step 3: Initializing and Provisioning the Standby Replica
Now switch to the secondary server (10.0.10.51). Ensure PostgreSQL 16 is installed with the exact same major and minor release as the primary. Before streaming begins, the standby database cluster directory must be cloned as a clean, consistent snapshot of the primary node.
1. Stop the PostgreSQL Service and Clear Data Directory
Stop the local PostgreSQL service on the replica and remove any automatically initialized empty database cluster files in /var/lib/postgresql/16/main:
# Stop PostgreSQL on Replica
sudo systemctl stop postgresql

# Purge default initialized data directory
sudo rm -rf /var/lib/postgresql/16/main/*
2. Perform Base Backup via pg_basebackup with Automatic Slot Creation
Execute pg_basebackup as the postgres user. We utilize modern flags: -R (write replica configuration and standby.signal), -C (create replication slot on the primary), and -S (assign a designated slot name replica_slot_1):
# Execute base backup stream from Primary node
sudo -u postgres pg_basebackup \
  -h 10.0.10.50 \
  -p 5432 \
  -U replicator \
  -D /var/lib/postgresql/16/main \
  -Fp \
  -Xs \
  -R \
  -P \
  -v \
  -C \
  -S replica_slot_1
When prompted, enter the password configured earlier (StrongAuthPassphraseSecure2026!). Alternatively, store the credentials in ~postgres/.pgpass with chmod 600 permissions to allow automated deployment.
The flags passed to pg_basebackup provide enterprise guarantees:
-D /var/lib/postgresql/16/main: Target destination directory for the base cluster clone.-Fp: Plain format (direct file copying without tar compression).-Xs: Stream Write-Ahead Logs concurrently with the backup so no separate archive pass is needed.-R: Automatically generatesstandby.signalin the data directory and writes connection parameters topostgresql.auto.conf.-C -S replica_slot_1: Automatically creates a persistent physical replication slot namedreplica_slot_1on the primary node.-P -v: Enables real-time progress indicators and verbose logging.
3. Review Generated Standby Configuration
Inspect the generated /var/lib/postgresql/16/main/postgresql.auto.conf on the replica node:
# Automatically generated by pg_basebackup
primary_conninfo = 'user=replicator password=StrongAuthPassphraseSecure2026! host=10.0.10.50 port=5432 sslmode=prefer sslcompression=0 gssencmode=prefer krbsrvname=postgres target_session_attrs=any'
primary_slot_name = 'replica_slot_1'
Verify that the trigger file standby.signal exists in the data directory:
ls -la /var/lib/postgresql/16/main/standby.signalArchitecture Note: In PostgreSQL 12 and later,
recovery.confhas been deprecated. Standby status is determined exclusively by the presence of the empty filestandby.signalin the root data directory. As long as this file is present upon startup, PostgreSQL operates in read-only recovery mode, listening for incoming WAL packets.
4. Tune Replica Hot Standby Parameters
Edit /etc/postgresql/16/main/postgresql.conf on the replica server to prevent long-running analytical queries from being prematurely killed when WAL changes conflict with existing MVCC snapshots:
# /etc/postgresql/16/main/postgresql.conf - Replica Standby Tuning
hot_standby = on
max_standby_archive_delay = 300s
max_standby_streaming_delay = 300s
hot_standby_feedback = on
wal_receiver_status_interval = 10s
wal_receiver_timeout = 60s
Ensure correct file ownership and start the PostgreSQL service on the replica:
sudo chown -R postgres:postgres /var/lib/postgresql/16/main
sudo chmod 700 /var/lib/postgresql/16/main
sudo systemctl start postgresql
sudo systemctl status postgresql
Step 4: Real-Time Replication Verification and Lag Auditing
With both nodes active, execute telemetry queries to verify that WAL streaming is active and quantify replication lag in both bytes and elapsed time.
1. Telemetry Query on Primary Node
Log in to the primary database and inspect pg_stat_replication:
sudo -u postgres psql -x -c "
SELECT
    pid,
    usename,
    application_name,
    client_addr,
    backend_start,
    state,
    sync_state,
    sync_priority,
    pg_wal_lsn_diff(pg_current_wal_lsn(), sent_lsn) AS sent_lag_bytes,
    pg_wal_lsn_diff(sent_lsn, write_lsn) AS write_lag_bytes,
    pg_wal_lsn_diff(write_lsn, flush_lsn) AS flush_lag_bytes,
    pg_wal_lsn_diff(flush_lsn, replay_lsn) AS replay_lag_bytes,
    reply_time
FROM pg_stat_replication;
"
A healthy replication stream reports state: streaming and replay_lag_bytes: 0 (or single-digit kilobytes during intense batch updates).
2. Telemetry Query on Standby Replica
On the replica node, verify the status of the WAL receiver process and check recovery mode:
sudo -u postgres psql -x -c "
SELECT
    pg_is_in_recovery() AS in_recovery,
    status,
    receive_start_lsn,
    received_lsn,
    latest_end_lsn,
    sender_host,
    sender_port,
    slot_name
FROM pg_stat_wal_receiver;
"
The query must return in_recovery: t and status: streaming, confirming the standby is operating as an active Hot Standby replica.
Step 5: Failover and Manual Standby Promotion
In a disaster recovery scenario where the primary node experiences unrecoverable hardware failure or power outage, the standby node can be promoted to become the new read-write primary in seconds.
To promote the replica node immediately, run:
# Method A: Using pg_ctl (preferred for immediate execution)
sudo -u postgres pg_ctlcluster 16 main promote

# Method B: Using SQL command directly inside psql
sudo -u postgres psql -c "SELECT pg_promote();"
Upon promotion, PostgreSQL deletes the standby.signal file, completes replaying any buffered WAL segments, switches the timeline from timeline 1 to timeline 2, and opens the database for read-write transactions. Verify the change by checking SELECT pg_is_in_recovery();, which will now return f (false).
For production databases processing financial transactions, e-commerce storefronts, or high-throughput API endpoints where sub-millisecond NVMe I/O is non-negotiable, hosting your PostgreSQL cluster on MeraHost Enterprise Cloud guarantees dedicated NVMe storage tiers, predictable latency, and predictable pricing with zero renewal price hikes.
Frequently Asked Questions
What is the difference between physical streaming replication and logical replication?
Physical streaming replication duplicates the entire database cluster byte-for-byte at the storage block level using Write-Ahead Logs (WAL). It replicates all databases, tables, indices, schemas, and catalogs identically with minimal CPU overhead. Logical replication, introduced in PostgreSQL 10, operates at the SQL row level on a per-table publication/subscription basis, allowing selective replication, data transformation, and cross-major-version migrations, but requires significantly higher CPU and decoding overhead.
Why are replication slots necessary, and what operational risk do they introduce?
Replication slots guarantee that the primary node will never recycle or purge WAL segments from disk until the connected standby replica has confirmed receipt and application. This prevents the dreaded “requested WAL segment has already been removed” failure if a replica goes offline for hours. However, if an offline standby is neglected and a slot remains abandoned, the primary will continue accumulating WAL files until disk space is 100% exhausted. Always configure max_slot_wal_keep_size (e.g., 32GB) to protect the primary from out-of-disk crashes.
Can a PostgreSQL standby replica handle write operations or create temporary tables?
No. A standby replica in Hot Standby mode is strictly read-only. Any attempt to execute INSERT, UPDATE, DELETE, or DDL operations like CREATE TABLE will trigger a read-only transaction error (ERROR: cannot execute INSERT in a read-only transaction). Furthermore, standbys cannot create temporary tables unless wal_level is configured appropriately and read-write session states are prohibited. All writes must target the primary node directly.
How do I resolve “canceling statement due to conflict with recovery” errors on the replica?
When a replica executes a long-running read query on a table that is simultaneously being vacuumed or modified by incoming WAL replay from the primary, PostgreSQL must choose between delaying recovery or canceling the read query. To eliminate query cancellations, enable hot_standby_feedback = on on the replica (which signals the primary not to clean up dead tuples still needed by the standby’s active queries) and increase max_standby_streaming_delay = 300s.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).