
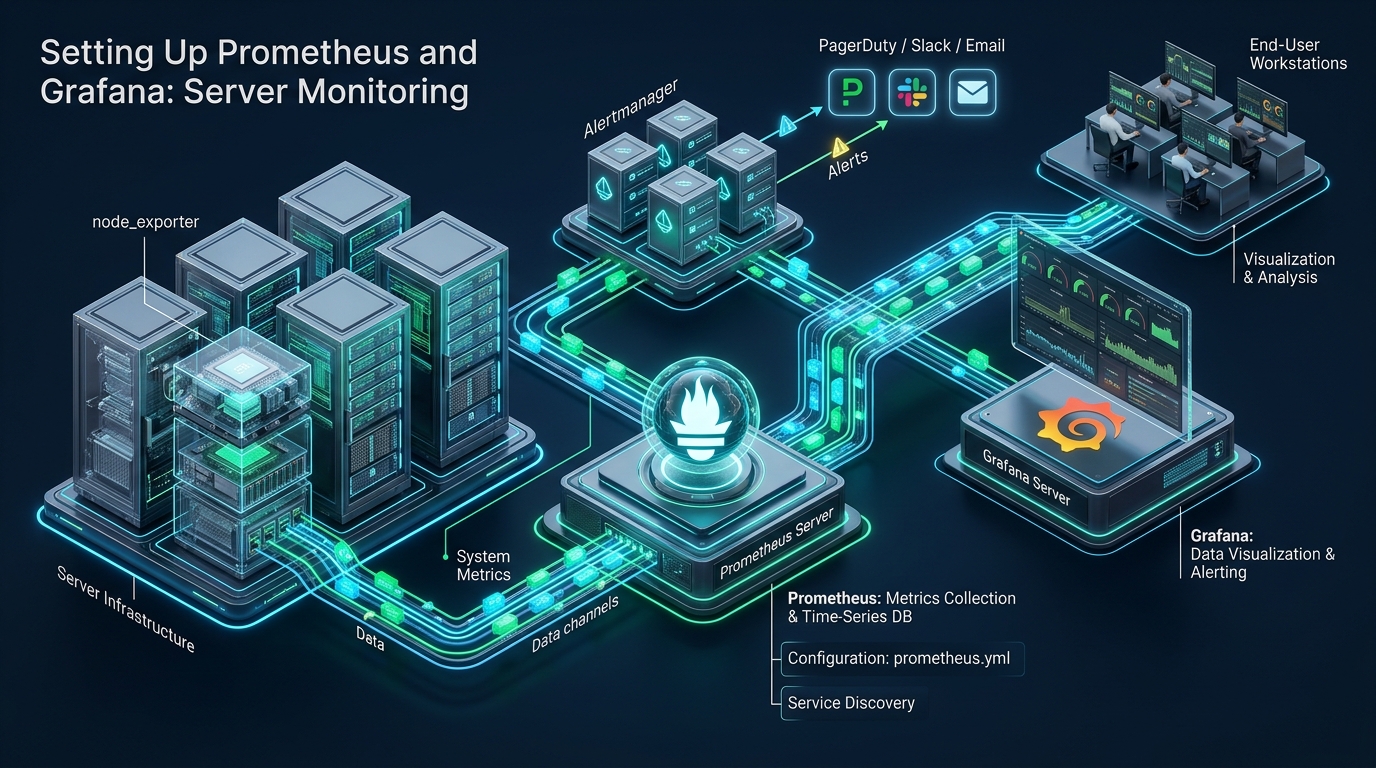
Operating enterprise Linux fleets without high-fidelity observability turns minor kernel page cache bottlenecks and transient I/O saturation into catastrophic system downtime. Whether staging container workloads on CpanelFree or managing multi-node bare-metal infrastructure, relying on passive logs or intermittent polling fails to capture sub-second operational anomalies. Implementing a dedicated pull-based Prometheus time-series database coupled with dynamic Grafana dashboards establishes immutable telemetry and real-time visibility across CPU, memory, filesystem, and network sub-systems.
What Is the Prometheus and Grafana Monitoring Stack?
Quick Summary: A Prometheus and Grafana server monitoring setup pairs Prometheus—an open-source time-series database utilizing a pull-based HTTP scrape architecture—with Node Exporter for Linux kernel metrics and Grafana for real-time visualization. This decoupled architecture ingests raw host telemetry, evaluates PromQL threshold rules, and delivers actionable alerts with minimal system overhead.
In modern systems administration, infrastructure observability is divided into three distinct pillars: metrics, logs, and traces. While logs provide post-mortem context, time-series metrics deliver proactive state verification. The combination of Prometheus, Node Exporter, and Grafana represents the gold standard for metric-driven monitoring due to its operational simplicity, pull-based scrape model, and multi-dimensional data model identified by metric names and key-value label pairs.
Core Architecture Components
- Prometheus Server: Acts as the scraping engine, TSDB (Time Series Database) storage engine, and query processing hub via PromQL. It periodically pulls HTTP endpoints exposed by target exporters.
- Node Exporter: A lightweight binary written in Go that runs as a system daemon on target Linux hosts, collecting kernel statistics from
/procand/sys. - Alertmanager: Handles alerts emitted by Prometheus, deduping, grouping, and routing notifications to channels like PagerDuty, Slack, or webhook endpoints.
- Grafana: The presentation layer that queries Prometheus via PromQL and converts multi-dimensional matrices into dynamic visual panels, heatmaps, and executive dashboards.
Architecture Note: Unlike push-based agents (e.g., traditional Zabbix or legacy Graphite) that bombard monitoring hosts with unthrottled packets, Prometheus controls collection cadence through scheduled pull cycles. If an edge node experiences network degradation or CPU starvation, the central Prometheus server regulates its own scrape rate, preventing cascading ingestion collapse.
Production vs Default Architecture Benchmarks
Deploying Prometheus and Grafana using stock repository configurations often leads to runaway disk space consumption, excessive kernel context switching from extraneous collectors, and memory exhaustion during large query evaluations. Tuning TSDB retention flags, memory bounds, and collector parameters achieves maximum efficiency.
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Scrape Interval & Resolution | 15s uniform scrape interval | Tiered (15s core / 60s storage & low priority) |
| TSDB Retention Strategy | 15 days, unconstrained disk size | 30d time cap + 85% storage volume max-bytes cap |
| Prometheus Memory Footprint | Unbounded heap allocation | GOMEMLIMIT capped at 80% RAM + memory limits |
| Node Exporter Collector Overhead | All collectors enabled (ARP, bcache, infiniband) | Filtered collectors, <0.8% single core overhead |
| Alert Evaluation Latency | Unscheduled polling / 1m jitter | Strict 15s evaluation cycle with duration timers |
| Grafana Query Caching | Direct TSDB query pass-through | Query caching + recorded rule series |
Step 1: Installing and Hardening Node Exporter on Target Hosts
To extract granular hardware and operating system metrics from Linux hosts, Node Exporter must run as an isolated, unprivileged system daemon. Running monitoring agents under root creates an unnecessary security vector. We isolate Node Exporter into its own dedicated system user without shell access.
Download the latest stable Node Exporter release from the official Prometheus repositories and install the binary into /usr/local/bin/:
# Create unprivileged system service user
sudo useradd --no-create-home --shell /bin/false node_exporter

# Download and unpack official binary
NODE_VERSION="1.8.2"
cd /tmp
curl -LO "https://github.com/prometheus/node_exporter/releases/download/v${NODE_VERSION}/node_exporter-${NODE_VERSION}.linux-amd64.tar.gz"
tar -xvf "node_exporter-${NODE_VERSION}.linux-amd64.tar.gz"
sudo cp "node_exporter-${NODE_VERSION}.linux-amd64/node_exporter" /usr/local/bin/
sudo chown node_exporter:node_exporter /usr/local/bin/node_exporter
rm -rf node_exporter*
Next, define a hardened systemd unit file at /etc/systemd/system/node_exporter.service. In production, disable noisy or unneeded collectors (such as bcache, fibrechannel, infiniband, and xfs) to preserve kernel cycles and prevent metric explosion.
[Unit]
Description=Node Exporter Hardware and OS Metrics Daemon
Documentation=https://prometheus.io/docs/guides/node-exporter/
After=network.target

[Service]
User=node_exporter
Group=node_exporter
Type=simple
ExecStart=/usr/local/bin/node_exporter \
  --collector.disable-defaults \
  --collector.cpu \
  --collector.diskstats \
  --collector.filesystem \
  --collector.loadavg \
  --collector.meminfo \
  --collector.netdev \
  --collector.stat \
  --collector.time \
  --collector.uname \
  --collector.vmstat \
  --collector.filesystem.mount-points-exclude="^/(sys|proc|dev|host|etc)($|/)" \
  --web.listen-address="0.0.0.0:9100"

# Security Hardening Flags
ProtectSystem=strict
ProtectHome=true
NoNewPrivileges=true
PrivateTmp=true
ProtectKernelTunables=true
ProtectControlGroups=true
CapabilityBoundingSet=

Restart=always
RestartSec=5s

[Install]
WantedBy=multi-user.target
Enable and start the service, then verify that the raw metrics endpoint is serving data:
sudo systemctl daemon-reload
sudo systemctl enable --now node_exporter
curl -s http://localhost:9100/metrics | head -n 20
Security Hardening: Never expose port 9100 directly to the public internet without mutual TLS (mTLS) or network firewall isolation. Restrict inbound traffic on port 9100 via
iptables,nftables, or cloud security groups strictly to the IP address of your central Prometheus server.
Step 2: Installing and Configuring Prometheus Core
The Prometheus core server handles metric ingestion, TSDB chunk storage, and evaluation loops. Create a dedicated user, establish required directory hierarchies, and assign restrictive ownership permissions.
# Create unprivileged system user and directories
sudo useradd --no-create-home --shell /bin/false prometheus
sudo mkdir -p /etc/prometheus /etc/prometheus/rules /var/lib/prometheus

# Download and install Prometheus binary
PROM_VERSION="2.54.1"
cd /tmp
curl -LO "https://github.com/prometheus/prometheus/releases/download/v${PROM_VERSION}/prometheus-${PROM_VERSION}.linux-amd64.tar.gz"
tar -xvf "prometheus-${PROM_VERSION}.linux-amd64.tar.gz"
cd "prometheus-${PROM_VERSION}.linux-amd64"
sudo cp prometheus promtool /usr/local/bin/
sudo cp -r consoles console_libraries /etc/prometheus/
sudo chown -R prometheus:prometheus /etc/prometheus /var/lib/prometheus
sudo chown prometheus:prometheus /usr/local/bin/prometheus /usr/local/bin/promtool
rm -rf /tmp/prometheus*
Production Prometheus Configuration (`/etc/prometheus/prometheus.yml`)
The primary configuration file governs scrape intervals, rule evaluation intervals, alerting rules, and scrape targets. Create /etc/prometheus/prometheus.yml with the following production-hardened specification:
global:
  scrape_interval: 15s
  evaluation_interval: 15s
  scrape_timeout: 10s
  external_labels:
    cluster: 'production-primary'
    datacenter: 'in-west-01'

rule_files:
  - "/etc/prometheus/rules/*.yml"

alerting:
  alertmanagers:
    - static_configs:
        - targets:
            - '127.0.0.1:9093'

scrape_configs:
  # Internal Prometheus self-monitoring
  - job_name: 'prometheus'
    metrics_path: '/metrics'
    static_configs:
      - targets: ['127.0.0.1:9090']

  # Fleet Linux Nodes (Node Exporter)
  - job_name: 'node_exporter'
    scrape_interval: 15s
    static_configs:
      - targets:
          - '127.0.0.1:9100'
          - '10.0.1.15:9100'
          - '10.0.1.16:9100'
    relabel_configs:
      - source_labels: [__address__]
        regex: '(.*):9100'
        target_label: instance
        replacement: '${1}'
Systemd Service Unit with Memory Sandboxing
To prevent Prometheus from triggering the Linux Out-Of-Memory (OOM) killer during heavy range queries, tune Go runtime memory allocation with GOMEMLIMIT and enforce systemd resource limits at /etc/systemd/system/prometheus.service:
[Unit]
Description=Prometheus Time Series Monitoring Engine
Documentation=https://prometheus.io/docs/introduction/overview/
After=network.target

[Service]
User=prometheus
Group=prometheus
Type=simple
Environment="GOMEMLIMIT=3200MiB"
ExecStart=/usr/local/bin/prometheus \
  --config.file=/etc/prometheus/prometheus.yml \
  --storage.tsdb.path=/var/lib/prometheus \
  --storage.tsdb.retention.time=30d \
  --storage.tsdb.retention.size=40GB \
  --storage.tsdb.min-block-duration=2h \
  --storage.tsdb.max-block-duration=2h \
  --web.listen-address="127.0.0.1:9090" \
  --web.enable-lifecycle

# Sandboxing and Kernel Protection
ProtectSystem=full
ProtectHome=true
NoNewPrivileges=true
LimitNOFILE=65536
MemoryMax=4G
Restart=on-failure
RestartSec=5s

[Install]
WantedBy=multi-user.target
Validate the configuration syntax using promtool before starting the daemon:
sudo promtool check config /etc/prometheus/prometheus.yml
sudo systemctl daemon-reload
sudo systemctl enable --now prometheus
sudo systemctl status prometheus
Step 3: Defining Production PromQL Alerting Rules
Monitoring without alerting requires constant human screen inspection. Write actionable alerting rules in /etc/prometheus/rules/host_alerts.yml to catch resource saturation before kernel deadlocks manifest:
groups:
  - name: host_saturation_alerts
    rules:
      - alert: HostHighCpuLoad
        expr: (100 - (avg by (instance) (rate(node_cpu_seconds_total{mode="idle"}[5m])) * 100)) > 85
        for: 5m
        labels:
          severity: critical
        annotations:
          summary: "High CPU load detected on instance {{ $labels.instance }}"
          description: "CPU utilization has exceeded 85% for more than 5 minutes (current value: {{ $value | printf "%.2f" }}%)."

      - alert: HostOutOfMemory
        expr: ((node_memory_MemAvailable_bytes / node_memory_MemTotal_bytes) * 100) < 10
        for: 3m
        labels:
          severity: critical
        annotations:
          summary: "Host out of memory on {{ $labels.instance }}"
          description: "Node memory available is below 10% (current: {{ $value | printf "%.2f" }}%)."

      - alert: HostDiskFillingUp
        expr: (node_filesystem_free_bytes{mountpoint="/"}/node_filesystem_size_bytes{mountpoint="/"} * 100) < 15
        for: 10m
        labels:
          severity: warning
        annotations:
          summary: "Root filesystem running out of disk space on {{ $labels.instance }}"
          description: "Root partition free space is below 15% (current: {{ $value | printf "%.2f" }}%)."
Validate the rule syntax using promtool check rules /etc/prometheus/rules/host_alerts.yml and trigger a live Prometheus configuration reload via HTTP: curl -X POST http://127.0.0.1:9090/-/reload.
Step 4: Installing and Securing Grafana
Grafana transforms raw time-series data into actionable dashboards. For enterprise Linux deployments (Ubuntu/Debian or RHEL/Rocky Linux), install Grafana from the official package repository to maintain seamless security patch updates.
# Install Grafana APT repository and key (Debian/Ubuntu)
sudo apt-get install -y apt-transport-https software-properties-common wget
sudo mkdir -p /etc/apt/keyrings/
wget -q -O - https://apt.grafana.com/gpg.key | gpg --dearmor | sudo tee /etc/apt/keyrings/grafana.gpg > /dev/null
echo "deb [signed-by=/etc/apt/keyrings/grafana.gpg] https://apt.grafana.com stable main" | sudo tee -a /etc/apt/sources.list.d/grafana.list

sudo apt-get update
sudo apt-get install -y grafana
sudo systemctl daemon-reload
sudo systemctl enable --now grafana-server
Production Grafana Hardening (`/etc/grafana/grafana.ini`)
By default, Grafana binds to 0.0.0.0:3000 and allows user registration. Modify /etc/grafana/grafana.ini to bind exclusively to localhost (serving traffic behind an NGINX reverse proxy with TLS), disable open registration, and enforce secure cookies:
[server]
http_addr = 127.0.0.1
http_port = 3000
domain = monitor.yourdomain.com
root_url = https://monitor.yourdomain.com/
enforce_domain = true

[security]
admin_user = sysadmin
cookie_secure = true
disable_gravatar = true
hide_version = true

[users]
allow_sign_up = false
auto_assign_org_role = Viewer

[analytics]
reporting_enabled = false
check_for_updates = false
Restart Grafana to enforce the security posture: sudo systemctl restart grafana-server.
Automating Prometheus as a Grafana Data Source via Provisioning
Eliminate manual GUI clicks by configuring declarative provisioning. Create /etc/grafana/provisioning/datasources/prometheus.yaml:
apiVersion: 1

datasources:
  - name: Prometheus
    type: prometheus
    access: proxy
    url: http://127.0.0.1:9090
    isDefault: true
    jsonData:
      timeInterval: 15s
      httpMethod: POST
    editable: false
Upon restarting Grafana, the Prometheus data source connects automatically and is ready to power pre-built community dashboards such as the renowned Node Exporter Full (Dashboard ID: 1860).
Step 5: Production Operational Checklist & Infrastructure Sizing
Observability infrastructure requires deliberate capacity planning. As your monitored fleet grows from 5 to 500 nodes, write traffic to the Prometheus TSDB scales linearly with active time series.
- TSDB Disk Sizing Formula:
Disk Required = (Scrapes/sec) × (Retention in Seconds) × (Bytes/Sample). Prometheus averages 1.3 to 2 bytes per sample due to Gorilla compression. At 10,000 samples/sec with 30-day retention, allocate at least 45GB of dedicated NVMe storage. - Filesystem Tuning: Mount the TSDB storage directory on an
ext4orXFSfilesystem formatted withnoatimeto eliminate redundant write overhead for every head-block read. - Continuous Backup: Enable the Prometheus lifecycle API (
--web.enable-lifecycle) and take transactional snapshots viacurl -X POST http://localhost:9090/api/v1/snapshotbefore performing kernel upgrades.
For mission-critical production systems that cannot afford observability downtime, hosting your monitoring tier and application clusters on MeraHost Enterprise Cloud guarantees dedicated Enterprise NVMe disk I/O, unmetered network bandwidth, and hardened LiteSpeed acceleration with predictable pricing.
Frequently Asked Questions
How much disk space and RAM does Prometheus require in production?
For a typical infrastructure with 10 to 50 Linux servers scraping 1,000 metrics per host at 15-second intervals, Prometheus requires approximately 4 GB to 8 GB of RAM and 40 GB to 80 GB of fast NVMe storage for a 30-day retention window. RAM consumption is primarily driven by active series in the TSDB Head block and query complexity.
Why use Prometheus pull architecture instead of push-based agents like Telegraf or Zabbix?
The pull architecture ensures that the central monitoring server controls the ingestion rate and network socket allocation. If target systems experience resource spikes or high latency, Prometheus prevents network saturation. Furthermore, pull architectures make health detection immediate: if an HTTP scrape target fails to respond, Prometheus immediately records an up == 0 metric.
Can Prometheus and Grafana be installed on the same server?
Yes, for small to medium environments (under 100 monitored nodes), hosting Prometheus and Grafana on the same dedicated virtual or physical server is common and cost-effective. However, strict memory boundaries (via systemd MemoryMax and GOMEMLIMIT) must be configured to ensure a large Grafana dashboard query does not trigger the OOM killer on the Prometheus TSDB process.
How do I secure Node Exporter metrics from unauthorized access?
You should never expose port 9100 publicly. Secure Node Exporter by binding it to a private internal network interface (e.g., WireGuard, Tailscale, or VPC subnet), enforcing host firewall rules (iptables/ufw) to permit traffic only from the Prometheus server IP, or implementing basic authentication and TLS using Node Exporter web configuration files.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).