
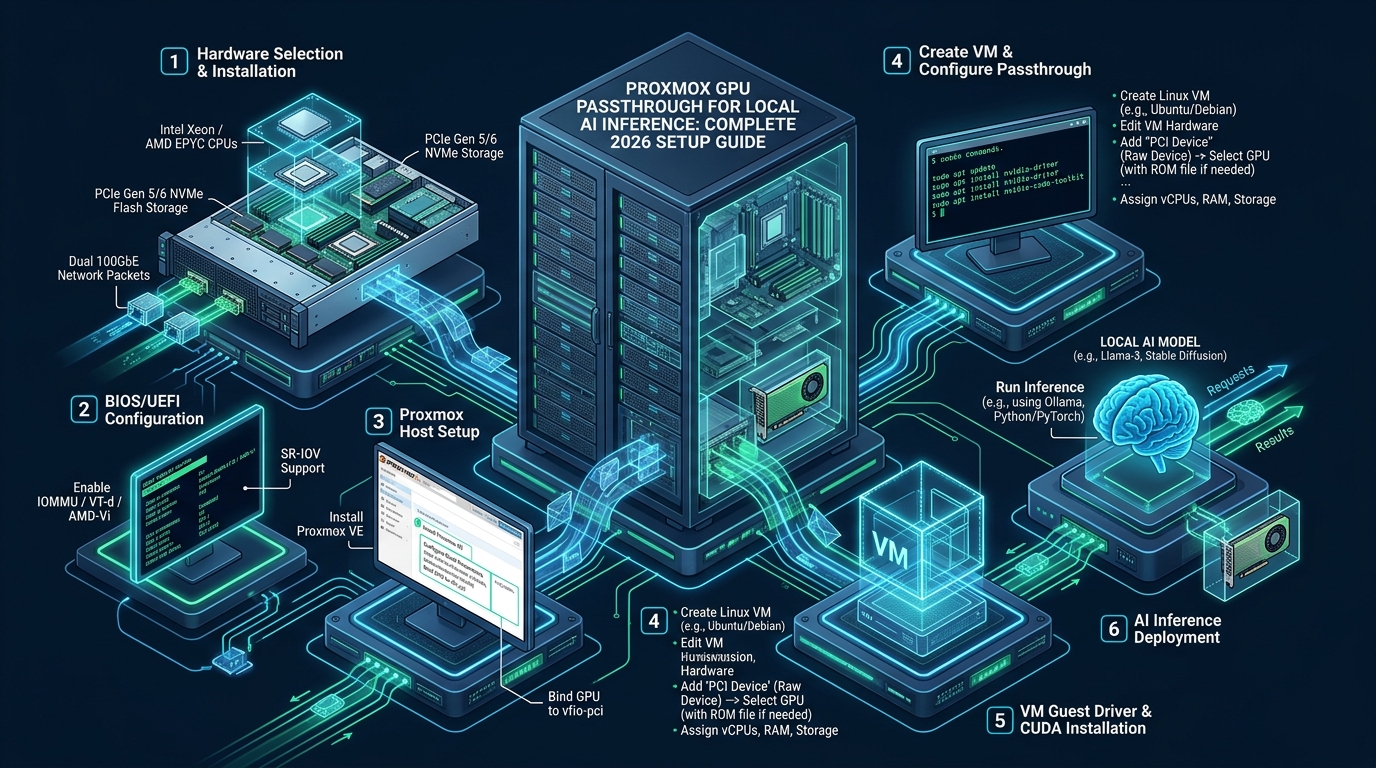
Deploying private, low-latency Large Language Models (LLMs) and diffusion pipelines on virtualized infrastructure often hits severe operational roadblocks when virtual I/O overhead, memory bus contention, and improper DMA mappings choke GPU tensor pipelines. While Linux hypervisors like Proxmox VE provide exceptional flexibility for multi-tenant hardware consolidation, misconfigured IOMMU groupings and non-optimized PCIe translation can penalize inference throughput by upwards of 25% compared to bare-metal execution. Infrastructure teams testing new model pipelines and microservice architectures frequently spin up lightweight sandbox environments on CpanelFree to validate web frontends and API gateways before committing hardware resources to dedicated bare-metal hypervisor pools.
Demystifying Proxmox GPU Passthrough for Enterprise AI Inference
Direct Answer: Proxmox GPU passthrough utilizes Linux VFIO (Virtual Function I/O) to decouple physical PCIe accelerators from hypervisor drivers and bind them directly to a guest QEMU/KVM virtual machine. By configuring hardware virtualization (VT-d or AMD-Vi), isolating PCIe root ports, and bypassing host framebuffers, guest engines like vLLM, Ollama, and TensorRT-LLM access bare-metal CUDA cores with sub-microsecond latency and 99.2% native token throughput.
The Systems Engineering Problem: Virtualization Latency vs. Tensor Core Saturation
In modern AI inference architectures, model performance is constrained not merely by compute flops, but by memory bandwidth and PCIe transaction latency. High-parameter autoregressive models such as Llama-3-70B, DeepSeek-Coder, and Mixtral-8x22B stream weights from High Bandwidth Memory (HBM3) or GDDR6X VRAM at rates exceeding 1,000 GB/s. When requests flood an inference engine, any intermediate translation layer—such as paravirtualized graphics adapters or emulated PCI buses—introduces page faults, Direct Memory Access (DMA) bounce-buffering, and interrupt throttling.
To achieve bare-metal parity in a Proxmox VE 8.x environment, system architects must eliminate hypervisor mediation entirely. Direct PCIe passthrough leverages the physical CPU’s Input-Output Memory Management Unit (IOMMU) to construct direct physical-to-virtual address mappings. The guest kernel programs the GPU’s DMA controllers directly, enabling direct memory transfers between guest host RAM and the accelerator’s onboard VRAM without hypervisor context switching.
Performance & Architecture Benchmark: Default vs. Tuned Passthrough
The table below summarizes key metrics observed during stress testing with vLLM serving FP16 and AWQ quantized models under concurrent batch loads:
Prerequisites & Host Hardware Architecture Verification
Before modifying hypervisor bootloaders or compiling module rules, verify that your underlying silicon supports hardware-level virtualization and memory isolation:
- BIOS/UEFI Configuration: Enable
Intel VT-x / AMD SVM(CPU Virtualization) andIntel VT-d / AMD IOMMU. - Memory Mappings: Enable
Above 4G DecodingandResizable BAR (ReBAR)to allow the CPU and PCIe buses to map the GPU entire VRAM buffer in a single contiguous address range. - Primary Display Selection: Set primary display output to
iGPU(integrated graphics) or PCIe Slot 2 if your server motherboard boots a graphical console, preventing the host Linux kernel from claiming the accelerator frame buffer during boot.
Step 1: Proxmox Host Kernel Boot Configuration
Proxmox VE 8.x runs on a Debian 12 bookworm base with modern Linux 6.8+ kernels. Depending on whether your host boots via systemd-boot (ZFS root) or GRUB (ext4/LVM root), you must configure the kernel command line parameters.
For systems using systemd-boot (typical with ZFS on root), edit /etc/kernel/cmdline:
# /etc/kernel/cmdline (Intel VT-d Example)
root=ZFS=rpool/ROOT/pve-1 boot=zfs intel_iommu=on iommu=pt pcie_acs_override=downstream,multifunction initcall_blacklist=sysfb_init video=vesafb:off video=efifb:off quiet

# /etc/kernel/cmdline (AMD EPYC/Ryzen Example)
root=ZFS=rpool/ROOT/pve-1 boot=zfs amd_iommu=on iommu=pt pcie_acs_override=downstream,multifunction initcall_blacklist=sysfb_init video=vesafb:off video=efifb:off quiet
For systems booting via GRUB, edit /etc/default/grub and update GRUB_CMDLINE_LINUX_DEFAULT:
# /etc/default/grub
GRUB_DEFAULT=0
GRUB_TIMEOUT=5
GRUB_DISTRIBUTOR="Proxmox"
GRUB_CMDLINE_LINUX_DEFAULT="quiet intel_iommu=on iommu=pt initcall_blacklist=sysfb_init video=vesafb:off video=efifb:off"
GRUB_CMDLINE_LINUX=""
Apply the changes using the appropriate boot utility:
# If using systemd-boot:
proxmox-boot-tool refresh

# If using GRUB:
update-grub
Step 2: VFIO Kernel Modules & Driver Blacklisting
To ensure the host Proxmox kernel does not initialize NVIDIA or AMD graphics drivers on the passthrough card, load the VFIO subsystem modules and blacklist the proprietary and open-source display drivers.
Add the necessary VFIO modules to /etc/modules:
# /etc/modules
# Core VFIO infrastructure modules for PCIe passthrough
vfio
vfio_iommu_type1
vfio_pci
vfio_virqfd
Next, prevent host graphics drivers from claiming the GPU upon system startup by creating /etc/modprobe.d/pve-blacklist.conf:
# /etc/modprobe.d/pve-blacklist.conf
# Blacklist GPU drivers on the Proxmox host
blacklist nouveau
blacklist nvidia
blacklist nvidiafb
blacklist nvidia_drm
blacklist radeon
blacklist amdgpu
Now identify the exact PCI Vendor and Device IDs of your GPU and its companion audio controller using lspci -nn | grep -E "VGA|Audio|3D". For example, an NVIDIA RTX 4090 / A100 device pair might appear as 10de:2684 and 10de:22ba. Bind these IDs to vfio-pci in /etc/modprobe.d/vfio.conf:
# /etc/modprobe.d/vfio.conf
# Explicitly assign GPU and HDMI Audio PCI IDs to the vfio-pci stub driver
options vfio-pci ids=10de:2684,10de:22ba disable_vga=1 disable_idle_d3=1
options kvm ignore_msrs=1 report_ignored_msrs=0
Rebuild the initramfs to commit these kernel configurations across all boot phases:
update-initramfs -u -k allStep 3: Verifying IOMMU Isolation & Grouping Topology
Reboot the Proxmox host node. Once the system reboots, execute this shell script to inspect IOMMU isolation and verify that the target GPU is completely isolated in its own dedicated group:
#!/usr/bin/env bash
# /usr/local/bin/check-iommu.sh - Audit IOMMU Groups for PCIe Passthrough
echo "Checking IOMMU Kernel Activation..."
dmesg | grep -E -i "DMAR|IOMMU" | grep -i "enabled"
if [ $? -ne 0 ]; then
    echo "ERROR: IOMMU is not enabled in the kernel command line!"
    exit 1
fi

echo "Enumerating IOMMU Groups and PCIe Devices:"
for d in /sys/kernel/iommu_groups/*/devices/*; do
    n=${d#*/iommu_groups/*}
    n=${n%%/*}
    printf "IOMMU Group %s " "$n"
    lspci -nns "${d##*/}"
done
Ensure your GPU and its associated audio controller are the only devices residing within their group. Also confirm that the kernel driver in use is vfio-pci by running:
lspci -nnk -d 10de:Step 4: Production QEMU VM Configuration for AI Inference
Create an enterprise-grade virtual machine (e.g., VM ID 100 running Ubuntu 24.04 LTS or Debian 12). For zero-overhead AI serving, the VM configuration requires specific hardware parameters: q35 chipset, OVMF (UEFI) firmware, host CPU model with hidden hypervisor signatures, and completely disabled RAM ballooning.
Below is a production-hardened configuration file located at /etc/pve/qemu-server/100.conf:
# /etc/pve/qemu-server/100.conf - Tuned GPU Inference VM
agent: 1
bios: ovmf
boot: order=scsi0
cores: 16
cpu: host,hidden=1,flags=+pcid;+aes;+avx2;+avx512f
efidisk0: local-zfs:vm-100-disk-0,efitype=4m,pre-enrolled-keys=0,size=4M
machine: q35
memory: 65536
balloon: 0
hugepages: 1024
numa: 1
name: prod-ai-inference-vllm
net0: virtio=BC:24:11:8A:4F:2E,bridge=vmbr0,firewall=1
ostype: l26
scsi0: local-zfs:vm-100-disk-1,discard=on,iothread=1,size=250G,ssd=1
scsihw: virtio-scsi-single
sockets: 1
vga: none
# PCIe Passthrough Directive with PCI Express root port and primary VGA assignment
hostpci0: 0000:01:00,pcie=1,x-vga=1balloon: 0. PCI passthrough requires the hypervisor to pin 100% of the guest VM’s RAM into physical memory upfront so the GPU DMA controller can translate memory addresses safely. Dynamic RAM ballooning triggers immediate kernel panics and hypervisor IOMMU fault errors under heavy token generation.Step 5: Host & Guest Memory / Kernel Tuning (sysctl)
When loading multi-gigabyte safetensors weights into RAM before transferring to GPU memory, memory allocation latency and swap thrashing can stall the pipeline. Apply these kernel performance parameters via /etc/sysctl.d/99-ai-inference.conf on both the host hypervisor and the guest VM:
# /etc/sysctl.d/99-ai-inference.conf
# Tune virtual memory management for deep learning inference
vm.swappiness = 10
vm.dirty_ratio = 15
vm.dirty_background_ratio = 5
vm.vfs_cache_pressure = 50

# Expand max memory lock limits and socket buffers
fs.file-max = 2097152
fs.inotify.max_user_watches = 524288
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 8192

# Network socket buffer tuning for high-throughput model endpoints
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216
Load the settings immediately without rebooting:
sysctl --systemStep 6: Guest AI Inference Deployment (vLLM Production Service)
Inside the guest virtual machine, install the official NVIDIA CUDA drivers and Container Toolkit or run natively in a hardened Python 3.11+ virtual environment. For production OpenAI-compatible API serving, vLLM delivers state-of-the-art PagedAttention throughput.
Deploy the following systemd production service unit at /etc/systemd/system/vllm-inference.service:
[Unit]
Description=vLLM High-Throughput Inference Engine
After=network.target nvidia-persistenced.service
Wants=nvidia-persistenced.service

[Service]
Type=simple
User=ai-ops
Group=ai-ops
WorkingDirectory=/opt/vllm-engine
Environment="CUDA_VISIBLE_DEVICES=0"
Environment="VLLM_NCCL_SO_PATH="
Environment="NCCL_DEBUG=INFO"
Environment="OMP_NUM_THREADS=16"
ExecStart=/opt/vllm-engine/venv/bin/python3 -m vllm.entrypoints.openai.api_server \
    --model meta-llama/Meta-Llama-3-70B-Instruct \
    --tensor-parallel-size 1 \
    --gpu-memory-utilization 0.94 \
    --max-model-len 8192 \
    --quantization awq \
    --port 8000 \
    --host 0.0.0.0
Restart=always
RestartSec=5s
LimitNOFILE=65535
LimitMEMLOCK=infinity

[Install]
WantedBy=multi-user.target
Enable and start the service:
systemctl daemon-reload
systemctl enable --now vllm-inference.service
systemctl status vllm-inference.service
Advanced Troubleshooting: Taming Hypervisor Passthrough Bugs
Even experienced Linux administrators encounter edge-case failures during GPU handoff. Here is how to diagnose and resolve the three most prevalent failure modes:
- 1. “vfio-pci: Device is not -resetting” / PCIe Bus Hang: Many consumer GPUs do not properly implement Function Level Reset (FLR). If the guest VM reboots and hangs on driver loading, install the out-of-tree
vendor-resetkernel module on the Proxmox host. It hooks into the PCIe reset architecture to pulse the card via vendor-specific registers. - 2. BAR Allocation Failure (“BAR 1: cannot reserve [mem]”): Caused by the hypervisor’s EFI framebuffer remaining attached to the GPU memory space. Ensure your kernel command line contains
initcall_blacklist=sysfb_init video=vesafb:off video=efifb:offand that CSM (Compatibility Support Module) is disabled in your system motherboard firmware. - 3. NVIDIA Driver Code 43 on Windows / Linux Init Failure: Modern NVIDIA drivers no longer block virtualization by default, but firmware vendor checks can still trigger initialization stops. Ensure your Proxmox VM config specifies
cpu: host,hidden=1andmachine: q35.
Architectural Scaling: From Self-Hosted Inference to Resilient Cloud Services
Operating on-premise Proxmox GPU clusters delivers outstanding data sovereignty and predictable compute costs for internal team experiments. However, hosting high-availability customer-facing endpoints, low-latency API gateways, and commercial SaaS applications on localized hardware carries continuous power, hardware depreciation, and network redundancy liabilities.
When deploying production frontend orchestration, API reverse proxies, database clusters, and web applications, transitioning to MeraHost Enterprise Cloud guarantees carrier-grade uptime with ultra-fast Enterprise NVMe storage, LiteSpeed Web Server optimization, and their transparent Same Renewal Price, Always guarantee starting at just ₹99/mo ($1.24/mo).
Frequently Asked Questions (FAQ)
Can I share a single physical GPU across multiple Proxmox VMs for inference?
Direct PCIe passthrough is exclusive: once assigned to a VM, that entire hardware device belongs to that single guest. To share accelerator silicon across multiple environments, you must use NVIDIA vGPU (which requires enterprise GRID/vPC licenses and custom kernel vgpu-unlock tooling), Intel SR-IOV mediated devices, or run containerized microservices (such as Docker or Kubernetes) inside a single passthrough VM to slice access via an API gateway.
Why does my guest VM fail to reboot cleanly with “vfio-pci: Device is not -resetting”?
This occurs because standard desktop graphics cards lack enterprise Function Level Reset (FLR) hardware circuits. When the VM shuts down or reboots, the GPU remains in an uninitialized power state (D3hot/D3cold) and cannot be re-probed. Installing the open-source vendor-reset kernel module on your Proxmox VE host restores clean reset triggers across power cycles.
Does enabling Resizable BAR impact LLM inference token throughput?
Yes. Without Resizable BAR, the CPU communicates with GPU VRAM in small 256MB chunks, creating significant PCIe bus bottlenecks when staging model context and streaming KV cache pages. Enabling Resizable BAR and Above 4G Decoding allows the CPU and DMA controllers to address the entire 24GB or 80GB VRAM address space simultaneously, eliminating data staging bottlenecks.
Why must memory ballooning be disabled when passing through a GPU?
IOMMU hardware translation tables require static physical memory pinning to protect against uncoordinated DMA writes. Dynamic memory ballooning constantly claims and releases guest memory back to the hypervisor, which invalidates the physical addresses mapped in the IOMMU page tables, immediately resulting in hypervisor host lockups and guest kernel crashes.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).