Securing Self-Hosted AI API Endpoints with OAuth2 Proxy and Rate Limiting on Nginx
Secure self-hosted AI endpoints using OAuth2 Proxy and Nginx rate limiting. Protect GPU inference backends from abuse with OIDC, JWTs, and token buckets.
/BlogZero-Cost CloudBrowse all engineering tutorials and benchmarks tagged with #AI/ML Infrastructure.
Secure self-hosted AI endpoints using OAuth2 Proxy and Nginx rate limiting. Protect GPU inference backends from abuse with OIDC, JWTs, and token buckets.
Monitor NVIDIA GPU thermal limits, power draw, and VRAM leaks with Prometheus and Grafana. Deploy enterprise DCGM exporters and optimized alert pipelines.
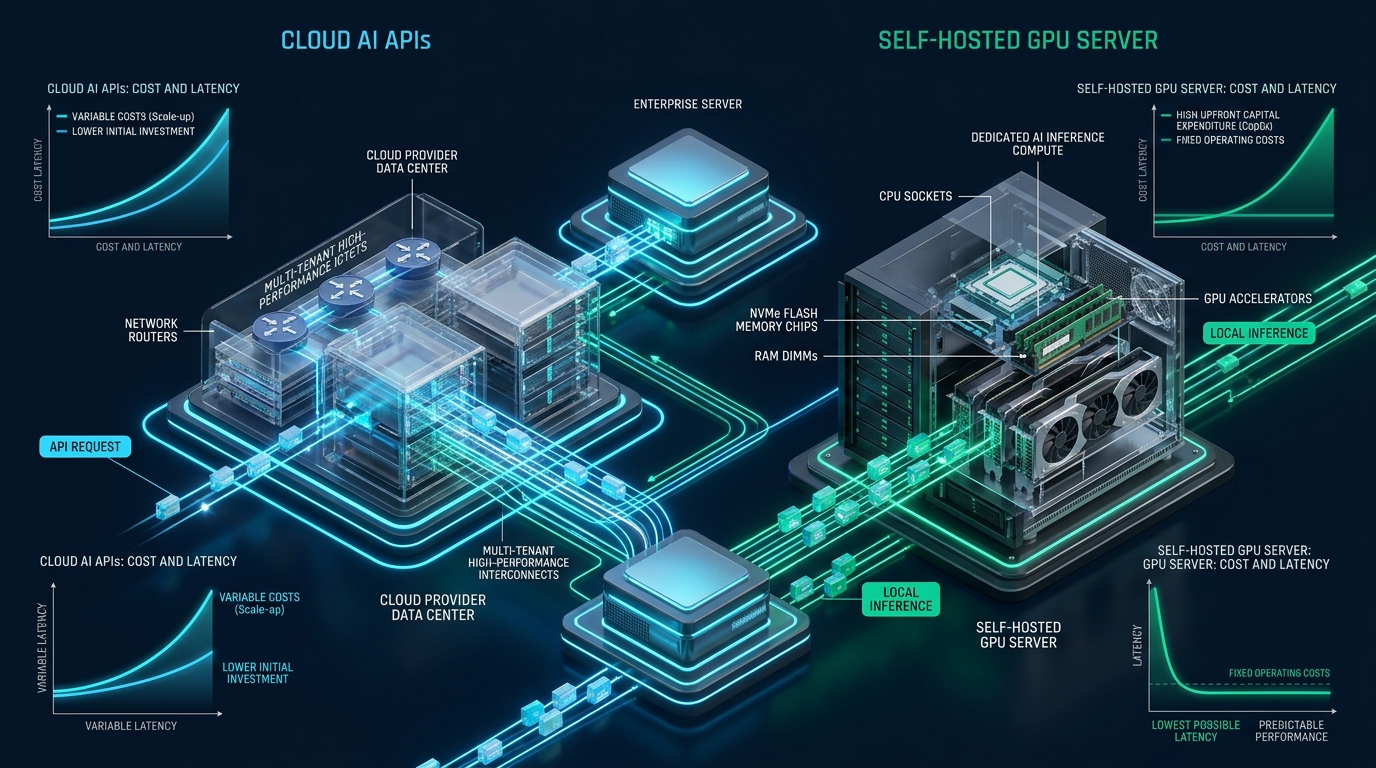
Compare cost, latency, and throughput between cloud AI APIs and self-hosted GPUs. Benchmark production inference stacks with real Linux configurations.
Enterprise architecture guide to NVIDIA MIG partitioning on Linux servers for deterministic AI workload isolation and multi-tenant scaling.
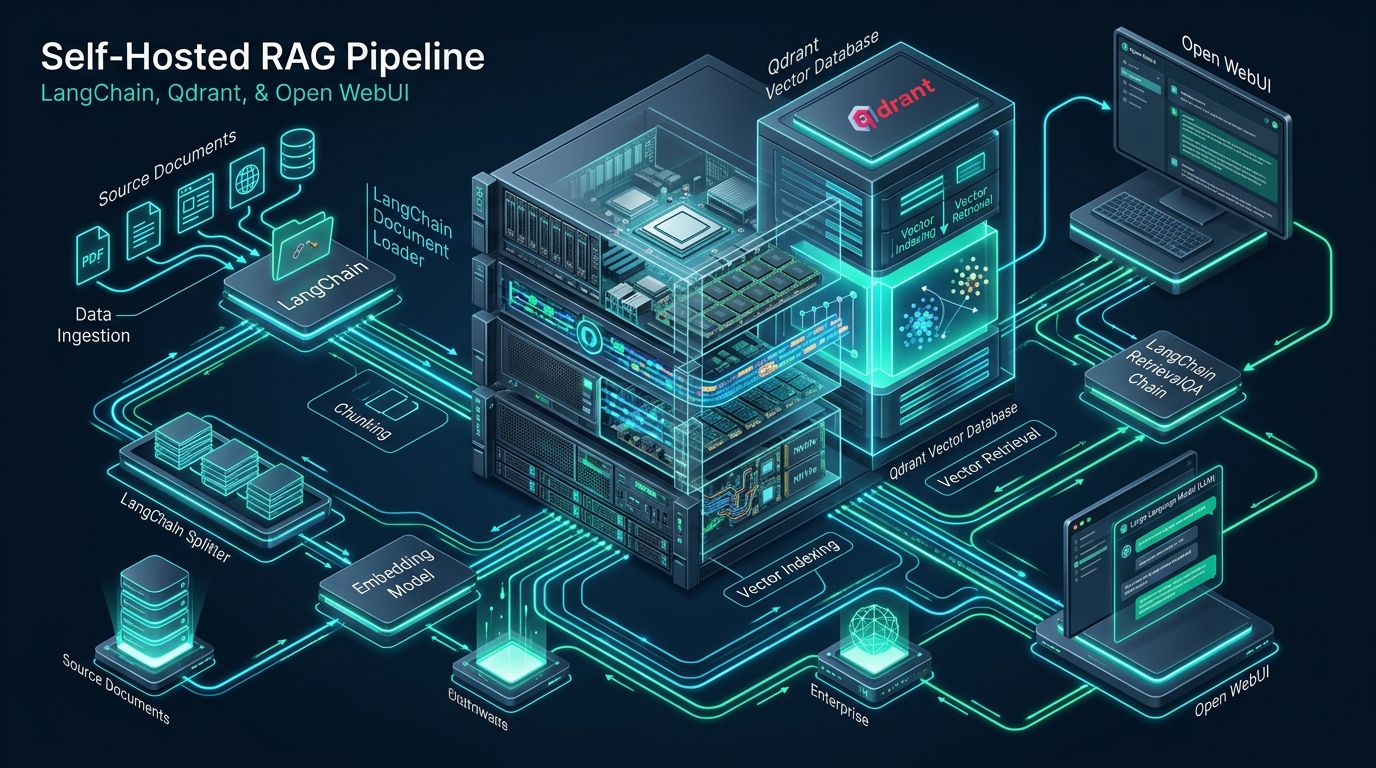
Deploy a private, self-hosted RAG pipeline using LangChain, Qdrant, and Open WebUI on Linux. Eliminate third-party data leakage with sub-15ms vector search.
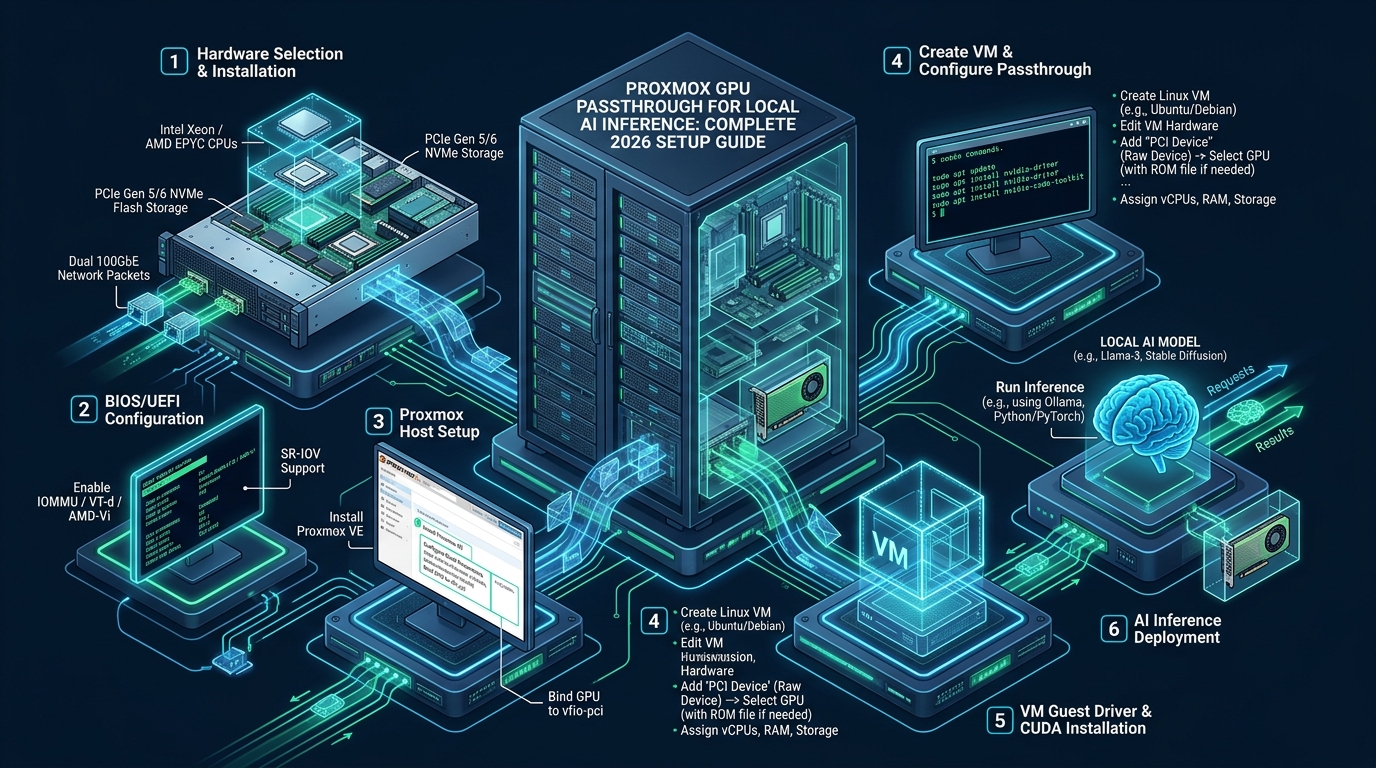
Master Proxmox VE GPU passthrough for low-latency local AI inference. Configure IOMMU, vfio-pci drivers, and QEMU for raw bare-metal LLM performance.