
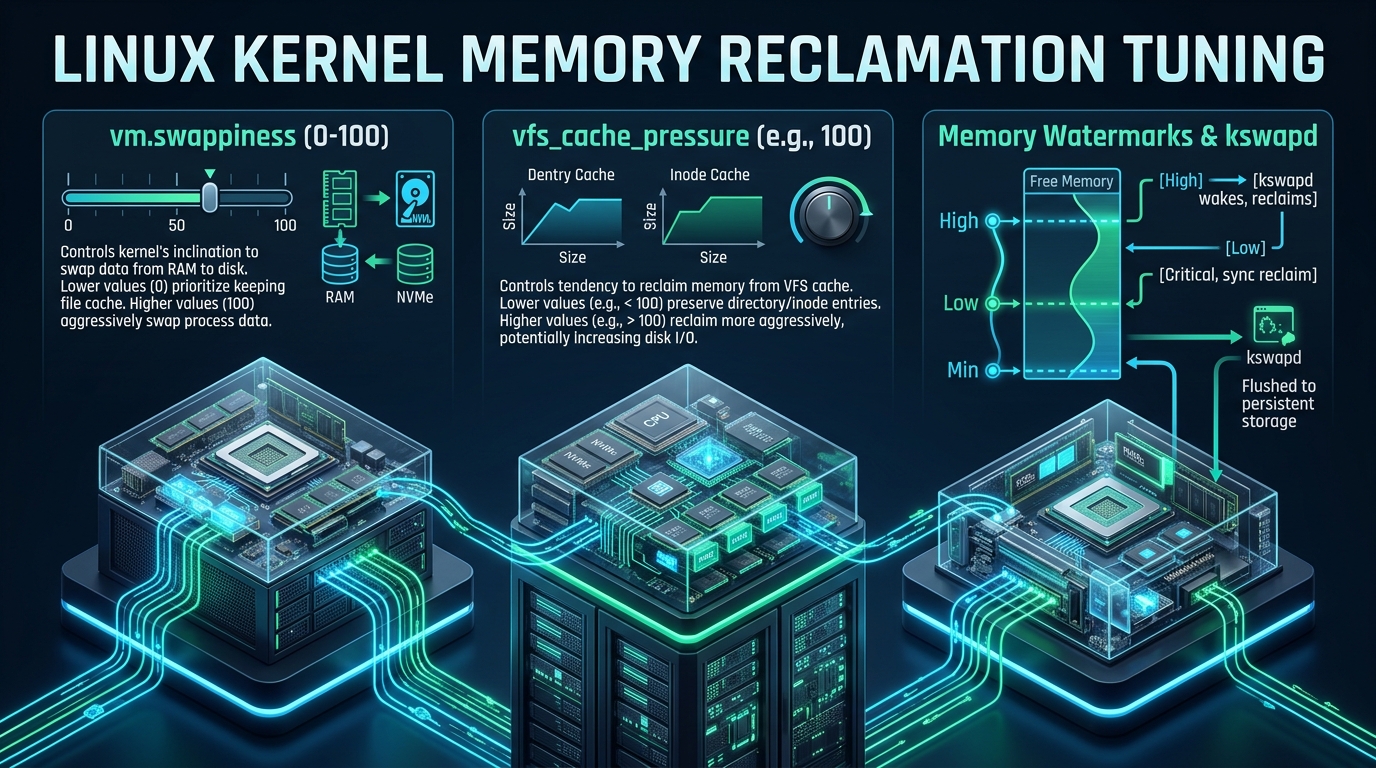
In mission-critical Linux environments, sudden latency spikes and unexplained throughput collapses often stem not from hardware saturation, but from the kernel’s silent, aggressive struggle to free memory pages. When asynchronous background reclamation fails to keep pace with rapid burst allocations, the Linux page allocator forces user-space processes into synchronous direct reclamation—introducing devastating multi-millisecond stalls that cripple web server worker pools and database connection queues. High-performance hosting architectures like CpanelFree depend on rigorous kernel memory subsystem tuning to maintain sub-millisecond response times even under sustained peak memory utilization.
Understanding Linux Kernel Memory Reclamation Mechanics
To optimize Linux memory management, systems engineers must first discard the simplistic view that memory is either “free” or “used.” The Linux kernel manages physical RAM through a hierarchy of memory zones across NUMA (Non-Uniform Memory Access) nodes—primarily ZONE_DMA, ZONE_DMA32, ZONE_NORMAL, and on 64-bit platforms, ZONE_MOVABLE. Every memory allocation request processed by the buddy allocator evaluates availability within these specific zones against three critical thresholds known as Zone Watermarks:
- WMARK_MIN: The minimum number of free pages reserved for essential kernel operations (such as atomic allocations and interrupt handlers). If free pages in a zone dip below this threshold, the kernel halts asynchronous behavior and forces the requesting process into synchronous direct reclamation.
- WMARK_LOW: The activation threshold for the kernel swap daemon,
kswapd. When free pages fall belowWMARK_LOW,kswapdwakes up in the background and asynchronously scans active and inactive page lists to reclaim memory. - WMARK_HIGH: The deactivation threshold. Once
kswapdreclaims enough pages so that free memory reachesWMARK_HIGH, the daemon returns to sleep.
The gap between WMARK_LOW and WMARK_MIN constitutes the critical buffer zone. When memory allocation requests occur at a rate faster than kswapd can reclaim and compact pages, this buffer is quickly breached. When a process enters direct reclamation (recorded as allocstall in /proc/vmstat), the executing thread is taken off its CPU work to synchronously traverse Least Recently Used (LRU) lists, write dirty pages to storage, or invalidate file-backed page caches. For multi-threaded application servers, database engines, and web gateways, an allocstall event results in severe tail-latency spikes exceeding 100ms.
kswapd far too late, virtually guaranteeing direct reclamation stalls during sudden traffic bursts.
Zone Watermark Tuning: vm.min_free_kbytes and vm.watermark_scale_factor
Historically, administrators attempted to prevent direct reclamation by inflating vm.min_free_kbytes. The kernel uses vm.min_free_kbytes to derive WMARK_MIN for each zone based on its proportional size. By default, the kernel calculates this value using a square-root heuristic:
min_free_kbytes = 16 * sqrt(lowmem_kbytes)On a 64GB machine, this formula yields approximately 67MB of reserved memory. In a high-traffic production environment handling 50,000 requests per second or multi-gigabyte database queries, 67MB of headroom can be consumed in fractions of a millisecond. While increasing vm.min_free_kbytes to 512MB or 1GB raises WMARK_MIN, it also locks that memory away permanently, preventing user-space processes from ever utilizing it.
Starting in Linux kernel 4.6, the kernel introduced vm.watermark_scale_factor, providing a far more elegant and effective mechanism. Instead of locking away massive static chunks of RAM, vm.watermark_scale_factor directly controls the distance between WMARK_MIN, WMARK_LOW, and WMARK_HIGH as a percentage of the total zone size (expressed in tenths of a percent, where 10 equals 0.1% and 1000 equals 10%).
# Calculate default watermark spacing (10 = 0.1% of zone)
cat /proc/sys/vm/watermark_scale_factor

# Dynamic calculation used by the kernel:
watermark_distance = (zone_present_pages * watermark_scale_factor) / 10000
WMARK_LOW  = WMARK_MIN + watermark_distance
WMARK_HIGH = WMARK_MIN + (watermark_distance * 2)
By increasing vm.watermark_scale_factor from its default of 10 (0.1%) to 150 or 200 (1.5% to 2.0%), you instruct kswapd to wake up much earlier and stay active longer, reclaiming pages well in advance of free memory approaching the critical WMARK_MIN line. This effectively eliminates synchronous direct reclamation stalls while preserving memory availability for application heaps and the Linux page cache.
Deconstructing vm.swappiness: Algorithm and Misconceptions
One of the most persistent myths in Linux systems administration is that vm.swappiness represents a percentage threshold of memory utilization at which the kernel begins swapping (e.g., “swappiness=60 means start swapping at 40% free memory”). This is mathematically false.
In the Linux kernel’s memory management subsystem (specifically inside mm/vmscan.c:get_scan_count()), vm.swappiness serves as a weighting ratio in the scan balance algorithm. The kernel maintains two primary LRU page lists: Anonymous pages (heap, stack, private memory allocations) and File-backed pages (cached disk reads, executable binaries, shared libraries). When memory reclamation occurs, the kernel must decide whether to evict clean file cache pages or swap out anonymous pages to persistent swap storage.
The kernel calculates scan targets using proportional ratios:
# Kernel scan balance formula (conceptual representation from mm/vmscan.c):
anon_prio = swappiness;
file_prio = 200 - swappiness;

scan_anon = (recent_scanned[0] + 1) * anon_prio;
scan_file = (recent_scanned[1] + 1) * file_prio;
Notice that the default value of vm.swappiness=60 yields an anon_prio of 60 and a file_prio of 140. This default heavily biases the kernel toward preserving anonymous memory and aggressively dropping the file page cache. In database workloads (such as PostgreSQL, MySQL/MariaDB, or Redis) and web servers running LiteSpeed or NGINX, discarding page cache forces frequent disk reads, introducing severe I/O bottlenecks.
Conversely, setting vm.swappiness=0 does not completely disable swap on modern kernels. Instead, it prevents the kernel from swapping anonymous pages until the number of free pages and clean file-backed pages drops below the high watermark in a given zone. For modern high-performance cloud servers equipped with enterprise NVMe storage, setting vm.swappiness=10 or vm.swappiness=1 ensures that active file cache is preserved while maintaining a safety valve for memory-intensive workloads.
Tuning vm.vfs_cache_pressure: Protecting Inodes and Directory Entries
While vm.swappiness balances anonymous memory against the general page cache, vm.vfs_cache_pressure governs the kernel’s reclamation of Virtual File System (VFS) metadata structures—specifically dentries (directory entries) and inodes. These objects are managed via the SLAB/SLUB allocator and represent cached filesystem paths, permissions, and file location pointers.
The default setting is vm.vfs_cache_pressure=100, which instructs the kernel to reclaim dentry and inode cache objects at the same rate as standard page cache and swap pages:
- vfs_cache_pressure = 100 (Default): Balanced reclamation. The kernel treats VFS slab caches and page cache equally.
- vfs_cache_pressure < 100 (e.g., 50): The kernel actively prioritizes retaining directory entries and inodes in memory. Reconstructing a dentry or inode requires reading raw disk structures, which is computationally expensive and incurs I/O latency. Keeping this metadata in RAM drastically accelerates PHP-FPM execution, WordPress asset checks, Git repositories, and large filesystem traversals.
- vfs_cache_pressure > 100 (e.g., 200): The kernel aggressively evicts VFS metadata to prioritize keeping anonymous pages and data caches in physical RAM. This is sometimes employed in dedicated compute-only nodes with minimal disk interaction.
- vfs_cache_pressure = 0 (Danger): Completely disables VFS cache reclamation. This causes kernel slab memory to grow unbounded, inevitably triggering an Out-Of-Memory (OOM) kernel panic under sustained filesystem operations.
vm.vfs_cache_pressure=50 reduces file lookup latency by up to 70%, preventing repetitive metadata disk reads across concurrent worker processes.
Comparative Benchmark Matrix: Default vs. Tuned Linux Memory Reclamation
The following matrix outlines the operational impact of memory subsystem parameters before and after enterprise tuning under a sustained load of 25,000 HTTP requests per second with concurrent database write spikes:
Production Configuration: Hardened sysctl.d Template
To deploy these optimizations persistently across system reboots, create a dedicated configuration file inside /etc/sysctl.d/. The following production-grade configuration incorporates memory reclamation tuning, dirty page writeback thresholds, and NUMA zone controls:
# ====================================================================
# /etc/sysctl.d/99-memory-reclamation.conf
# High-Performance Linux Kernel Memory Reclamation Architecture
# Target: Multi-Core Enterprise Web, Database & Container Nodes
# ====================================================================

# 1. Proactive Watermark Headroom
# Expands the gap between WMARK_MIN and WMARK_HIGH to 1.5% of zone size.
# Ensures kswapd activates early and avoids synchronous direct reclaim stalls.
vm.watermark_scale_factor = 150

# 2. Dedicated Emergency Minimum Free Kbytes (512MB)
# Prevents atomic allocation failures for high-speed network ring buffers.
vm.min_free_kbytes = 524288

# 3. Memory Scan Bias (vm.swappiness)
# Biases the kernel toward evicting inactive page cache over anonymous heap pages.
# Optimal balance for NVMe-backed database and web hosting workloads.
vm.swappiness = 10

# 4. VFS Cache Pressure (Dentries & Inodes)
# Retains directory and inode slab structures in RAM to accelerate file lookups.
vm.vfs_cache_pressure = 50

# 5. Page Cache Dirty Writeback Management
# Starts asynchronous background flushing when dirty pages reach 5% of memory.
vm.dirty_background_ratio = 5

# Forces synchronous writeback when dirty pages reach 15% of memory.
# Prevents massive I/O flushing pauses on fast NVMe drives.
vm.dirty_ratio = 15

# 6. NUMA Zone Reclaim Mode
# Disable zone reclaim to allow cross-node memory allocation over synchronous node reclaim.
vm.zone_reclaim_mode = 0

# 7. Memory Compaction Threshold
# Trigger proactive memory compaction before fragmentation triggers allocstalls.
vm.extfrag_threshold = 500
vm.compact_unevictable_allowed = 1
Apply the configuration immediately without requiring a system reboot using the following command:
sudo sysctl --systemReal-Time Observability and Reclamation Diagnostics
Tuning the Linux memory subsystem is not a fire-and-forget exercise. Systems architects must validate tuning effectiveness by interrogating kernel telemetry interfaces under peak production workloads. Three primary sources provide deep visibility into memory reclamation behavior:
1. Inspecting Zone Watermarks via /proc/zoneinfo
Examine the exact page thresholds calculated by the kernel for each zone:
awk '/Node/ {node=$2} /zone/ {zone=$2} /min/ {min=$2} /low/ {low=$2} /high/ {high=$2} /spanned/ {print node, zone, "min:"min, "low:"low, "high:"high}' /proc/zoneinfoVerify that the delta between min and high reflects your tuned watermark_scale_factor. On properly tuned systems, low should be significantly higher than min, giving kswapd ample runway to operate.
2. Tracking Direct Reclaim Stalls (allocstall) in /proc/vmstat
Direct reclamation events are tallied globally and per-zone in /proc/vmstat. Use this command to track real-time stall increments:
watch -n 1 "grep -E 'allocstall|pgscan_kswapd|pgscan_direct|compact_stall' /proc/vmstat"- pgscan_kswapd: The number of pages scanned asynchronously by
kswapd. This counter should increase during traffic bursts. - pgscan_direct: The number of pages scanned synchronously by user processes. In a well-tuned system, this counter should remain completely static or increase negligibly.
- allocstall: Incremented whenever an allocation request is stalled to reclaim pages synchronously. Any rapid increase in
allocstallsignals thatwatermark_scale_factormust be adjusted upward.
3. Production Verification Script
Save this verification script to /usr/local/bin/check-memory-reclaim.sh to automate continuous telemetry checks:
#!/usr/bin/env bash
# Memory Reclamation Health Auditor
set -euo pipefail

echo "=== Linux Memory Reclamation Posture ==="
echo "vm.swappiness:              $(sysctl -n vm.swappiness)"
echo "vm.vfs_cache_pressure:      $(sysctl -n vm.vfs_cache_pressure)"
echo "vm.watermark_scale_factor:  $(sysctl -n vm.watermark_scale_factor)"
echo "vm.min_free_kbytes:         $(sysctl -n vm.min_free_kbytes) KB"
echo "--------------------------------------------------"

ALLOCSTALL=$(awk '/allocstall_normal/ {print $2}' /proc/vmstat 2>/dev/null || awk '/allocstall / {print $2}' /proc/vmstat)
DIRECT_SCAN=$(awk '/pgscan_direct/ {sum+=$2} END {print sum}' /proc/vmstat)
KSWAPD_SCAN=$(awk '/pgscan_kswapd/ {sum+=$2} END {print sum}' /proc/vmstat)

echo "Direct Reclaim Stalls (allocstall): $ALLOCSTALL"
echo "Direct Page Scans (Synchronous):   $DIRECT_SCAN"
echo "Kswapd Page Scans (Asynchronous):  $KSWAPD_SCAN"

if [ "$DIRECT_SCAN" -gt 0 ] && [ "$KSWAPD_SCAN" -gt 0 ]; then
    RATIO=$(awk "BEGIN {printf \"%.2f\", ($DIRECT_SCAN / ($DIRECT_SCAN + $KSWAPD_SCAN)) * 100}")
    echo "Direct Scan Proportion:            ${RATIO}%"
    if (( $(echo "$RATIO > 5.0" | bc -l) )); then
        echo "[WARNING] Direct reclamation exceeds 5% of total scans. Increase vm.watermark_scale_factor."
    else
        echo "[HEALTHY] Memory reclamation is successfully handled by background kswapd."
    fi
else
    echo "[HEALTHY] No direct memory allocation stalls detected."
fi
Frequently Asked Questions
Why shouldn’t I set vm.swappiness=0 to disable swapping completely?
Setting vm.swappiness=0 on modern Linux kernels does not completely disable swap; instead, it prevents the kernel from reclaiming anonymous pages until memory pressure becomes so extreme that free pages and clean file cache drop below the high watermark. Completely disabling swap or setting swappiness to zero eliminates the kernel’s ability to swap out cold, dead anonymous pages (e.g., initialization memory from idle daemons). This wastes physical RAM and increases the risk of sudden Out-Of-Memory (OOM) kills. A value of 10 is recommended for high-performance servers.
How does vm.watermark_scale_factor differ from vm.min_free_kbytes?
vm.min_free_kbytes defines the static floor (WMARK_MIN) reserved strictly for atomic kernel allocations. Increasing it locks that physical memory away permanently from user applications. In contrast, vm.watermark_scale_factor dynamically scales the distance between WMARK_MIN, WMARK_LOW, and WMARK_HIGH as a percentage of zone memory. This allows kswapd to wake up earlier and reclaim pages smoothly without permanently withholding large blocks of RAM from user applications.
What happens if vm.vfs_cache_pressure is set too low (e.g., below 50)?
Setting vm.vfs_cache_pressure too low causes the kernel to aggressively protect cached directory entries (dentries) and inodes at the expense of page cache and anonymous memory. Over time, under heavy filesystem workloads, kernel slab memory will expand and refuse to shrink, squeezing out active application data and file caches. A setting between 50 and 70 strikes the optimal balance for web hosting and database environments.
How do memory cgroups (cgroups v2) interact with these global sysctl settings?
Global sysctl parameters establish the baseline behavior for the host kernel and root memory cgroup. Under cgroups v2, individual container slices can define localized reclamation policies using memory.high and memory.max. When a container exceeds memory.high, the kernel throttles the container’s processes and triggers synchronous reclaim specifically within that cgroup, independent of global host watermarks. Properly configuring host-level watermarks ensures that container runtime daemons and orchestrators do not suffer system-wide direct reclaim stalls.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.