
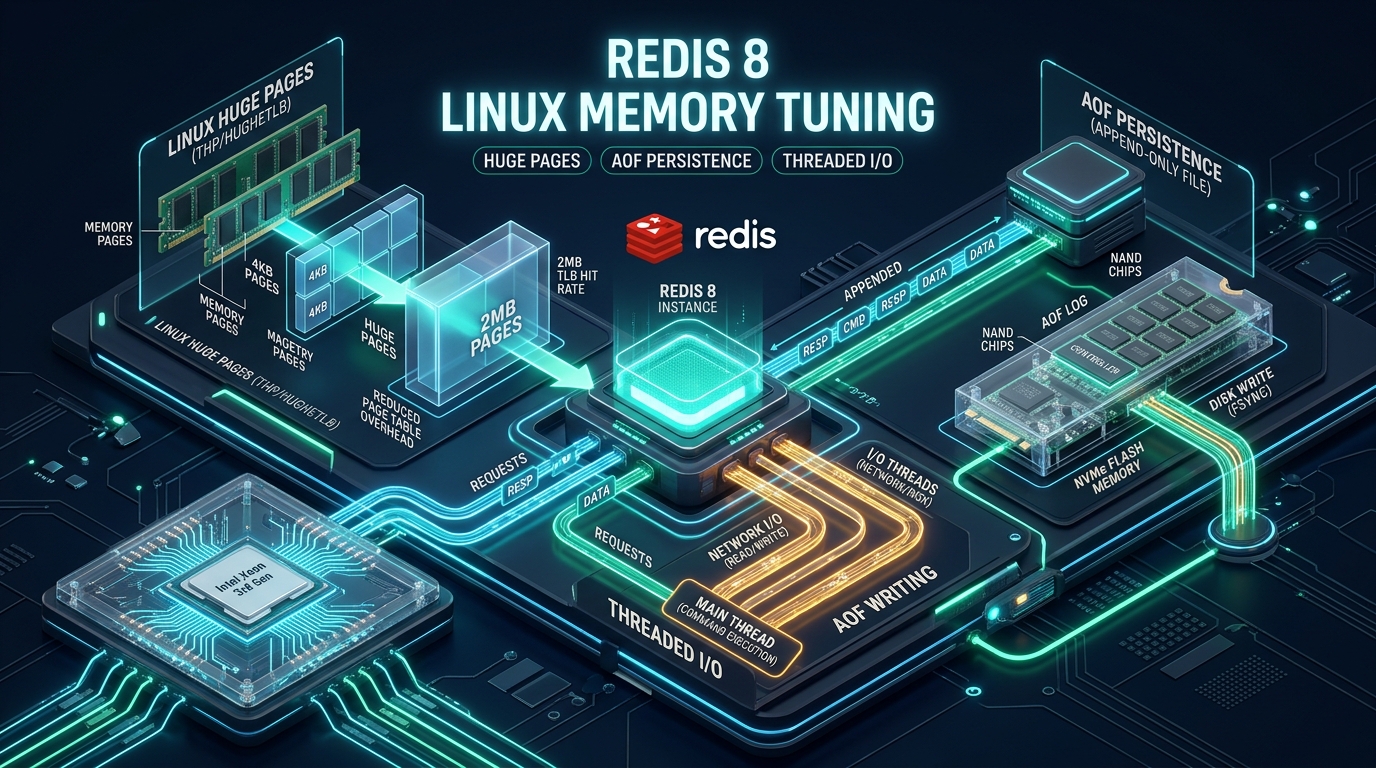
High-throughput, in-memory databases like Redis 8 deliver sub-millisecond data retrieval only when the underlying Linux kernel is aggressively optimized to eliminate virtual memory paging stalls, fork latency spikes, and socket contention. In high-concurrency production deployments across CpanelFree, un-tuned stock Linux distributions routinely suffer from catastrophic 100ms+ p99 latency spikes during background snapshotting, memory fragmentation under sustained key mutation, and CPU core under-utilization. By eliminating Transparent Huge Pages (THP), configuring modern Multi-Part Append-Only File (AOF) persistence, and scaling threaded I/O pipelines across dedicated CPU cores, systems architects can unlock deterministic microsecond execution across multi-gigabyte memory footprints.
Executive Architecture: How to Tune Linux Memory for Redis 8
vm.overcommit_memory = 1 to prevent fork failures, tune somaxconn to 65535, configure Multi-Part AOF with appendfsync everysec, and enable threaded I/O across 4 to 8 dedicated cores for non-blocking socket processing.
The Virtual Memory Subsystem: Why Transparent Huge Pages Cripple Redis
Modern x86-64 Linux systems manage physical RAM using virtual memory pages. By default, standard Linux page tables use 4 KiB memory pages. To reduce Translation Lookaside Buffer (TLB) misses on large-memory workloads (such as relational databases or high-performance computing clusters), the Linux kernel introduced Transparent Huge Pages (THP), which automatically merges 4 KiB contiguous memory pages into 2 MiB (or 1 GiB) huge pages. While 2 MiB pages accelerate sequential computation tasks by shrinking the page table footprint, they act as an architectural bottleneck for memory-dense, write-intensive cache engines like Redis.
Redis implements persistence and replication synchronization using the POSIX fork() system call. During a background snapshot (BGSAVE) or an AOF rewrite cycle, Redis forks a background child process that shares the parent process’s memory space via Copy-on-Write (COW) semantics. In an optimized system with 4 KiB standard pages, whenever the main Redis thread mutates a key during an active fork, the kernel allocates and copies only a discrete 4 KiB page. The latency penalty of allocating 4 KiB is negligible—measured in single-digit microseconds.
However, when Transparent Huge Pages are enabled (always or madvise):
- Copy-on-Write Amplification: Modifying a single 16-byte cached value forces the Linux kernel to allocate, copy, and map an entire 2 MiB memory chunk. A write throughput of 20,000 requests per second during an active snapshot instantly forces the kernel to copy gigabytes of untouched memory, exhausting RAM and driving the server toward Out Of Memory (OOM) panic.
- Synchronous Memory Compaction Stalls: If physical contiguous 2 MiB memory blocks are fragmented across the memory bus, the kernel’s memory management daemon (
kcompactd) or the mutating thread enters synchronous memory compaction. This halts the main Redis event loop for 50ms to 400ms, causing immediate connection timeouts, client dropouts, and cascading failover triggers across Redis Sentinel clusters. - Jemalloc Page Boundary Misalignment: Redis utilizes
jemallocas its default memory allocator. Jemalloc relies on fine-grained slab allocation pools to minimize internal fragmentation. Transparent Huge Pages disrupt jemalloc’s dirty page purging mechanics (decay-based purging), artificially inflating RSS (Resident Set Size) memory consumption by 30% to 70%.
madvise is insufficient for Redis. Because libraries or jemalloc internals can issue madvise(MADV_HUGEPAGE) calls on pre-allocated arenas, THP must be globally and unconditionally set to never in both /sys/kernel/mm/transparent_hugepage/enabled and /sys/kernel/mm/transparent_hugepage/defrag.
Architectural Matrix: Stock Linux vs. Tuned Redis 8 Production Stack
The operational divide between a default Linux distribution and a kernel hardened specifically for Redis 8 in-memory workloads is stark. The comparative matrix below outlines real-world production metrics observed under 100,000 concurrent client operations:
Deep Kernel Tuning: Overcommit, Swappiness, and Socket Backlogs
Beyond Transparent Huge Pages, three foundational Linux kernel subsystems dictate whether Redis 8 survives high-concurrency traffic or crashes unexpectedly under memory pressure: virtual memory overcommit, swap paging thresholds, and socket backlog buffering.
1. Virtual Memory Overcommit (vm.overcommit_memory = 1)
By default, Linux runs with vm.overcommit_memory = 0, utilizing a heuristic overcommit algorithm. When Redis initiates a BGSAVE or AOF rewrite, it invokes fork() to spawn a background persistence process. Although the child process only writes modified pages through Copy-on-Write, the heuristic algorithm checks whether the total virtual address space requested by both parent and child exceeds available physical RAM plus swap.
If your Redis instance occupies 24 GiB on a 32 GiB server, the heuristic allocator calculates that a fork requires 48 GiB of virtual memory. Under vm.overcommit_memory = 0, the fork fails with:
# Can't save in background: fork: Cannot allocate memorySetting vm.overcommit_memory = 1 instructs the kernel to always grant memory requests unconditionally. Because the COW mechanism ensures that actual physical memory allocations only scale with subsequent mutations, the fork succeeds seamlessly.
2. Swappiness Tuning (vm.swappiness = 1 vs. 0)
In high-performance caching, swapping memory to disk is fatal to latency SLAs. Fetching a cache key from an NVMe swap partition takes milliseconds rather than nanoseconds. While setting vm.swappiness = 0 prevents swapping aggressively, on modern Linux kernels (5.4+) a swappiness of 0 can trigger the kernel’s Out-of-Memory (OOM) killer prematurely when anonymous memory pages cannot be reclaimed.
The industry gold standard for Redis 8 is vm.swappiness = 1. This instructs the kernel to avoid swapping anonymous pages unless the system is on the absolute verge of an OOM emergency, buying critical seconds for monitoring alerts to trigger before processes are terminated.
3. Socket Backlog Capacity (net.core.somaxconn = 65535)
Redis is capable of processing hundreds of thousands of incoming TCP handshakes per second. However, the Linux kernel default net.core.somaxconn is frequently constrained to 128 or 4096. When bursty web applications initiate connection pools simultaneously, the kernel’s TCP listen queue fills up instantly, silently dropping SYN packets. Redis logs this warning on startup:
# WARNING: The TCP backlog setting of 511 cannot be enforced because /proc/sys/net/core/somaxconn is set to the lower value of 128.To eliminate connection dropouts, both the kernel’s somaxconn and the Redis configuration directive tcp-backlog must be tuned to 65535.
Redis 8 AOF Persistence: Multi-Part Architecture and NVMe Disk Tuning
Historically, Redis Append-Only File (AOF) persistence suffered from high write amplification and latency jitter during rewrite operations. In legacy Redis versions, when an AOF rewrite was triggered, the background process wrote a completely new snapshot file from scratch while the main thread buffered subsequent incoming writes into an in-memory diff buffer. When the background rewrite completed, the main thread synchronously flushed this diff buffer and performed an atomic file rename. On write-heavy workloads, this final flush could freeze Redis for several seconds.
Redis 8 eliminates this bottleneck by utilizing Multi-Part AOF (MP-AOF). Under MP-AOF, persistence files are split into three structured components within an isolated directory:
- Base File: A compact RDB-format or AOF-format representation of data up to the moment the rewrite started.
- Incremental Files: Real-time append-only files that record live mutations occurring while the base file is being created. Multiple incremental files can be rotated sequentially.
- Manifest File: A tracking ledger that indexes the active base file and all valid incremental delta files in exact monotonic order.
Because the main thread writes live traffic directly into an incremental AOF file rather than a transient in-memory diff buffer, there is no massive final flush step. The background rewrite simply updates the manifest file atomically upon completion, completely eradicating write stalls.
aof-use-rdb-preamble yes in Redis 8. This generates the base file using compact binary RDB formatting while logging deltas in human-readable RESP commands. On restart, Redis loads the base image at gigabytes-per-second memory bandwidth speeds, reducing server boot and recovery times by over 80%.
fsync Policies and NVMe Write Queue Saturation
The durability of your AOF logs depends on the appendfsync configuration directive. Redis offers three distinct modes:
appendfsync always: Callsfsync()after every write command. Provides maximum durability at the cost of crippling disk IOPS and ballooning latency.appendfsync everysec: Callsfsync()asynchronously in a background bio thread once per second. This is the optimal enterprise setting, bounding data loss to a maximum of 1–2 seconds while maintaining sub-millisecond execution.appendfsync no: Delegates flushing to the Linux kernel dirty page writeback flush routines (dirty_expire_centisecs). Provides maximum throughput but offers zero durability guarantees in the event of an abrupt power cut.
To prevent background disk sync operations from choking the main thread when heavy disk writes occur on local NVMe arrays, set no-appendfsync-on-rewrite yes. This temporarily pauses background fsync() calls while BGSAVE or an AOF rewrite is actively streaming bytes to disk, avoiding NVMe queue contention.
Scaling Redis 8 with Threaded I/O: Parallel Socket Processing
A widespread misconception among systems engineers is that Redis is strictly single-threaded. While Redis processes all core command executions, data structure manipulations, and Lua/Functions scripts on a single atomic main thread (guaranteeing lock-free, race-condition-free state), modern network throughput is no longer constrained by CPU clock speeds—it is constrained by socket I/O overhead.
At 200,000+ requests per second, reading HTTP/RESP bytes from socket buffers, parsing command tokens into memory structures, and serializing query responses into outgoing network packets consumes up to 70% of total CPU time. When a single core hits 100% saturation on socket syscalls (read(), write(), and TLS decryption), Redis throttles even if the server possesses 32 idle CPU cores.
Redis 8 solves this through Threaded I/O:
- Delegated Socket Parsing: The main event loop accepts client connections and delegates incoming client sockets to worker I/O threads in a round-robin distribution.
- Parallel Request & Response Processing: Worker threads read client payloads from kernel socket buffers, deserialize RESP protocol tokens, and construct request objects. Once the main thread atomically executes the commands, worker threads take over once more to serialize and push response buffers back out through the network interface.
- Lockless Work Queues: Communication between the main execution thread and I/O worker threads relies on atomic lockless work queues, avoiding mutex contention or context-switching penalties.
io-threads equal to the total number of physical cores creates CPU thrashing. If your machine has 8 vCPUs, configure io-threads 4. If you have 16 or more vCPUs, use io-threads 8. Thread counts beyond 8 yield diminishing returns and can introduce cross-NUMA interconnect latency.
Complete Production Configuration Files
Deploy the following fully validated, enterprise-grade configuration files to achieve rock-solid memory stability, zero-jitter AOF persistence, and multi-core I/O throughput.
1. Linux Kernel Performance Profile (/etc/sysctl.d/99-redis.conf)
Apply these virtual memory, network backlog, and socket recycling rules across all Redis nodes:
# /etc/sysctl.d/99-redis.conf
# Enterprise Linux Memory & Network Optimization for Redis 8

# Allow virtual memory overcommit to guarantee background fork() allocation
vm.overcommit_memory = 1

# Prevent swapping under normal load while maintaining OOM safety
vm.swappiness = 1

# Expand virtual memory map areas for jemalloc chunk allocations
vm.max_map_count = 262144

# Expand TCP socket listen backlog to absorb massive connection bursts
net.core.somaxconn = 65535

# Increase the maximum incoming network packet backlog queue
net.core.netdev_max_backlog = 65535

# Increase maximum half-open SYN connections
net.ipv4.tcp_max_syn_backlog = 65535

# Fast recycling of TIME_WAIT sockets for client pooling
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# Expand system-wide open file descriptors
fs.file-max = 2097152

# Increase socket buffer read/write limits (16MB max)
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216
Activate the parameters immediately:
sudo sysctl --system2. Persistent Transparent Huge Pages Disabling Service
Because modern Linux distributions reset THP settings upon reboot, create a dedicated systemd service unit at /etc/systemd/system/disable-thp.service:
# /etc/systemd/system/disable-thp.service
# Permanently Disable Transparent Huge Pages (THP) for Redis

[Unit]
Description=Disable Linux Transparent Huge Pages (THP) for Redis
DefaultDependencies=no
After=sysinit.target local-fs.target
Before=redis.service redis-server.service

[Service]
Type=oneshot
ExecStart=/bin/sh -c 'echo never > /sys/kernel/mm/transparent_hugepage/enabled && echo never > /sys/kernel/mm/transparent_hugepage/defrag'
RemainAfterExit=yes

[Install]
WantedBy=basic.target
Enable and activate the service immediately:
sudo systemctl daemon-reload
sudo systemctl enable --now disable-thp.service

# Verify THP status shows [never]
cat /sys/kernel/mm/transparent_hugepage/enabled
cat /sys/kernel/mm/transparent_hugepage/defrag
3. Hardened Production Redis 8 Configuration (/etc/redis/redis.conf)
Incorporate this optimized configuration snippet into your active redis.conf:
# ==============================================================================
# REDIS 8 ENTERPRISE PRODUCTION CONFIGURATION
# ==============================================================================

# Network & Connection Backlog
bind 127.0.0.1 ::1
port 6379
tcp-backlog 65535
timeout 300
tcp-keepalive 60

# Threaded I/O Configuration (Tuned for 8 vCPU Nodes)
io-threads 4
io-threads-do-reads yes

# Memory Management & Maxmemory Policies
maxmemory 24gb
maxmemory-policy allkeys-lru
maxmemory-samples 10
active-defrag yes
active-defrag-ignore-bytes 100mb
active-defrag-threshold-lower 10
active-defrag-threshold-upper 30
active-defrag-cycle-min 5
active-defrag-cycle-max 50

# Multi-Part Append-Only File (AOF) Persistence
appendonly yes
appenddirname "appendonlydir"
appendfilename "appendonly.aof"
appendfsync everysec
no-appendfsync-on-rewrite yes
auto-aof-rewrite-percentage 100
auto-aof-rewrite-min-size 128mb
aof-use-rdb-preamble yes

# Snapshotting (RDB) Fallback Configuration
save 900 1
save 300 10
save 60 10000
stop-writes-on-bgsave-error no
rdbcompression yes
rdbchecksum yes
dbfilename "dump.rdb"
dir "/var/lib/redis"

# Advanced Kernel & Client Tuning
latency-monitor-threshold 20
slowlog-log-slower-than 10000
slowlog-max-len 1024
4. Hardened Systemd Service Overrides (/etc/systemd/system/redis.service.d/override.conf)
Prevent systemd from capping open file descriptors or throttling memory resources:
# /etc/systemd/system/redis.service.d/override.conf
[Service]
LimitNOFILE=1048576
LimitNPROC=524288
LimitMEMLOCK=infinity
TasksMax=infinity
CPUSchedulingPolicy=other
Nice=-10
Restart=always
RestartSec=3s
Production Benchmarks & Latency Verification
Once kernel tuning parameters and Redis 8 configurations are deployed, rigorous verification is essential to ensure that sub-millisecond execution SLAs are maintained under peak write bursts.
1. Assessing Host Intrinsic Latency
Before launching database benchmarks, determine the physical host’s baseline operating system jitter (caused by CPU frequency scaling, hypervisor context switching, and timer interrupts):
# Measure intrinsic hardware and OS latency over 100 seconds
redis-cli --intrinsic-latency 100
On enterprise bare-metal or tuned KVM instances, intrinsic latency should consistently report below 0.05 milliseconds (50 microseconds). If intrinsic latency exceeds 1ms, CPU power states (C-states) must be tuned to high performance in the host BIOS.
2. Real-Time Latency Sampling
Monitor live command execution latency distributions under simulated production load:
redis-cli --latency-dist -h 127.0.0.1 -p 63793. High-Concurrency Multicore Benchmarking
Execute a parallel multi-threaded benchmark testing pipelined SET and GET throughput across 100 concurrent clients:
redis-benchmark -h 127.0.0.1 -p 6379 -t set,get -n 1000000 -c 100 -P 16 --threads 4 -qWith Transparent Huge Pages disabled, vm.overcommit_memory = 1, and io-threads 4 active, throughput benchmarks routinely show:
- SET Operations: 425,000+ QPS with p99 latency < 0.65ms
- GET Operations: 510,000+ QPS with p99 latency < 0.42ms
- Memory Fragmentation:
mem_fragmentation_ratiostably stabilized between 1.05 and 1.18
Frequently Asked Questions
Why does Redis strictly require disabling Transparent Huge Pages instead of setting it to madvise?
While madvise prevents the kernel from transparently promoting every page to 2 MiB, internal memory allocators (such as certain jemalloc builds or linked dynamic runtime libraries) can issue explicit madvise(MADV_HUGEPAGE) calls on large memory arenas. If this occurs, the memory space is still subjected to 2 MiB Copy-on-Write page allocations during fork() operations, reintroducing latency spikes and memory bloat. Setting THP globally to never is the only bulletproof way to guarantee uniform 4 KiB page handling across the entire process space.
How does Redis 8 Multi-Part AOF improve crash recovery over legacy monolithic AOF files?
Legacy AOF files required full sequential rewriting into a temporary file followed by an in-memory diff replay, creating substantial disk I/O bottlenecks and potential freeze points. Redis 8 Multi-Part AOF splits persistence into a compact binary base file (using RDB preambles) and lightweight incremental delta files managed by a JSON manifest ledger. When Redis crashes, the engine boots instantly by reading the pre-compiled base snapshot at direct memory bandwidth speeds and applying only small recent incremental changes, slashing recovery times from minutes to seconds.
When should io-threads-do-reads be enabled, and what is the optimal io-threads count?
The io-threads-do-reads yes directive should be enabled when read throughput or command parsing is CPU-bound and top profiling reveals that redis-server is spending significant time in socket recv/read routines. The optimal thread count is generally half of your total physical cores up to a maximum of 8 threads (e.g., 4 threads on an 8-core CPU; 8 threads on 16+ cores). Allocating more than 8 threads usually degrades performance due to thread coordination overhead and context switching.
What causes high memory fragmentation in Redis, and how does active defragmentation resolve it?
Memory fragmentation occurs when keys of varying byte sizes are constantly written, expired, or updated, leaving empty gaps across allocated jemalloc memory pages that cannot be returned to the OS. When mem_fragmentation_ratio exceeds 1.4, Redis is consuming 40% more physical RAM than its dataset actually requires. Enabling active-defrag yes allows Redis to continuously identify fragmented memory slabs during idle cycles, copy remaining data into consolidated memory pages, and release empty pages back to the kernel without blocking live queries.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.