
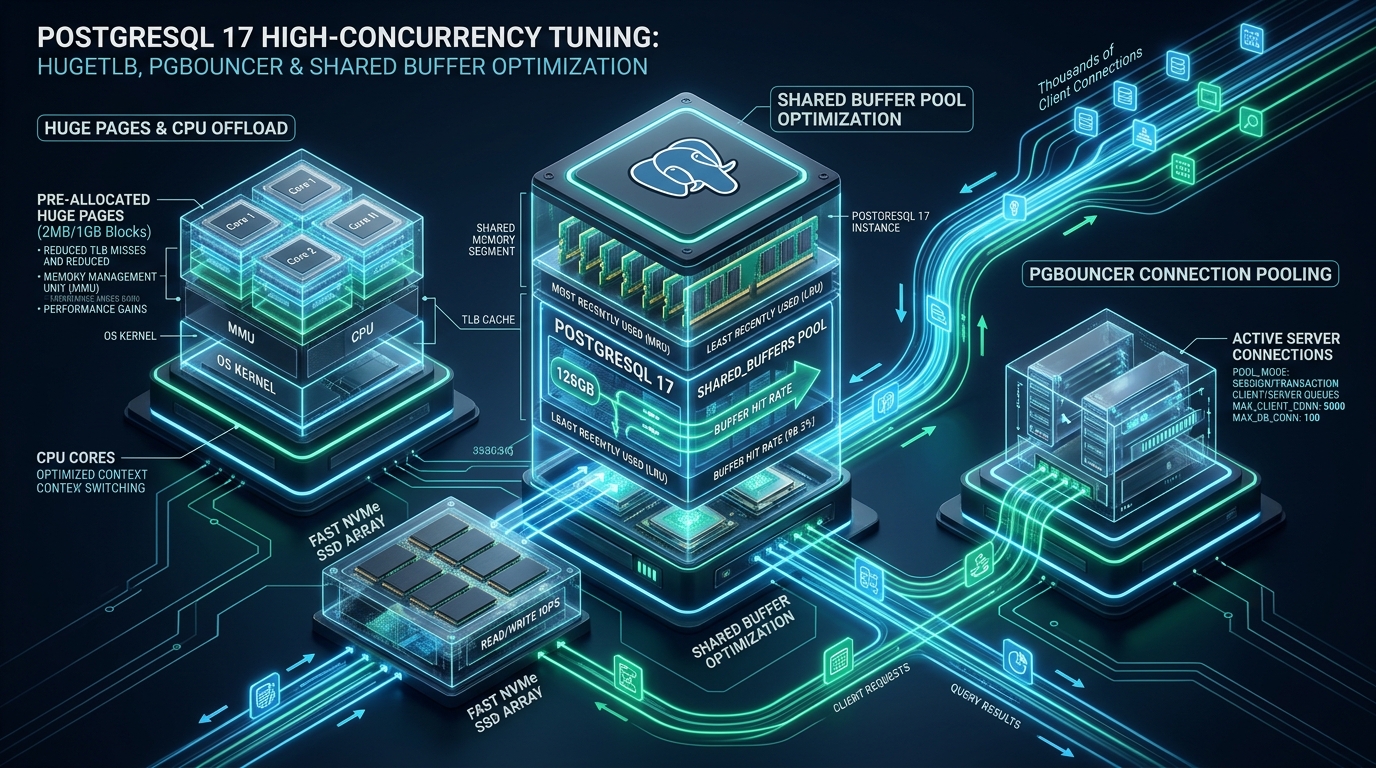
Scaling high-throughput transactional databases requires mastering the interplay between Linux kernel memory subsystems, client connection lifecycles, and shared buffer architectures. When query volume surges beyond thousands of concurrent client sessions, PostgreSQL’s traditional process-per-connection model quickly succumbs to CPU context switching, Translation Lookaside Buffer (TLB) thrashing, and severe memory overhead. At CpanelFree, our bare-metal infrastructure engineering teams leverage advanced kernel tuning, explicit Huge Pages allocation, and PgBouncer transaction-mode pooling to eliminate these bottlenecks and sustain deterministic sub-millisecond latencies under intense enterprise workloads.
Architectural Blueprint: PostgreSQL 17 Tuning PgBouncer & High Concurrency
To tune PostgreSQL 17 for high concurrency, configure PgBouncer in transaction pooling mode to cap active backend connections to 2–4× CPU cores, allocate 2MB Linux Huge Pages (
vm.nr_hugepages) matching shared_buffers (typically 25%–40% system RAM) to eliminate TLB cache thrashing, and optimize query memory with tuned work_mem and asynchronous I/O.
PostgreSQL 17 introduces monumental internal architectural improvements, including streamlined memory allocation pathways, enhanced vacuum indexing routines, and upgraded parallel execution capabilities. However, regardless of database engine improvements, attempting to attach 5,000 or 10,000 direct client TCP connections directly to the Postgres postmaster daemon will exhaust physical hardware resources. Each native backend worker process consumes between 5MB and 20MB of private RSS memory for execution plans, catalog caches, and per-process buffers. Multiplying 5,000 connections by 15MB yields over 75GB of RAM consumed merely by idle session handles—completely starving the operating system and PostgreSQL shared buffer pool.
To overcome this limitation, enterprise architects implement a three-tiered performance topology: hardware-aligned Linux kernel memory structures (Huge Pages), an ultra-lightweight connection multiplexer (PgBouncer), and precisely calibrated PostgreSQL 17 buffer caches.
Architectural Comparison: Default vs. High-Concurrency Production Tuning
The comparative matrix below details performance divergence across baseline out-of-the-box configurations versus an enterprise-tuned PostgreSQL 17 deployment operating on dedicated NVMe bare metal with PgBouncer connection multiplexing:
1. Linux Kernel Memory Hardening: Eliminating TLB Misses with Huge Pages
Modern x86_64 processors manage memory mappings through the Translation Lookaside Buffer (TLB), an on-chip hardware cache designed to convert virtual memory addresses into physical RAM locations. By default, Linux employs standard 4KB memory pages. When configuring a 32GB or 64GB PostgreSQL shared_buffers pool using standard 4KB pages, the kernel must catalog between 8,388,608 and 16,777,216 distinct page table entries.
Under heavy concurrent read/write transactions, the CPU’s limited L1/L2 TLB cache entries are constantly flushed. This causes catastrophic TLB misses, forcing processor cores into costly multi-step page table walks across physical memory buses. The solution is explicit allocation of Linux Huge Pages (Hugetlbfs), which scales individual page frames from 4KB to 2MB (a 512× reduction in page table footprint) or 1GB blocks.
To calculate the exact number of 2MB Huge Pages required for PostgreSQL 17, inspect the mapped shared memory segments while PostgreSQL is active:
# 1. Determine PostgreSQL postmaster PID
PG_PID=$(head -n 1 /var/lib/postgresql/17/main/postmaster.pid)

# 2. Calculate peak shared memory requirement in 2048 kB pages
PAGE_SIZE=2048
VMSHARED=$(grep -i VmShared /proc/$PG_PID/status | awk '{print $2}')
REQUIRED_PAGES=$(( (VMSHARED + PAGE_SIZE - 1) / PAGE_SIZE ))
echo "Allocating static Huge Pages: $REQUIRED_PAGES (total: $(( REQUIRED_PAGES * 2 )) MB)"
Persist these memory allocations, TCP socket backlogs, and memory overcommit policies inside /etc/sysctl.d/99-postgresql.conf:
# /etc/sysctl.d/99-postgresql.conf - High-Concurrency Linux Kernel Profile
# Architecture Target: 64GB RAM Dedicated Database Host

# Pre-allocate 16,500 Huge Pages (33,000 MB reserved for 32GB shared_buffers)
vm.nr_hugepages = 16500

# Prevent aggressive OOM paging; retain dirty pages in RAM
vm.swappiness = 1
vm.dirty_background_ratio = 3
vm.dirty_ratio = 10

# Disable unrestricted overcommit to guarantee shared memory stability
vm.overcommit_memory = 2
vm.overcommit_ratio = 85

# Increase IPC shared memory limits (POSIX / System V)
kernel.shmmax = 35433480192
kernel.shmall = 8650752

# Network socket backlog and connection scaling for PgBouncer ingress
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 65535
net.ipv4.tcp_fin_timeout = 15
net.ipv4.tcp_tw_reuse = 1
net.ipv4.ip_local_port_range = 1024 65535

# Increase file descriptor headroom for multi-thousand connection handling
fs.file-max = 2097152
Apply the configuration dynamically with sysctl --system, and verify that the pages are active using grep -i HugePages /proc/meminfo.
2. PostgreSQL 17 Engine Tuning: Calibrating Shared Buffers and Memory Pools
The core caching engine in PostgreSQL 17 is governed by the shared_buffers parameter. Shared buffers act as the primary in-memory cache for table tuples, indexes, and write-ahead log structures. For dedicated database servers running Linux, the general production rule is to assign 25% to 40% of total physical RAM to shared_buffers. Assigning more than 40% often yields diminishing returns because PostgreSQL relies heavily on the Linux page cache for read-ahead streaming and double-buffering writes.
In addition to shared buffers, individual query worker threads utilize work_mem for sort operations (ORDER BY), hash joins, and bitmap index scans. Setting work_mem excessively high in an environment with hundreds of concurrent connections will provoke immediate Out-Of-Memory (OOM) killer terminations because a single complex query containing three joins and a sort can allocate four distinct work_mem chunks simultaneously.
work_mem from the default 4MB up to 32MB or 64MB without risking OOM crashes. This guarantees that complex analytical aggregations and hash tables execute entirely in L3/RAM without touching temporary disk files.
Deploy the following hardened configuration file to /etc/postgresql/17/main/conf.d/99-high-concurrency.conf:
# /etc/postgresql/17/main/conf.d/99-high-concurrency.conf
# Tuned for 64GB RAM, 16 vCPU Bare-Metal NVMe Host with PgBouncer Multiplexing

# Connection Pool Sizing (Postgres worker floor matched to CPU cores)
max_connections = 150
superuser_reserved_connections = 5

# Memory Allocation & Huge Pages
huge_pages = on
shared_buffers = 16GB
effective_cache_size = 48GB
work_mem = 32MB
maintenance_work_mem = 2GB

# Checkpoint Tuning & WAL Stream Stability
wal_buffers = 64MB
min_wal_size = 2GB
max_wal_size = 16GB
checkpoint_completion_target = 0.9
checkpoint_timeout = 15min

# Disk I/O & Parallelism for High-Speed NVMe Storage
random_page_cost = 1.1
effective_io_concurrency = 300
max_worker_processes = 16
max_parallel_workers = 16
max_parallel_workers_per_gather = 4
max_parallel_maintenance_workers = 4

# Query Planner & Lock Contention Mitigation
default_statistics_target = 200
jit = off                           # Disable JIT for high-concurrency OLTP to avoid compilation overhead
track_io_timing = on
track_functions = all
3. PgBouncer Architecture: Mastering Transaction-Mode Connection Multiplexing
To scale from 150 backend database workers to 10,000 active application threads, PgBouncer serves as the mission-critical connection pooler. PgBouncer maintains persistent, authenticated connection sockets directly to PostgreSQL 17 while presenting a lightning-fast asynchronous event loop (powered by libevent) to inbound clients.
PgBouncer supports three primary pooling modes:
- Session Pooling: Holds a server connection for the entire duration of a client session. Useful for legacy applications that rely heavily on session-level prepared statements, but does not provide massive connection consolidation.
- Transaction Pooling (Recommended): Allocates a PostgreSQL server connection to a client exclusively for the duration of a single database transaction block (
BEGIN ... COMMIT). The instant the transaction commits, the physical backend socket returns to the pool for another client. This achieves 50:1 to 100:1 connection multiplexing. - Statement Pooling: Assigns connections per individual query. Disallows multi-statement transactions; rarely suitable for modern web applications.
SET timezone, temporary tables, listen/notify channels, and non-named prepared statements—must be handled cautiously. In PostgreSQL 17 and PgBouncer 1.21+, use protocol-level named prepared statement support (max_prepared_statements = 100) to maintain execution speed without breaking transaction isolation.
Here is a complete, production-grade /etc/pgbouncer/pgbouncer.ini configuration file optimized for handling 10,000 client sockets:
;; /etc/pgbouncer/pgbouncer.ini - Enterprise Concurrency Sizing
[databases]
* = host=127.0.0.1 port=5432 auth_user=pgbouncer_auth

[pgbouncer]
logfile = /var/log/postgresql/pgbouncer.log
pidfile = /var/run/postgresql/pgbouncer.pid
listen_addr = *
listen_port = 6432
auth_type = scram-sha-256
auth_file = /etc/pgbouncer/userlist.txt
auth_query = SELECT usename, passwd FROM public.pgbouncer_get_auth($1)

;; Connection Pool Architecture
pool_mode = transaction
max_client_conn = 10000
default_pool_size = 64
min_pool_size = 16
reserve_pool_size = 16
reserve_pool_timeout = 2.0
max_db_connections = 120

;; Timeout & Liveness Enforcements
server_reset_query = DISCARD ALL
server_check_delay = 10.0
server_check_query = SELECT 1
server_idle_timeout = 600.0
client_idle_timeout = 300.0
query_timeout = 30.0

;; Buffer Tuning & Prepared Statements
max_prepared_statements = 100
pkt_buf = 4096
listen_backlog = 4096
so_reuseport = 1
To avoid operating system thread exhaustion and socket starvation under load, configure the systemd unit drop-in override for PgBouncer by creating /etc/systemd/system/pgbouncer.service.d/override.conf:
# /etc/systemd/system/pgbouncer.service.d/override.conf
[Service]
LimitNOFILE=65536
LimitNPROC=32768
Restart=always
RestartSec=3s
4. Production Verification: Benchmarking and Real-Time Observability
To confirm that PostgreSQL 17, Huge Pages, and PgBouncer are operating synchronously without packet dropped queues or lock thrashing, execute automated synthetic stress tests using pgbench.
Initialize a high-scale benchmark schema (Scale Factor 500 = ~7.5GB database data) and launch a concurrency stress run simulating 2,000 clients across 64 worker threads targeting the PgBouncer port (6432):
# Initialize pgbench dataset with scale factor 500
pgbench -i -s 500 -p 6432 -h 127.0.0.1 -U app_user production_db

# Execute a 60-second multi-thread benchmark simulating 2,000 clients
pgbench -c 2000 -j 64 -T 60 -P 5 -M prepared -p 6432 -h 127.0.0.1 -U app_user production_db
During test execution, run this real-time SQL diagnostic query to inspect cache hit ratios across all active database schemas:
SELECT
    datname,
    numbackends AS active_connections,
    blks_read AS disk_blocks_read,
    blks_hit AS buffer_blocks_hit,
    ROUND((blks_hit::numeric / NULLIF(blks_hit + blks_read, 0)) * 100, 2) AS buffer_hit_ratio,
    temp_files AS temp_disk_spills,
    pg_size_pretty(temp_bytes) AS temp_bytes_written
FROM pg_stat_database
WHERE datname = current_database();
A properly tuned PostgreSQL 17 instance backed by Huge Pages and sized buffer pools will maintain a buffer_hit_ratio consistently above 99.0%, with temp_files registering zero for OLTP workloads.
Frequently Asked Questions
Why does PostgreSQL 17 require static Huge Pages instead of Transparent Huge Pages (THP)?
Transparent Huge Pages (THP) allocates 2MB memory blocks opportunistically via background kernel defragmentation (khugepaged). Under high write concurrency, this background compaction triggers severe memory allocation latencies and CPU spikes known as “TLB shootdowns.” Static Huge Pages are pinned in physical RAM at system boot via vm.nr_hugepages, guaranteeing zero page-fault latency, immutable allocation, and zero memory swapping for PostgreSQL’s shared buffer pool.
How does PgBouncer transaction pooling handle prepared statements in PostgreSQL 17?
Historically, transaction pooling broke application-level prepared statements because statements prepared on one server socket were unknown when the client acquired a different backend socket for its next transaction. Starting in modern PgBouncer releases (1.21+), PgBouncer intercepts named prepared statements using the PostgreSQL extended query protocol and synchronizes statement definitions automatically across backend pools when max_prepared_statements is enabled.
What is the optimal ratio between PostgreSQL max_connections and CPU cores?
The ideal number of active backend database workers is generally formulated as (2 * CPU_Cores) + Effective_Spindle_Count. On a 16-core NVMe server, setting max_connections to between 32 and 64 backend workers maximizes CPU cache locality and minimizes context switching. All inbound connection volume (e.g. 5,000 to 10,000 clients) should terminate at PgBouncer, which queues and streams transactions through the small, hyper-efficient backend worker pool.
How can I diagnose whether my PostgreSQL instance is actively using Huge Pages?
Set huge_pages = on in postgresql.conf (or try during testing). If PostgreSQL starts successfully, it has bound to Hugetlbfs. You can confirm active utilization by executing grep -i HugePages /proc/meminfo in Linux. The HugePages_Rsvd and HugePages_Free counters will reflect the exact page count reserved by the active PostgreSQL postmaster process.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.