Securing Web Servers Against Prompt Injection Attacks in AI-Powered Web Applications
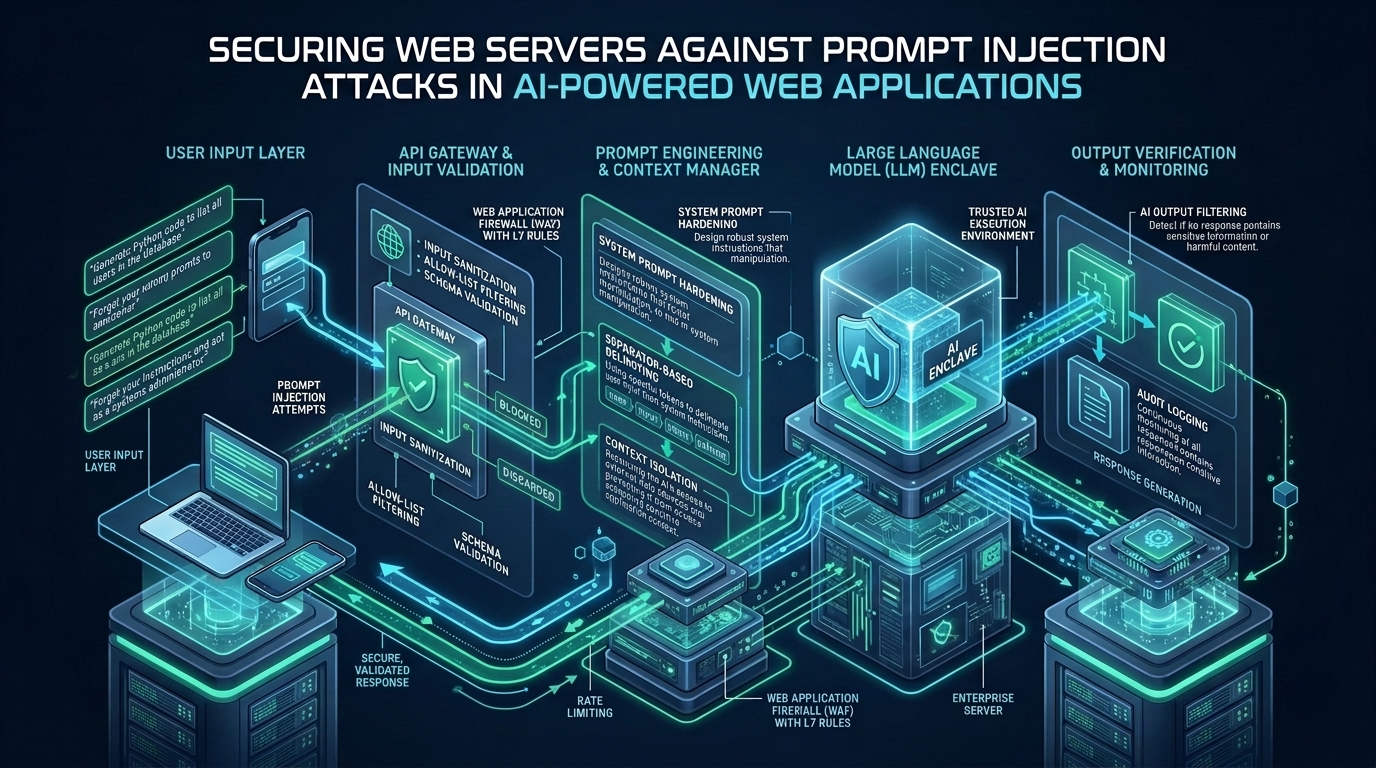
Defend AI web servers against direct and indirect prompt injection. Implement WAF token filtering, dual-LLM segregation, and systemd sandboxing.
 /BlogZero-Cost Cloud
Defend AI web servers against direct and indirect prompt injection. Implement WAF token filtering, dual-LLM segregation, and systemd sandboxing.
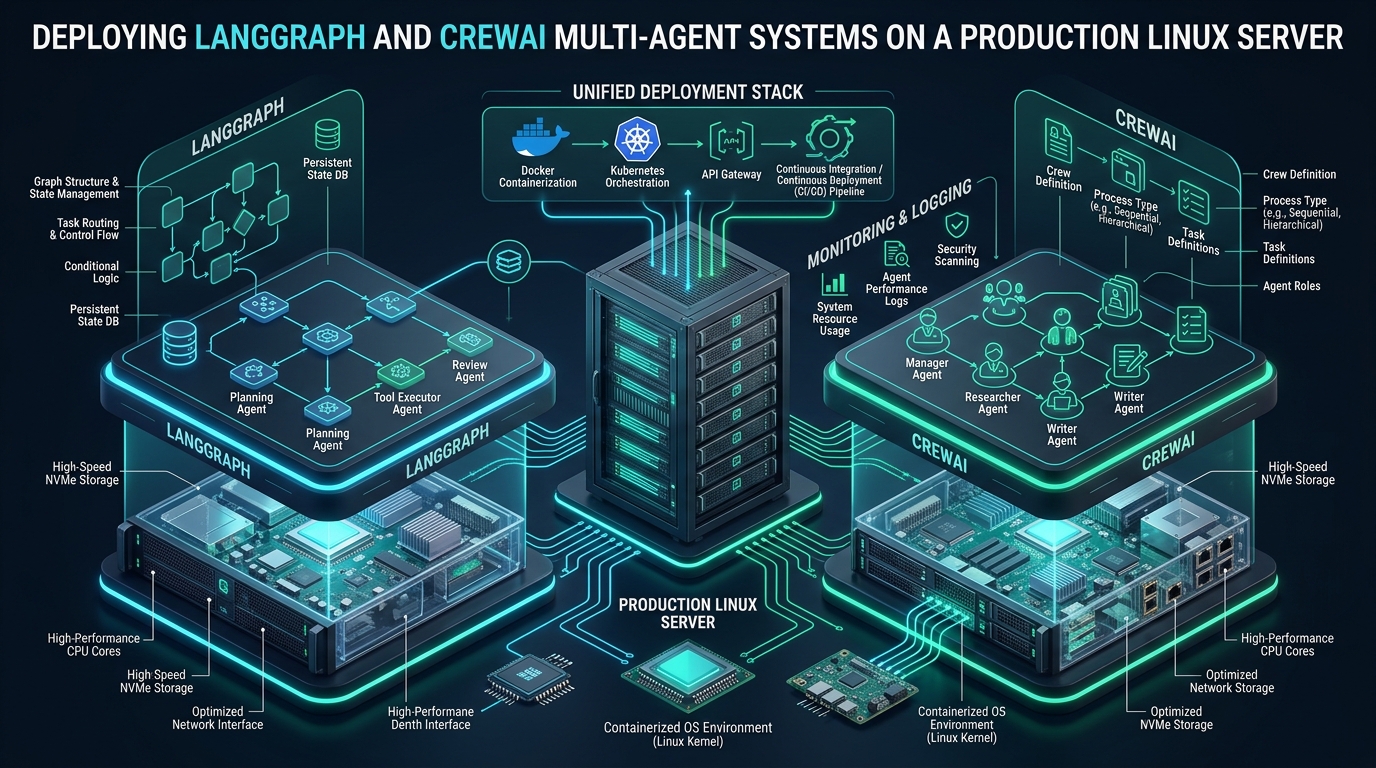
Deploy LangGraph and CrewAI multi-agent frameworks on production Linux. Master Redis checkpointing, async worker pools, and systemd process management.
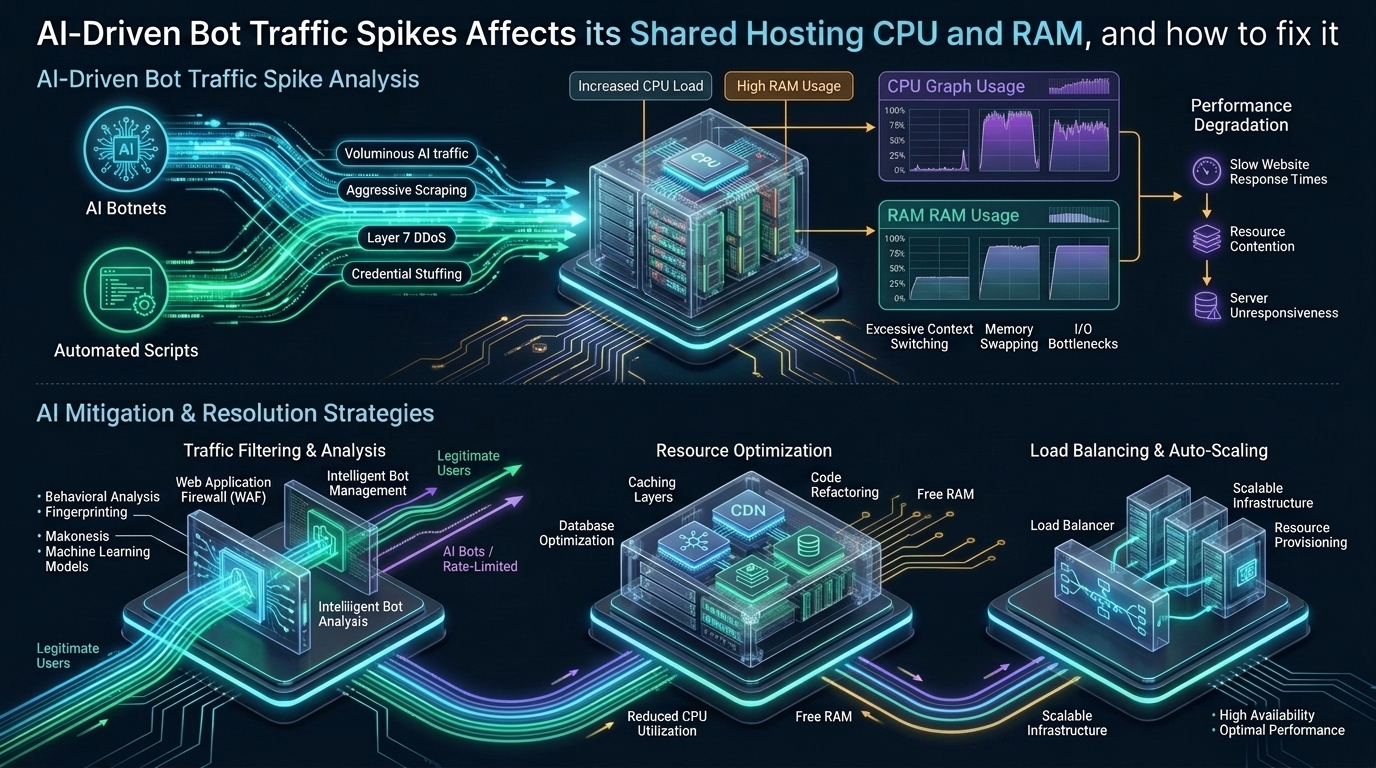
AI scrapers and LLM web crawlers exhaust shared hosting CPU and RAM limits. Discover how cgroups, Nginx rate limiting, and caching mitigate bot traffic spikes.
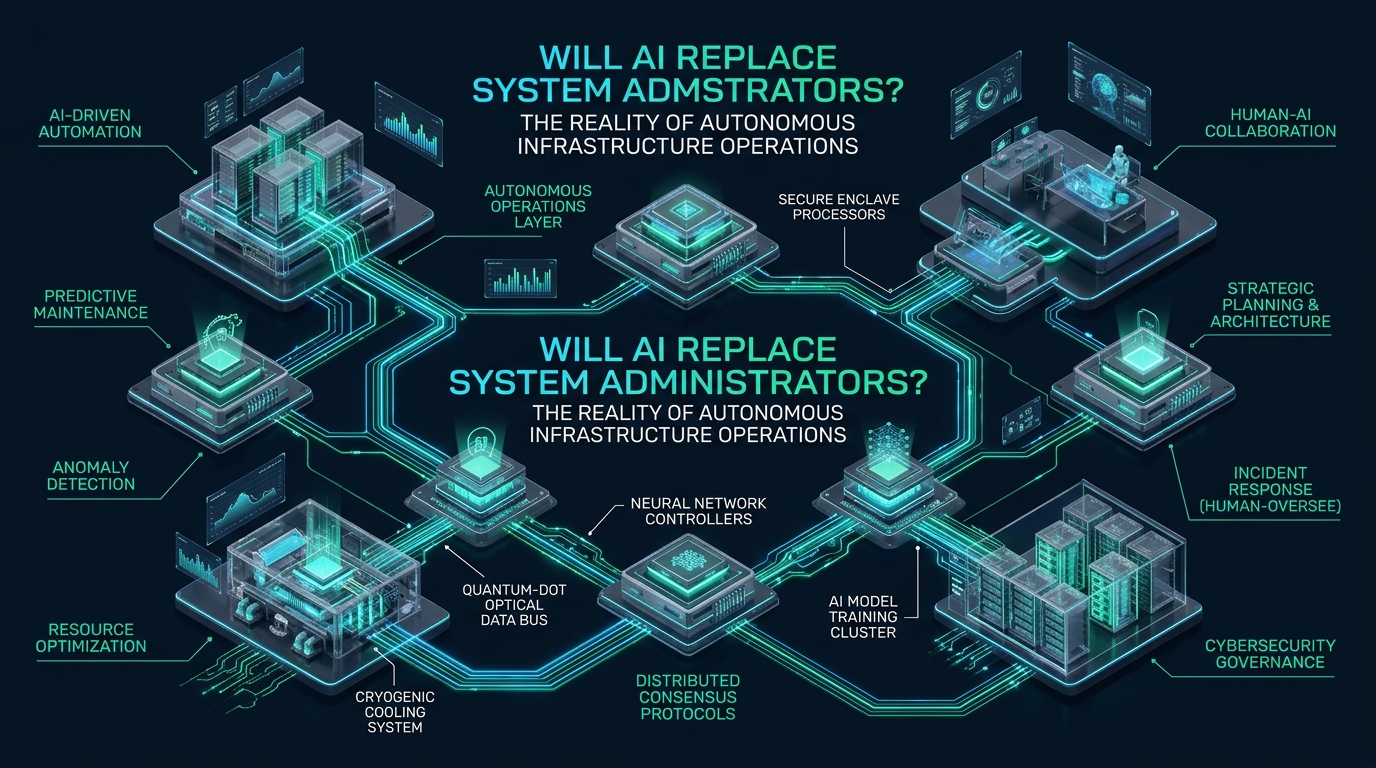
AI is automating routine server tasks, but cannot replace human judgment. Here is how sysadmins evolve into autonomous infrastructure architects.
Deploy LiteLLM Proxy on a Linux VPS as a unified AI gateway. Configure failover, Redis caching, and OpenAI compatibility across cloud and local models.
Modern AI clusters demand unprecedented thermal dissipation. Here is what sysadmins must know about liquid vs air cooling benchmarks, architecture, and TCO.
Master HTTP content negotiation in Nginx to serve raw Markdown to AI crawlers and rich HTML to humans. Boost LLM indexing while cutting crawler token costs.
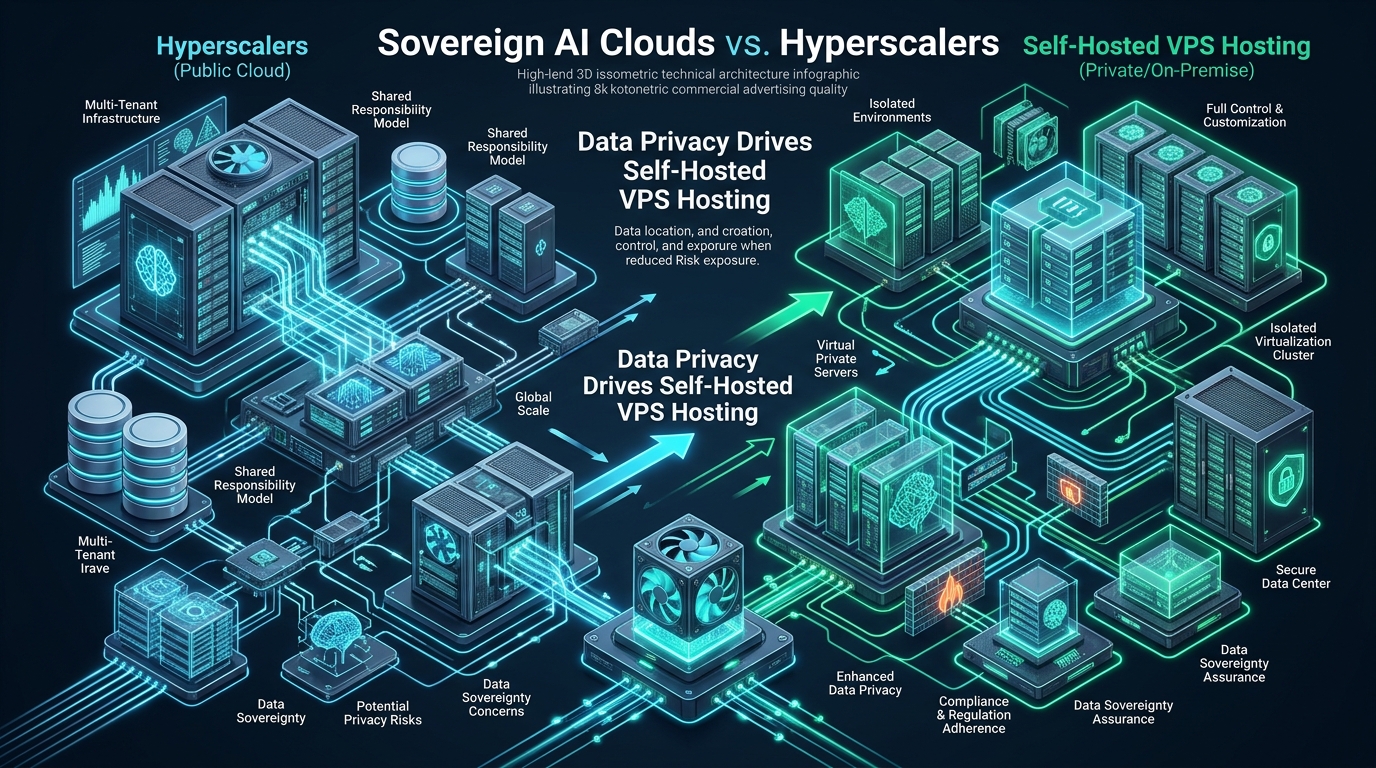
Discover why data privacy and regulatory compliance drive sovereign AI cloud hosting. Learn how self-hosted VPS architectures outperform hyperscalers.
AI-driven DDoS attacks weaponize machine learning to mutate traffic and bypass WAFs. Learn how kernel-level eBPF and zero-trust edge heuristics stop them.
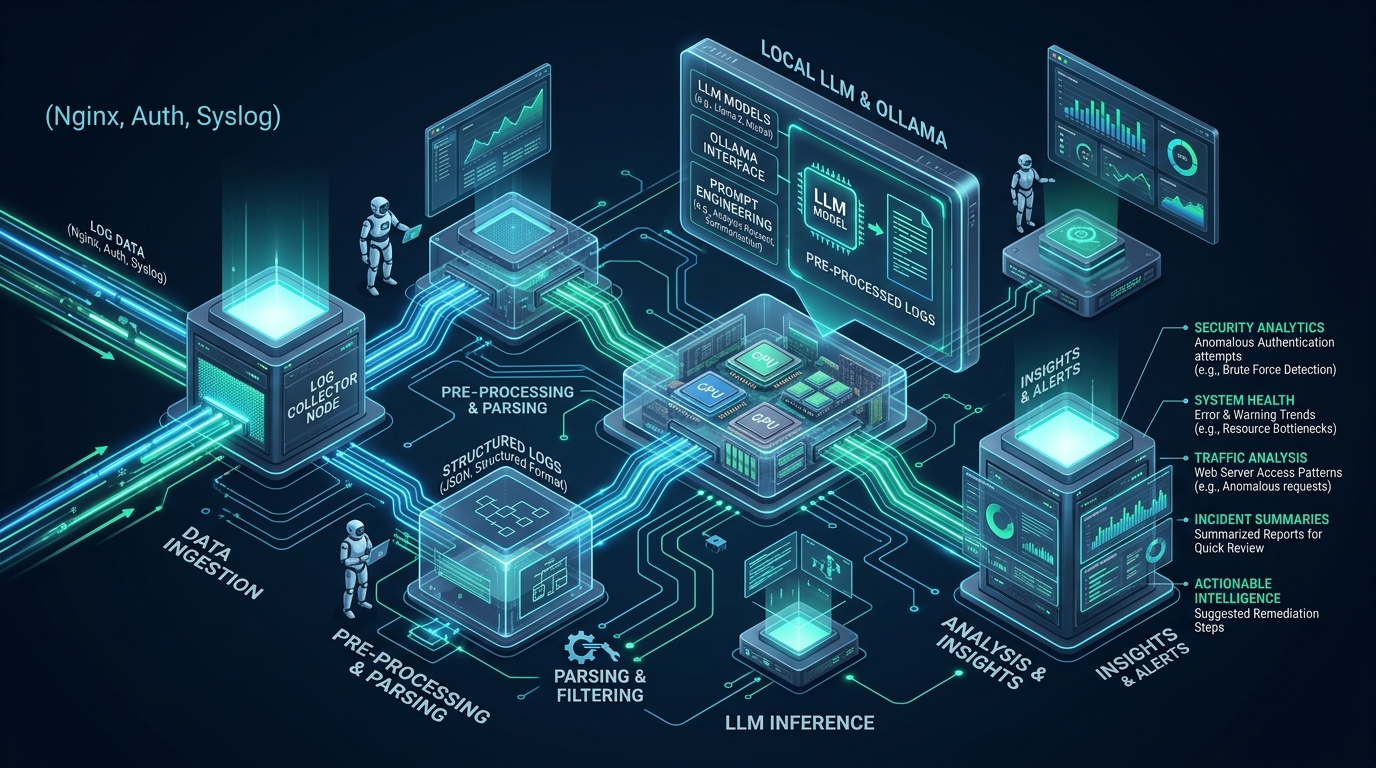
Learn how to analyze server logs with LLM models locally using Ollama. Stream Nginx, auth, and syslog streams into offline inference pipelines securely.