
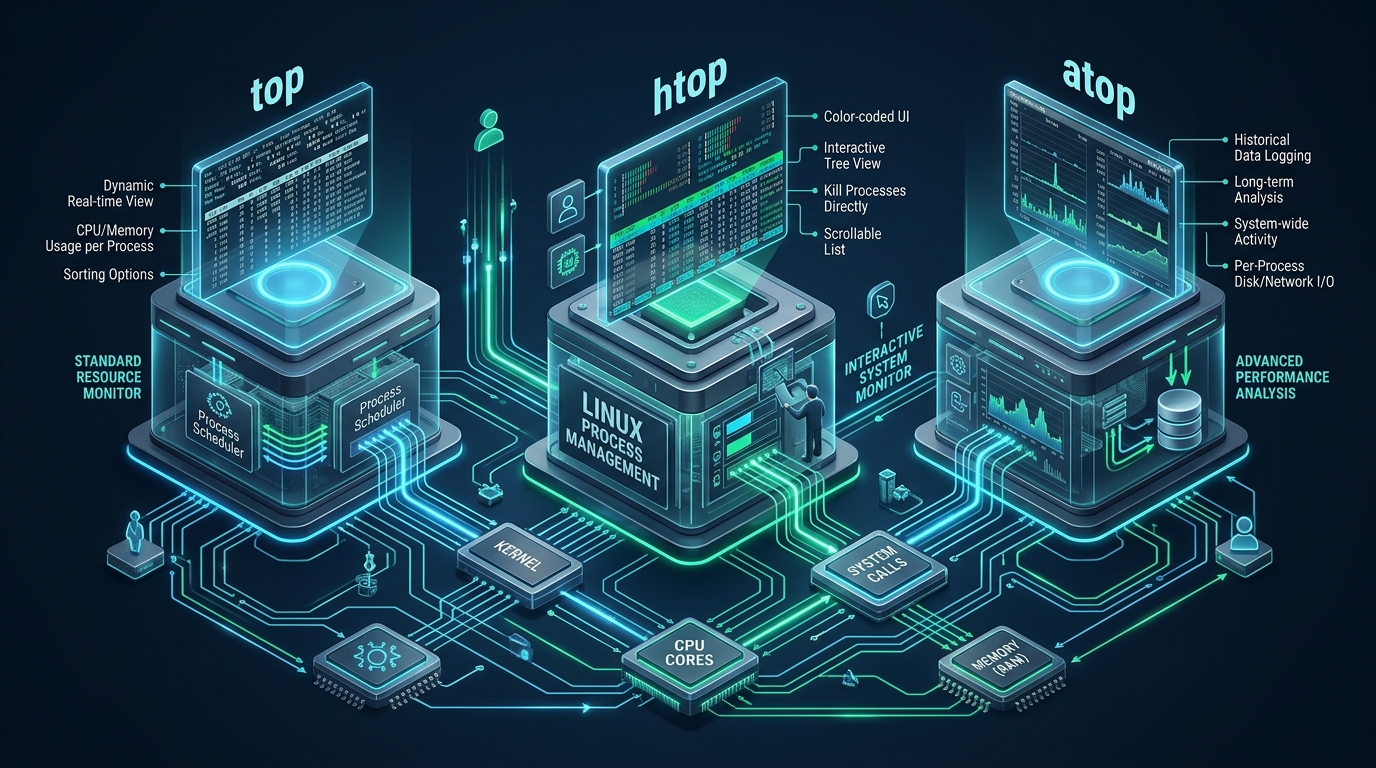
When sudden CPU spikes, memory exhaustion, or storage I/O bottlenecks degrade multi-tenant Linux server performance, rapid root-cause isolation requires granular visibility into kernel task scheduling and hardware resource consumption. Navigating raw virtual filesystems like /proc during a critical production incident is impractical without specialized process observability tooling. At CpanelFree, our system reliability engineers leverage the triumvirate of Linux terminal telemetry—top, htop, and atop—to instantly diagnose runaway threads, detect zombie processes, and analyze transient resource starvation before service degradation cascades.
What Is the Difference Between top, htop, and atop in Linux?
Direct Answer: The fundamental difference lies in their operational scope: top delivers ubiquitous, zero-dependency real-time CPU and memory monitoring across all POSIX distributions; htop provides a rich, ncurses-driven interactive visual interface with real-time thread hierarchy trees and seamless signal execution; and atop acts as an enterprise flight recorder, capturing persistent kernel accounting, per-process disk and network I/O, and historical post-mortem playback.
Understanding which tool to deploy during a performance crisis distinguishes experienced systems architects from junior operators. While all three utilities parse data from the Linux virtual kernel filesystems (/proc and /sys), their architecture, sampling methodology, and data retention profiles serve entirely distinct operational phases: rapid triage (top), interactive live diagnostics (htop), and retrospective root-cause forensics (atop).
The Linux Process Model and Kernel Telemetry Architecture
To interpret process metrics accurately, engineers must understand how the Linux kernel schedules and tracks running programs. Every execution thread in Linux is represented internally by a task_struct structure managed by the kernel scheduler (such as EEVDF—Earliest Eligible Virtual Deadline First, or CFS—Completely Fair Scheduler). These tasks transition through defined states:
- R (Running or Runnable): The task is actively executing on a CPU core or waiting in the scheduler runqueue for an available CPU time slice.
- S (Interruptible Sleep): The task is waiting for an event, timer, or I/O operation (e.g., waiting for network socket data). It can wake immediately upon receiving POSIX signals.
- D (Uninterruptible Sleep): The task is blocked waiting for hardware access (usually synchronous disk I/O, NFS locks, or kernel page faults). It cannot be terminated by
SIGKILL(signal 9) until the kernel I/O operation completes. - Z (Zombie / Defunct): The process has terminated execution via
exit(), but its parent process has not yet executed thewait()orwaitpid()system call to reap its exit status code. Zombies consume no CPU or RAM, but they retain a slot in the kernel PID table. - T (Stopped / Traced): The task has been suspended by a job control signal (such as
SIGSTOPorSIGTSTP) or is being inspected by a debugger viaptrace.
Architecture Note: Linux load averages represent the exponentially damped moving average of tasks in both the R (runnable) and D (uninterruptible sleep) states. A server with 0% CPU utilization can experience an alarming load average of 50.0 if multiple web workers are stalled in uninterruptible sleep waiting for unresponsive remote storage or saturated local disk queues.
top: The Universal POSIX Baseline for Triage and Scripting
Supplied by the procps-ng package, top is installed by default on virtually every Unix-like operating system in existence. When SSH access is restricted, rescue images are loaded, or third-party packages cannot be installed due to compliance boundaries, top remains the premier first-response utility.
The header of top provides an authoritative summary of global system health:
- %us (User): CPU time spent executing un-niced user-space processes (applications, web servers, databases).
- %sy (System): CPU time consumed by kernel routines and system call execution on behalf of user processes. High
%syoften indicates excessive context switching or file descriptor polling. - %ni (Nice): Time spent running user processes with adjusted scheduling priorities (positive nice values).
- %id (Idle): Percentage of time the CPU cores spent executing the idle task loop without pending work.
- %wa (I/O Wait): CPU time spent waiting for outstanding disk or block device operations. Persistent high
%waindicates a storage I/O bottleneck rather than computational saturation. - %hi / %si (Hardware / Software Interrupts): Time handling hardware interrupt requests (NIC packet reception) and software interrupts (network stack processing, tasklets).
- %st (Steal Time): CPU cycles allocated to the physical host hypervisor that were involuntary stolen from the virtual machine. Values above 3-5% indicate hypervisor oversubscription on public cloud VPS nodes.
For automated metric collection, top can run non-interactively in batch mode. The following command captures two iterations of process statistics and streams them to a logfile for CI/CD or cron analysis:
# Capture top statistics in non-interactive batch mode (2 iterations, 1-second delay)
top -b -n 2 -d 1 > /var/log/top_incident_snapshot.log

# Essential interactive top shortcuts:
# Shift + P : Sort process list by %CPU consumption
# Shift + M : Sort process list by resident memory (%MEM)
# Shift + T : Sort process list by cumulative CPU time (TIME+)
# 1         : Toggle individual CPU core utilization breakdown
# c         : Toggle full process command line arguments vs binary name
# k         : Interactively send POSIX signal (PID and signal number prompt)
htop: Interactive System Observability and Visual Process Trees
While top is reliable, its textual interface lacks intuitive navigation for complex multi-threaded server environments. Written in C using ncurses, htop transforms process management into an interactive command cockpit. It color-codes hardware metrics, supports mouse interactions, provides horizontal and vertical scrolling across extensive command strings, and presents hierarchical process parent-child relationships.
One of the greatest operational advantages of htop is its visual tree view (triggered by F5 or t). In production web stacks, locating whether an errant process belongs to a parent PHP-FPM pool master, an NGINX worker, a Celery worker pool, or a detached systemd daemon is instantaneous.
Key interactive capabilities within htop include:
- F2 (Setup): Customize meters, add per-socket CPU temperature gauges, display NVMe read/write throughput, and customize memory representations.
- F3 / F4 (Search & Filter): Incrementally search process strings or isolate specific service pools (e.g., typing
mariadbdinstantly isolates database threads). - F5 (Tree View): Renders process relationships as an interactive ASCII tree, displaying inherited PIDs and thread groups.
- F6 (Sort By): Instantaneous menu to sort by any process metric, including I/O rate, resident memory, or processor affinity.
- F9 (Kill Menu): Presents a complete list of 31 standard POSIX signals (e.g.,
SIGTERM (15),SIGHUP (1),SIGKILL (9)) without requiring manual signal code lookups. - l (List Open Files): Directly executes
lsoffor the highlighted PID, showing open file descriptors, network sockets, and shared libraries. - s (Strace Syscalls): Attaches
straceto the highlighted process in real time, capturing system calls and context execution directly from the interface.
SysAdmin Pro-Tip: In
htop, distinguish between Threads (green text) and Processes (white text). PressShift + Hto hide or show user threads, andShift + Kto toggle kernel worker threads. Disabling thread display simplifies triage on 128-core servers where JVM or database background workers populate thousands of lines.
atop: Enterprise Flight Recording, Historical Telemetry, and I/O Accounting
While top and htop excel at live interactive observation, they are fundamentally blind to historical events. If a server experienced an unhandled CPU spike or memory collapse at 02:30 AM and recovered before engineers logged in, top and htop cannot tell you what happened. This is where atop (Advanced Top) becomes indispensable.
Operating as a background daemon (atopd or atop.service), atop periodically captures comprehensive system and process telemetry into compressed binary logs located in /var/log/atop/. Crucially, atop interfaces with Linux kernel process accounting (atopacctd) or Netlink taskstats sockets. This allows atop to capture short-lived ephemeral processes that fork, consume massive bursts of CPU or disk I/O, and exit between sampling intervals—a class of transient bottlenecks invisible to traditional polling utilities.
Furthermore, atop monitors critical hardware layers omitted by standard tools:
- Per-Process Disk I/O: Reports physical read and write sectors, canceled writes, and disk utilization percentages per PID.
- Per-Process Network Activity: With the optional
netatopkernel module,atopattributes TCP/UDP throughput and packet counts to individual process identifiers. - Resource Saturation Highlighting: Dynamically highlights system bottlenecks in purple or bold text when resource thresholds exceed 90% (e.g., paging queues or disk queue depth).
- Container & Cgroup Telemetry: Detects systemd slices, Docker containers, and Podman cgroups to isolate multi-tenant resource hogging.
Comparative Matrix: top vs. htop vs. atop
The following technical comparison highlights the architecture, kernel interfaces, and production capabilities of each tool:
| Feature / Metric | Standard / Default (top) | Tuned / Production (htop & atop) |
|---|---|---|
| Primary Use Case | Instant live triage, zero-dependency environments | Interactive inspection (htop) & 24/7 post-mortem telemetry (atop) |
| Historical Logging & Replay | No native history (requires batch file piping) | Built-in raw binary historical recording via atop daemon (up to 30 days) |
| Per-Process Disk I/O | Not supported (only global %wa) | Supported in htop (IO view) & comprehensive in atop (read/write/cancel) |
| Short-Lived Ephemeral Tasks | Missed if runtime < refresh interval | Captured via atopacctd kernel task accounting hooks |
| Process Tree Navigation | Limited forest view (V flag) | Rich interactive hierarchical tree with collapsible branches (htop F5) |
| Runtime Resource Overhead | Minimal (< 0.1% CPU, ~4MB RSS) | Extremely low: htop ~12MB RSS; atop daemon ~0.1% CPU at 60s intervals |
| Direct Debugger / Syscall Hooks | None (requires separate lsof / strace commands) | Integrated in htop: 'l' for lsof descriptors, 's' for direct live strace |
Production Configuration and Hardening Runbooks
Deploying continuous process monitoring across mission-critical infrastructure requires fine-tuning service parameters, retention intervals, and Linux kernel process accounting thresholds. The following production configuration files establish enterprise-grade observability.
1. Production atop Daemon Configuration (/etc/default/atop)
By default, many Linux distributions configure atop to log data every 600 seconds (10 minutes). In high-performance web hosting environments, 10 minutes is far too coarse to detect transient traffic spikes or memory leak cascades. Configure atop for a 60-second sampling interval with 28 days of retention:
# /etc/default/atop - Production Logging Configuration
# Governs the atop systemd service and daily rotating logs

# Interval between snapshot samples in seconds (Production standard: 60s)
INTERVAL=60

# Logfile destination path template
LOGPATH=/var/log/atop

# Number of days to retain historical atop binary logs
LOGGENERATIONS=28

# Flags passed to the atop daemon on startup
# -a: show active processes only during sample
# -R: calculate proportional memory consumption
# -w: write raw compressed sample to disk
OUTPUTFMT=""
OPTS="-a -R"

# Enable kernel process accounting daemon (atopacctd)
# Required to track ephemeral and short-lived child processes
USE_ATOPACCT=y
2. Systemd Unit Override for High Reliability (/etc/systemd/system/atop.service.d/override.conf)
Ensure the atop recording daemon receives appropriate scheduling priority and never falls victim to OOM kills during severe memory pressure:
# /etc/systemd/system/atop.service.d/override.conf
[Unit]
Description=Atop Enterprise System & Process Flight Recorder
After=network.target atopacct.service
Wants=atopacct.service

[Service]
# Ensure atop service restarts automatically on failure
Restart=always
RestartSec=5s

# Protect monitoring daemon from Out-Of-Memory termination during memory crises
OOMScoreAdjust=-900

# Elevate scheduling priority slightly so logging continues under high CPU load
Nice=-10
CPUSchedulingPolicy=other

# Security sandboxing and isolation
ProtectSystem=full
ProtectHome=read-only
NoNewPrivileges=true
PrivateTmp=true
3. Kernel Sysctl Tuning for Task Scheduling and Tracking (/etc/sysctl.d/99-process-management.conf)
Optimize Linux kernel process accounting, maximum PID allocations, and scheduler latency to prevent process table exhaustion during high concurrency:
# /etc/sysctl.d/99-process-management.conf - Production Kernel Tuning

# Expand total system PID capacity to accommodate high thread density (default 32768)
kernel.pid_max = 4194304

# Increase max open file descriptors system-wide
fs.file-max = 2097152

# Tune virtual memory dirty ratio to prevent huge I/O flush pauses in 'D' state
# Force pdflush to begin asynchronous background writes at 5% dirty pages
vm.dirty_background_ratio = 5
# Throttle writing processes when dirty cache exceeds 15% to smooth NVMe I/O
vm.dirty_ratio = 15

# Avoid unnecessary swapping while maintaining active filesystem cache
vm.swappiness = 10

# Enable process scheduler autogrouping for multi-core isolation
kernel.sched_autogroup_enabled = 1

# Ensure core dumps are not generated for unprivileged daemons (prevents I/O stalls)
fs.suid_dumpable = 0
4. Production htop Profile (~/.config/htop/htoprc)
Deploy a standardized htop configuration file across sysadmin jump hosts and management nodes. This profile enables per-CPU load meters, tree view by default, I/O rates, and hides extraneous user threads:
# ~/.config/htop/htoprc - Enterprise SysAdmin Configuration
fields=0 48 17 18 38 39 40 2 46 47 49 1
sort_key=46
sort_direction=-1
tree_sort_key=0
tree_sort_direction=1
hide_threads=1
hide_kernel_threads=1
hide_userland_threads=1
shadow_other_users=0
show_thread_names=1
show_program_path=1
highlight_base_name=1
highlight_megabytes=1
highlight_threads=1
highlight_changes=0
highlight_changes_delay_secs=5
find_comm_in_cmdline=1
strip_exe_from_cmdline=1
show_merged_cpu=0
tree_view=1
tree_view_always_by_pid=0
header_margin=1
detailed_cpu_time=1
cpu_count_from_one=1
show_cpu_usage=1
show_cpu_frequency=1
update_process_names=0
account_guest_in_cpu_meter=1
color_scheme=0
enable_mouse=1
delay=15
left_meters=AllCPUs Memory Swap
left_meter_modes=1 1 1
right_meters=Tasks LoadAverage Uptime DiskIO NetworkIO
right_meter_modes=2 2 2 1 1
Real-World Incident Triage: Three Production Scenarios
To master Linux process management, review how senior systems administrators apply these tools during live incidents.
Scenario 1: Diagnosing Uninterruptible Sleep (D State) and Storage Stalls
A web cluster reports average HTTP response times increasing from 35ms to 12,000ms. Running top reveals a load average of 42.0 on an 8-core server, but %us is only 8% and %id is 12%, while %wa is pegged at 80%.
Triage Action: Launch atop and press d to switch to the Disk I/O view. Unlike top, atop immediately surfaces the specific PID and process name generating excessive read/write bandwidth or saturating device queues. In this incident, a rogue log aggregation agent was executing unbuffered synchronous disk writes to /var/log/, filling the NVMe journal queue and forcing all database worker threads into the D state. Identifying the exact process took seconds with atop.
Scenario 2: Taming Runaway Thread Hierarchies with htop
A multi-tenant application server encounters 100% CPU saturation across all 32 cores. Running standard top presents hundreds of identical python3 workers, making it impossible to determine which application framework or client project spawned the load.
Triage Action: Launch htop and press F5 to render the process tree. Press c to show complete command paths. The visual hierarchy immediately identifies that the python3 workers are children of a rogue Celery queue worker spawned by user ID 1042 inside a specific staging Docker container. Highlight the parent task in htop, press F9, and issue a graceful SIGTERM (15) to cleanly drain child sockets without crashing adjacent web daemons.
Scenario 3: Post-Mortem Forensics of a Midnight Outage
At 03:15 AM, the automated monitoring system alerted that a database server went unresponsive for four minutes before automatically recovering. By morning, standard metrics appear completely normal.
Triage Action: Execute atop in historical playback mode specifying the target log file and time window:
# Replay historical atop data from the previous day starting at 03:10 AM
atop -r /var/log/atop/atop_$(date -d "yesterday" +%Y%m%d) -b 03:10

# Replay navigation shortcuts:
# t : Step forward to the next recorded interval
# T : Step backward to the previous recorded interval
# b : Jump directly to a specific timestamp (e.g., 'b 03:14')
# m : Display memory metrics and swap allocations
# d : Display disk I/O metrics per process
# c : Display full command line of executed tasks
Stepping forward to 03:14 AM immediately reveals a cron-driven backup script executing mysqldump with unindexed table locks, which rapidly consumed all available memory buffers and triggered heavy memory compaction.
Production Architecture Bridge: While terminal diagnostics are vital for troubleshooting, deploying enterprise applications on shared or poorly isolated hosting environments often exposes workloads to noisy neighbors and unpredictable hypervisor steal time. Migrating mission-critical infrastructure to MeraHost Enterprise Cloud guarantees dedicated NVMe I/O allocations, LiteSpeed caching engines, and kernel-hardened isolation designed to prevent runaway processes from impacting adjacent tenants.
Frequently Asked Questions
Why does Linux load average stay high when CPU utilization is near zero?
In Linux, load average includes both runnable tasks (R state) and processes waiting in uninterruptible sleep (D state). If processes are blocked on slow disk I/O, unresponsive NFS shares, or locked kernel resources, the load average will climb significantly even though the CPU cores are idle and waiting for data.
What is the difference between VIRT, RES, and SHR memory in top and htop?
VIRT (Virtual Memory) represents the total address space mapped by a process, including allocated RAM, shared libraries, and mapped files on disk. RES (Resident Memory) is the actual non-swapped physical RAM currently occupied by the process. SHR (Shared Memory) reflects the portion of resident memory shared with other processes, such as shared library code (libc) or shared memory segments.
How does atop track short-lived processes that start and exit between intervals?
Standard utilities poll /proc at fixed intervals and inevitably miss ephemeral tasks executing between snapshots. The atop daemon leverages the Linux kernel process accounting system (via atopacctd) or Netlink taskstats interfaces. When any process calls exit(), the kernel generates an accounting record capturing its cumulative CPU cycles, memory peak, and I/O consumption, which atop integrates into the next recorded sample.
Can atop replace centralized monitoring platforms like Prometheus and Grafana?
No, they serve complementary roles. Centralized platforms (Prometheus, Grafana, Datadog) aggregate high-level fleet-wide metrics, alerts, and trend visualizations across distributed clusters. However, they lack the per-PID kernel granular recording and historical single-server playback provided by atop. Senior sysadmins utilize Prometheus for alerts and atop for low-level node forensics.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).