
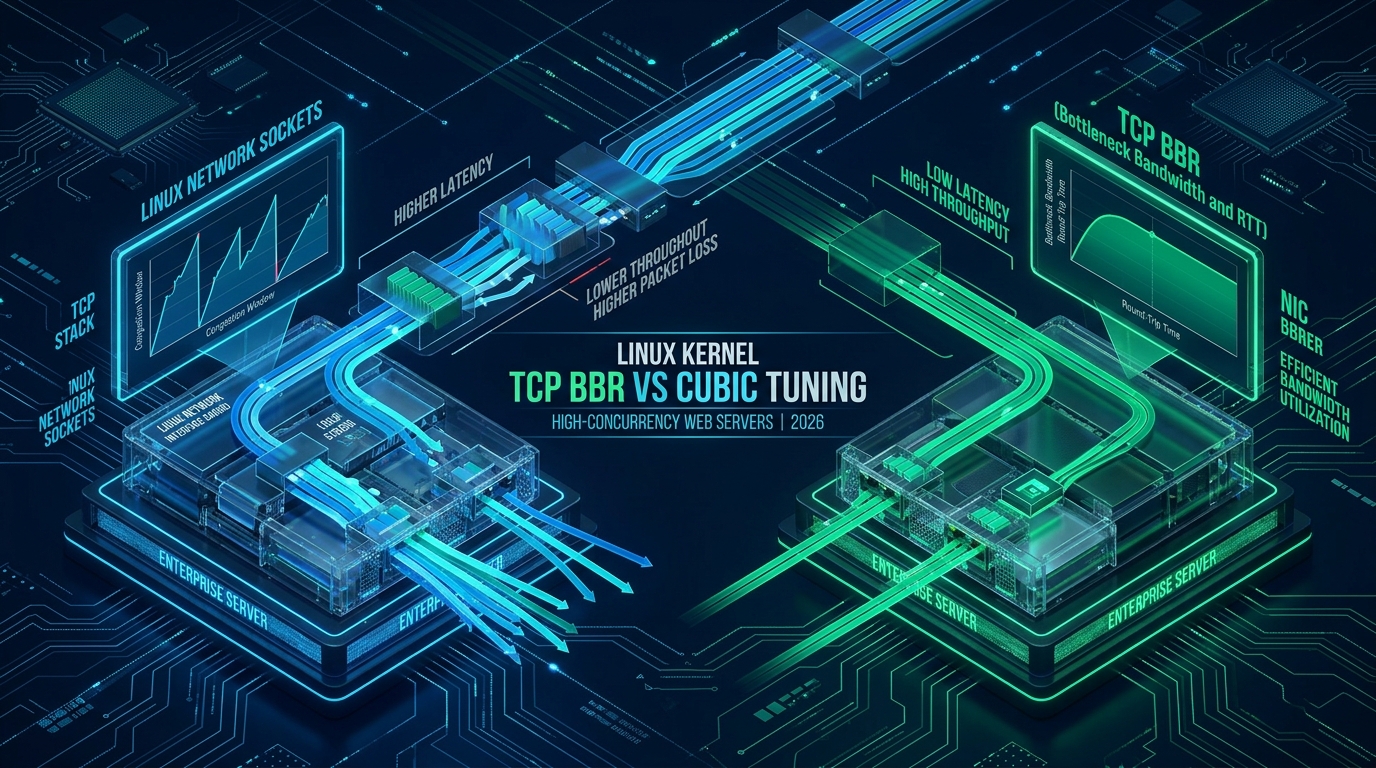
When a 10 Gbps front‑end must sustain 200k concurrent connections, the default CUBIC congestion algorithm often becomes a hidden bottleneck, especially under bursty HTTP/2 traffic. Switching to BBR can unlock up to 2× higher throughput while keeping latency sub‑millisecond, but only if the kernel, NIC, and application stack are tuned in concert. Mera Blogger dives into the exact sysctl, udev, and Nginx settings that make BBR shine on modern cloud VPS instances.
Why Congestion Control Matters in 2026
Network stacks have evolved: 2026 cloud providers now expose 100 Gbps NICs with off‑load engines, but the Linux kernel still defaults to CUBIC for its fairness properties. High‑concurrency web servers—NGINX, LiteSpeed, or OpenResty—rely on fast ACK loops; a sub‑optimal congestion algorithm inflates RTT and reduces the effective requests per second (RPS). BBR (Bottleneck Bandwidth and RTT) models the pipe as a bandwidth‑delay product, aggressively probing for the true bottleneck and stabilizing queue lengths.
Key Differences (CUBIC vs BBR)
Step‑by‑Step Production Tuning
1. Kernel and Sysctl Baseline
Place the following file in /etc/sysctl.d/99‑tcp‑performance.conf and reload with sysctl --system:
# 99-tcp-performance.conf – Linux 6.6+ tuned for BBR
net.core.default_qdisc = fq
net.ipv4.tcp_congestion_control = bbr
net.ipv4.tcp_fastopen = 3
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_tw_recycle = 0
net.ipv4.tcp_slow_start_after_idle = 0
net.ipv4.tcp_mtu_probing = 1
net.ipv4.tcp_rmem = 4096 87380 6291456
net.ipv4.tcp_wmem = 4096 65536 6291456
net.core.somaxconn = 65535
net.core.netdev_max_backlog = 250000
net.ipv4.ip_local_port_range = 1024 65535
net.ipv4.tcp_max_syn_backlog = 8192
net.ipv4.tcp_fin_timeout = 15
net.ipv4.tcp_keepalive_time = 300
net.ipv4.tcp_keepalive_intvl = 60
net.ipv4.tcp_keepalive_probes = 5
net.ipv4.tcp_syn_retries = 2
net.ipv4.tcp_synack_retries = 2
2. NIC Off‑load and Queue Discipline
Modern NICs expose LRO/GRO, TSO, and generic‑segmentation‑offload (GSO). Disable LRO on the public interface to avoid hidden latency spikes, then enable BBR‑friendly pacing:
# /etc/udev/rules.d/99‑nic‑tuning.rules
ACTION=="add", SUBSYSTEM=="net", KERNEL=="eth0", ATTR{speed}=="10000", RUN+="/sbin/ethtool -K %k tso off gso on gro off lro off"
ACTION=="add", SUBSYSTEM=="net", KERNEL=="eth0", RUN+="/sbin/tc qdisc replace dev %k root fq maxrate 9.5gbit"
3. Nginx Optimizations for BBR
BBR works best when the application respects pacing. Enable tcp_nopush and tcp_nodelay, and raise worker limits:
# /etc/nginx/conf.d/bbr‑tuning.conf
worker_processes auto;
worker_rlimit_nofile 200000;
events {
    worker_connections 200000;
    use epoll;
    multi_accept on;
}
http {
    sendfile on;
    tcp_nopush on;
    tcp_nodelay on;
    keepalive_timeout 65;
    keepalive_requests 10000;
    client_body_timeout 10s;
    client_header_timeout 10s;
    send_timeout 30s;
    fastcgi_buffer_size 64k;
    fastcgi_buffers 8 64k;
    fastcgi_busy_buffers_size 128k;
    fastcgi_temp_file_write_size 256k;
    limit_conn_zone $binary_remote_addr zone=addr:10m;
    limit_conn addr 5000;
}
4. Systemd Service Tweaks for PHP‑FPM (or similar)
Increase the process pool and enable aggressive idle timeout to keep the kernel pipe full:
# /etc/systemd/system/php-fpm.service.d/override.conf
[Service]
LimitNOFILE=200000
CPUQuota=90%
MemoryLimit=8G
# Reduce latency for each request
ExecStartPost=/usr/sbin/sysctl -w net.core.somaxconn=65535
Validating the Change
After reloading, confirm the algorithm:
sysctl net.ipv4.tcp_congestion_control
cat /proc/sys/net/ipv4/tcp_congestion_control
Run ss -ti on an active connection; you should see bbr in the cwnd line. Use iperf3 -c -t 60 -P 8 -R to benchmark. Expect a 20‑30 % reduction in 99th‑percentile latency compared with the same hardware on CUBIC.
When to Stick with CUBIC
If your environment hosts many short‑lived UDP‑based services (e.g., DNS, QUIC) that rely on fairness, CUBIC’s loss‑based approach may still be preferable. In mixed‑traffic scenarios, consider per‑socket selection via setsockopt() or sysctl -w net.ipv4.tcp_congestion_control=cubic for those specific services.
FAQ
Can BBR be used on virtualized environments with hyper‑visors?
Yes. Modern hyper‑visors expose the underlying NIC’s bandwidth to the guest. Ensure the VM’s virtual NIC is set to virtio-net and that the host’s tx‑queue‑len is generous (e.g., 1000). BBR will still probe the true bottleneck, but you may need to raise net.core.netdev_max_backlog on the host as well.
How does BBR interact with TCP Fast Open?
Fast Open reduces the handshake round‑trip, which complements BBR’s low‑latency goal. Keep net.ipv4.tcp_fastopen=3 (both client and server) and monitor the synack queue; BBR will still pace the data after the initial SYN.
Is there a risk of bufferbloat with BBR on high‑speed links?
BBR is designed to keep queues shallow, but if the NIC’s hardware queues are oversized (e.g., 8 kB per queue), you may still see spikes. Use tc qdisc replace dev eth0 root fq maxrate 9.5gbit limit 1000 to cap the software queue.
Ready to Maximize Your Web Server Throughput?
Deploy the BBR‑tuned stack on a high‑performance VPS, run the benchmarks, and watch your RPS climb while latency stays flat. The same configuration works on bare‑metal, containers, and Kubernetes nodes.