
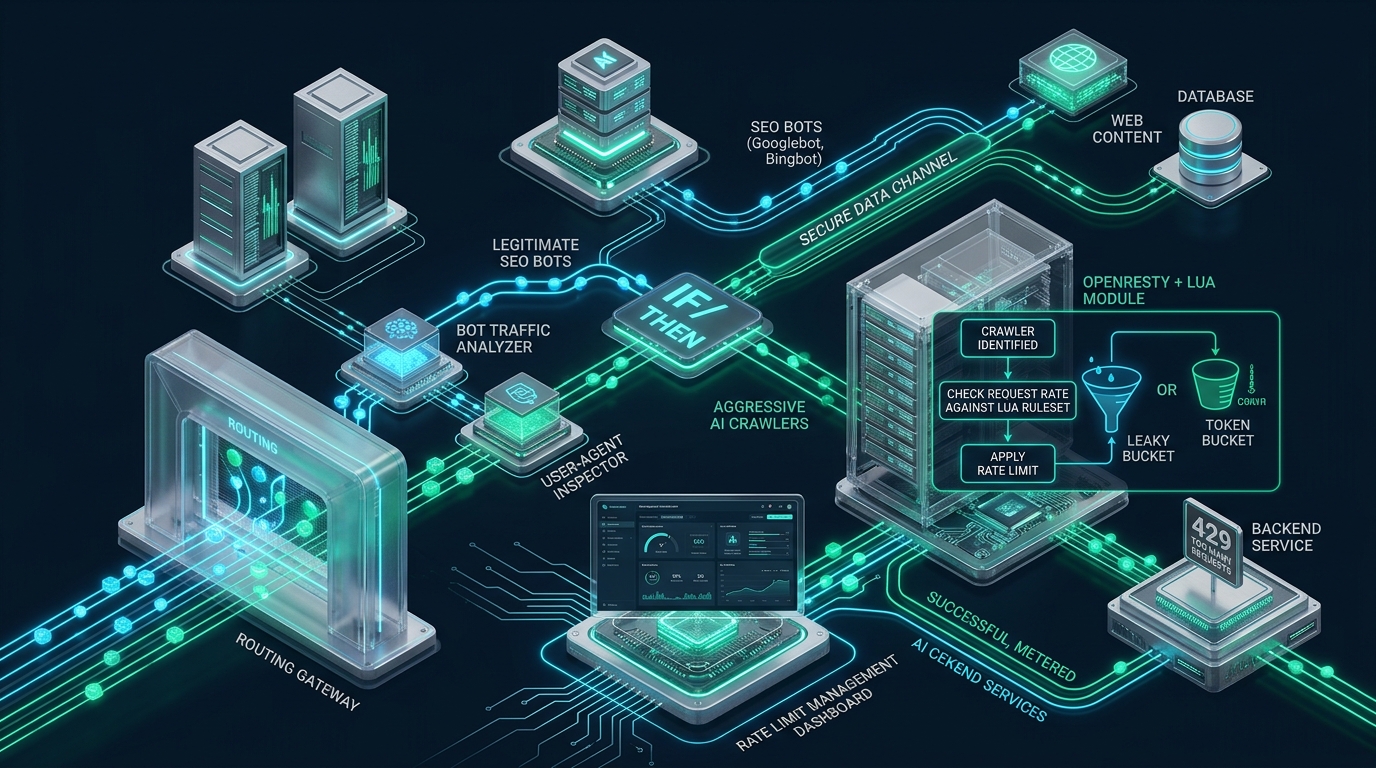
Unregulated crawling from commercial Large Language Model scrapers and autonomous AI retrieval agents has created an unprecedented availability crisis for production Linux web infrastructure. When distributed bot swarms originating from providers like ByteDance, OpenAI, Anthropic, and Perplexity aggressively scrape dynamic endpoints on platforms hosted via CpanelFree, they routinely saturate PHP-FPM worker pools, exhaust database connection limits, and induce crippling 504 gateway timeouts. Applying blunt IP-level throttling or crude User-Agent blacklists inevitably causes severe collateral damage by blocking verified search engine crawlers like Googlebot and Bingbot, decimating organic search visibility. By embedding Lua-driven traffic classification directly into the OpenResty Nginx event loop with non-blocking shared dictionary memory, systems architects can surgically throttle predatory AI bots to strict token-bucket envelopes while guaranteeing zero latency or crawl budget penalties for critical SEO spiders.
Architectural Paradigm: Differentiating AI Data Scrapers from Search Engine Crawlers
Direct Answer: To rate limit AI crawlers with OpenResty and Lua without blocking SEO, inspect incoming request headers in the access_by_lua_block phase, authenticate search engine bots using cached forward-confirmed reverse DNS (FCrDNS), and apply dynamic token-bucket rate limits against AI crawler signatures using resty.limit.req and shared memory dictionaries without dropping organic search engine spiders.
The operational profile of generative AI crawlers differs fundamentally from traditional search indexing spiders. Search engine bots such as Googlebot, Bingbot, and DuckDuckBot are engineered to respect webmaster crawl limits, adhere rigorously to robots.txt directives, honor HTTP 429 Retry-After headers, and moderate request concurrency based on measured origin server latency. Their objective is discovery, indexing, and bidirectional traffic referral. In contrast, AI scraping agents (including Bytespider, CCBot, GPTBot, ClaudeBot, and Amazonbot) are designed for massive dataset extraction, model pre-training, and near-real-time Retrieval-Augmented Generation (RAG). They frequently ignore crawl-delay directives, execute concurrent scrapers across hundreds of distributed cloud subnets, and aggressively trigger cache-busting search queries, pagination loops, and faceted filter permutations that completely bypass reverse proxy microcaching layers.
When origin servers experience this scraping intensity, traditional edge defenses routinely fail. Naive User-Agent blocking is ineffective because malicious or aggressive scrapers easily rotate their headers to mimic common desktop browsers or even impersonate Googlebot. Conversely, applying global IP-based rate limiting (such as Nginx’s built-in limit_req_zone $binary_remote_addr) inadvertently throttles Googlebot during heavy re-indexing passes, triggering Google Search Console crawl errors, de-indexing events, and substantial organic ranking drops. To establish a robust defense, engineering teams must deploy an intelligent, programmable edge proxy capable of verifying crawler identities at wire speed.
Architecture Note: Never rely on static User-Agent filtering alone to grant rate limit exemptions. Sophisticated scrapers frequently forge headers such as
Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html). True protection requires Forward-Confirmed Reverse DNS (FCrDNS) verification, executed asynchronously within the proxy and cached in shared memory to avoid DNS resolution bottlenecks.
Benchmarking Crawler Management Architectures
Before implementing custom Lua logic, systems engineers must evaluate the operational trade-offs of existing bot mitigation strategies. Below is a comprehensive architectural comparison benchmarking standard Nginx rate limiting, cloud-hosted WAF rules, and an OpenResty Lua shared-memory architecture across critical performance and reliability dimensions:
| Architectural Metric | Standard Nginx limit_req |
Commercial Cloud WAF | OpenResty + Lua Shdict |
|---|---|---|---|
| Bot Identification Precision | Crude (IP address or static string) | Proprietary heuristics / Blackbox | Surgical (Regex + FCrDNS verification) |
| SEO False-Positive Risk | High (Throttles shared bot IP pools) | Moderate (CAPTCHA challenges search bots) | Zero (Cryptographic FCrDNS whitelist) |
| Request Latency Overhead | < 0.1 ms (Hash table lookup) | 15 ms – 45 ms (External CDN hop) | 0.2 ms – 0.4 ms (LuaJIT shared dict) |
| Dynamic Throttling Granularity | Fixed rate/burst per zone | Coarse rate tiers per plan | Granular per-bot leaky bucket & delay |
| Memory Footprint per 100k Sessions | ~6.4 MB (64-byte binary IP nodes) | Offloaded to vendor cloud | ~12 MB (Shdict LRU memory slab) |
| Infrastructure Cost / Licensing | $0 (Standard open-source Nginx) | $200 – $3,000+ / mo (Usage tiered) | $0 (Open-source OpenResty stack) |
The OpenResty Request Pipeline: Non-Blocking Execution in the Access Phase
OpenResty integrates the LuaJIT runtime directly into Nginx’s asynchronous, event-driven architecture. Nginx processes HTTP transactions through eleven distinct phases, including post-read, server-rewrite, find-config, rewrite, post-rewrite, pre-access, access, post-access, pre-content, content, and log. The optimal injection point for bot rate limiting is the access phase, executed via access_by_lua_block or access_by_lua_file.
Executing crawler verification during the access phase ensures that unauthorized or abusive requests are intercepted and terminated before Nginx allocates resources to upstream reverse proxy buffers, PHP-FPM FastCGI processes, or Python WSGI workers. If an AI scraper violates rate thresholds, OpenResty immediately generates an HTTP 429 Too Many Requests response with standard Retry-After headers directly from worker memory, completely shielding backend application servers and databases from CPU load.
To implement this without performance degradation, OpenResty provides thread-safe shared memory dictionaries (lua_shared_dict). These dictionaries reside in Nginx’s master process shared memory segment, making them accessible across all worker processes without inter-process locking contention or serialization overhead. By combining lua_shared_dict with the official resty.limit.req library, we implement a memory-efficient leaky-bucket rate limiter that throttles bots by calculating request arrival intervals and dynamically delaying or rejecting excess traffic.
Security Advisory: Never perform synchronous DNS lookups using blocking system calls (such as standard POSIX
gethostbyaddr) inside an Nginx worker process. If an influx of crawler traffic triggers dozens of simultaneous blocking DNS resolutions, the Nginx worker event loop will freeze, causing latency spikes for all concurrent web visitors. Always utilize OpenResty’s non-blocking coroutine-based resolver (resty.dns.resolver) backed by local caching.
Production Configuration: Step-by-Step Deployment
Below are production-ready configuration files designed for enterprise deployment on Linux web servers running OpenResty. Follow the file paths and configurations precisely to construct an autonomous, high-performance crawler control gateway.
1. OpenResty Core Configuration: /etc/openresty/conf.d/ai_crawler_ratelimit.conf
This configuration defines the shared memory dictionaries for rate limiting and DNS caching, establishes non-blocking internal resolvers, and attaches the Lua access controller to incoming HTTP traffic:
# /etc/openresty/conf.d/ai_crawler_ratelimit.conf
# Define shared memory dictionaries for rate limiting and DNS validation
lua_shared_dict ai_crawler_limit 20m;
lua_shared_dict dns_verify_cache 10m;

# Internal non-blocking DNS resolver with caching
resolver 1.1.1.1 8.8.8.8 ipv6=off valid=600s;
resolver_timeout 2s;

# Global Lua package path
lua_package_path "/etc/openresty/lua/?.lua;;";

server {
    listen 80;
    listen 443 ssl http2;
    server_name example.com www.example.com;

    # SSL configuration omitted for brevity
    # ssl_certificate /etc/ssl/certs/example.com.crt;
    # ssl_certificate_key /etc/ssl/private/example.com.key;

    # Custom structured JSON access log for crawler auditing
    log_format crawler_json escape=json '{'
        '"time_local":"$time_local",'
        '"remote_addr":"$remote_addr",'
        '"request_method":"$request_method",'
        '"request_uri":"$request_uri",'
        '"status":"$status",'
        '"body_bytes_sent":"$body_bytes_sent",'
        '"http_referer":"$http_referer",'
        '"http_user_agent":"$http_user_agent",'
        '"crawler_type":"$sent_http_x_crawler_type",'
        '"rate_limited":"$sent_http_x_ratelimit_action"'
    '}';

    access_log /var/log/openresty/crawler_access.log crawler_json;

    location / {
        # Intercept and rate limit requests during the access phase
        access_by_lua_file /etc/openresty/lua/crawler_control.lua;

        # Standard upstream application proxy
        proxy_pass http://127.0.0.1:8080;
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;
        proxy_connect_timeout 5s;
        proxy_read_timeout 60s;
        proxy_send_timeout 60s;
    }
}
2. The Production Lua Engine: /etc/openresty/lua/crawler_control.lua
Save the following script to /etc/openresty/lua/crawler_control.lua. It parses User-Agent headers, executes non-blocking Forward-Confirmed Reverse DNS (FCrDNS) checks for major search engines, caches verified IPs for 24 hours, and applies strict leaky-bucket rate limits against unverified bots and commercial AI scrapers:
-- /etc/openresty/lua/crawler_control.lua
local limit_req = require "resty.limit.req"
local resolver = require "resty.dns.resolver"

local user_agent = ngx.var.http_user_agent or ""
local client_ip = ngx.var.remote_addr

-- Initialize rate limiters on shared dictionary
-- AI Crawlers: 5 requests per minute (0.083 req/s) with burst allowance of 2
local lim_ai, err_ai = limit_req.new("ai_crawler_limit", 5/60, 2)
if not lim_ai then
    ngx.log(ngx.ERR, "Failed to instantiate AI rate limiter: ", err_ai)
    return
end

-- Fallback scraper limit: 30 requests per minute with burst of 10
local lim_general, err_gen = limit_req.new("ai_crawler_limit", 30/60, 10)
if not lim_general then
    ngx.log(ngx.ERR, "Failed to instantiate General rate limiter: ", err_gen)
    return
end

-- Shared dictionary for DNS resolution caching (24-hour TTL)
local dns_cache = ngx.shared.dns_verify_cache

-- Known aggressive AI crawlers and data brokers regex pattern
local ai_pattern = "(?i)(Bytespider|GPTBot|ChatGPT-User|ClaudeBot|Anthropic-AI|PerplexityBot|CCBot|Diffbot|Amazonbot|FacebookBot|cohere-ai|Omgilibot|OAI-SearchBot|ImagesiftBot)"

-- Legitimate search engine signatures requiring FCrDNS verification
local seo_patterns = {
    google = "(?i)Googlebot",
    bing = "(?i)bingbot",
    apple = "(?i)Applebot",
    yandex = "(?i)YandexBot"
}

-- Function: Non-blocking Forward-Confirmed Reverse DNS (FCrDNS) Verification
local function verify_seo_crawler(ip, bot_type)
    local cache_key = "fcrdns:" .. ip
    local cached_status = dns_cache:get(cache_key)
    if cached_status ~= nil then
        return cached_status == "VERIFIED"
    end

    local r, err = resolver:new{
        nameservers = {"1.1.1.1", "8.8.8.8"},
        retrans = 2,
        timeout = 1500, -- 1.5 second non-blocking timeout
    }
    if not r then
        ngx.log(ngx.WARN, "DNS resolver initialization error: ", err)
        return false
    end

    -- Reverse PTR lookup
    local answers, err_ptr = r:query(r:arpa_str(ip), {qtype = r.TYPE_PTR})
    if not answers or answers.errcode then
        dns_cache:set(cache_key, "FAILED", 3600) -- Cache negative lookup for 1 hour
        return false
    end

    local ptr_hostname = nil
    for _, ans in ipairs(answers) do
        if ans.ptrdname then
            ptr_hostname = ans.ptrdname
            break
        end
    end

    if not ptr_hostname then
        dns_cache:set(cache_key, "FAILED", 3600)
        return false
    end

    -- Validate authoritative search engine domains
    local valid_domain = false
    if bot_type == "google" and (ptr_hostname:match("%.googlebot%.com$") or ptr_hostname:match("%.google%.com$")) then
        valid_domain = true
    elseif bot_type == "bing" and ptr_hostname:match("%.search%.msn%.com$") then
        valid_domain = true
    elseif bot_type == "apple" and ptr_hostname:match("%.applebot%.apple%.com$") then
        valid_domain = true
    elseif bot_type == "yandex" and (ptr_hostname:match("%.yandex%.ru$") or ptr_hostname:match("%.yandex%.com$") or ptr_hostname:match("%.yandex%.net$")) then
        valid_domain = true
    end

    if not valid_domain then
        ngx.log(ngx.WARN, "Spoofed search bot detected from IP: ", ip, " with PTR: ", ptr_hostname)
        dns_cache:set(cache_key, "FAILED", 86400)
        return false
    end

    -- Forward lookup to verify reverse mapping matches client IP
    local forward_ans, err_fwd = r:query(ptr_hostname, {qtype = r.TYPE_A})
    if not forward_ans or forward_ans.errcode then
        dns_cache:set(cache_key, "FAILED", 3600)
        return false
    end

    for _, ans in ipairs(forward_ans) do
        if ans.address == ip then
            dns_cache:set(cache_key, "VERIFIED", 86400) -- Cache verified bot IP for 24 hours
            return true
        end
    end

    dns_cache:set(cache_key, "FAILED", 86400)
    return false
end

-- Step 1: Detect and verify legitimate search engines
for bot_name, pattern in pairs(seo_patterns) do
    if ngx.re.find(user_agent, pattern, "jo") then
        local is_legit = verify_seo_crawler(client_ip, bot_name)
        if is_legit then
            ngx.header["X-Crawler-Type"] = "Verified-" .. bot_name
            ngx.header["X-RateLimit-Action"] = "BYPASS"
            return -- Legitimate search engine: bypass all rate limits
        else
            -- Spoofed bot signature: reject immediately with 403 Forbidden
            ngx.header["X-Crawler-Type"] = "Spoofed-" .. bot_name
            ngx.header["X-RateLimit-Action"] = "BLOCKED"
            ngx.status = ngx.HTTP_FORBIDDEN
            ngx.say('{"error":"Forbidden","message":"Spoofed search crawler identity detected."}')
            ngx.exit(ngx.HTTP_FORBIDDEN)
        end
    end
end

-- Step 2: Rate limit aggressive AI crawlers
if ngx.re.find(user_agent, ai_pattern, "jo") then
    ngx.header["X-Crawler-Type"] = "AI-Scraper"
    local delay, err = lim_ai:incoming(client_ip, true)
    if not delay then
        if err == "rejected" then
            ngx.header["X-RateLimit-Action"] = "RATE_LIMITED"
            ngx.header["Retry-After"] = "60"
            ngx.status = 429
            ngx.header["Content-Type"] = "application/json"
            ngx.say('{"error":"Too Many Requests","message":"AI scraping rate limit exceeded. Retry in 60 seconds."}')
            ngx.exit(429)
        end
        ngx.log(ngx.ERR, "Failed to evaluate AI rate limit: ", err)
        return
    end

    if delay >= 0.001 then
        ngx.sleep(delay) -- Apply non-blocking sub-second sleep to smooth burst
    end
    ngx.header["X-RateLimit-Action"] = "THROTTLED"
    return
end

-- Step 3: Default unclassified traffic passes through cleanly
ngx.header["X-Crawler-Type"] = "Standard-Client"
ngx.header["X-RateLimit-Action"] = "ALLOWED"
3. Kernel & Network Buffer Tuning: /etc/sysctl.d/99-openresty-highconcurrency.conf
When handling thousands of crawler requests while maintaining microsecond response times for end users, the underlying Linux kernel TCP stack must be tuned to prevent socket exhaustion and SYN packet dropping:
# /etc/sysctl.d/99-openresty-highconcurrency.conf
# Maximize socket listen backlog for high connection bursts
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 65535

# Increase network interface input queue
net.core.netdev_max_backlog = 16384

# Enable rapid reuse of TIME_WAIT sockets for outgoing proxy connections
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# Expand ephemeral port range to support high upstream proxy density
net.ipv4.ip_local_port_range = 1024 65535

# Increase system-wide file descriptor limit
fs.file-max = 2097152

# Protect against TCP SYN flood attacks during distributed scraping runs
net.ipv4.tcp_syncookies = 1
Apply these kernel parameters immediately without rebooting by executing:
sudo sysctl -p /etc/sysctl.d/99-openresty-highconcurrency.confOperational Validation & Production Telemetry
Once deployed, verify that the Lua rate limiter accurately distinguishes between legitimate search engines, spoofed crawlers, and aggressive AI scrapers using targeted curl diagnostic probes:
# Test 1: Simulate spoofed Googlebot from non-Google IP (Expect 403 Forbidden)
curl -i -H "User-Agent: Mozilla/5.0 (compatible; Googlebot/2.1; +http://www.google.com/bot.html)" https://example.com/

# Test 2: Simulate ByteSpider AI scraper within threshold (Expect 200 OK with throttled headers)
curl -i -H "User-Agent: Mozilla/5.0 (compatible; Bytespider; +https://zhanzhang.toutiao.com/)" https://example.com/

# Test 3: Rapid burst test against AI rate limiter (Expect 429 Too Many Requests with Retry-After)
for i in {1..6}; do
    curl -s -o /dev/null -w "%{http_code}\n" -H "User-Agent: Mozilla/5.0 (compatible; GPTBot/1.0; +https://openai.com/gptbot)" https://example.com/
done
Reviewing the structured JSON log at /var/log/openresty/crawler_access.log allows monitoring tools (such as Vector, Fluentbit, or Prometheus) to generate real-time metrics tracking the volume of throttled AI scrapers versus unhindered search engine requests.
Transitioning from Staging to Enterprise Production Infrastructure
Implementing custom OpenResty reverse proxy architectures on staging platforms like CpanelFree provides an outstanding zero-cost environment for profiling Lua regex expressions, calibrating token-bucket burst limits, and stress-testing DNS resolution coroutines. However, when migrating high-concurrency web properties to production where sustained AI scraping coexists with millions of human pageviews, infrastructure underlying the edge proxy becomes paramount.
Operating shared dictionaries, SSL termination, and dynamic LuaJIT execution under massive scraper volume requires deterministic CPU thread allocation, ultra-low memory latency, and carrier-grade network transit. For enterprise web deployments that cannot tolerate jitter, throttling overhead, or surprise renewal rate spikes, hosting your edge infrastructure on MeraHost Enterprise Cloud guarantees dedicated AMD EPYC and Intel Xeon compute resources with enterprise NVMe storage arrays. By combining OpenResty’s non-blocking Lua engine with high-performance bare-metal or cloud instances from MeraHost, your applications remain impervious to aggressive scraper storms while delivering peak Core Web Vitals to human visitors and search crawlers alike.
Frequently Asked Questions
Why not simply block all AI crawlers using robots.txt directives?
While reputable search engines adhere strictly to robots.txt, many commercial AI scrapers and third-party data brokers routinely disregard disallow rules or interpret them selectively. Furthermore, completely disallowing AI crawlers in robots.txt prevents your content from being cited in emerging AI search engines (such as Perplexity and SearchGPT). Rate limiting via OpenResty allows you to control the exact request cadence and bandwidth consumption of AI bots without severing visibility in AI search summaries.
Does returning HTTP 429 status codes to AI crawlers hurt Google rankings?
No, because our OpenResty Lua architecture authenticates Googlebot and Bingbot using Forward-Confirmed Reverse DNS (FCrDNS) and completely exempts verified search crawlers from the rate limiter. Search engine spiders receive normal HTTP 200 responses with full crawl budget allocation. Only unverified bots and matching AI User-Agents receive HTTP 429 status codes, preserving your organic SEO rankings.
How does OpenResty handle DNS resolution without slowing down incoming web traffic?
Our implementation utilizes the resty.dns.resolver module, which executes DNS lookups inside non-blocking coroutines rather than standard synchronous system calls. Furthermore, verified search bot IPs are stored in a 10MB shared memory dictionary (lua_shared_dict dns_verify_cache) with a 24-hour TTL. After the initial lookup, subsequent requests from that IP are validated in approximately 0.2 milliseconds directly from memory.
What is the memory overhead of maintaining shared dictionaries for high-traffic sites?
Shared dictionaries in OpenResty are allocated as fixed-size shared memory slabs when Nginx boots. A 20MB rate limit zone and a 10MB DNS cache zone consume exactly 30MB of system RAM, regardless of traffic volume. OpenResty manages entries using an internal LRU (Least Recently Used) algorithm, ensuring that active client and crawler states are retained without risks of memory fragmentation or unbounded RAM consumption.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).