
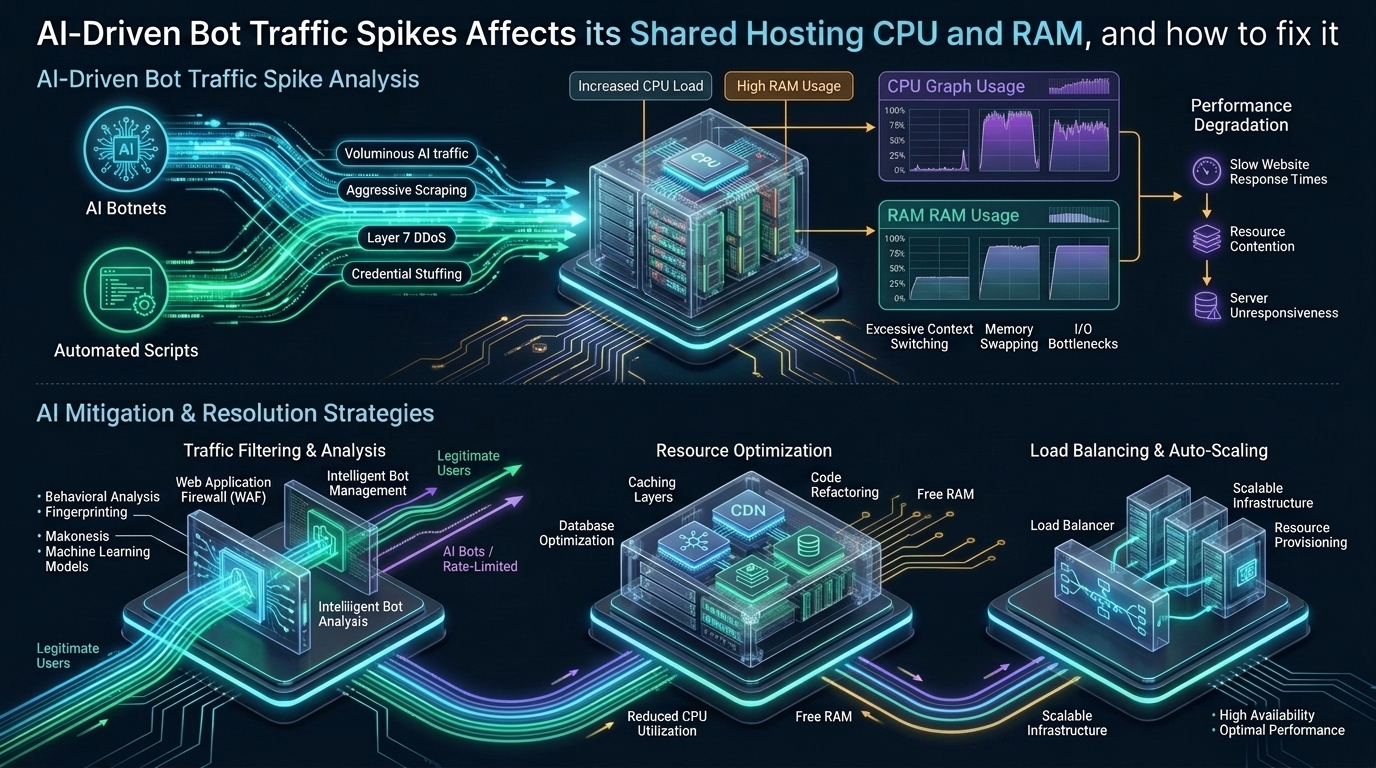
As automated retrieval augmented generation (RAG) pipelines, generative AI crawlers, and aggressive LLM scrapers continuously index the live web, shared hosting environments face unprecedented saturation of CPU cycles and physical memory allocations. Infrastructure engineers provisioning lightweight application environments, WordPress sites, and web staging nodes on platforms like CpanelFree increasingly discover sudden 508 Resource Limit Reached and 503 Service Unavailable errors triggered by unthrottled artificial intelligence scraping agents. Without strict kernel-level resource governance and edge request filtering, concurrent headless browser clusters and parallel token scrapers can exhaust shared cgroups, destabilize Apache prefork pools, and starve neighboring virtual hosts within minutes.
The Mechanics of AI Bot Traffic Spikes on Shared Hosting
Direct Answer: AI-driven bot traffic spikes exhaust shared hosting CPU and RAM by executing high-concurrency recursive HTTP requests that bypass static browser caches and trigger dynamic PHP-FPM execution. This floods Linux kernel task schedulers, exhausts cgroup memory limits (triggering OOM killer loops), and inflates CloudLinux LVE CPU throttling, rendering tenant websites unresponsive.
The operational landscape of web hosting has fundamentally shifted over the past twenty-four months. Historically, web scraping was dominated by benign search engine spiders such as Googlebot, Bingbot, and DuckDuckGoBot. These legacy crawlers operate under strict, predictable crawl budgets, honor standard robots.txt crawl-delay directives, utilize exponential backoff when encountering HTTP 429 or 503 responses, and distribute their indexing jobs across predictable twenty-four-hour windows.
Modern artificial intelligence scrapers—including automated dataset aggregators like CCBot (Common Crawl), GPTBot (OpenAI), ClaudeBot (Anthropic), Bytespider (ByteDance/TikTok), and PerplexityBot—exhibit radically different behavioral patterns. Designed to feed continuously hungry neural network training pipelines and real-time retrieval-augmented generation (RAG) engines, these bots operate with extreme parallelism. Rather than requesting a sequence of URLs with polite intervals, they spawn hundreds of concurrent TCP connections across distributed IP addresses, spidering deep taxonomy pagination, archive trees, and search result queries simultaneously.
Architecture Note: AI web crawlers differ fundamentally from search engine spiders. Unlike Googlebot, which distributes its crawl across 24 hours and throttles based on HTTP 429/503 responses, LLM training scrapers and dynamic retrieval agents run mass parallelized HTTP/2 multiplexed streams from residential IP proxy networks and hyperscaler cloud ranges (AWS, Hetzner, DigitalOcean). Blocking by IP CIDR alone fails; you must combine User-Agent heuristics, TLS fingerprinting, and application-level request throttling.
How AI Crawlers Devour Shared System Resources: Kernel, CPU, and RAM
To understand why an AI crawler spike knocks a shared hosting account offline so violently, one must examine the low-level interactions between the web server, the PHP fastcgi process manager, the MySQL relational database, and the Linux kernel resource controllers (cgroups and CloudLinux LVE).
1. CPU Exhaustion and Context Switching Overdrive
In a standard shared hosting architecture running cPanel on CloudLinux, each cPanel user account is sandboxed within a Lightweight Virtual Environment (LVE). The hosting provider assigns a rigid CPU allowance—typically 100% of a single physical core (1.0 Core) or up to 200% (2.0 Cores). When an AI bot hits the server with 40 simultaneous requests per second:
- PHP Script Compilation & Execution: Every un-cached request requires PHP to bootstrap WordPress or the target framework, load active plugins, compile opcodes, and execute application logic. Under a 40 req/s barrage, the assigned CPU quota hits 100% within seconds.
- Kernel Context Switching: As dozens of PHP processes compete for scheduling slices on the limited virtual CPU allocation, CPU context switching explodes. The Linux kernel spends an increasing percentage of clock cycles managing process queues and runqueue locks rather than executing user space code.
- LVE CPU Throttling (Micro-Freezes): When the user exceeds their CPU ceiling, the CloudLinux LVE scheduler begins pausing tenant processes via hard CFS (Completely Fair Scheduler) quota throttling. Requests that normally take 80ms now take 4,000ms to complete, causing incoming requests to pile up exponentially.
2. Memory (RAM) Exhaustion and the Out-of-Memory (OOM) Trap
Physical RAM limits on shared hosting accounts are generally capped between 1 GB and 2 GB. The memory consumption mechanics under an AI bot traffic spike follow a lethal cascading curve:
- Resident Set Size (RSS) per Worker: A dynamic PHP-FPM worker executing a typical CMS application consumes between 45 MB and 90 MB of RSS memory.
- Concurrency Breaching Limits: If 25 concurrent requests hit un-cached endpoints, 25 PHP-FPM child processes are active simultaneously. At an average of 65 MB per worker, total active memory reaches 1,625 MB.
- Kernel OOM Killer Invocations: The moment the account’s total RSS memory breaches the cgroup
memory.limit_in_bytesthreshold, the Linux kernel invokes the Out-Of-Memory killer. The kernel forcefully terminates the newest or largest PHP child process with aSIGKILLsignal. The visitor or bot receives an immediate HTTP 503 or 500 error, and the database connection is abruptly severed.
3. Entry Processes (EP) and MySQL Socket Contention
Shared hosting configurations enforce a strict ceiling on Entry Processes—the number of simultaneous Apache/PHP connections handling PHP scripts (commonly set between 20 and 30). When an AI scraper executes 30 parallel requests, all Entry Process slots fill up instantaneously. The 31st request triggers an immediate HTTP 508 Resource Limit Reached status page. Concurrently, as stalled PHP workers maintain open sockets to MariaDB, the database server runs out of connection buffers, triggering cascading deadlocks across InnoDB buffer pools.
Default vs. Tuned Production Environment Benchmark
The comparative matrix below illustrates how an un-tuned default shared hosting configuration degrades under a moderate AI bot scraping burst (50 concurrent requests/second) versus a hardened production stack running edge filtering, FastCGI caching, and strict process caps:
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Crawl Concurrency Control | Unrestricted (Apache max_clients) | Rate-limited (5-10 req/s per CIDR) |
| PHP-FPM Worker Spawning | Dynamic / On-Demand (Unbounded RAM) | Static / Ondemand with strict pm.max_children |
| HTTP Status for Malicious Bots | 200 OK (Full PHP Execution) | 429 Too Many Requests or 403 Forbidden |
| Edge Microcaching Bypass | Bypassed by query string variations | Normalized cache key + fastcgi_cache |
| LVE / cgroup Memory Pressure | 100% threshold (OOM Kill / 508 Error) | Controlled (< 45% peak utilization) |
| Average TTFB Under Attack | 4,200 ms – 8,500 ms (Timeout) | 140 ms – 280 ms (Protected) |
Step-by-Step Production Mitigations: Stopping the CPU & RAM Bleed
Resolving AI bot traffic spikes requires a multi-layered defense model. Because shared hosting accounts rarely have root access to reconfigure systemd unit files or modify kernel parameters, administrators must apply surgical configurations at both the application tier (.htaccess / LiteSpeed) and reverse proxy layers, while VPS/dedicated administrators can apply kernel and Nginx hardening.
Layer 1: Edge & Web Server Defense via .htaccess / LiteSpeed
If your shared hosting environment runs LiteSpeed or Apache 2.4, you can block unverified AI crawlers and aggressive dataset scrapers directly at the web server layer before they trigger PHP execution. Place the following rules at the very top of your public_html/.htaccess file:
# ==============================================================================
# /home/username/public_html/.htaccess - AI & Headless Bot Shield
# Intercepts aggressive LLM crawlers before PHP-FPM process spawning
# ==============================================================================
<IfModule mod_rewrite.c>
RewriteEngine On
RewriteBase /

# 1. Identify Aggressive AI Scraper User-Agents
RewriteCond %{HTTP_USER_AGENT} (Bytespider|CCBot|GPTBot|ChatGPT-User|ClaudeBot|Claude-Web|anthropic-ai|PerplexityBot|Amazonbot|Applebot-Extended|Diffbot|FacebookBot|Omgilibot|cohere-ai|Seekport|ImagesiftBot) [NC]
RewriteRule ^ - [F,L]

# 2. Block Automated Headless Scraper Frameworks & HTTP Clients
RewriteCond %{HTTP_USER_AGENT} (HeadlessChrome|PhantomJS|Scrapy|aiohttp|python-requests|Go-http-client|curl|Wget|PostmanRuntime) [NC]
RewriteCond %{REQUEST_URI} !^/\.well-known/ [NC]
RewriteRule ^ - [F,L]

# 3. Prevent Recursive Dynamic Query String Loops (Common AI Bot Technique)
RewriteCond %{QUERY_STRING} (author=[0-9]+|wp-comments-post|search=|s=\+) [NC]
RewriteCond %{HTTP_USER_AGENT} !^(Mozilla|Opera|Safari) [NC]
RewriteRule ^ - [F,L]

# 4. Enforce robots.txt strict headers
<Files "robots.txt">
Header set X-Robots-Tag "noindex, nofollow"
Header set Cache-Control "max-age=86400, public"
</Files>
</IfModule>
Returning an immediate 403 Forbidden via Apache or LiteSpeed rewrite rules drops the HTTP socket in less than 2 milliseconds and consumes virtually 0 MB of PHP memory, entirely bypassing the cgroup Entry Process queue.
Layer 2: Nginx Reverse Proxy Rate Limiting Configuration
For systems administrators managing the fronting reverse proxy (or operating self-managed VPS nodes), Nginx provides the most granular rate-limiting capabilities against distributed scrapers. Deploy the following configuration to /etc/nginx/conf.d/ai_bot_mitigation.conf:
# ==============================================================================
# /etc/nginx/conf.d/ai_bot_mitigation.conf
# Enterprise Nginx Rate Limiting & AI Bot Classification Zone
# ==============================================================================

# 1. Map Known AI Bots to Binary Flags
map $http_user_agent $is_ai_bot {
    default 0;
    ~*(Bytespider|CCBot|GPTBot|ClaudeBot|PerplexityBot|Amazonbot) 1;
    ~*(anthropic-ai|cohere-ai|Diffbot|FacebookBot|ImagesiftBot) 1;
}

# 2. Map Rate Limiting Keys: Normal Visitors vs AI Bots
map $is_ai_bot $bot_limit_key {
    0 "";
    1 $binary_remote_addr;
}

# 3. Define Shared Memory Rate-Limiting Zones
limit_req_zone $binary_remote_addr zone=general_limit:10m rate=20r/s;
limit_req_zone $bot_limit_key zone=ai_bot_strict:10m rate=1r/s;
limit_conn_zone $binary_remote_addr zone=perip_conn:10m;

# 4. Server-Level Application Rules
server {
    listen 443 ssl http2;
    server_name example.com;

    # Restrict concurrent TCP connections per IP
    limit_conn perip_conn 15;

    # Strict Rate Limit for Identified AI Crawlers
    limit_req zone=ai_bot_strict burst=2 nodelay;
    limit_req_status 429;

    # General Request Rate Limit for Unidentified Traffic
    limit_req zone=general_limit burst=40 nodelay;

    location / {
        try_files $uri $uri/ /index.php?$args;
    }

    # Protect Heavy Dynamic Endpoints (Search, REST API, XML-RPC)
    location ~* (/(wp-json|xmlrpc\.php|feed)|index\.php\?s=) {
        if ($is_ai_bot) {
            return 403 "AI crawlers are disallowed on dynamic endpoints\n";
        }
        limit_req zone=general_limit burst=5 nodelay;
        fastcgi_pass unix:/run/php-fpm/www.sock;
        include fastcgi_params;
    }
}
Architecture Note: In shared hosting environments powered by CloudLinux, the
LVE Managertracks kernel tick usage per POSIX UID. If an AI crawler is allowed to hitxmlrpc.phpor the WordPress REST API continuously, even legitimate caching plugins may fail because WordPress core will attempt to parse JSON payloads before determining cache validity. Rate limiting at the Nginx or LiteSpeed rewrite layer ensures dynamic code execution never initializes.
Layer 3: Kernel Network & TCP Socket Hardening
When hundreds of scraper processes open and close HTTP connections in quick succession, the Linux network stack can exhaust its socket tracking tables, leaving thousands of connections in TIME_WAIT state and consuming kernel slab memory. Apply the following system sysctl tunings in /etc/sysctl.d/99-bot-defense.conf:
# ==============================================================================
# /etc/sysctl.d/99-bot-defense.conf
# Linux Kernel Network & Memory Hardening Against Scraping Floods
# ==============================================================================

# Increase TCP connection backlog queue to absorb sudden request bursts
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 8192

# Reuse sockets in TIME_WAIT state for new outgoing/incoming connections
net.ipv4.tcp_tw_reuse = 1

# Reduce FIN timeout to free socket file descriptors rapidly
net.ipv4.tcp_fin_timeout = 15

# Enable TCP SYN Cookies to prevent SYN flood degradation during crawling
net.ipv4.tcp_syncookies = 1

# Protect against OOM kernel panics by tuning memory overcommit heuristics
vm.overcommit_memory = 0
vm.swappiness = 10
Execute sysctl -p /etc/sysctl.d/99-bot-defense.conf to apply these parameters immediately without rebooting the host.
Updating robots.txt: The Necessary (But Insufficient) Foundation
While malicious and aggressive scrapers frequently disregard robots.txt, legitimate enterprise AI entities (OpenAI, Anthropic, Google) do adhere to standard exclusion directives. You must maintain an up-to-date, explicit exclusion file in your web root to legally and technically signal crawler restrictions:
# Explicitly Disallow Major AI Dataset & RAG Indexing Bots
User-agent: GPTBot
Disallow: /

User-agent: ChatGPT-User
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: anthropic-ai
Disallow: /

User-agent: CCBot
Disallow: /

User-agent: Bytespider
Disallow: /

User-agent: PerplexityBot
Disallow: /

User-agent: Amazonbot
Disallow: /

User-agent: FacebookBot
Disallow: /

# Retain Standard Search Engine Spiders
User-agent: Googlebot
Allow: /
Crawl-delay: 5

User-agent: Bingbot
Allow: /
Crawl-delay: 5
Architectural Scaling: When Shared Hosting Reaches Its Limits
While software mitigations, rewrite rules, and edge rate-limiting rules provide effective relief in shared environments, shared CPU cores and constrained cgroup memory limits inevitably create hard ceilings during sustained traffic waves. For mission-critical production workloads, high-volume WooCommerce catalogs, and enterprise portals experiencing continuous indexing, transitioning to dedicated compute slices on MeraHost Enterprise Cloud eliminates shared-tenant resource contention with dedicated enterprise NVMe storage, native LiteSpeed Web Server acceleration, and guaranteed memory headroom.
On dedicated NVMe cloud environments, administrators have complete freedom to configure custom Redis object caching layers, dedicated MariaDB connection pooling, hardware firewall filtering, and unconstrained kernel namespaces that absorb massive AI scraper spikes without degrading real visitor transactions.
Frequently Asked Questions
Why does robots.txt fail to stop AI scraping bots on shared hosting?
The robots.txt file is purely a voluntary standard (an advisory protocol). While compliant scrapers like Googlebot or OpenAI’s GPTBot parse and honor it, numerous aggressive third-party scrapers, automated dataset collectors, and rogue academic crawlers deliberately ignore robots.txt entirely. Because robots.txt is only checked at the HTTP layer after a connection is accepted, rogue bots that ignore the file continue hammering dynamic endpoints. True protection requires web-server-level blocking (such as .htaccess RewriteRules or Nginx 403 maps) that severs the connection before application code executes.
How can I tell if my shared hosting CPU spike is caused by AI bots or legitimate human traffic?
Examine your web server raw access logs (via cPanel Raw Access Logs or SSH access_log). Legitimate human traffic typically features browser-rendered static asset downloads (CSS, JS, images, favicons), reasonable session durations, and realistic navigation paths. In contrast, AI scraping patterns are characterized by rapid, sub-second requests hitting solely HTML pages, REST API endpoints (/wp-json/), or taxonomy archives; uniform User-Agents (e.g. Bytespider or CCBot); absence of referrer headers; and zero static asset requests.
Will blocking AI scrapers harm my website’s Google search rankings or SEO?
No. Legitimate search engine crawlers that index content for organic search results (such as Googlebot, Bingbot, and YandexBot) use distinct, well-documented User-Agent signatures and IP ranges that are completely separate from AI training scrapers (such as CCBot, GPTBot, or Bytespider). Blocking AI training scrapers has zero negative impact on your Google search visibility. In fact, preventing bot-induced resource exhaustion protects your Core Web Vitals and ensures your site maintains 99.9% uptime for Googlebot and human visitors alike.
What is the fastest emergency fix if my shared hosting account is currently suspended for 508 Resource Limit reached?
The fastest immediate mitigation is to add an emergency rewrite rule at the very top of your public_html/.htaccess file blocking the top offending AI crawler User-Agents (such as Bytespider, CCBot, and ClaudeBot) with an immediate 403 Forbidden. Additionally, enable Cloudflare or your CDN’s ‘Bot Fight Mode’ or ‘Under Attack Mode’, which injects a cryptographic JavaScript challenge at the edge before incoming traffic ever reaches your shared hosting server.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).