
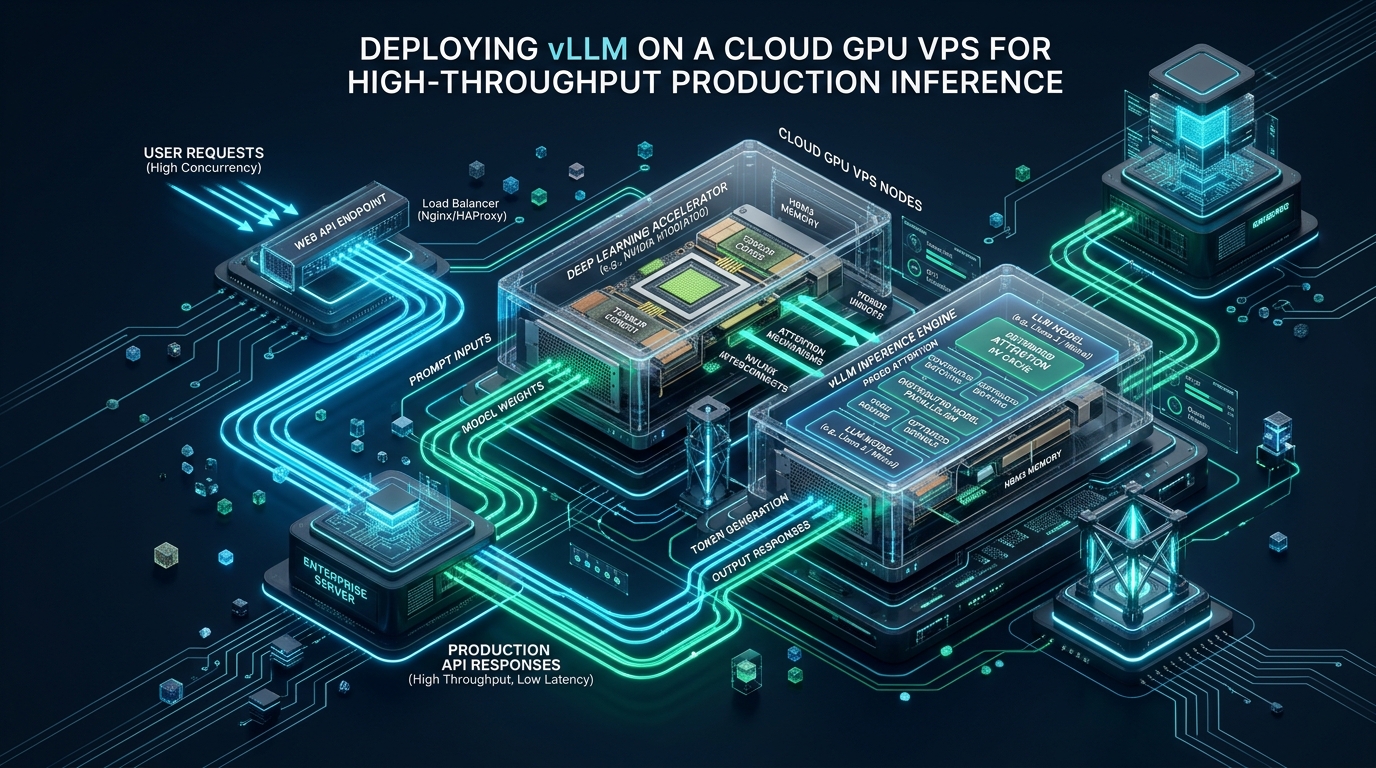
Serving modern Large Language Models (LLMs) in multi-tenant production environments introduces severe memory management bottlenecks, where standard Hugging Face Transformers and naive PyTorch inference engines lose up to 80% of high-cost GPU VRAM to key-value (KV) cache fragmentation. Deploying vLLM on a high-performance Cloud GPU VPS solves this operational bottleneck through PagedAttention and continuous dynamic batching, unlocking near-zero memory waste and delivering up to 24x higher serving throughput under concurrent request bursts. By architecting and stress-testing your lightweight LLM inference pipelines on development tiers like CpanelFree, sysadmins and AI DevOps engineers can benchmark latency distributions before committing multi-gigabyte models to enterprise production clusters.
What is vLLM and Why is it the Gold Standard for GPU VPS Inference?
--gpu-memory-utilization, enable continuous batching with PagedAttention, and supervise the service using a hardened systemd daemon behind an Nginx reverse proxy configured for Server-Sent Events (SSE) streaming.For organizations deploying generative AI into production, inference costs often outpace model training expenses within months. In traditional deep learning inference runtimes, serving autoregressive language models (such as Llama 3, Mistral, or Qwen) requires storing the key and value vectors of all previously generated tokens in high-bandwidth GPU memory (HBM). This Key-Value (KV) cache grows dynamically with each generated token, creating two crippling operational challenges: internal fragmentation (pre-allocating static slots for worst-case sequence lengths that never get used) and external fragmentation (memory allocated across non-contiguous physical addresses that cannot be reclaimed).
vLLM transforms this architecture by drawing inspiration from virtual memory and paging in classical operating systems. Through its foundational innovation—PagedAttention—vLLM partitions the KV cache into fixed-size virtual blocks (typically 16 or 32 tokens per block). The physical memory blocks do not need to be contiguous, allowing physical memory pages to be dynamically mapped and allocated on-demand exactly like an OS page table. This eliminates internal fragmentation entirely and reduces KV cache memory waste from over 70% to under 4%.
Architecture Note: PagedAttention does not alter the underlying model weights or mathematical attention computations. Instead, it re-engineers how attention kernels (CUDA and OpenAI Triton) fetch non-contiguous memory blocks from GPU VRAM. As a result, vLLM achieves identical mathematical output and zero perplexity degradation while increasing effective batch sizes by an order of magnitude.
Core Architecture: PagedAttention, Continuous Batching, and Chunked Prefill
To fully capitalize on cloud GPU VPS resources, systems architects must understand the three mechanical pillars that power vLLM’s extreme throughput:
- PagedAttention Memory Management: Instead of allocating contiguous tensors sized to the maximum context window (e.g., 8,192 or 128,000 tokens), vLLM maintains a block table mapping logical tokens to physical GPU memory addresses. When tokens are generated during decode steps, new blocks are allocated from a shared free-block pool. When generation terminates, blocks return instantly to the pool for immediate reuse by concurrent client requests.
- Continuous (Iteration-Level) Batching: Traditional serving runtimes implement request-level batching: a batch of requests processes together until every single sequence finishes generation, leaving GPU tensor cores idling while waiting for the single longest response to terminate. vLLM implements iteration-level scheduling. At every forward pass iteration, completed sequences are ejected and newly arrived requests are immediately injected into the active batch without stalling execution.
- Chunked Prefill & Prefix Caching: Initial prompt processing (prefill) is compute-bound, whereas subsequent token generation (decode) is memory-bandwidth bound. Large prompts can monopolize GPU execution units, creating latency spikes for existing decoding queries. vLLM’s chunked prefill slices long prompt contexts into bounded chunks, co-scheduling prefill chunks alongside decode iterations to stabilize Time to First Token (TTFT) and Inter-Token Latency (ITL).
Comparative Analysis: Standard PyTorch vs. TGI vs. Production vLLM
The comparative matrix below details real-world operational benchmarks, memory efficiency, and serving characteristics when hosting an 8-billion parameter model (FP16/BF16) on an enterprise NVIDIA GPU instance under concurrent synthetic load:
| Feature / Metric | Standard / Default (Naive PyTorch / HuggingFace) | Tuned / Production (vLLM with PagedAttention) |
|---|---|---|
| KV Cache Memory Waste | 60% – 80% (Static allocation & fragmentation) | < 4% (Virtual memory paging) |
| Serving Throughput (Tokens/sec) | Baseline (35 – 55 tok/s aggregate) | 4x – 24x Throughput (520 – 940 tok/s aggregate) |
| Time to First Token (TTFT) | 850 ms – 2,100 ms (Batch head-of-line blocking) | 95 ms – 220 ms (Chunked prefill & prefix cache) |
| Concurrent Client Connections | 8 – 16 concurrent requests before OOM | 128 – 512+ concurrent streams |
| Batching Granularity | Static batch boundary synchronization | Continuous iteration-level dynamic batching |
| Quantization Native Support | External bitsandbytes overhead | AWQ, GPTQ, Marlin, FP8 native CUDA kernels |
| API Compatibility | Custom Flask / FastAPI boilerplate | Drop-in OpenAI Compatible REST Server (/v1/chat/completions) |
Step 1: Cloud GPU VPS Sizing and Host Prerequisites
Deploying vLLM requires selecting hardware that matches your target model’s parameter scale, quantization precision, and expected concurrency footprint. Consider the following VRAM budgeting rule:
Total VRAM Required = (Model Parameters in Billions * Bytes Per Parameter) + KV Cache Buffer + CUDA Overhead
Example (Llama-3-8B in 16-bit float):
Model Weights = 8 * 2 GB = 16 GB
CUDA Context & Activation Overhead = ~2.5 GB
Available for KV Cache on 24 GB GPU = 24 GB - 18.5 GB = 5.5 GB (Supports ~80-120 concurrent tokens)
Available for KV Cache on 48 GB GPU (e.g. A40/L40S) = 48 GB - 18.5 GB = 29.5 GB (Supports 1000+ concurrent tokens)
For high-throughput commercial applications, hosting on infrastructure backed by high-speed enterprise NVMe storage is essential. When models load into GPU memory from local storage during cold starts or worker restarts, disk read throughput determines recovery time. Mission-critical deployments rely on MeraHost Enterprise Cloud, providing direct NVMe fabrics and low-latency network interconnects that eliminate host-level storage bottlenecks.
Step 2: Linux Kernel and OS Optimization for GPU Inference
Before launching vLLM, optimize the Linux kernel to eliminate socket bottlenecks, IPC latency, and memory page stalls. Place the following tuned parameters into /etc/sysctl.d/99-vllm-gpu-tuning.conf:
# /etc/sysctl.d/99-vllm-gpu-tuning.conf
# High-concurrency network socket and memory tuning for vLLM GPU inference nodes

# Maximum socket receive and send buffer sizes
net.core.rmem_max = 67108864
net.core.wmem_max = 67108864
net.ipv4.tcp_rmem = 4096 87380 67108864
net.ipv4.tcp_wmem = 4096 65536 67108864

# Connection queue capacity for high-concurrency client bursts
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 65535
net.core.netdev_max_backlog = 65535

# Fast socket teardown and reuse
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# Enable BBR Congestion Control for low-latency streaming
net.core.default_qdisc = fq
net.ipv4.tcp_congestion_control = bbr

# Memory management: Prevent swap thrashing and increase virtual memory map capacity
vm.swappiness = 10
vm.max_map_count = 262144
vm.overcommit_memory = 1
fs.file-max = 2097152
Activate the configuration immediately without rebooting:
sudo sysctl --systemNext, lock GPU clocks and enable persistence mode to prevent driver re-initialization latency across process lifecycles:
# Enable NVIDIA GPU persistence mode
sudo nvidia-smi -pm 1

# Optional: Set maximum memory and graphics clocks for consistent latency profiles
sudo nvidia-smi -ac 5001,1590
Step 3: Installing vLLM in an Isolated Production Environment
Always isolate the vLLM environment from system Python packages using Python 3.10+ and a dedicated virtual environment or container. Install the pre-compiled CUDA-accelerated wheel:
# Install system prerequisites
sudo apt update && sudo apt install -y python3-pip python3-venv numactl git curl

# Create dedicated vLLM system user and working directory
sudo useradd -m -s /bin/bash -d /opt/vllm vllm-runner
sudo mkdir -p /opt/vllm/models /opt/vllm/venv /var/log/vllm
sudo chown -R vllm-runner:vllm-runner /opt/vllm /var/log/vllm

# Initialize virtual environment and install vLLM
sudo -u vllm-runner python3 -m venv /opt/vllm/venv
sudo -u vllm-runner /opt/vllm/venv/bin/pip install --upgrade pip
sudo -u vllm-runner /opt/vllm/venv/bin/pip install vllm ray[default] flash-attn --no-build-isolation
Architecture Note: When serving models on Ampere (A100, RTX 3090), Ada Lovelace (L4, L40S, RTX 4090), or Hopper (H100) GPUs, verify that
flash-attninstalls cleanly. FlashAttention-2 accelerates the prefill phase by avoiding materialization of intermediate attention matrices in HBM, maximizing memory bandwidth efficiency.
Step 4: Hardened Systemd Service for Production Supervision
To ensure high availability, automatic crash recovery, process isolation, and graceful shutdowns, create a production systemd service at /etc/systemd/system/vllm.service:
# /etc/systemd/system/vllm.service
[Unit]
Description=vLLM High-Throughput OpenAI-Compatible Inference Server
After=network-online.target time-sync.target
Wants=network-online.target
Documentation=https://docs.vllm.ai/

[Service]
Type=simple
User=vllm-runner
Group=vllm-runner
WorkingDirectory=/opt/vllm

# Environment Variables for CUDA and vLLM Engine
Environment="PATH=/opt/vllm/venv/bin:/usr/local/cuda/bin:/usr/bin:/bin"
Environment="CUDA_VISIBLE_DEVICES=0"
Environment="VLLM_ENGINE_ITERATION_TIMEOUT_S=60"
Environment="NCCL_DEBUG=WARN"
Environment="RAY_memory_monitor_refresh_ms=0"

# Production Executable Command
# Model: meta-llama/Meta-Llama-3-8B-Instruct
# Port: 8000 (Internal binding)
ExecStart=/opt/vllm/venv/bin/python3 -m vllm.entrypoints.openai.api_server \
    --model meta-llama/Meta-Llama-3-8B-Instruct \
    --host 127.0.0.1 \
    --port 8000 \
    --tensor-parallel-size 1 \
    --gpu-memory-utilization 0.90 \
    --max-model-len 8192 \
    --max-num-seqs 256 \
    --block-size 16 \
    --swap-space 4 \
    --enable-chunked-prefill \
    --disable-log-requests

# Process Resiliency and Resource Limits
Restart=always
RestartSec=5s
KillMode=mixed
TimeoutStopSec=30s
LimitNOFILE=1048576
LimitNPROC=1048576
LimitMEMLOCK=infinity

# Security Sandboxing Flags
ProtectSystem=full
ProtectHome=read-only
PrivateTmp=true
NoNewPrivileges=true

[Install]
WantedBy=multi-user.target
Reload systemd and start the vLLM daemon:
sudo systemctl daemon-reload
sudo systemctl enable --now vllm.service
sudo systemctl status vllm.service
Step 5: Nginx Reverse Proxy & Streaming SSE Gateway
The internal vLLM daemon binds to 127.0.0.1:8000. Production clients require TLS termination, request throttling, and unbuffered streaming for Server-Sent Events (SSE). Configure /etc/nginx/conf.d/vllm-proxy.conf:
# /etc/nginx/conf.d/vllm-proxy.conf
# Upstream pool with persistent keepalive connections
upstream vllm_backend {
    server 127.0.0.1:8000;
    keepalive 64;
}

# Rate-limiting zone for token endpoints
limit_req_zone $binary_remote_addr zone=vllm_limit:10m rate=30r/s;

server {
    listen 80;
    server_name llm.yourdomain.com;
    return 301 https://$host$request_uri;
}

server {
    listen 443 ssl http2;
    server_name llm.yourdomain.com;

    # SSL Certificates
    ssl_certificate /etc/letsencrypt/live/llm.yourdomain.com/fullchain.pem;
    ssl_certificate_key /etc/letsencrypt/live/llm.yourdomain.com/privkey.pem;
    ssl_protocols TLSv1.2 TLSv1.3;
    ssl_ciphers HIGH:!aNULL:!MD5;

    # Client payload settings
    client_max_body_size 32M;
    client_body_buffer_size 128k;

    # Health Check Endpoint
    location /health {
        proxy_pass http://vllm_backend/health;
        access_log off;
    }

    # Prometheus Metrics Scraping Endpoint
    location /metrics {
        allow 10.0.0.0/8;
        allow 127.0.0.1;
        deny all;
        proxy_pass http://vllm_backend/metrics;
    }

    # Core OpenAI API Inference Endpoints
    location /v1/ {
        limit_req zone=vllm_limit burst=50 nodelay;

        proxy_pass http://vllm_backend/v1/;
        proxy_http_version 1.1;

        # Keepalive and Connection Headers
        proxy_set_header Connection "";
        proxy_set_header Host $host;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Proto $scheme;

        # CRITICAL: Disable proxy buffering for real-time SSE token streaming
        proxy_buffering off;
        proxy_cache off;
        chunked_transfer_encoding on;

        # Generous timeouts for long reasoning chains and deep generation
        proxy_connect_timeout 30s;
        proxy_send_timeout 300s;
        proxy_read_timeout 600s;
    }
}
Validate the syntax and apply the configuration:
sudo nginx -t && sudo systemctl reload nginxStep 6: Verifying and Benchmarking Streaming Inference
Once the proxy is active, query the OpenAI-compatible completions endpoint to verify token generation speed and streaming mechanics using curl:
curl -N -X POST https://llm.yourdomain.com/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{
    "model": "meta-llama/Meta-Llama-3-8B-Instruct",
    "messages": [
      {"role": "system", "content": "You are a Linux Kernel Architect."},
      {"role": "user", "content": "Explain PagedAttention memory fragmentation in three sentences."}
    ],
    "temperature": 0.2,
    "max_tokens": 150,
    "stream": true
  }'
To quantify production throughput, execute vLLM’s built-in benchmarking harness against synthetic multi-client workloads:
# Benchmark throughput across 1,000 requests at a rate of 20 requests per second
python3 /opt/vllm/venv/bin/benchmark_serving.py \
  --backend vllm \
  --model meta-llama/Meta-Llama-3-8B-Instruct \
  --dataset-name sharegpt \
  --num-prompts 1000 \
  --request-rate 20.0 \
  --host 127.0.0.1 \
  --port 8000
Step 7: Production Telemetry, Prometheus Metrics, and Health Triage
Monitoring vLLM in enterprise production environments requires scraping the native /metrics endpoint into Prometheus and Grafana. Key metrics to monitor on your operational dashboards include:
vllm:num_requests_running: The number of sequences actively generating tokens in the current forward pass.vllm:num_requests_waiting: Sequences queued because GPU KV cache blocks are fully saturated. A sustained count above zero indicates the need for horizontal scaling or model quantization.vllm:gpu_cache_usage_factor: The percentage of allocated KV cache blocks currently in active use. Aim for 75%–85% steady-state utilization.vllm:time_to_first_token_seconds: Distribution of prefill latency experienced by incoming requests.vllm:time_per_output_token_seconds: Inter-token decode latency, determining the human-perceived streaming smoothness.
Frequently Asked Questions: Deploying vLLM on Cloud GPU VPS
How much GPU VRAM is required to run modern 8B and 70B parameter models in vLLM?
In uncompressed 16-bit precision (FP16/BF16), an 8-billion parameter model requires ~16 GB VRAM for model weights plus at least 4-8 GB for the KV cache and activation overhead, making a 24 GB GPU (such as an NVIDIA A10G, L4, or RTX 4090) the minimum production baseline. A 70-billion parameter model in 16-bit requires ~140 GB VRAM, mandating multiple GPUs (e.g., 2x A100-80GB or 4x A40-48GB) orchestrated with tensor parallelism (--tensor-parallel-size 2 or 4). Alternatively, 4-bit AWQ or GPTQ quantization compresses 70B models into ~38-42 GB VRAM, enabling execution on a single 48 GB GPU.
What is the operational difference between static batching and continuous iteration-level batching?
Static batching groups a fixed set of requests together and processes them until the slowest request finishes its complete token generation cycle. If one request requests 1,000 tokens and nine requests ask for 20 tokens, the nine requests hold GPU memory and wait idle until the single 1,000-token request finishes. Continuous iteration-level batching inspects the batch state at every single forward pass step. Finished sequences immediately release their memory blocks and exit, and queued incoming requests are injected on the very next token iteration without stalling execution.
How do you prevent CUDA Out of Memory (CUDA OOM) crashes during high traffic spikes?
Unlike naive PyTorch runtimes which crash with fatal CUDA OOM errors when memory saturates, vLLM pre-allocates a fixed pool of GPU VRAM at initialization controlled by --gpu-memory-utilization (typically set to 0.90). When concurrent requests consume all available physical KV cache blocks, vLLM dynamically handles the contention by queuing new requests (waiting queue) or temporarily preempting lower-priority requests by swapping their KV blocks into system RAM (configured via --swap-space). This ensures the inference daemon remains completely stable and never crashes under load.
Can I prototype and test vLLM API client consumers on free cloud VPS tiers?
Yes. While GPU-accelerated vLLM inference itself requires dedicated NVIDIA hardware, you can develop and test web applications, chat interfaces, middleware proxies, and API client pipelines using free staging environments on CpanelFree. Once your client applications, token streaming consumers, and rate-limiting rules are thoroughly validated, you can seamlessly connect them to production vLLM endpoints hosted on high-performance enterprise infrastructure like MeraHost.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).