
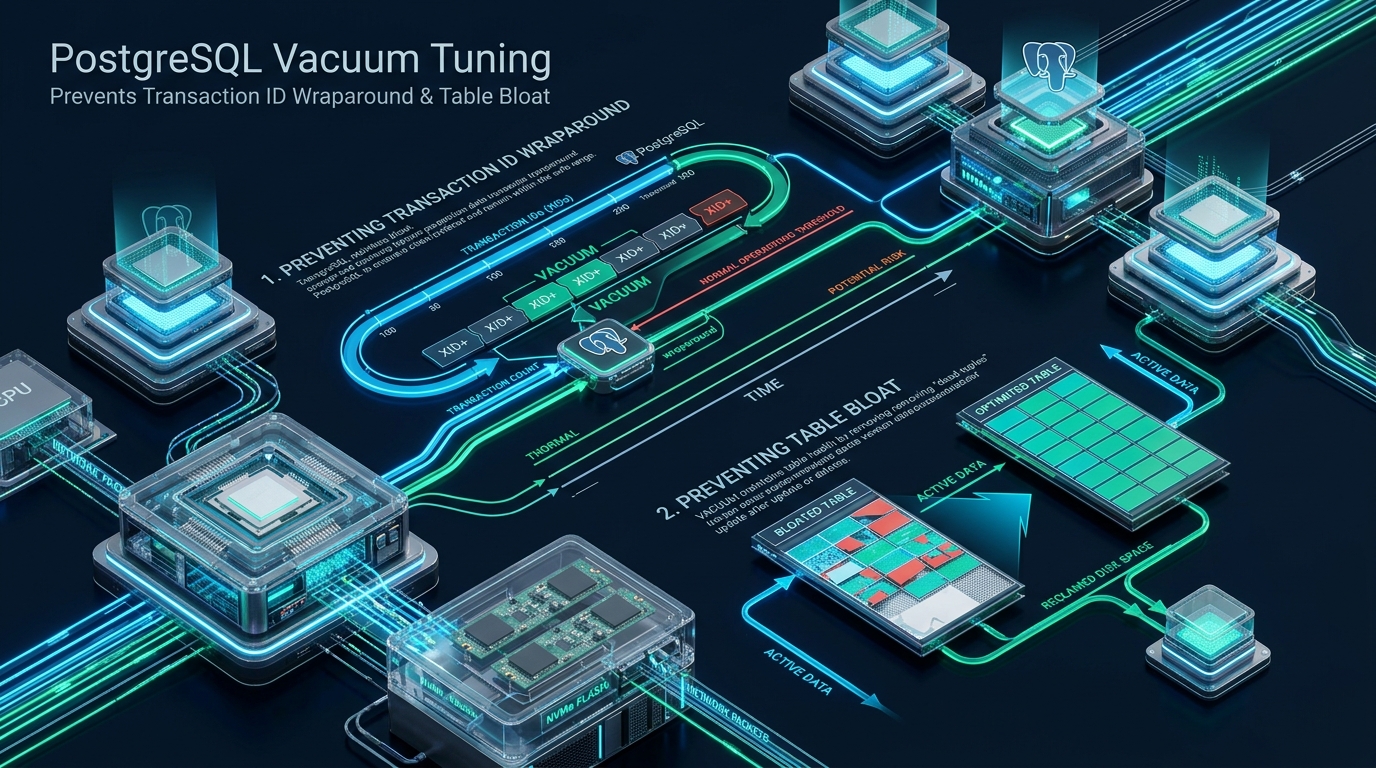
PostgreSQL’s Multi-Version Concurrency Control (MVCC) architecture delivers phenomenal concurrency by treating row updates as non-blocking tuple insertions paired with dead row tombstones. However, under high-throughput production workloads, PostgreSQL’s conservative default autovacuum heuristics fail to reclaim dead tuples at pace with ingestion, triggering severe disk bloat, cache pollution, and the looming existential crisis of 32-bit Transaction ID (XID) wraparound failure. At CpanelFree, operating resilient Linux cloud infrastructure demands aggressive autovacuum tuning, proactive dead tuple remediation, and kernel-level storage optimization to maintain sub-millisecond query latency across terabyte-scale datasets.
PostgreSQL Autovacuum Architecture: The Battle Against Bloat and Wraparound
Tuning PostgreSQL autovacuum to eliminate table bloat requires increasing worker concurrency, scaling up
autovacuum_vacuum_cost_limit, reducing autovacuum_vacuum_scale_factor to 0.02 or lower, and allocating sufficient maintenance_work_mem. Left untuned, dead tuples bloat physical storage and distort planner statistics, ultimately triggering forced emergency vacuuming when database age exceeds autovacuum_freeze_max_age.
To master PostgreSQL maintenance, one must examine how the storage engine persists relational state. When an application executes an UPDATE statement in PostgreSQL, the engine does not perform an in-place overwrite of disk blocks. Instead, it writes an entirely new row version (tuple) into the heap page and writes an expiration timestamp—specifically the current transaction identifier (XID)—into the header field xmax of the previous tuple. The new tuple receives the transaction’s identifier in its xmin header.
Similarly, a DELETE statement simply updates the xmax attribute of the target tuple without freeing physical disk space. These expired, invisible records are known as dead tuples. Dead tuples remain permanently inside 8 KB relation data pages until a VACUUM operation sweeps the table, records free space in the Free Space Map (FSM), and flags those page offsets as reusable for subsequent INSERT or UPDATE operations.
UPDATE statement never overwrites existing bytes on disk. Instead, the engine marks the previous tuple as obsolete by setting its xmax header to the current transaction ID, writing a brand new tuple with its own xmin header. Without continuous autovacuum sweeps, physical heap pages remain pinned with dead rows, forcing sequential scans and index traversals across gigabytes of phantom data.The Anatomy of Table and Index Bloat
Table bloat occurs when the creation rate of dead tuples significantly outpaces the rate at which autovacuum processes pages. When an 8 KB page becomes saturated with dead tuples and free space is fragmented, newly arriving rows cannot fit into existing pages. PostgreSQL must allocate new pages from the underlying filesystem, expanding the physical size of the table file in $PGDATA/base/.
Even worse is B-tree index bloat. When indexed columns undergo updates, new index entries must be created pointing to new heap tuples. While PostgreSQL includes Heap-Only Tuples (HOT) optimization—allowing updates on the same page without updating index entries if no indexed columns are modified—any update touching an indexed attribute forces index page splits. Over time, B-tree indexes degrade into sparse, half-empty structures where point queries require traversing three to five times more index pages than necessary, destroying L1/L2 CPU cache locality and saturating the PostgreSQL shared buffer pool.
The Autovacuum Trigger Formula
Autovacuum relies on two mathematical thresholds calculated by the PostgreSQL background statistics collector to determine when a table requires a vacuum or an analyze pass:
# Autovacuum Vacuum Threshold Formula:
vacuum_trigger = autovacuum_vacuum_threshold + (autovacuum_vacuum_scale_factor * reltuples)

# Autovacuum Analyze Threshold Formula:
analyze_trigger = autovacuum_analyze_threshold + (autovacuum_analyze_scale_factor * reltuples)
Consider the disastrous consequences of default settings on high-volume production tables. The default autovacuum_vacuum_scale_factor is 0.2 (20%), and autovacuum_vacuum_threshold is 50:
- On a small table with 10,000 rows: autovacuum triggers after
50 + (0.20 * 10,000) = 2,050dead rows. This works fine. - On an enterprise table with 50,000,000 rows: autovacuum will not trigger until
50 + (0.20 * 50,000,000) = 10,000,050dead rows accumulate!
Permitting 10 million dead rows to accumulate before initiating a cleanup sweep guarantees catastrophic I/O spikes. When autovacuum finally triggers on that 50-million-row table, the vacuum worker must scan hundreds of thousands of heap pages and multiple gigabytes of indexes simultaneously, consuming all available disk I/O and stalling user-facing transactions.
Transaction ID (XID) Wraparound: The 32-Bit Finite Horizon
While table bloat causes severe performance degradation and disk exhaustion, Transaction ID (XID) wraparound represents an existential threat: unmanaged wraparound leads to automatic database shutdown and potential silent data loss.
PostgreSQL identifies all transactions using a 32-bit unsigned integer, yielding a total capacity of approximately 4,294,967,296 (4.29 billion) transaction IDs. Because transaction numbers continually increment, PostgreSQL implements a circular modulo-232 arithmetic comparison:
# Modulo-2^32 Comparison Logic:
if (XID_2 - XID_1) < 2^31:
    XID_1 occurred in the past relative to XID_2 (visible)
else:
    XID_1 occurred in the future relative to XID_2 (invisible)
At any given moment, 2 billion transaction IDs represent the “past” (visible to running transactions), and 2 billion transaction IDs represent the “future” (invisible). As the current XID counter approaches 2.14 billion transactions beyond an ancient row’s creation XID, that ancient row would suddenly appear to have been created in the future, instantly rendering committed historical data completely invisible to all queries.
xmin with a special flag FrozenTransactionId (value 2), signaling to the MVCC visibility engine that the row was committed infinitely far in the past and is perpetually visible to all current and future transactions.The Anti-Wraparound Fail-Safe Mechanism
PostgreSQL enforces multiple defense rings to guarantee that XID wraparound never occurs silently:
- Normal Autovacuum Freeze: When a table’s oldest unfrozen XID exceeds
vacuum_freeze_min_age(default 50 million transactions), normal autovacuum sweeps proactively freeze eligible tuples. - Forced Anti-Wraparound Autovacuum: When the age of any table or database exceeds
autovacuum_freeze_max_age(default 200 million transactions), PostgreSQL launches an aggressive anti-wraparound autovacuum. This worker process cannot be cancelled by administrative commands, ignoresautovacuum = off, and operates continuously until the oldest XID is advanced. - Emergency Read-Only Shutdown: If anti-wraparound vacuuming fails to keep pace and only 3,000,000 transactions remain before wraparound, PostgreSQL halts all write operations, terminates client connections, and enters a forced emergency read-only state, requiring manual single-user mode intervention.
Tuning Matrix: Default vs. Enterprise Production Configurations
The following comparative matrix outlines key vacuum and kernel parameters, detailing why out-of-the-box defaults must be tuned for production cloud infrastructure:
Real Production Configuration Files
Deploying an enterprise-grade PostgreSQL cluster requires tuning both the database engine parameters and the underlying Linux kernel memory subsystem. Below are battle-tested configuration files ready for immediate deployment.
1. PostgreSQL Autovacuum & Resource Tuning Configuration
Save the following configuration to /etc/postgresql/16/main/conf.d/99-autovacuum-tuning.conf:
# ====================================================================
# CpanelFree Enterprise PostgreSQL 16 Autovacuum & Storage Tuning
# Location: /etc/postgresql/16/main/conf.d/99-autovacuum-tuning.conf
# ====================================================================

# Enable autovacuum subsystem
autovacuum = on

# Increase worker count to match CPU core availability
# Allows concurrent vacuuming across partitioned tables
autovacuum_max_workers = 6

# Sleep time between autovacuum daemon wakeups
autovacuum_naptime = 15s

# Drastically reduce scale factors to trigger early, incremental vacuums
autovacuum_vacuum_scale_factor = 0.02
autovacuum_analyze_scale_factor = 0.01

# Minimum number of row updates/deletes before triggering vacuum/analyze
autovacuum_vacuum_threshold = 50
autovacuum_analyze_threshold = 50

# Cost-based vacuum delay parameters
# In modern NVMe environments, cost limit must be high to avoid artificial bottlenecks
autovacuum_vacuum_cost_delay = 2ms
autovacuum_vacuum_cost_limit = 3000

# Allocate ample memory for dead tuple TID collection in RAM (max 1GB per worker)
# 1GB holds ~178 million dead tuple pointers per index sweep pass
maintenance_work_mem = 1GB
autovacuum_work_mem = -1  # Inherits from maintenance_work_mem

# Max parallel workers for manual VACUUM and CREATE INDEX
max_parallel_maintenance_workers = 4

# Transaction ID Wraparound & Freeze Tuning
# Default 200M is often too aggressive for terabyte tables; 1B provides ample headroom
autovacuum_freeze_max_age = 1000000000
autovacuum_multixact_freeze_max_age = 1200000000
vacuum_freeze_min_age = 50000000
vacuum_freeze_table_age = 800000000

# Log autovacuum runs exceeding 500 milliseconds for APM telemetry
log_autovacuum_min_duration = 500ms
2. Linux Kernel Virtual Memory & Storage sysctl Tuning
Autovacuum generates substantial background write traffic as it modifies data pages and updates the Free Space Map. Without kernel tuning, the Linux kernel will accumulate massive dirty page buffers before flushing them in violent bursts, causing severe disk latency spikes. Deploy this configuration to /etc/sysctl.d/99-postgresql-storage.conf:
# ====================================================================
# CpanelFree Linux Kernel Tuning for PostgreSQL High-I/O Workloads
# Location: /etc/sysctl.d/99-postgresql-storage.conf
# ====================================================================

# Start flushing dirty pages to NVMe storage early to avoid I/O stalls
vm.dirty_background_ratio = 3
vm.dirty_ratio = 8

# Flush dirty memory pages every 5 seconds (500 centisecs)
vm.dirty_expire_centisecs = 500
vm.dirty_writeback_centisecs = 250

# Prevent kernel memory overcommit disasters
vm.overcommit_memory = 2
vm.overcommit_ratio = 85

# Reduce swappiness to keep PostgreSQL shared buffers resident in physical RAM
vm.swappiness = 1

# Increase max open file descriptors for large database clusters
fs.file-max = 2097152
Apply the kernel parameters immediately with:
sudo sysctl --system3. Per-Table Granular Autovacuum Overrides
Global configuration parameters provide a sound baseline, but high-velocity tables (such as message queues, audit logs, or session caches) require bespoke tuning. PostgreSQL allows administrators to apply storage parameters directly to individual tables:
-- Tune a high-throughput session table with millions of daily updates/deletes
ALTER TABLE app_sessions SET (
    autovacuum_vacuum_scale_factor = 0.005,  -- Trigger vacuum at 0.5% dead tuples
    autovacuum_vacuum_threshold = 100,
    autovacuum_vacuum_cost_limit = 5000,     -- Dedicated high cost budget
    autovacuum_vacuum_cost_delay = 0         -- Run at maximum unthrottled speed
);

-- Adjust fillfactor for tables subject to frequent in-place updates to enable HOT
ALTER TABLE user_profiles SET (fillfactor = 85);
Real-World Telemetry: Monitoring Bloat and XID Age
Enterprise database reliability requires continuous observability. The following production-tested SQL queries provide instant insight into database health, dead tuple volume, and XID wraparound proximity.
1. Auditing Database Transaction ID (XID) Age
Execute this query to verify that no database is approaching autovacuum_freeze_max_age:
SELECT
    datname,
    age(datfrozenxid) AS xid_age,
    2147483648 - age(datfrozenxid) AS tx_until_wraparound,
    ROUND(100.0 * age(datfrozenxid) / 2147483648, 2) AS wraparound_risk_pct
FROM pg_database
WHERE datallowconn
ORDER BY xid_age DESC;
2. Identifying Bloated Tables and Dead Tuple Ratios
This query inspects pg_stat_user_tables to identify relations where dead tuples represent a substantial percentage of total storage:
SELECT
    schemaname,
    relname AS table_name,
    n_live_tup AS live_tuples,
    n_dead_tup AS dead_tuples,
    ROUND(100.0 * n_dead_tup / NULLIF(n_live_tup + n_dead_tup, 0), 2) AS dead_tuple_pct,
    last_autovacuum,
    last_autoanalyze
FROM pg_stat_user_tables
WHERE (n_live_tup + n_dead_tup) > 10000
ORDER BY n_dead_tup DESC
LIMIT 15;
Safe Online Bloat Remediation: pg_repack vs. VACUUM FULL
When table bloat has already accumulated to unacceptable levels, standard VACUUM is insufficient because it only marks space in the Free Space Map—it does not return allocated disk blocks back to the underlying Linux filesystem. Administrators face two primary solutions:
- VACUUM FULL: Completely rewrites the table into a fresh disk file, stripping all bloat and returning space to the OS. Caveat:
VACUUM FULLacquires an exclusiveACCESS EXCLUSIVElock on the relation, blocking all concurrentSELECT,INSERT,UPDATE, andDELETEqueries for the duration of the operation. In production, this guarantees an application outage. - pg_repack: The gold standard for zero-downtime online bloat remediation.
pg_repackcreates a temporary shadow table, copies existing rows, creates a trigger to capture concurrent DML modifications, builds new indexes, and performs a brief metadata swap under a short exclusive lock, reclaiming gigabytes of disk space without interrupting application queries.
# Install pg_repack on Debian/Ubuntu systems
sudo apt-get install postgresql-16-repack

# Run online repack on a bloated production table without locking reads/writes
pg_repack -d production_db -t app_sessions --no-kill-backend
Frequently Asked Questions
Why doesn’t standard VACUUM release disk space back to the Linux filesystem?
Standard VACUUM operates strictly within existing 8 KB heap pages. When dead tuples are purged, the liberated space is cataloged in the table’s Free Space Map (FSM) so future INSERT and UPDATE queries can reuse those page slots. PostgreSQL will only return disk space to the OS if completely empty pages exist at the very end (tail) of the physical table file. To return all allocated space from interior pages, you must perform an online table rebuild using pg_repack or execute VACUUM FULL during an approved maintenance window.
How does maintenance_work_mem directly affect autovacuum execution speed?
During the first phase of a vacuum sweep, the worker scans heap pages and collects the physical pointers (ItemPointer / TID: BlockNumber + OffsetNumber) of all dead tuples into a memory array sized by maintenance_work_mem. If maintenance_work_mem is too small (e.g., default 64 MB), the array fills up quickly, forcing the worker to pause the heap scan and iterate across all table indexes to purge those pointers before returning to scan remaining heap pages. Setting maintenance_work_mem = 1GB allows the worker to collect up to 178 million dead tuple pointers in a single pass, eliminating costly multi-pass index iterations.
What immediate actions should be taken if PostgreSQL halts due to XID wraparound?
If PostgreSQL enters emergency shutdown due to impending wraparound (within 3 million transactions of failure), normal connections are refused. You must stop the PostgreSQL service and start the server in single-user mode: postgres --single -D /var/lib/postgresql/data -P databasename. In single-user mode, run VACUUM FREEZE; on the affected databases. Single-user mode disables normal autovacuum overhead and runs with full administrative priority, advancing datfrozenxid and restoring normal operations.
What is the performance impact of lowering autovacuum_vacuum_scale_factor?
Lowering autovacuum_vacuum_scale_factor from 0.20 to 0.02 causes autovacuum to trigger much more frequently in smaller, incremental bursts. Rather than waiting for 20% of a massive table to become dead before launching a massive, multi-hour vacuum pass that saturates disk I/O, autovacuum cleans up 2% dead tuples in seconds. Combined with modern NVMe flash arrays and a tuned autovacuum_vacuum_cost_limit, this produces consistent query latency and eliminates table bloat.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.