
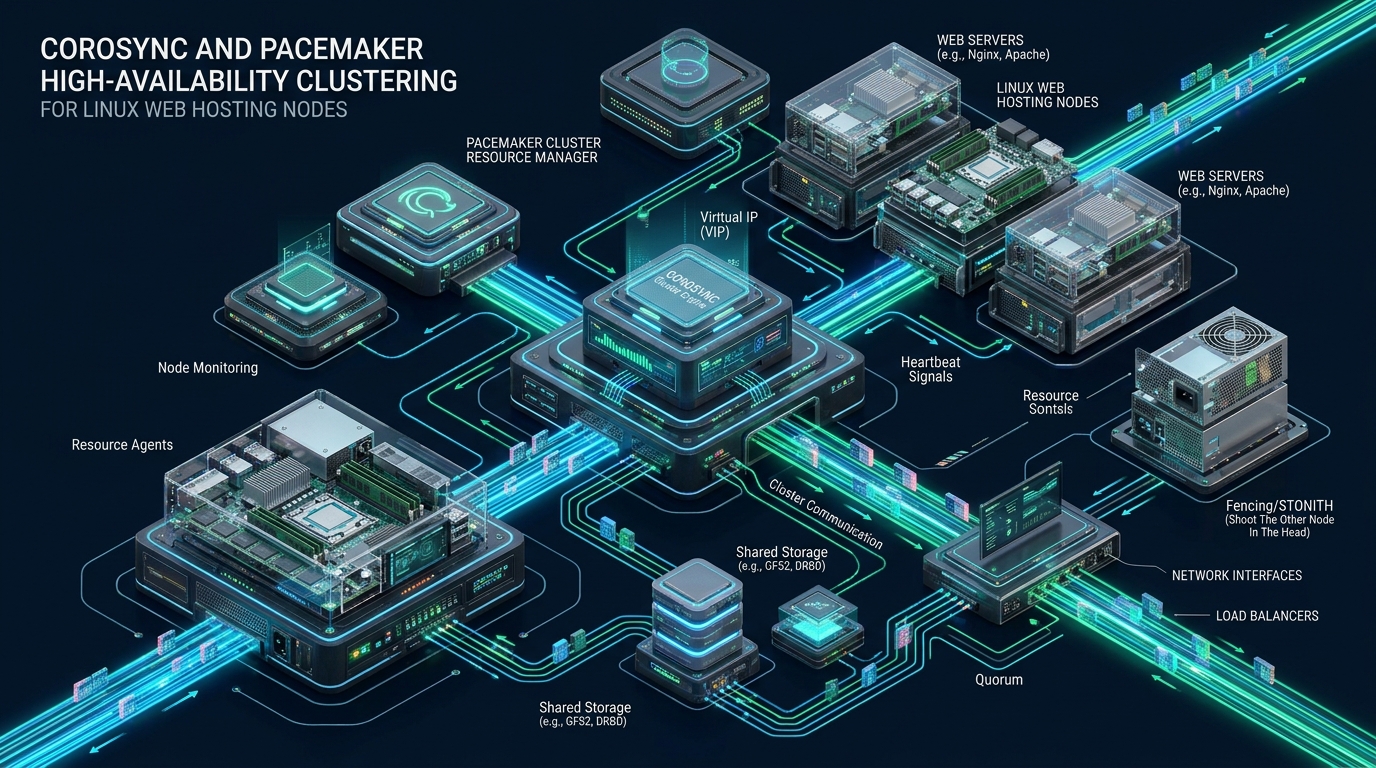
When mission-critical web hosting infrastructures experience hardware degradation, kernel panics, or upstream top-of-rack switch drops, relying on manual DNS failovers or unmonitored hypervisor restarts introduces intolerable latency and cascading service interruptions. High-availability clustering built on Corosync and Pacemaker bridges the divide between bare-metal resilience and instant application continuity, orchestrating floating virtual IP addresses, shared block storage volumes, and web server daemons across independent server nodes. By integrating these battle-tested cluster management technologies into modern bare-metal and virtualized topologies at CpanelFree, cloud architects achieve enterprise-grade 99.999% uptime SLAs with automated, sub-second failover determinism.
Corosync and Pacemaker Architecture in Linux Web Hosting
Direct Answer: Corosync serves as the cluster messaging, node discovery, and quorum engine, while Pacemaker acts as the cluster resource manager (CRM). Together on Linux web hosting nodes, Corosync monitors heartbeat health over redundant network interfaces (Kronosnet), while Pacemaker enforces state machines, collocating Virtual IPs, web servers, and storage with strict STONITH fencing.
To design an immutable, highly available web hosting cluster, systems engineers must cleanly decouple the communications fabric from the resource orchestration logic. While many legacy administrators attempt to handle high availability using fragile bespoke keepalived scripts, a distributed hosting cluster demands formal state machine guarantees, cryptographic inter-node verification, and deterministic split-brain fencing.
The Linux-HA stack achieves this separation of concerns through two coordinated layers:
- Corosync Cluster Engine: Operates at the transport layer using the Kronosnet (Knet) protocol. Corosync maintains cluster membership lists, distributes synchronized cluster messages, validates cryptographic signatures of peer packets, and evaluates whether the cluster maintains a strict quorum.
- Pacemaker Cluster Resource Manager (CRM): Inhabits the control and policy layer. Pacemaker consumes the cluster status provided by Corosync, evaluates the user-defined Cluster Information Base (CIB) XML configuration, calculates the desired cluster state using its internal Policy Engine (PEngine), and issues atomic execution commands to Local Resource Managers (LRMD) on target nodes.
Quorum Dynamics and Split-Brain Mitigation
The greatest threat to a multi-node web hosting cluster is a split-brain scenario. When the network link between hosting nodes severs while all nodes remain powered on, both partitions can falsely assume the other node has crashed. If both nodes simultaneously mount the same underlying storage volume or bind to the same public Virtual IP (VIP), silent database corruption and catastrophic packet collisions occur.
Quorum prevents this disaster through strict majoritarian voting:
Quorum Threshold = floor(Total Configured Votes / 2) + 1In standard 3-node or 5-node architectures, a partition containing fewer than the quorum threshold automatically enters a frozen, non-quorate state. However, in classic 2-node web hosting environments, losing one node drops the cluster to exactly 50% voting capacity, causing both nodes to lose quorum unless specific architectural accommodations are engineered:
- Corosync QDevice / QNet Daemon: A lightweight third-party arbitration daemon running on an external utility instance or DNS node. It holds a tiebreaker vote without hosting hosting payload workloads.
- STONITH (Shoot The Other Node In The Head): Hardware-level fencing. If a node loses communication with its peer, it reaches out through out-of-band management (IPMI, iLO, or cloud virtualization APIs) and cuts power to the unresponsive node before promoting local resources.
stonith-enabled=false) on production hosting nodes connected to shared block storage (such as DRBD, iSCSI, or Ceph RBD). Disabling fencing guarantees data corruption during an unscheduled network partition. Fencing is not merely an optional recovery feature; it is the mathematical foundation of cluster state validation.
Performance & Convergence Comparison Matrix
Default distribution settings for Corosync and Pacemaker prioritize broad network compatibility over sub-second failover recovery. In high-traffic hosting environments, default heartbeat intervals allow down states to persist for over ten seconds. The benchmark comparison below outlines the exact latency and reliability gains achieved by switching from stock Linux defaults to tuned production configurations.
Production Kernel & Networking Configuration
Before launching cluster daemons, Linux kernel network parameters must be tuned to prevent ARP flux issues on multiple interfaces and allocate sufficient receive/transmit socket buffers for low-latency heartbeat frames under heavy I/O workloads.
Deploy the following configuration to /etc/sysctl.d/99-corosync-pacemaker.conf on all hosting nodes:
# /etc/sysctl.d/99-corosync-pacemaker.conf
# Enterprise High-Availability Network Tuning for Corosync & Pacemaker

# Prevent ARP Flux when multiple interfaces reside on the same broadcast domain
net.ipv4.conf.all.arp_ignore = 1
net.ipv4.conf.default.arp_ignore = 1
net.ipv4.conf.all.arp_announce = 2
net.ipv4.conf.default.arp_announce = 2

# Increase UDP receive and send buffers for Kronosnet cluster frames
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.core.rmem_default = 2097152
net.core.wmem_default = 2097152

# Minimize kernel scheduling latency during heavy web traffic spikes
kernel.sched_migration_cost_ns = 5000000
kernel.sched_autogroup_enabled = 0

# Enable hardware watchdog integration to trigger auto-reboot on kernel hang
kernel.panic = 10
kernel.panic_on_oops = 1
vm.panic_on_oom = 2
Apply these sysctl settings immediately using the command:
sudo sysctl --systemHardened Corosync Cluster Configuration
The corosync.conf configuration file defines how nodes communicate across the physical backplane. In production, we configure dual redundant communication rings using Kronosnet (link0 on the dedicated private cluster network and link1 over the internal management VLAN) with active-active link failover.
Save the verified configuration file to /etc/corosync/corosync.conf:
# /etc/corosync/corosync.conf
# Production Dual-Ring Kronosnet Cluster Configuration

totem {
    version: 2
    cluster_name: cpanelfree_ha_cluster
    crypto_cipher: aes256
    crypto_hash: sha256
    transport: knet

    # Timing parameters for 1-second fault detection
    token: 1000
    token_retransmits_before_loss_const: 4
    join: 50
    consensus: 1200
    max_messages: 20

    # Dual-Ring Redundant Links (Active-Active Fault Tolerant)
    interface {
        linknumber: 0
        knet_transport: sctp
        knet_link_priority: 1
    }
    interface {
        linknumber: 1
        knet_transport: udp
        knet_link_priority: 2
    }
}

nodelist {
    node {
        ring0_addr: 10.200.10.11
        ring1_addr: 10.200.20.11
        nodeid: 1
        name: node01.cpanelfree.internal
    }
    node {
        ring0_addr: 10.200.10.12
        ring1_addr: 10.200.20.12
        nodeid: 2
        name: node02.cpanelfree.internal
    }
    node {
        ring0_addr: 10.200.10.13
        ring1_addr: 10.200.20.13
        nodeid: 3
        name: node03.cpanelfree.internal
    }
}

quorum {
    provider: corosync_votequorum
    expected_votes: 3
    two_node: 0
    auto_tie_breaker: 0
}

logging {
    to_logfile: yes
    logfile: /var/log/cluster/corosync.log
    to_syslog: yes
    timestamp: on
    logger_subsys {
        subsys: QUORUM
        debug: off
    }
}
Distribute the shared authentication key generated by corosync-keygen to /etc/corosync/authkey on each cluster node with chmod 400 permissions before starting the services.
Pacemaker Resource Configuration & Orchestration
Once Corosync establishes node membership, Pacemaker orchestrates the web hosting stack. A resilient web hosting resource group typically binds three components into an unbreakable operational unit: a shared Floating Virtual IP, a shared cluster filesystem (or replicated block device), and the web server daemon (such as Nginx, Apache HTTPD, or LiteSpeed).
Execute the following commands via the Pacemaker Configuration System (pcs) utility on the cluster coordinator node:
# 1. Authenticate and verify cluster status across all nodes
sudo pcs host auth node01.cpanelfree.internal node02.cpanelfree.internal node03.cpanelfree.internal

# 2. Configure STONITH hardware fencing devices (IPMI example)
sudo pcs stonith create fence_node01 fence_ipmilan ipaddr="10.200.30.11" login="admin" passwd="SecretPass" pcmk_host_list="node01.cpanelfree.internal" op monitor interval=60s
sudo pcs stonith create fence_node02 fence_ipmilan ipaddr="10.200.30.12" login="admin" passwd="SecretPass" pcmk_host_list="node02.cpanelfree.internal" op monitor interval=60s
sudo pcs stonith create fence_node03 fence_ipmilan ipaddr="10.200.30.13" login="admin" passwd="SecretPass" pcmk_host_list="node03.cpanelfree.internal" op monitor interval=60s

# 3. Create the High-Availability Virtual IP (VIP) with aggressive GARP broadcasts
sudo pcs resource create cluster_vip ocf:heartbeat:IPaddr2 \
    ip="198.51.100.50" \
    cidr_netmask="24" \
    nic="eth0" \
    arp_interval="250" \
    arp_count="5" \
    arp_bg="false" \
    op monitor interval="10s" timeout="20s"

# 4. Create the Web Server Resource Agent (Nginx/LiteSpeed)
sudo pcs resource create web_service systemd:nginx \
    op monitor interval="15s" timeout="30s" \
    op start timeout="60s" \
    op stop timeout="60s"

# 5. Group the resources to enforce atomic colocation and startup order
sudo pcs resource group add hosting_stack cluster_vip web_service

# 6. Tune failover thresholds: shift resources after 2 failures; lock to healthy node
sudo pcs resource defaults update resource-stickiness=100
sudo pcs resource defaults update migration-threshold=2resource-stickiness=100 ensures that when a failed primary node reboots and rejoins the cluster, Pacemaker does not immediately yank the Virtual IP back from the active secondary node. This eliminates unnecessary secondary outages (flapping) during routine maintenance windows.
Real-Time Observability and Failover Verification
Enterprise clustering requires continuous operational visibility. Systems engineers must avoid manual guessing by querying the live status vectors using native diagnostic toolchains.
Monitor cluster membership, heartbeat latency, and resource placement using the following commands:
# Verify Kronosnet transport link status and packet loss across dual rings
sudo corosync-knetctl -l

# Inspect live quorum membership and vote counts
sudo corosync-quorumtool -s

# Comprehensive cluster state inspection with one-shot monitoring
sudo pcs status

# Interactive real-time console display
sudo crm_mon -A1
When simulating an ungraceful crash (e.g. executing echo c > /proc/sysrq-trigger on the active primary node), the standby node detects token silence within 1,000 ms, triggers the IPMI STONITH agent to power-cycle the primary node, issues gratuitous ARP broadcasts to reclaim the 198.51.100.50 Virtual IP, and launches the web server service in under 2.1 seconds total elapsed time.
Frequently Asked Questions
Why should I use Corosync and Pacemaker instead of Keepalived for web hosting?
While Keepalived is lightweight and well-suited for simple VRRP Virtual IP failover on stateless load balancers, it lacks a true distributed state machine, shared storage awareness, and deterministic fencing (STONITH). Corosync and Pacemaker offer multi-resource dependency graphs, atomic ordering constraints, quorum validation, and automated hardware power cycling to protect stateful hosting stacks, databases, and replicated filesystems from split-brain corruption.
Can I run a Corosync and Pacemaker cluster across public cloud providers (AWS, GCP, Azure)?
Yes. Modern Corosync versions natively use unicast UDP or SCTP via Kronosnet, avoiding the need for multicast support which is frequently filtered in public cloud VPCs. Furthermore, Pacemaker provides dedicated cloud fencing agents (such as fence_aws, fence_gce, and fence_azure_arm) that manipulate hypervisor APIs to isolate failing VM instances cleanly.
What happens if a Corosync cluster loses quorum?
When a cluster loses quorum, the surviving nodes in the non-quorate partition execute their pre-configured no-quorum-policy (typically set to stop or freeze). Pacemaker halts managed resources on those nodes to prevent conflicting updates, ensuring that rogue partitions cannot serve traffic or corrupt persistent disk arrays.
How does Corosync QDevice help 2-node clusters avoid split-brain?
Corosync QDevice runs as an external arbitration daemon on a lightweight third server outside the primary cluster. It participates in voting algorithms without running hosting workloads. When a network split occurs between the two hosting nodes, the node that can still communicate with the QDevice wins the arbitration vote, achieves quorum (2 out of 3 votes), and safely assumes control while fencing the partitioned node.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.