
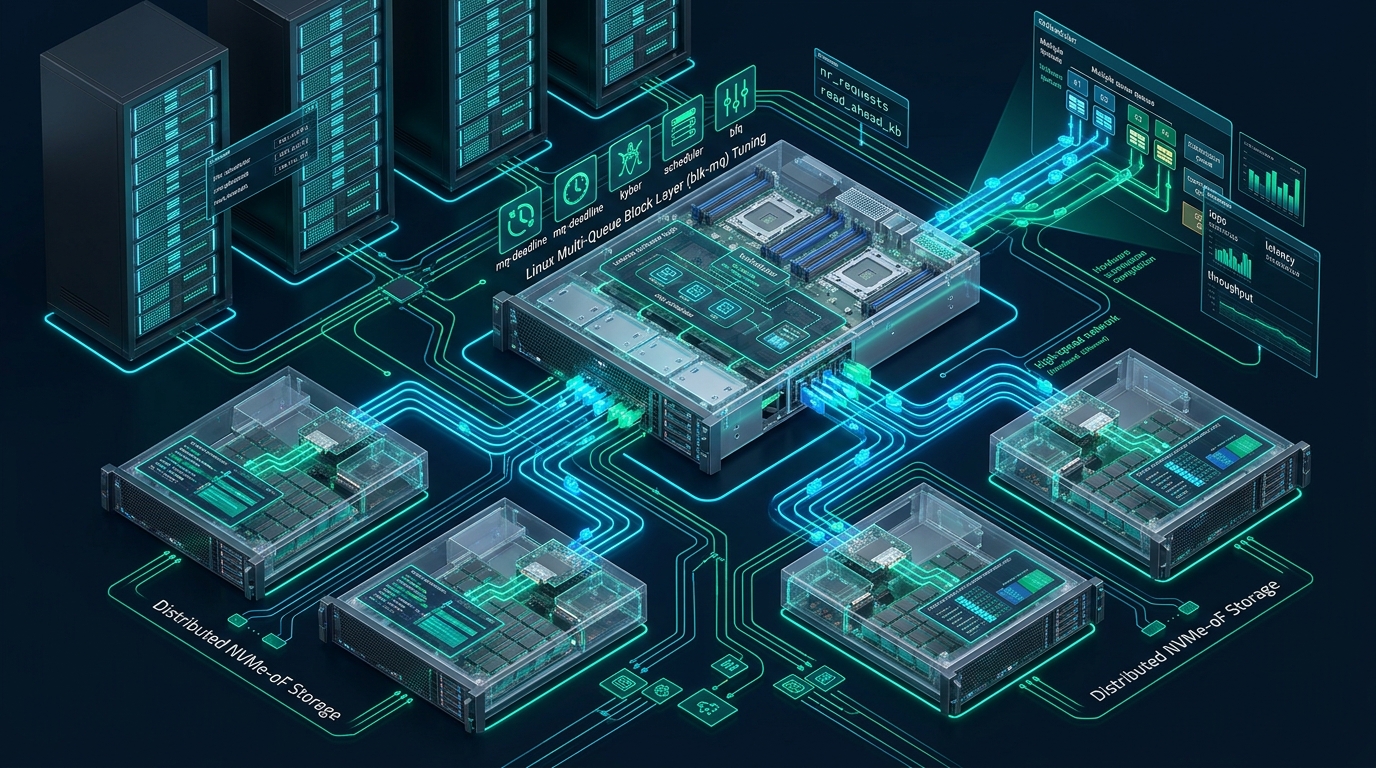
In modern multi-tenant cloud architectures and distributed storage platforms, standard storage I/O paths frequently degrade into catastrophic throughput bottlenecks when subjected to microsecond-scale solid-state media. Traditional single-queue kernel block layers were engineered around the rotational mechanics of spinning disks, relying on global request locks that severely choke under the parallel demands of millions of IOPS generated by NVMe-over-Fabrics (NVMe-oF) fabrics—an operational barrier we continuously dismantle for mission-critical workloads at CpanelFree. By strategically tuning the Linux Multi-Queue Block Layer (blk-mq), platform engineers can eradicate software lock contention, bind CPU cores natively to hardware submission queues, and achieve sub-100-microsecond deterministic tail latencies across RoCEv2, InfiniBand, and NVMe/TCP deployments.
What Is Linux blk-mq NVMe-oF Tuning?
none I/O scheduler, aligning queue depths, tuning polling intervals, and pinning hardware completion interrupts across NUMA nodes, systems achieve deterministic microsecond tail latencies and multi-million IOPS throughput.When enterprise systems scale distributed storage across fabric networks, the bottleneck rarely resides within the physical flash memory cells or the network fabric alone. Instead, the primary constraint emerges inside the Linux operating system kernel where I/O requests are prepared, merged, queued, and dispatched. Distributed storage protocols such as NVMe over RDMA (RoCEv2) and NVMe/TCP bypass traditional SCSI transport stacks, yet without precise configuration of the multi-queue subsystem, kernel worker threads spend excessive cycles competing for centralized spinlocks and thrashing CPU L3 cache lines across NUMA sockets.
Architectural Anatomy: The Two-Tier Linux blk-mq Subsystem
The Linux Multi-Queue Block Layer architecture divides I/O operations into two distinct, decoupled hierarchies: software staging queues (software queues) and hardware dispatch queues (hardware queues or hw_queues). Understanding this separation is essential for configuring distributed storage targets and initiators:
- Per-CPU Software Staging Queues: The Linux kernel maintains an individual software queue for every logical CPU core present on the system. When a userspace thread submits an I/O request via POSIX asynchronous calls or
io_uring, the request enters the local CPU core’s queue without acquiring global locks or traversing memory across CPU sockets. - Hardware Dispatch Queues (hctx): The block layer maps these per-CPU software queues onto a collection of hardware dispatch queues negotiated by the underlying transport driver (e.g.,
nvme-rdmaornvme-tcp). In an ideal enterprise deployment, the number of hardware queues matches or scales proportionally to the CPU topology, ensuring zero lock contention during command dispatch. - Lockless Tag Allocation (sbitmap): Command tagging in
blk-mqutilizes scalable bitmap structures (sbitmap). Rather than locking an atomic counter, threads allocate command tags concurrently across partitioned word bits, virtually eliminating memory bus serialization under massive concurrency.
Comparative Matrix: Standard vs. Production Tuned blk-mq
The following performance matrix demonstrates the quantifiable operational advantages achieved when migrating from default kernel parameters to a fully tuned blk-mq storage stack running on an active NVMe-oF fabric:
Production Kernel Configuration: /etc/sysctl.d/99-nvme-of-performance.conf
Tuning distributed storage at the block layer requires harmonic coordination with the network subsystem and memory management primitives. For NVMe/TCP and RoCEv2 fabrics, socket buffer exhaustion and premature dirty page throttling will trigger artificial request stalls in the blk-mq software queues. Deploy the following hardened production configuration:
# ==============================================================================
# Linux Multi-Queue Block Layer & NVMe-oF High-Throughput Optimization
# Target: Production NVMe-over-Fabrics Initiators & Storage Targets
# Path: /etc/sysctl.d/99-nvme-of-performance.conf
# ==============================================================================

# Maximize socket memory buffers for high-bandwidth NVMe/TCP data transfers
net.core.rmem_max = 67108864
net.core.wmem_max = 67108864
net.core.rmem_default = 33554432
net.core.wmem_default = 33554432
net.core.optmem_max = 2048576

# Tune TCP auto-tuning buffer windows (min, default, max in bytes)
net.ipv4.tcp_rmem = 4096 87380 67108864
net.ipv4.tcp_wmem = 4096 65536 67108864

# High-density network backlog processing for incoming storage frame bursts
net.core.netdev_max_backlog = 250000
net.core.somaxconn = 65535

# Enable TCP BBR or tuned Cubic with zero-timestamp overhead
net.ipv4.tcp_congestion_control = bbr
net.ipv4.tcp_slow_start_after_idle = 0
net.ipv4.tcp_notsent_lowat = 16384

# Prevent dirty page writeback throttling from stalling blk-mq dispatches
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10
vm.dirty_expire_centisecs = 1000
vm.dirty_writeback_centisecs = 250

# Disable aggressive NUMA memory page balancing overhead
kernel.numa_balancing = 0

# Increase maximum asynchronous I/O concurrent request contexts
fs.aio-max-nr = 10485760
fs.file-max = 20971520
Activate the settings immediately without rebooting via:
sudo sysctl --systemAutomating Block Layer Parameters with Persistent Udev Rules
When remote NVMe namespaces are connected over fabric transports (using nvme connect), the Linux kernel dynamically instantiates block devices such as /dev/nvme0n1. By default, systems may assign elevator schedulers like mq-deadline or bfq, which introduce unnecessary sorting logic, request merging overhead, and lock contention. For flash media capable of microsecond response times, the optimal scheduler is none.
Furthermore, tuning nr_requests (the depth of the block layer queue) and adjusting read_ahead_kb to avoid saturating fabric links with unsolicited read data is essential. Create the persistent udev rule below:
# ==============================================================================
# Persistent Udev Rules for blk-mq on NVMe-oF Block Devices
# Path: /etc/udev/rules.d/60-nvme-blkmq.rules
# ==============================================================================

# Apply zero-overhead bypass scheduler (none) to all NVMe block devices
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/scheduler}="none"

# Expand request queue depth to prevent blk-mq tag exhaustion during peak I/O
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/nr_requests}="2048"

# Reduce readahead cache window to avoid fabric queue pollution on random workloads
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/read_ahead_kb}="128"

# Disable rotational heuristics and enable write-cache optimizations
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/rotational}="0"
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/nomerges}="1"
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/rq_affinity}="2"
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/io_poll}="1"
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/io_poll_delay}="0"
Reload and trigger the udev subsystem across active devices:
sudo udevadm control --reload-rules && sudo udevadm trigger --subsystem-match=blockrq_affinity=2 forces hardware interrupt completions to be processed strictly on the CPU core that initiated the I/O request. This avoids CPU cross-calls (IPIs) and preserves warm cache residency in CPU L1 and L2 caches. Setting nomerges=1 disables simple bio merging, saving critical CPU cycles because flash drives and distributed targets handle random requests without seeking penalty.NUMA-Aware Interrupt Affinity and Queue Alignment
In high-throughput dual-socket or multi-socket servers, routing storage traffic across interconnects (such as Intel UPI or AMD Infinity Fabric) severely impairs performance. When an NVMe-oF network interface card (NIC) resides on NUMA Node 0, but the block layer completion interrupts trigger on NUMA Node 1, each completed I/O packet incurs an expensive cross-socket memory hop.
Automated daemons such as irqbalance often distribute interrupts uniformly across all cores without regard to PCIe topology, introducing significant tail latency jitter. To enforce deterministic performance, platform architects pin hardware queues directly to NUMA-local cores via a dedicated systemd service:
[Unit]
Description=NVMe-oF and blk-mq Hardware Interrupt Affinity Pinning
After=network.target local-fs.target
ConditionPathExists=/sys/class/net

[Service]
Type=oneshot
RemainAfterExit=yes
ExecStart=/bin/bash -c '  NIC="enp65s0f0np0";   NUMA_NODE=$(cat /sys/class/net/$NIC/device/numa_node);   if [ "$NUMA_NODE" -lt 0 ]; then NUMA_NODE=0; fi;   CORES=$(lscpu | grep -E "NUMA node$NUMA_NODE CPU\(s\):" | awk "{print \$NF}");   echo "[+] Pinning $NIC interrupts to NUMA Node $NUMA_NODE (Cores: $CORES)";   systemctl stop irqbalance 2>/dev/null || true;   for irq in $(ls -d /sys/class/net/$NIC/device/msi_irqs/* 2>/dev/null | xargs -n1 basename); do     MASK=$(cat /sys/devices/system/node/node$NUMA_NODE/cpumap);     echo "$MASK" > /proc/irq/$irq/smp_affinity 2>/dev/null || true;   done;   for dev in $(ls -d /sys/block/nvme* 2>/dev/null); do     echo 2 > $dev/queue/rq_affinity;     echo none > $dev/queue/scheduler;     echo 2048 > $dev/queue/nr_requests;   done'

[Install]
WantedBy=multi-user.target
Save this service unit to /etc/systemd/system/nvme-affinity.service, enable it, and launch it:
sudo systemctl daemon-reload
sudo systemctl enable --now nvme-affinity.service
Benchmarking blk-mq with FIO and io_uring
To validate that your multi-queue configuration is operating at maximum efficiency without kernel lock stalls, execute rigorous synthetic testing using the fio (Flexible I/O Tester) suite. Utilize the modern io_uring asynchronous engine, which interfaces with blk-mq with minimal system call overhead.
Save the following benchmarking profile to /opt/benchmarks/nvme-of-fio.job:
[global]
ioengine=io_uring
direct=1
buffered=0
norandommap=1
randrepeat=0
time_based=1
runtime=60
ramp_time=10
group_reporting=1
iodepth=64
iodepth_batch_submit=16
iodepth_batch_complete=16
hipri=1

[nvme-4k-randread]
filename=/dev/nvme0n1
rw=randread
bs=4k
numjobs=16
cpus_allowed=0-15
cpus_allowed_policy=split

[nvme-4k-randwrite]
filename=/dev/nvme1n1
rw=randwrite
bs=4k
numjobs=16
cpus_allowed=16-31
cpus_allowed_policy=split
Run the validation workload and monitor I/O throughput in real time:
fio /opt/benchmarks/nvme-of-fio.job --output=/tmp/fio-results-tuned.logDuring execution, observe that CPU usage across all worker cores reflects purely user-space and kernel I/O submission paths, with near-zero time spent in softirq (%si) or wait states (%wa) when hybrid polling (hipri=1) is activated.
Advanced Diagnostics: Inspecting blk-mq Queues and Debugfs
When investigating performance degradation or suspected queue stalls in production environments, the Linux kernel exposes real-time internal blk-mq telemetry via debugfs. Ensure debugfs is mounted at /sys/kernel/debug to inspect queue depths, hardware context allocations, and command tag consumption:
# Mount debugfs if not already present
sudo mount -t debugfs none /sys/kernel/debug 2>/dev/null || true

# Inspect the active hardware dispatch queue mapping for NVMe namespace nvme0n1
cat /sys/kernel/debug/block/nvme0n1/hctx0/cpu_map

# Verify tag allocation depth and active tags in flight
cat /sys/kernel/debug/block/nvme0n1/hctx0/tags

# Check dispatched request counters and queue depth utilization
cat /sys/kernel/debug/block/nvme0n1/hctx0/dispatched
If the tags file reveals that all hardware tags are continuously saturated, the bottleneck has shifted from the host kernel blk-mq layer to either fabric network congestion (e.g., RoCE PFC pause frames or TCP window starvation) or backend NVMe controller submission limits. In such scenarios, increasing the target-side queue depth or deploying multi-path NVMe namespaces (nvme-multipath) across redundant fabric interfaces provides the necessary relief.
nr_requests to extreme values such as 16384 on multi-tenant nodes hosting hundreds of NVMe namespaces. Excessively deep request queues consume significant unevictable kernel slab memory and can exacerbate tail latency during sudden storage controller link resets.Frequently Asked Questions
Why should I set the I/O scheduler to ‘none’ for distributed NVMe-oF storage?
The none scheduler bypasses all kernel elevator logic, including request sorting and deadline tracking. Because distributed NVMe media offers sub-100-microsecond access times and internal parallelism across hundreds of flash channels, software reordering adds CPU serialization and locking overhead without yielding any performance benefit.
What is the primary difference between blk-mq tuning for NVMe/TCP vs NVMe over RDMA (RoCEv2)?
While both rely on the same blk-mq software and hardware queue abstractions, NVMe/TCP processes data packets through the kernel network stack, making TCP socket buffers (rmem/wmem), page zero-copy, and TCP congestion control critical tuning targets. NVMe over RDMA offloads packet processing directly to the NIC hardware, shifting the tuning focus to memory registration pools, PCIe completion coalescing, and RoCE Flow Control (PFC).
How does rq_affinity=2 improve NVMe-oF tail latency?
When rq_affinity is set to 2, the kernel guarantees that the completion handler for an I/O request executes strictly on the exact CPU core that initiated the request. This eliminates Inter-Processor Interrupts (IPIs) between distinct CPU cores, preserves warm cache line locality in CPU L1/L2 caches, and drastically mitigates p99.9 and p99.99 latency spikes.
Can I utilize blk-mq polling with io_uring on distributed storage targets?
Yes. By enabling queue/io_poll=1 in udev and passing the IORING_SETUP_IOPOLL flag in userspace applications, the kernel actively polls the NVMe completion queue rather than awaiting hardware interrupts. This shaves several microseconds off each I/O operation, achieving the lowest possible latency on high-performance flash clusters.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.