Setting Up LiteLLM Proxy on a Linux VPS: Unified Gateway for OpenAI, Anthropic, and Local Models
Deploy LiteLLM Proxy on a Linux VPS as a unified AI gateway. Configure failover, Redis caching, and OpenAI compatibility across cloud and local models.
/BlogZero-Cost CloudBrowse all engineering tutorials and benchmarks tagged with #Databases & Performance.
Deploy LiteLLM Proxy on a Linux VPS as a unified AI gateway. Configure failover, Redis caching, and OpenAI compatibility across cloud and local models.
Modern AI clusters demand unprecedented thermal dissipation. Here is what sysadmins must know about liquid vs air cooling benchmarks, architecture, and TCO.
Master HTTP content negotiation in Nginx to serve raw Markdown to AI crawlers and rich HTML to humans. Boost LLM indexing while cutting crawler token costs.
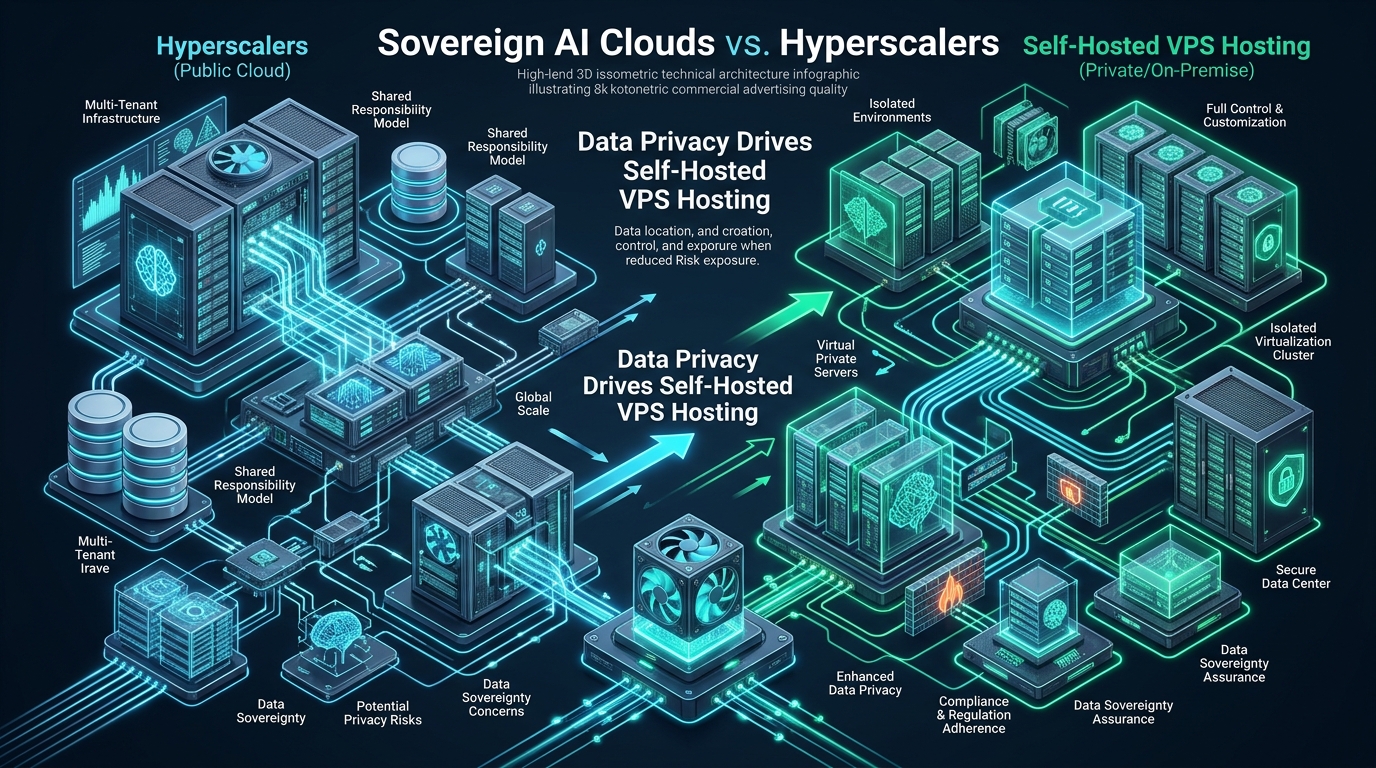
Discover why data privacy and regulatory compliance drive sovereign AI cloud hosting. Learn how self-hosted VPS architectures outperform hyperscalers.
AI-driven DDoS attacks weaponize machine learning to mutate traffic and bypass WAFs. Learn how kernel-level eBPF and zero-trust edge heuristics stop them.
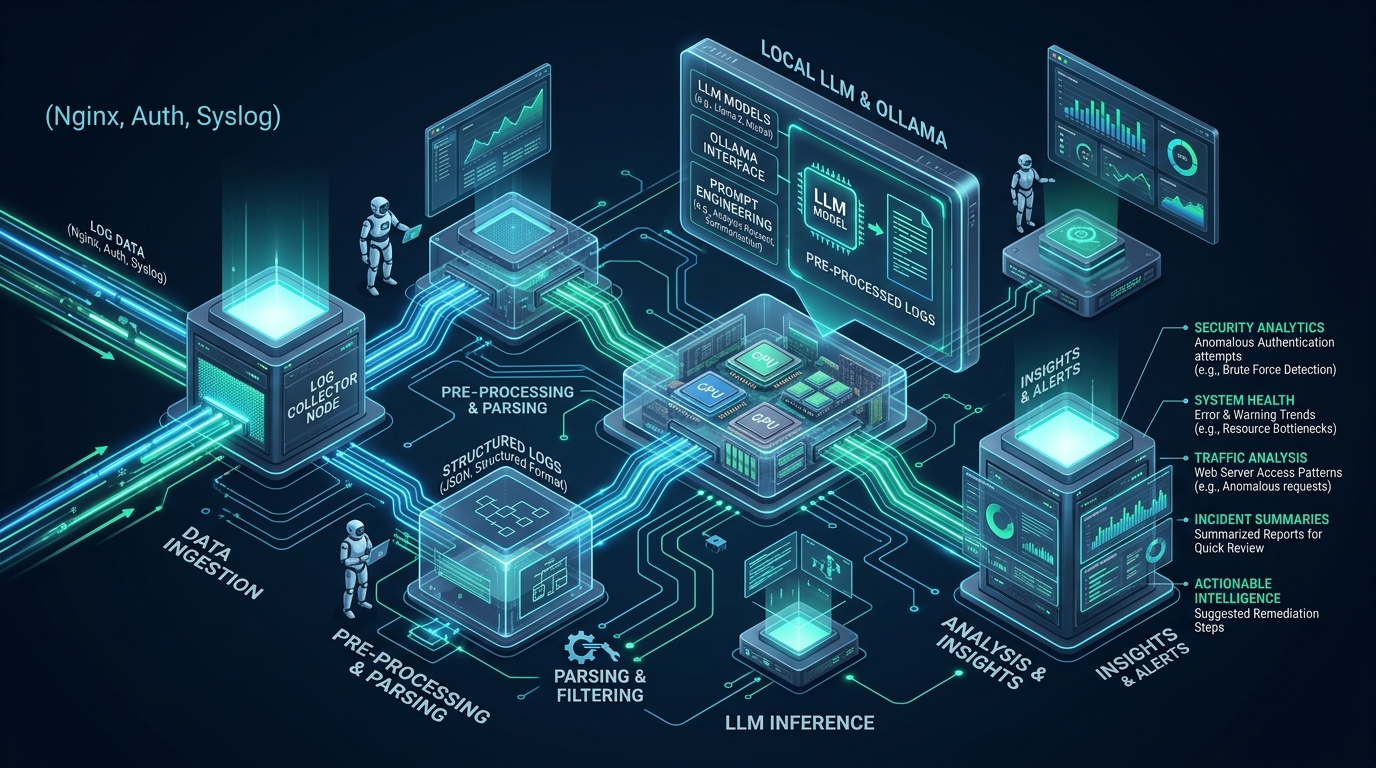
Learn how to analyze server logs with LLM models locally using Ollama. Stream Nginx, auth, and syslog streams into offline inference pipelines securely.
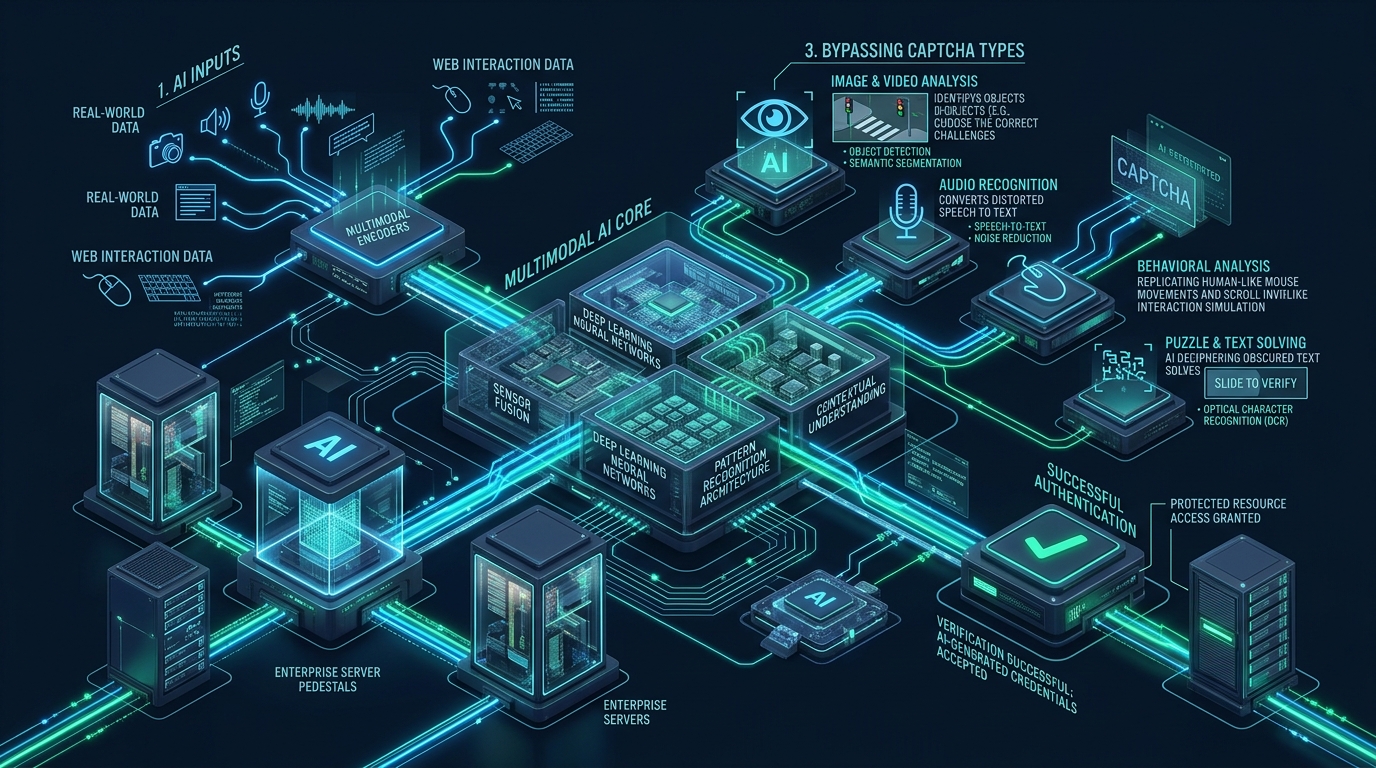
Multimodal AI models now bypass traditional visual and audio CAPTCHAs in under 800ms. Explore the architectural shift to zero-trust behavioral verification.
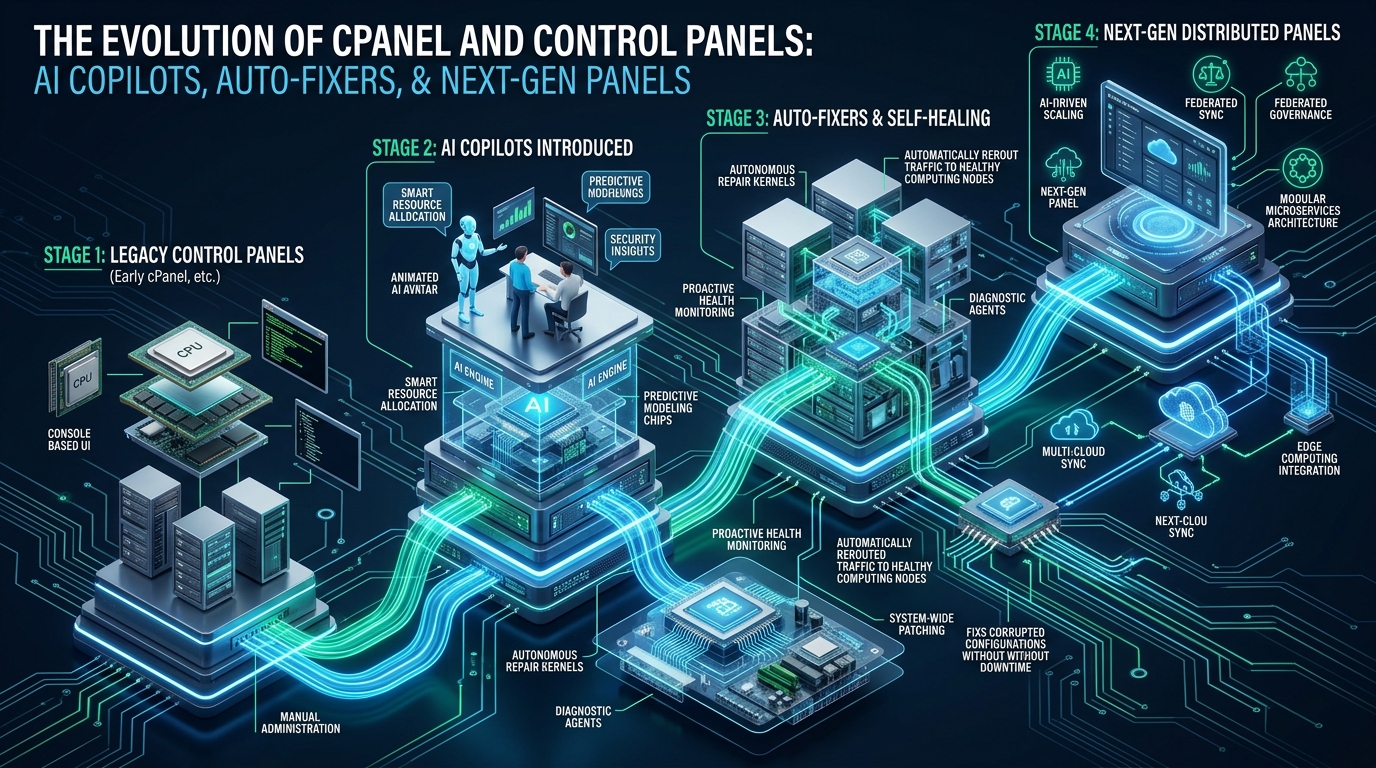
Explore how cpanel ai copilot integrations, autonomous auto-fixers, and next-gen panels eliminate sysadmin toil, optimize telemetry, and harden Linux fleets.
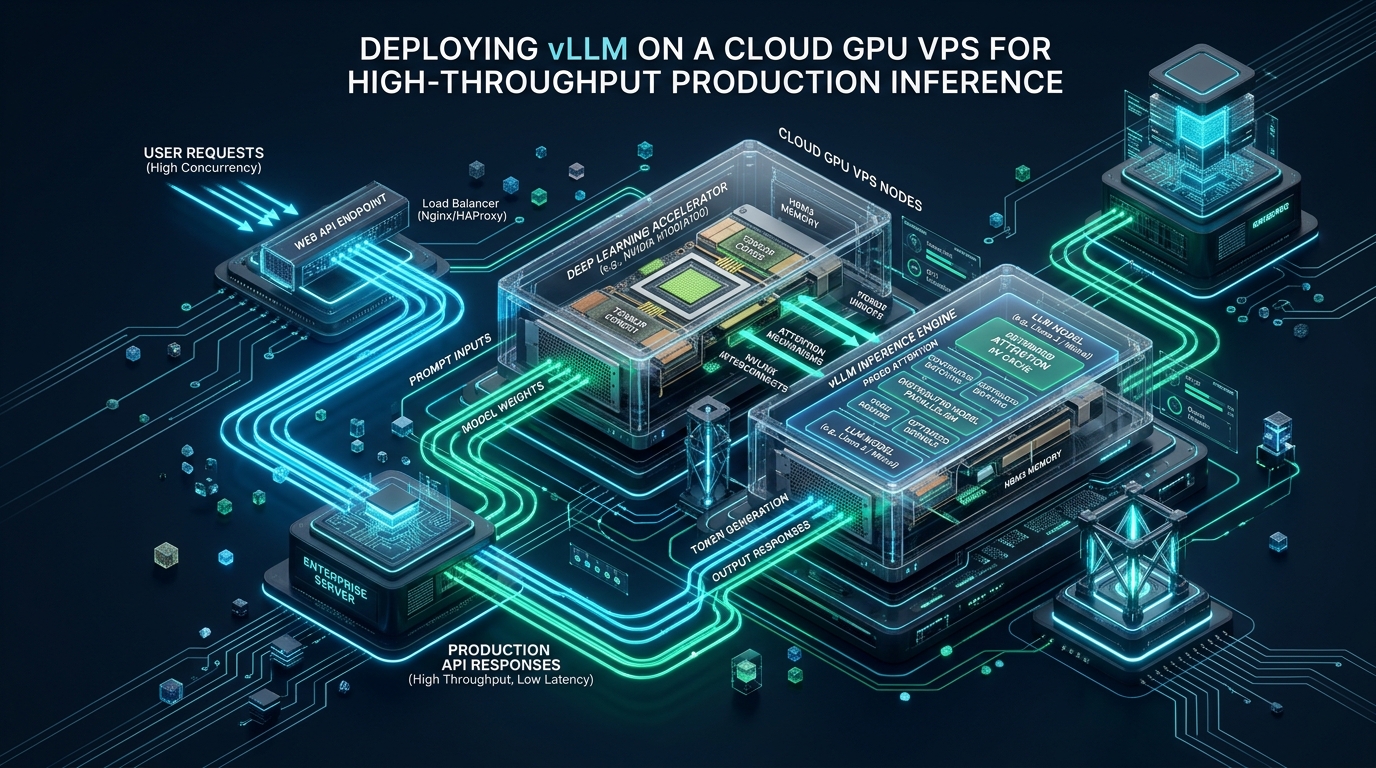
Deploy vLLM on cloud GPU VPS instances for high-throughput LLM serving. Master PagedAttention, continuous batching, and CUDA optimization for production scale.
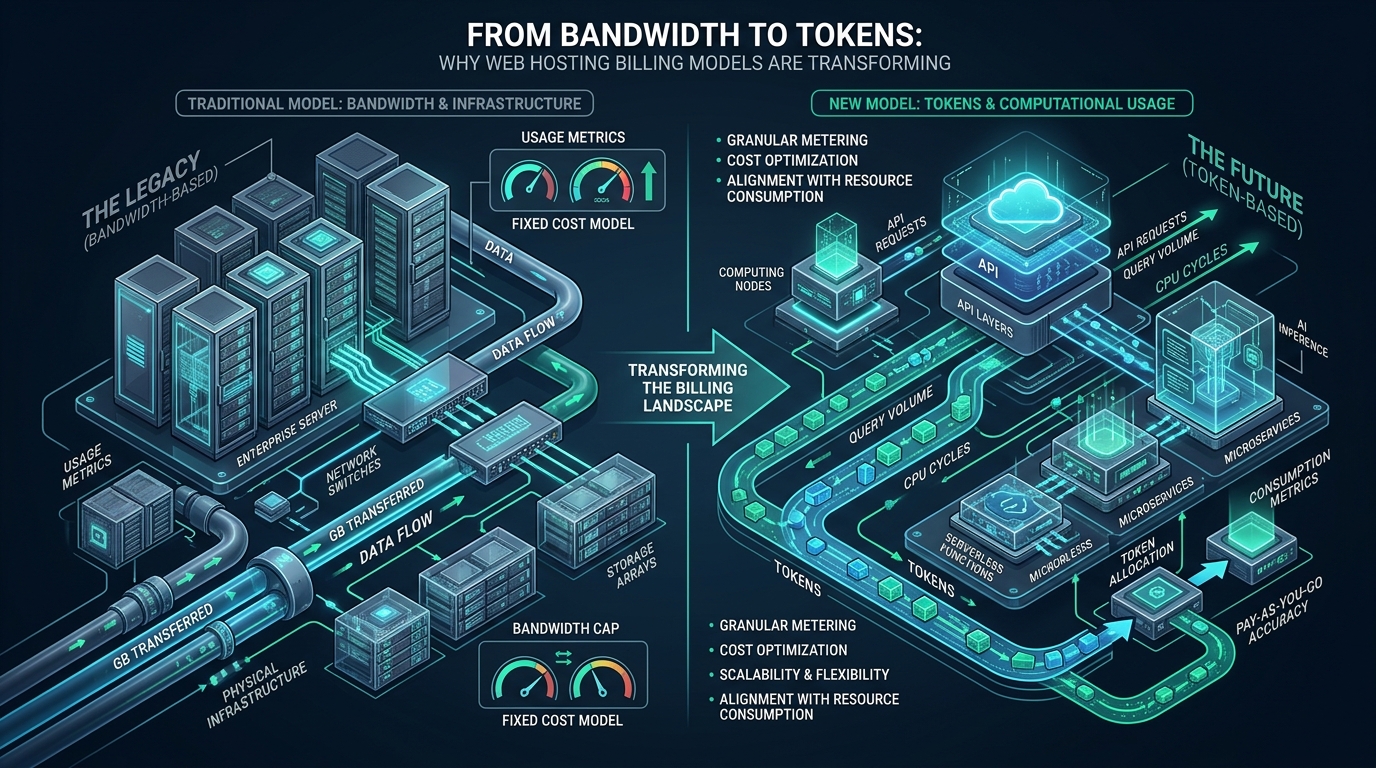
As AI workloads displace static sites, web hosting billing shifts from raw bandwidth to tokens and compute cycles. Discover how to architect your stack.