
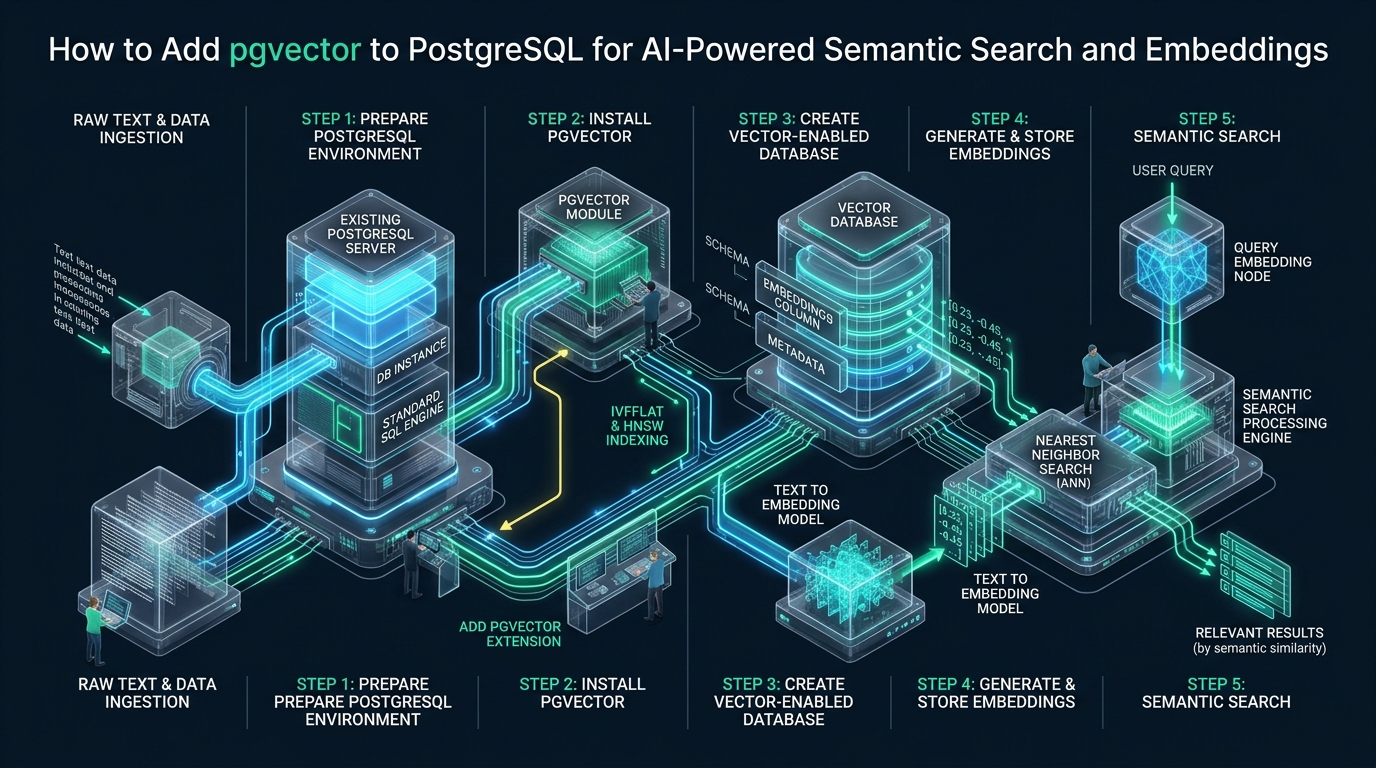
Modern AI applications and retrieval-augmented generation (RAG) pipelines frequently suffer from operational fragmentation when deploying standalone vector databases alongside traditional relational engines. Synchronization delays, transactional inconsistencies, and dual-pipeline network overhead often degrade semantic search performance and inflate infrastructure costs. By consolidating relational records, document metadata, and high-dimensional embeddings within a unified relational instance tested on CpanelFree, engineering teams can eliminate microservice sprawl while preserving strict ACID guarantees.
How to Install and Configure pgvector on PostgreSQL for High-Throughput AI Search
Direct Answer: To install pgvector on PostgreSQL, install the postgresql-16-pgvector package via official PGDG repositories, run CREATE EXTENSION vector; inside your database, and store embeddings using the vector(dimensions) data type. For production query latency under 10ms at scale, build an approximate nearest neighbor HNSW index using cosine or inner product distance, and allocate sufficient maintenance_work_mem to allow the hierarchical graph to construct entirely within system RAM.
The Architectural Shift: Unified Relational Vectors vs. Standalone Databases
In early generative AI architectures, developers routinely reached for dedicated vector databases such as Pinecone, Qdrant, Weaviate, or Milvus. While specialized, introducing an external vector store establishes a split-brain data model. Your transactional metadata (user identities, billing tiers, document permissions, audit trails) resides in PostgreSQL, while 1536-dimensional floating-point embeddings live across a separate network boundary.
This architectural boundary creates three acute operational liabilities:
- Dual-Write Inconsistencies: If a document row updates or deletes in PostgreSQL but the secondary API call to the vector index fails or lags, user queries retrieve orphaned or stale embeddings.
- Multi-Hop Network Latency: Executing a vector similarity query in one cloud service, fetching candidate document IDs, and then running a secondary
WHERE id IN (...)query in PostgreSQL introduces compound round-trip network hops. - Complex Authorization Filters: Modern enterprise security mandates granular access control. With dedicated vector stores, pre-filtering or post-filtering by tenant ID and access permissions either forces massive vector re-ranking or requires duplicating relational permissions tables into vector metadata indices.
Architecture Note: When executing dense vector search, memory locality is the single greatest predictor of p99 tail latency. Decoupled vector stores incur serialization and deserialization overhead across external network sockets, whereas pgvector leverages PostgreSQL’s shared buffer pool and Linux page cache to perform SIMD-accelerated distance calculations directly in memory.
Step 1: Installing pgvector on Production Linux Systems
Depending on whether you manage standard enterprise distributions or require custom compiler optimizations, you can install pgvector via official binary repositories or compile from source to leverage advanced CPU instruction sets.
Method A: Official Package Manager (Ubuntu / Debian / RHEL)
On Ubuntu and Debian systems with the official PostgreSQL Global Development Group (PGDG) apt repository configured, installation requires a single package manager command:
# Update package cache and install pgvector for PostgreSQL 16
sudo apt-get update
sudo apt-get install -y postgresql-16-pgvector

# For Red Hat Enterprise Linux, Rocky Linux, or AlmaLinux 9:
sudo dnf install -y https://download.postgresql.org/pub/repos/yum/reporpms/EL-9-x86_64/pgdg-redhat-repo-latest.noarch.rpm
sudo dnf install -y pgvector_16
Method B: Compiling from Source with AVX-512 Instruction Flags
For bare-metal or dedicated cloud hypervisors equipped with modern AMD EPYC (Zen 4) or Intel Xeon Scalable processors, compiling pgvector locally allows the compiler to auto-vectorize floating-point calculations using AVX-512 or AVX2. This yields a 2x to 3x throughput speedup during large index builds:
# Install build essentials and PostgreSQL development headers
sudo apt-get install -y build-essential git postgresql-server-dev-16

# Clone the latest pgvector stable release
cd /tmp
git clone --branch v0.8.0 https://github.com/pgvector/pgvector.git
cd pgvector

# Compile with native hardware architecture optimizations
make clean
make OPTFLAGS="" CFLAGS="-O3 -march=native"
sudo make install

# Verify library installation
ls -lh $(pg_config --pkglibdir)/vector.so
Step 2: Vector Operators and Mathematical Distance Functions
pgvector introduces three primary distance calculation operators tailored to different machine learning models and embedding generation frameworks:
- Euclidean Distance / L2 (
<->): Measures the straight-line distance between two vector coordinates. Ideal for computer vision embeddings and spatial clustering models. - Negative Inner Product / Dot Product (
<#>): Computes the dot product between vectors. Mathematically,<#>returns the negative dot product so that PostgreSQL’s ascending index order sorts closest matches first. - Cosine Distance (
<=>): Computes1 - cosine_similarity. This is the universal standard for natural language models (OpenAItext-embedding-3, Mistral, Cohere, and Hugging Face transformers) because it evaluates semantic direction rather than vector magnitude.
Production Tip: If your machine learning pipeline pre-normalizes vector embeddings to unit length (norm = 1.0) before database ingestion, use the Negative Inner Product operator (
<#>) instead of Cosine Distance (<=>). Because unit vectors have a length of 1, their dot product equals their cosine similarity, eliminating expensive floating-point square root calculations during query scans.
Step 3: Comparative Evaluation of Indexing Strategies
Without an index, PostgreSQL executes an exact sequential scan across every vector row (k-NN). While exact scans deliver 100% recall accuracy, execution time scales linearly: querying 1,000,000 rows with 1536 dimensions takes several seconds. pgvector supports two distinct Approximate Nearest Neighbor (ANN) index architectures: IVFFlat (Inverted File Flat) and HNSW (Hierarchical Navigable Small World).
| Feature / Metric | Exact Scan (No Index) | IVFFlat Index | HNSW Graph Index |
|---|---|---|---|
| Recall Accuracy | 100% (Ground Truth) | 85% – 95% (Approximate) | 98.5% – 99.8% (Near Optimal) |
| Query Latency (1M Vectors) | 1,800ms – 4,200ms | 25ms – 75ms | 2.4ms – 7.8ms |
| Index Build Time | Zero (No index) | Fast (k-means clustering) | Moderate to Intensive |
| RAM / Storage Footprint | 0 MB | Low (Inverted lists) | Higher (Multi-layer graph) |
| Build Prerequisite | None | Requires existing populated data | Can build on empty table |
The Verdict: For modern production AI applications, HNSW is overwhelmingly the superior choice. HNSW constructs a multi-layer geometric graph where higher layers skip across large vector distances and lower layers converge on exact nearest neighbors. Unlike IVFFlat, which requires a pre-existing corpus of records to compute k-means centroids, HNSW can be instantiated on an empty table and continuously populated with zero loss of clustering validity.
Step 4: Real Production Configuration Files
Building and querying vector graphs requires substantial memory bandwidth and dedicated execution memory. Default PostgreSQL and Linux kernel configurations will cause HNSW index builds to spill to disk or trigger system out-of-memory (OOM) kills. Apply these production configurations to sustain high indexing throughput.
1. Linux Kernel Tuning: /etc/sysctl.d/99-postgresql-vectors.conf
Deploy the following kernel settings to maintain cache locality, prevent unneeded swapping, and configure high-concurrency socket buffers:
# /etc/sysctl.d/99-postgresql-vectors.conf
# Kernel memory and disk caching optimizations for pgvector workloads

# Discourage swapping out warm vector graph pages from Linux page cache
vm.swappiness = 10

# Maximize memory mapping ceilings for large shared buffers
vm.max_map_count = 1048576

# Flush dirty pages progressively to prevent I/O stalls during index creation
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Network stack throughput for high-concurrency embedding ingestion
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 8192
net.ipv4.tcp_tw_reuse = 1
Apply these sysctl settings immediately with sudo sysctl --system.
2. PostgreSQL Engine Tuning: /etc/postgresql/16/main/conf.d/20-pgvector.conf
HNSW graph construction happens within memory allocated by maintenance_work_mem. If this parameter is too small, PostgreSQL writes intermediate graph nodes to temporary files on disk, turning a 5-minute index build into a multi-hour bottleneck.
# /etc/postgresql/16/main/conf.d/20-pgvector.conf
# Optimized engine parameters for 32GB RAM / 8 vCPU dedicated vector server

# Index Build Memory (Essential for building HNSW graph in RAM)
maintenance_work_mem = 4GB
max_parallel_maintenance_workers = 4

# Query Execution Memory per worker
work_mem = 64MB

# Buffer pool sizing (Ensure vector graph remains resident in RAM)
shared_buffers = 8GB
effective_cache_size = 24GB

# Background writer and checkpoint pacing
checkpoint_completion_target = 0.9
max_wal_size = 16GB
min_wal_size = 2GB

# HNSW Query Search Scope (Higher = better recall, lower = faster latency)
# Default is 40; production workloads balance recall at 100
hnsw.ef_search = 100
3. Systemd Process Limits: /etc/systemd/system/postgresql.service.d/override.conf
Prevent systemd cgroups from terminating PostgreSQL during memory-intensive vector builds:
# /etc/systemd/system/postgresql.service.d/override.conf
[Service]
LimitNOFILE=65536
LimitMEMLOCK=infinity
MemoryMax=30G
Reload and restart the daemon via sudo systemctl daemon-reload && sudo systemctl restart postgresql.
Step 5: Database Schema Design & Hybrid Search Implementation
Below is an enterprise-grade schema demonstrating vector embeddings combined with PostgreSQL’s native full-text search engine (tsvector) for hybrid retrieval:
-- Connect to your application database
\c app_knowledge_base;

-- Enable the pgvector extension
CREATE EXTENSION IF NOT EXISTS vector;

-- Create documents table with 1536-dimensional vector embedding column
CREATE TABLE documents (
    id BIGSERIAL PRIMARY KEY,
    title VARCHAR(255) NOT NULL,
    content TEXT NOT NULL,
    category VARCHAR(64) NOT NULL,
    metadata JSONB DEFAULT '{}'::jsonb,
    embedding vector(1536),
    tsv_content tsvector GENERATED ALWAYS AS (to_tsvector('english', title || ' ' || content)) STORED,
    created_at TIMESTAMPTZ DEFAULT CURRENT_TIMESTAMP
);

-- Full-text GIN index for keyword matching
CREATE INDEX idx_documents_tsv ON documents USING gin(tsv_content);

-- Build the HNSW Approximate Nearest Neighbor vector index
CREATE INDEX idx_documents_embedding_hnsw
ON documents
USING hnsw (embedding vector_cosine_ops)
WITH (m = 16, ef_construction = 128);
Tuning HNSW Index Parameters (m & ef_construction)
When creating an HNSW index, two critical parameters govern accuracy versus memory overhead:
m = 16: Specifies the maximum number of bidirectional connection links per node in the graph. Default is 16. Higher values (e.g., 24 to 32) improve recall for complex high-dimensional datasets at the cost of higher RAM usage.ef_construction = 128: Specifies the size of the dynamic candidate list evaluated when inserting a new vector into the graph. Higher values (64 to 200) increase index build time but generate a significantly more accurate graph topology.
Hybrid Search with Reciprocal Rank Fusion (RRF)
Pure vector semantic search struggles with exact technical strings, such as product SKUs, serial numbers, error codes, and unique acronyms. Combining dense vector cosine similarity with sparse BM25/full-text search using Reciprocal Rank Fusion (RRF) delivers the most resilient search results possible in a single SQL query:
WITH semantic_search AS (
    SELECT id, RANK() OVER (ORDER BY embedding <=> '[0.012,-0.045,...]'::vector) AS rank_dense
    FROM documents
    WHERE category = 'Enterprise Architecture'
    ORDER BY embedding <=> '[0.012,-0.045,...]'::vector
    LIMIT 20
),
keyword_search AS (
    SELECT id, RANK() OVER (ORDER BY ts_rank_cd(tsv_content, plainto_tsquery('english', 'PostgreSQL pgvector optimization')) DESC) AS rank_sparse
    FROM documents
    WHERE tsv_content @@ plainto_tsquery('english', 'PostgreSQL pgvector optimization')
      AND category = 'Enterprise Architecture'
    LIMIT 20
)
SELECT
    d.id,
    d.title,
    COALESCE(1.0 / (60 + s.rank_dense), 0.0) +
    COALESCE(1.0 / (60 + k.rank_sparse), 0.0) AS rrf_score
FROM documents d
LEFT JOIN semantic_search s ON d.id = s.id
LEFT JOIN keyword_search k ON d.id = k.id
WHERE s.id IS NOT NULL OR k.id IS NOT NULL
ORDER BY rrf_score DESC
LIMIT 10;
Memory Sizing and Production Infrastructure Considerations
To maintain low latency, the entire HNSW index should reside in memory. Use this reliable formula to estimate memory requirements before deploying:
Index RAM Requirement ≈ RowCount × ((Dimensions × 4 Bytes) + (m × 8 Bytes × 2))
For a production corpus of 1,000,000 document chunks using OpenAI 1536-dimensional embeddings with m = 16, the raw vector graph occupies approximately 6.4 GB of RAM. Adding operating system buffers, PostgreSQL connection workers, and relation tables means a minimum of 16 GB to 32 GB of dedicated system RAM is recommended.
When deploying enterprise AI workloads with millions of embeddings, shared host CPU throttling and slow disk paging will quickly degrade p99 query latency. For dedicated memory guarantees, sustained CPU performance, and predictable operating costs with zero renewal price hikes, deploy your PostgreSQL instances on MeraHost Enterprise Cloud, featuring pure Enterprise NVMe storage, dedicated hardware resources, and expert Linux infrastructure support.
Frequently Asked Questions
How many vector dimensions does pgvector support in production?
Starting with pgvector v0.7.0+, you can store unindexed vectors with up to 16,000 dimensions. For indexed tables using HNSW or IVFFlat, pgvector supports up to 2,000 dimensions for standard single-precision 32-bit floating point vectors. Additionally, pgvector supports halfvec (16-bit half-precision floating point) which allows indexing up to 4,000 dimensions while cutting index RAM requirements by 50%.
Should I choose HNSW or IVFFlat for semantic search?
For virtually all production semantic search and RAG workloads, HNSW is the recommended choice. HNSW delivers sub-10 millisecond query latency with recall accuracy exceeding 99%, and it can be constructed incrementally on live tables. IVFFlat should only be considered if system RAM is severely constrained and you can tolerate periodic index re-clustering as your table grows.
Can I filter vector search queries with standard SQL WHERE clauses?
Yes. One of pgvector’s greatest strengths over standalone vector databases is its native support for SQL expressions. PostgreSQL automatically applies relational filters (such as tenant IDs, user permissions, or publication dates) alongside vector index traversal via iterative index scans, guaranteeing strict data isolation without secondary network queries.
How do I upgrade pgvector without database downtime?
After updating the binary package or compiling the latest release from source, connect to your PostgreSQL database and execute ALTER EXTENSION vector UPDATE;. PostgreSQL dynamically reloads the new shared library in memory without requiring a server reboot or index rebuild.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).