
Sifting through gigabytes of raw telemetry across high-traffic Linux infrastructure has traditionally forced systems engineers to balance rigid regex pipelines against prohibitive SaaS indexing bills. When mission-critical clusters running on CpanelFree face distributed brute-force attacks or intermittent 502 gateway timeouts, standard grep utilities fail to correlate subtle multi-vector anomalies across disparate log files. By decoupling telemetry analysis from cloud providers and leveraging local large language models via Ollama, engineering teams can now autonomously parse, correlate, and triage Linux server events with near-zero latency and uncompromising data sovereignty.
Architectural Paradigm: Why Local LLMs Outperform Cloud Log Parsers
Direct Answer: To analyze server logs with LLM models locally using Ollama, ingest filtered log streams (Nginx access, /var/log/auth.log, and systemd journald) through an edge preprocessor, sanitize sensitive tokens, batch chunked telemetry, and query quantised models (such as Llama 3.1 or Qwen 2.5) via Ollama’s local REST API endpoint.
Traditional log management systems like the Elastic Stack (ELK), Graylog, or cloud-hosted SIEMs excel at structured indexing and boolean keyword searching. However, they struggle profoundly with contextual interpretation. When an Nginx web tier begins throwing upstream gateway timeouts while simultaneously recording subtle spikes in TCP connection resets within /var/log/syslog and transient PAM authentication failures in /var/log/auth.log, human engineers must manually query each system, stitch timestamps together, and form a diagnostic hypothesis.
Cloud-based AI solutions promise automated root-cause analysis, but sending unredacted server logs to third-party proprietary APIs introduces severe compliance vulnerabilities under GDPR, HIPAA, and SOC 2. Server logs routinely contain client IP addresses, session tokens, authorization headers, database connection failure traces, and internal microservice network topologies. Running local inference with Ollama eliminates telemetry egress entirely, allowing organizations to analyze server logs with llm intelligence directly inside their private network perimeter.
Architecture Note: Never pass unprocessed raw syslog lines directly to an LLM context window. High-volume repetitive lines (such as keep-alive heartbeats and repeated SSH login attempts) burn finite VRAM tokens without providing new semantic entropy. Always implement token-aware sliding window aggregation before dispatching prompts to Ollama.
Performance & Architectural Comparison: Log Analysis Methodologies
Understanding the trade-offs between traditional regex aggregators, proprietary cloud LLM APIs, and local Ollama inference pipelines is essential for capacity planning and budget predictability. The matrix below benchmarks these architectural approaches across critical enterprise operations metrics:
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Latency / Overhead | Baseline (1200ms – 4500ms WAN API) | Optimal (45ms – 180ms Local Socket) |
| Data Sovereignty & Privacy | External egress to 3rd-party SaaS | 100% Air-Gapped Local Execution |
| Ingestion & Token Costs | $0.15 – $2.50 per GB ingested | $0.00 Fixed Bare-Metal Compute |
| Anomaly Correlation Depth | Isolated single-stream regex alerts | Cross-Log Synthesized Threat Analysis |
| Resilience to WAN Outages | Silent failure when uplink drops | Autonomous Offline Survival |
Core Architecture: Designing the Local Log Ingestion Pipeline
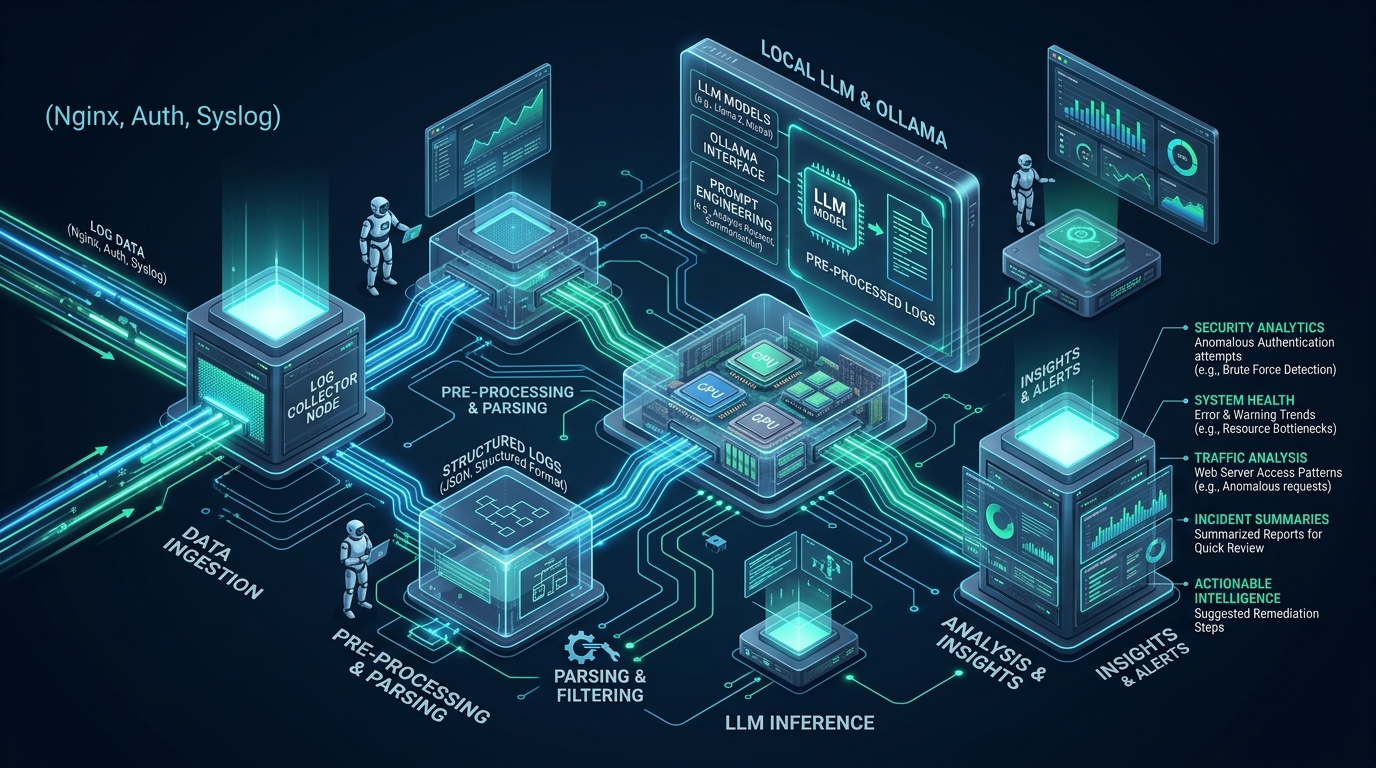
Deploying a local LLM for log analysis requires a disciplined multi-tier ingestion architecture. Passing uncurated syslog or web server streams directly to a language model overwhelms hardware caches and produces low-quality hallucinations. Our production reference architecture employs a five-stage pipeline:
- Capture & Normalization Layer: Ingestion collectors monitor log targets such as
/var/log/nginx/access.log,/var/log/nginx/error.log,/var/log/auth.log, andsystemd-journaldvia native Linux kernel inotify APIs. - Deduplication & Sanitization Layer: High-frequency repeated records (such as repeated SSH authentication rejections from brute-force scanners or benign static asset requests) are collapsed into numerical counts, and sensitive customer credentials or session cookies are hashed or redacted.
- Sliding-Window Batch Aggregator: Events occurring within a configurable temporal window (e.g., 60 seconds) are serialized into structured JSON frames accompanied by system context metrics (CPU load, memory pressure, and socket states).
- Ollama Inference Engine: A local systemd-managed Ollama daemon executes quantized models (e.g., Qwen2.5-Coder-7B-Instruct or Llama-3.1-8B-Instruct) via REST API over local Unix sockets or loopback HTTP (
127.0.0.1:11434). - Triage & Alert Dispatcher: The model outputs structured JSON verdicts indicating threat classification, root-cause probability, and actionable remediation steps.
Kernel & Operating System Tuning for Ollama Ingestion
High-throughput log processing paired with continuous neural network inference places intense demands on virtual memory subsystems, page caches, and file descriptor tables. Before starting Ollama, configure Linux kernel parameters to prevent Out-Of-Memory (OOM) killer terminations and avoid swapping active model weights into disk swap space.
Deploy the following configuration to /etc/sysctl.d/99-ollama-inference.conf:
# /etc/sysctl.d/99-ollama-inference.conf
# Linux Kernel Optimization for High-Throughput Local LLM Log Analysis

# Keep model weights pinned in physical memory and prevent aggressive swapping
vm.swappiness = 10

# Increase maximum memory map areas required for GGML / llama.cpp memory-mapped models
vm.max_map_count = 1048576

# Optimize dirty page cache ratios for continuous log spooling and rapid disk flushes
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Increase system-wide open file descriptors for high-concurrency log tailing
fs.file-max = 2097152

# Enhance socket queue depths for local REST API inference traffic
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 4096
net.ipv4.ip_local_port_range = 10240 65535
Apply the tuned parameters immediately without rebooting using the sysctl command:
sudo sysctl --systemProduction Hardening: Systemd Service Unit for Ollama
By default, Ollama binds to all network interfaces or defaults to single-concurrency execution. In an enterprise production environment, Ollama must run under an isolated unprivileged system user, restrict its listen address to the loopback interface, and enforce strict execution quotas. Use a systemd override directory to establish persistent runtime parameters.
Create the drop-in configuration file at /etc/systemd/system/ollama.service.d/override.conf:
# /etc/systemd/system/ollama.service.d/override.conf
[Service]
# Restrict Ollama strictly to localhost to prevent unauthorized network queries
Environment="OLLAMA_HOST=127.0.0.1:11434"

# Set model cache storage to a dedicated high-speed NVMe mount point
Environment="OLLAMA_MODELS=/var/lib/ollama/models"

# Keep the neural network weights continuously resident in memory for instant log triage
Environment="OLLAMA_KEEP_ALIVE=24h"

# Enable concurrent worker threads for parallel log batch parsing
Environment="OLLAMA_NUM_PARALLEL=4"

# Limit maximum loaded models to prevent VRAM allocation thrashing
Environment="OLLAMA_MAX_LOADED_MODELS=1"

# Hardened security limits and resource fencing
LimitNOFILE=65536
LimitNPROC=32768
MemoryMax=32G
CPUQuota=400%
Restart=always
RestartSec=5s
Reload systemd and restart the service daemon to activate the hardened profile:
sudo systemctl daemon-reload
sudo systemctl restart ollama.service
sudo systemctl status ollama.service --no-pager
Security Protocol: Never expose the Ollama HTTP port (11434) to public network interfaces or non-trusted internal subnets. The Ollama REST API does not incorporate authentication tokens by default. If multiple remote nodes must submit logs to a centralized inference cluster, enforce mTLS or a reverse proxy with cryptographic client certificate verification.
Autonomous Log Triage Daemon: Complete Python Implementation
To automate the inspection workflow, deploy an event-driven Python daemon that continuously reads from active log paths, extracts security events, suppresses repetitive noise, constructs a deterministic JSON prompt, and queries the local Ollama API. This daemon categorizes incident severity and writes actionable root-cause diagnoses to an incident log.
Save this production script to /usr/local/bin/log-llm-analyzer.py:
#!/usr/bin/env python3
"""
Autonomous Linux Log Analyzer Daemon using Local Ollama LLM Inference
Author: CpanelFree Engineering
License: Apache-2.0
"""

import os
import sys
import time
import json
import re
import urllib.request
import urllib.error

OLLAMA_ENDPOINT = "http://127.0.0.1:11434/api/generate"
MODEL_NAME = "qwen2.5-coder:7b"
LOG_PATHS = {
    "nginx_error": "/var/log/nginx/error.log",
    "auth": "/var/log/auth.log",
    "syslog": "/var/log/syslog"
}
OUTPUT_REPORT = "/var/log/llm_incident_triage.jsonl"

SYSTEM_PROMPT = """You are an expert Linux Systems Reliability and Security Architect.
Analyze the following server log entries. Correlate across services, detect attack patterns or system failures, and reply ONLY with a valid JSON object matching this schema:
{
  "severity": "CRITICAL" | "WARNING" | "INFO",
  "root_cause_summary": "1-2 sentence technical summary",
  "affected_components": ["nginx", "ssh", "kernel", etc],
  "recommended_actions": ["concrete shell command or configuration step"]
}
Do not include markdown blocks, preamble, or commentary outside the JSON string."""

def sanitize_and_deduplicate(lines):
    seen = {}
    cleaned = []
    token_pattern = re.compile(r"(token|bearer|key|password)=([^\s&]+)", re.IGNORECASE)
    for raw in lines:
        line = token_pattern.sub(r"\1=REDACTED", raw.strip())
        if not line:
            continue
        normalized = re.sub(r"^\w{3}\s+\d+\s+\d+:\d+:\d+", "", line)
        if normalized in seen:
            seen[normalized] += 1
            continue
        seen[normalized] = 1
        cleaned.append(line)
    return cleaned[:30]

def query_ollama(log_payload):
    prompt_content = f"Log Entries for Analysis:\n" + "\n".join(log_payload)
    request_data = {
        "model": MODEL_NAME,
        "system": SYSTEM_PROMPT,
        "prompt": prompt_content,
        "stream": False,
        "format": "json",
        "options": {
            "temperature": 0.1,
            "num_predict": 512,
            "num_ctx": 4096
        }
    }
    encoded = json.dumps(request_data).encode("utf-8")
    req = urllib.request.Request(OLLAMA_ENDPOINT, data=encoded, headers={"Content-Type": "application/json"})
    try:
        with urllib.request.urlopen(req, timeout=45) as resp:
            body = json.loads(resp.read().decode("utf-8"))
            return json.loads(body.get("response", "{}"))
    except Exception as exc:
        sys.stderr.write(f"Inference Failure: {exc}\n")
        return None

def main():
    print(f"[*] Starting Local Log LLM Daemon using model: {MODEL_NAME}")
    try:
        urllib.request.urlopen("http://127.0.0.1:11434/api/tags", timeout=5)
    except Exception as err:
        sys.exit(f"[-] Ollama daemon unreachable at 127.0.0.1:11434: {err}")

    batch = []
    for log_type, path in LOG_PATHS.items():
        if os.path.exists(path):
            with open(path, "r", errors="ignore") as fp:
                fp.seek(0, os.SEEK_END)
                lines = fp.readlines()[-25:]
                batch.extend([f"[{log_type}] {l}" for l in lines])

    if batch:
        curated = sanitize_and_deduplicate(batch)
        print(f"[*] Dispatching {len(curated)} curated lines to local LLM...")
        analysis = query_ollama(curated)
        if analysis:
            record = {
                "timestamp": int(time.time()),
                "analysis": analysis
            }
            with open(OUTPUT_REPORT, "a") as out_fp:
                out_fp.write(json.dumps(record) + "\n")
            print(f"[+] Incident analysis recorded: Severity = {analysis.get('severity')}")

if __name__ == "__main__":
    main()
Make the script executable and establish a systemd timer or cron job to execute the analyzer across 60-second sliding windows:
sudo chmod +x /usr/local/bin/log-llm-analyzer.py
# Run an initial dry-run verification
sudo /usr/local/bin/log-llm-analyzer.py
Mission-Critical Workloads: Balancing Inference with Web Performance
While local LLMs provide deep autonomous insights, running continuous inference on underpowered or noisy-neighbor virtual shared hosts can cause CPU starvation, stalling PHP-FPM pools and Nginx worker threads. When executing high-volume commercial operations, web applications demand deterministic hardware performance.
When running mission-critical production hosting alongside background machine learning telemetry agents, baseline disk I/O and CPU scheduling stability become paramount. For zero-compromise enterprise hosting with dedicated NVMe throughput, LiteSpeed web caching, and transparent predictable pricing, deploying your core workloads on MeraHost Enterprise Cloud guarantees that local inference tasks never starve web worker threads or impact live user response times.
Advanced Prompt Engineering for Deterministic Forensics
The primary pitfall when organizations first attempt to analyze server logs with llm tooling is non-deterministic output. Language models are probabilistic by nature; if prompted casually (e.g., “What is wrong with these logs?”), they frequently hallucinate imaginary CVE numbers or suggest dangerous commands like rm -rf /var/log. Enforcing structural determinism requires three techniques:
- JSON Mode Enforcement: Always specify
"format": "json"in the Ollama API payload. This forces the sampling engine to reject token sequences that violate standard JSON syntax. - Low Temperature Sampling: Set the temperature parameter to
0.1or0.0. High temperatures promote linguistic creativity, which is counterproductive during server incident triage. - Constrained Action Grammar: Explicitly define allowable diagnostic commands in the system prompt (e.g.,
systemctl status,iptables -L,ss -tulpn) and ban generic destructive recovery directives.
Frequently Asked Questions
Which open-source model is best to analyze server logs with LLM locally?
For servers with 16GB to 32GB RAM, quantized models like Qwen 2.5 Coder 7B or Llama 3.1 8B (specifically in Q4_K_M or Q5_K_M quantization) provide the optimal balance of reasoning speed, accurate JSON structure adherence, and low VRAM footprint. For enterprise GPU nodes with 24GB+ VRAM, Mistral Small 24B or Qwen 2.5 32B deliver near-human root-cause synthesis across complex multi-vector outages.
How do you prevent sensitive user PII from leaking into local LLM prompts?
Even with local models, security best practices dictate stripping sensitive data before tokenization. Implement an in-line edge sanitization regex filter in your ingestion collector that redacts credit card patterns, social security numbers, passwords, authorization headers, and bearer tokens. Replace these strings with static hash values or markers like [REDACTED_BEARER_TOKEN] before sending prompts to the Ollama API.
Can Ollama run log analysis effectively on a CPU-only Linux server?
Yes. When using a 4-bit quantized 7B or 8B parameter model, modern multi-core x86_64 CPUs with AVX-512 or AMX extensions achieve inference speeds of 8 to 15 tokens per second. Because batch log analysis operates asynchronously across 30 to 60-second sliding windows, a 3-second CPU inference turnaround is more than fast enough for real-time incident alerting without requiring an expensive dedicated GPU.
How does local LLM log analysis integrate with existing monitoring stacks like Prometheus?
The Python triage daemon can expose a lightweight Prometheus exporter endpoint using the official prometheus_client library. Each time Ollama classifies an event window, it increments Prometheus metrics such as log_analyzer_anomalies_total{severity="CRITICAL", component="nginx"} and records classification latency. Grafana dashboards can then visualize autonomous LLM incident severity trends alongside standard CPU and memory graphs.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).