
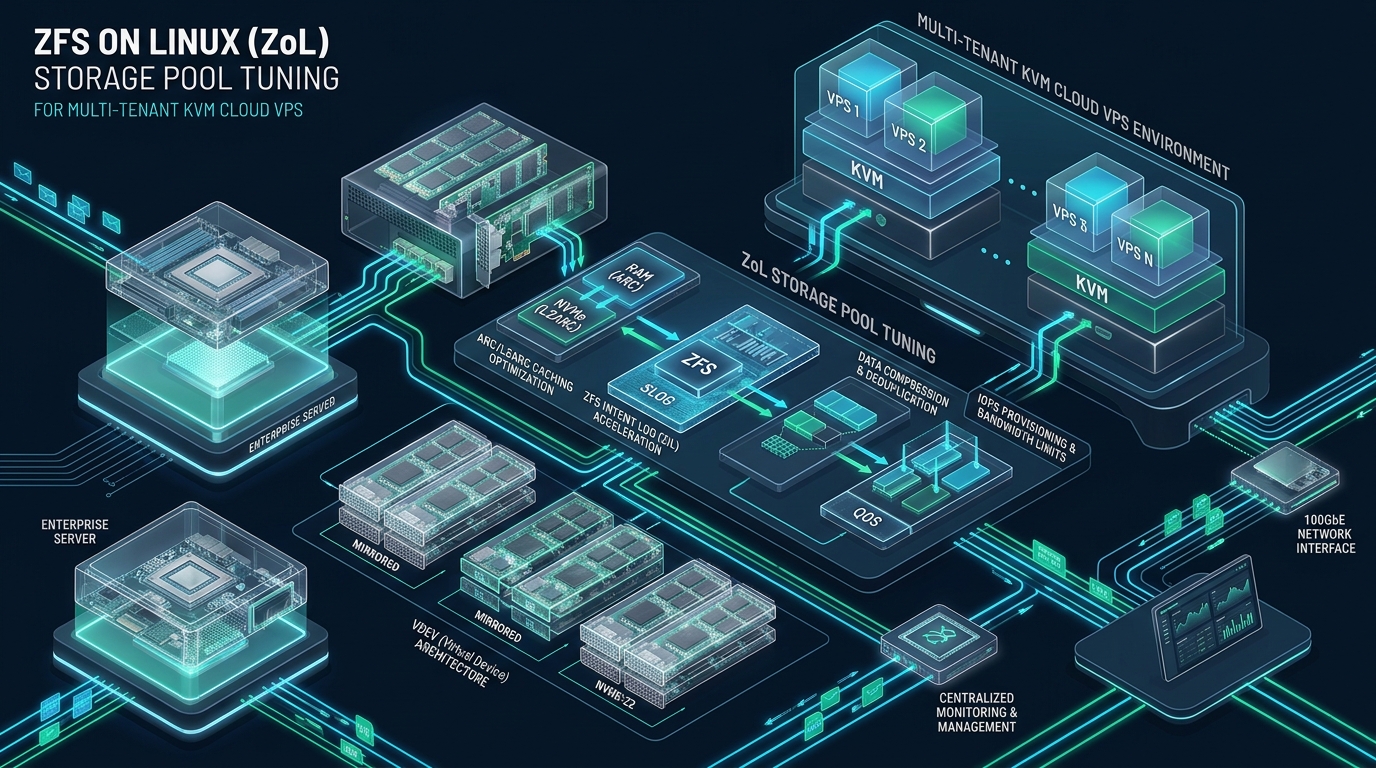
Operating high-density multi-tenant KVM virtualization clusters on bare metal requires balancing strict storage isolation, near-bare-metal I/O latency, and absolute data integrity against unpredictable noisy-neighbor workloads. Default installations of ZFS on Linux (ZoL) frequently suffer from catastrophic double-caching, severe write amplification, and unpredictable latency spikes during asynchronous transaction group (TXG) flushes, severely degrading guest responsiveness. By implementing architectural storage pool optimizations at CpanelFree, enterprise cloud engineers can unlock deterministic microsecond-level latency, robust dirty-data throttling, and seamless tenant scaling across NVMe storage tiers.
ZFS Storage Pool Tuning Architecture for Multi-Tenant KVM VPS
Optimal ZFS on Linux multi-tenant KVM VPS tuning requires matching ZVOL
volblocksize to the guest filesystem block size (typically 16KB or 64KB), deploying striped mirrors (RAID10) to maximize random write IOPS, capping the Adaptive Replacement Cache (ARC) to prevent Linux OOM-killer evictions, and utilizing dedicated Power-Loss Protected (PLP) NVMe SLOG devices for synchronous writes while enforcing tenant I/O QoS.
In a shared hypervisor environment hosting hundreds of virtual machines, storage performance is determined by random read/write latency and IOPS ceiling rather than raw sequential bandwidth. KVM tenants run disparate database engines, web servers, and container stacks that execute frequent, uncoordinated fsync() syscalls and random 4KB to 16KB writes. When multiple virtual machines simultaneously hammer the host file subsystem, an un-tuned copy-on-write (CoW) filesystem encounters extreme metadata fragmentation and severe lock contention.
To eliminate these hypervisor-level storage bottlenecks, systems administrators must architect their storage stack from the physical disk topology through OpenZFS kernel modules, the Linux virtual memory manager, and up into the QEMU/KVM disk abstraction layer.
1. VDEV Topology: Why Striped Mirrors are Non-Negotiable for Hypervisors
In multi-tenant KVM virtualization, random write IOPS is the single most critical performance metric. A classic administrative blunder is constructing a virtualization storage pool using RAIDZ1, RAIDZ2, or RAIDZ3 in an effort to maximize raw usable gigabytes per drive. In OpenZFS architecture, a RAIDZ group yields the random IOPS performance of only a single disk within that group, regardless of whether you assemble 4, 8, or 12 drives into the vdev.
Conversely, a storage pool constructed from striped mirrors (effectively RAID10) distributes random read and write operations evenly across every mirror pair. If you deploy an 8-drive enterprise NVMe pool organized as 4 two-way mirrors, your storage pool scales to 4 times the write IOPS and up to 8 times the read IOPS of a single drive. Furthermore, during drive replacement, rebuilding (resilvering) a striped mirror reads sequentially from only the surviving mirror partner, finishing within minutes instead of hours, avoiding the massive parity calculation penalties of RAIDZ that starve active guest VMs of disk bandwidth.
2. ZVOL Geometry and Block Size Alignment
When provisioning block storage devices for KVM virtual machines, cloud operators create ZVOLs (ZFS Volume Block Devices). The most crucial parameter defined at creation time is volblocksize. This attribute represents the allocation block size of the volume and cannot be modified once the ZVOL is populated with data.
The standard default volblocksize in older OpenZFS versions was 8KB, while datasets default to 128KB. If a KVM guest formats its virtual disk with ext4 or XFS using standard 4KB blocks or writes 16KB database pages (such as MySQL InnoDB), a volblocksize mismatch induces catastrophic write amplification. For instance, if the host ZVOL is set to 128KB and the guest writes a modified 4KB block, OpenZFS must read the entire 128KB block from disk, recalculate checksums, decompress, modify the 4KB segment, recompress, compute a new checksum, and write 128KB back to physical storage. This read-modify-write cycle destroys write throughput.
For general-purpose Linux multi-tenant guest workloads, set volblocksize=16k or volblocksize=64k based on guest profiling. Furthermore, modern enterprise NVMe SSDs utilize native 4KB or 8KB flash pages. Creating your pool with ashift=12 (2^12 = 4096 bytes) or ashift=13 (2^13 = 8192 bytes) prevents flash translation layer (FTL) write penalties.
3. Host Kernel & OpenZFS Module Parameters (/etc/modprobe.d/zfs.conf)
By default, OpenZFS on Linux dynamically consumes up to 50% of host RAM for the Adaptive Replacement Cache (ARC). On a dedicated 256GB KVM hypervisor hosting 30 virtual machines, if KVM instances consume 200GB of RAM and ZFS claims 128GB, the host kernel triggers aggressive memory reclaim and invokes the out-of-memory (OOM) killer, terminating QEMU processes.
To establish deterministic memory limits and smooth out transaction group flushes, deploy the following production configuration to /etc/modprobe.d/zfs.conf:
# /etc/modprobe.d/zfs.conf - Enterprise Production KVM ZoL Tuning
# Maintain strict memory boundary for ARC (e.g. 32GB max, 16GB min on a 256GB Host)
# Values calculated in bytes: 32GB = 34359738368, 16GB = 17179869184
options zfs zfs_arc_max=34359738368
options zfs zfs_arc_min=17179869184

# Keep kernel memory pressure balanced and reserve headroom for host OS
options zfs zfs_arc_sys_free=10737418240

# Transaction Group (TXG) sync tuning: reduce commit latency spikes
# Default is 5 seconds; reduce to 2 seconds for predictable flush latency
options zfs zfs_txg_timeout=2

# Dirty data bounds: cap unwritten buffers to prevent latency stuttering (4GB max, 1GB min)
options zfs zfs_dirty_data_max=4294967296
options zfs zfs_dirty_data_max_max=8589934592
options zfs zfs_dirty_data_sync_percent=20

# Persistent L2ARC: retain metadata and read cache across host reboots
options zfs l2arc_rebuild_enabled=1
options zfs l2arc_noprefetch=0
options zfs l2arc_write_max=67108864
options zfs l2arc_write_boost=134217728

# Async trimming for enterprise NVMe pools
options zfs zfs_trim_extent_bytes_max=134217728
options zfs zfs_trim_metaslab_skip=0

# Disable prefetch overhead for high-concurrency random virtualization I/O
options zfs zfs_prefetch_disable=1
4. Host Linux Virtual Memory Optimization (/etc/sysctl.d/99-kvm-zfs.conf)
In addition to OpenZFS module parameters, the host Linux kernel virtual memory (VM) subsystem must be tuned to prevent background page flushing from colliding with ZFS transaction groups. Apply these production sysctl settings to /etc/sysctl.d/99-kvm-zfs.conf:
# /etc/sysctl.d/99-kvm-zfs.conf - Linux Virtual Memory & KVM Tuning
# Minimize swapping aggressively since hypervisor RAM is pre-allocated
vm.swappiness=1

# Reserve safe memory headroom for kernel memory allocations
vm.min_free_kbytes=2097152

# Force timely background dirty page writeouts from host page cache
vm.dirty_background_ratio=5
vm.dirty_ratio=10

# Disable zone reclaim to prevent latency spikes under NUMA architectures
vm.zone_reclaim_mode=0

# Increase maximum tracking tables for high-density network virtualization
net.core.somaxconn=4096
net.ipv4.tcp_max_syn_backlog=8192
5. Automated Pool Creation and ZVOL Provisioning
Below is a production-grade Bash deployment script demonstrating the precise creation of an enterprise NVMe storage pool utilizing striped mirrors, LZ4 compression, proper alignment, and automated ZVOL provisioning for a KVM tenant:
#!/usr/bin/env bash
# Production ZoL Pool & Tenant ZVOL Provisioner for KVM Hypervisors
set -euo pipefail

POOL_NAME="kvm-nvme-pool"
DISKS_MIRROR1="/dev/disk/by-id/nvme-eui.002538b10140abcd /dev/disk/by-id/nvme-eui.002538b10140abce"
DISKS_MIRROR2="/dev/disk/by-id/nvme-eui.002538b10140abcf /dev/disk/by-id/nvme-eui.002538b10140abd0"
SLOG_MIRROR="/dev/disk/by-id/nvme-optane-part1 /dev/disk/by-id/nvme-optane-part2"

echo "[+] Creating high-performance striped mirror pool..."
zpool create -f -o ashift=12 \
  -O compression=lz4 \
  -O atime=off \
  -O normalization=formD \
  -O redundant_metadata=all \
  -O xattr=sa \
  ${POOL_NAME} \
  mirror ${DISKS_MIRROR1} \
  mirror ${DISKS_MIRROR2} \
  log mirror ${SLOG_MIRROR}

# Configure dataset for tenant container templates and raw disk volumes
zfs create -o canmount=off ${POOL_NAME}/vms

# Function to provision a tuned tenant ZVOL
provision_tenant_zvol() {
  local vm_id="$1"
  local size_gb="$2"
  local zvol_path="${POOL_NAME}/vms/vm-${vm_id}-disk0"

  echo "[+] Provisioning ZVOL for VM ${vm_id} with 16KB volblocksize..."
  # Use thin provisioning (-s) with explicit volblocksize
  zfs create -s -V "${size_gb}G" \
    -o volblocksize=16k \
    -o compression=lz4 \
    -o sync=standard \
    -o logbias=latency \
    "${zvol_path}"

  echo "[+] Setting block device permissions for libvirt/qemu..."
  udevadm settle
  chmod 660 "/dev/zvol/${zvol_path}"
  chown root:kvm "/dev/zvol/${zvol_path}"
}

# Example: Provision 100GB disk for VM ID 101
provision_tenant_zvol "101" "100"
6. Libvirt Domain XML Configuration for ZVOLs
To achieve peak performance and prevent the host and guest from double-caching data, configure the KVM domain XML disk definition to bypass the host page cache entirely. Specify cache='none', employ asynchronous I/O with io='native' or io='io_uring', and define fine-grained iotune limits to enforce tenant fairness:
<disk type='block' device='disk'>
  <driver name='qemu' type='raw' cache='none' io='native' discard='unmap'/>
  <source dev='/dev/zvol/kvm-nvme-pool/vms/vm-101-disk0'/>
  <target dev='vda' bus='virtio'/>
  <!-- Quality of Service (QoS): Enforce Tenant Limits -->
  <iotune>
    <total_iops_sec>5000</total_iops_sec>
    <total_iops_sec_max>10000</total_iops_sec_max>
    <total_iops_sec_max_length>30</total_iops_sec_max_length>
    <total_bytes_sec>262144000</total_bytes_sec> <!-- 250 MB/s -->
    <total_bytes_sec_max>524288000</total_bytes_sec_max>
  </iotune>
  <address type='pci' domain='0x0000' bus='0x04' slot='0x00' function='0x0'/>
</disk>discard='unmap' in the KVM disk driver. When a tenant deletes files inside the guest OS, fstrim forwards SCSI unmap / ATA trim commands down to OpenZFS, freeing up sparse ZVOL allocations on your physical NVMe arrays and preventing phantom pool exhaustion.
7. Separate Intent Log (SLOG): Eliminating Synchronous Write Latency
Synchronous writes (such as database transaction logs written with O_SYNC or fsync()) require OpenZFS to record data in the ZFS Intent Log (ZIL) before returning an acknowledgment to the application. In a default setup without a dedicated SLOG, the ZIL resides directly on the storage pool data disks. This causes two distinct writes for every sync transaction: first to the on-pool ZIL, and later during the TXG commit.
Under heavy multi-tenant database traffic, head-of-line blocking on the main vdevs drives P99 latency past 25ms. Adding a dedicated, high-end Separate Intent Log (SLOG) constructed from low-latency enterprise NVMe drives equipped with Power-Loss Protection (PLP) or Intel Optane SSDs offloads sync logging entirely. A mirrored Optane SLOG acknowledges synchronous writes in under 15 microseconds, freeing the main pool disks to process streaming asynchronous read and write requests unimpeded.
8. Validating Performance with Multi-Tenant FIO Benchmarking
To verify that your storage pool delivers deterministic multi-tenant throughput without queue starvation, run a synchronized 4-job fio benchmark simulating concurrent random read/write database workloads:
# fio multi-tenant simulation benchmark
fio --name=vm_randrw_test \
    --filename=/dev/zvol/kvm-nvme-pool/vms/vm-101-disk0 \
    --ioengine=libaio \
    --direct=1 \
    --bs=16k \
    --iodepth=32 \
    --numjobs=4 \
    --rw=randrw \
    --rwmixread=70 \
    --time_based \
    --runtime=60 \
    --group_reporting
While the test executes, monitor storage internals in real time using zpool iostat -v -l -q 1 to inspect disk queue depths and latency percentiles, and monitor memory pressure with arcstat 1. A properly tuned pool should maintain sub-millisecond average write latency and zero metadata starvation.
Frequently Asked Questions
Why is RAIDZ strongly discouraged for multi-tenant KVM VPS workloads?
A RAIDZ vdev (RAIDZ1, RAIDZ2, or RAIDZ3) offers the random I/O performance of only a single physical drive in the array. Multi-tenant virtualization is heavily dominated by concurrent, non-sequential random read and write operations. Striped mirrors (RAID10) distribute these operations across all mirror vdevs simultaneously, yielding linear IOPS scaling and significantly faster, safer rebuild times.
Should KVM virtual disks be provisioned as sparse ZVOLs or RAW files on a dataset?
Direct block-based ZVOLs provide superior performance, deterministic block management, and lower translation overhead compared to running QCOW2 or RAW files atop a mounted ZFS dataset. ZVOLs allow fine-grained volblocksize configuration, native snapshot orchestration, and direct pass-through via QEMU without an intermediate Linux VFS file lookup layer.
What is the recommended KVM caching mode when backed by ZFS storage?
Always configure KVM disks with cache=none and io=native (or io_uring). Setting cache=none directs QEMU to bypass the host Linux page cache, eliminating wasteful double-caching where data is stored redundantly in guest RAM, host page cache, and ZFS ARC. This allows the host ARC to manage RAM caching efficiently.
Does enabling LZ4 compression on ZFS reduce performance for KVM guest storage?
Enabling compression=lz4 almost universally enhances storage throughput. Modern multi-core CPUs execute LZ4 decompression at multiple gigabytes per second with negligible CPU usage. Because data is compressed before being committed to physical media, fewer bytes are written to NVMe flash, effectively multiplying usable bus bandwidth and extending SSD endurance.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.