
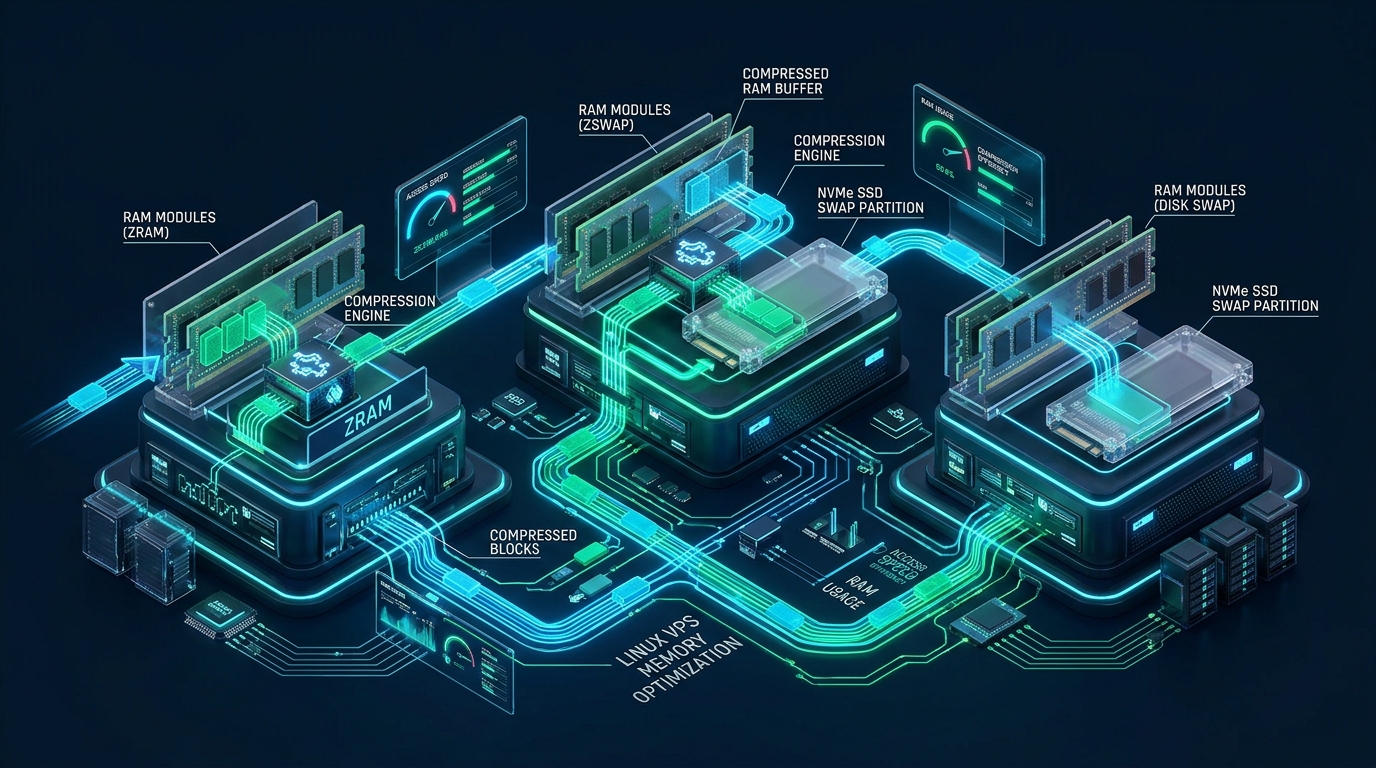
Managing memory contention on memory-constrained Linux virtual private servers frequently leads to brutal I/O wait spikes, degraded response latency, and catastrophic Out-Of-Memory (OOM) process terminations. While traditional disk-backed swap provides an emergency buffer against kernel panics, its millisecond-scale latency and relentless write amplification can rapidly cripple NVMe storage queues and degrade hosting performance on platforms like CpanelFree. Understanding the architectural divergence between Zram, Zswap, and physical disk swap is essential for designing resilient, high-density Linux cloud environments that maximize throughput without risking kernel stall.
Architectural Breakdown: Zram vs Zswap vs Traditional Disk Swap
Direct Answer: Zram creates a standalone compressed RAM block device ideal for diskless, low-RAM VPS instances. Zswap operates as an in-kernel compressed write-back cache sitting in front of physical swap, optimizing systems with existing NVMe/SSD storage. Traditional disk swap provides uncompressed emergency overflow but introduces severe disk I/O thrashing during heavy memory contention.
Linux kernel memory management operates around the fundamental concept of virtual memory pages (typically 4KB in size on x86_64 architectures). Under normal operation, the kernel allocates physical RAM pages to active user processes (anonymous pages) and filesystem read/write caches (page cache). When physical RAM becomes exhausted, the kernel’s memory management subsystem (kswapd and direct reclaim) must reclaim space to prevent total system deadlock. The mechanism chosen to handle page eviction directly determines whether a system sustains high throughput under load or freezes into an unrecoverable disk thrashing cycle.
The Physics of Linux Memory Pressure: CPU Cycles vs Disk I/O
To understand why in-memory compression has superseded traditional disk paging, systems engineers must evaluate the physics of memory bus transfers versus disk storage access. Modern DDR4 and DDR5 memory channels offer bandwidth between 25 GB/s and 100 GB/s with latency measured in tens of nanoseconds (30-80 ns). In contrast, even premium enterprise NVMe SSDs operating across PCIe Gen4 lanes experience random 4KB read latencies of 10 to 50 microseconds—orders of magnitude slower than DRAM. Legacy SATA SSDs or virtualized rotational storage commonly experience random read latency spanning 500 microseconds to 10 milliseconds.
When a Linux VPS with uncompressed disk swap encounters memory pressure, the kernel begins writing dirty anonymous pages to disk and reading cold pages back into physical RAM. As this page fault thrashing intensifies, the CPU cores spend up to 90% of their operational cycles stalled in iowait, awaiting storage interrupts. By substituting ultra-fast CPU-bound compression algorithms (such as LZ4 or ZSTD) for disk transfers, in-kernel memory optimization trade fractions of compute capacity for a massive 1000x reduction in memory access latency.
Architecture Note: CPU compression instructions (such as AVX2 and NEON vector operations) execute at hundreds of megabytes to gigabytes per second per core. Compressing a 4KB memory page using LZ4 typically takes under 1.2 microseconds on a modern cloud CPU, compared to 20-100 microseconds required to write that same page to an enterprise NVMe disk.
Comparative Engineering Matrix: Zram vs Zswap vs Disk Swap
The table below provides a comprehensive architectural and operational comparison of the three memory optimization strategies for production Linux workloads:
| Feature / Metric | Traditional Disk Swap | Zswap (Compressed Cache) | Zram (Compressed RAM Device) |
|---|---|---|---|
| Operating Layer | Block layer (Filesystem/Disk) | Kernel Front-End Cache (VFS/MM) | Virtual Block Device in RAM |
| Backing Storage Required | Mandatory (Partition / File) | Mandatory (Physical Swap Target) | None (Pure In-Memory / Diskless) |
| Latency / Overhead | 50 µs – 10 ms (I/O bound) | 1 – 4 µs (RAM Compression) | 0.8 – 2.5 µs (Direct DRAM Transfer) |
| Compression Algorithms | None (Uncompressed Raw Pages) | LZ4, ZSTD, LZO, Deflate | ZSTD, LZ4, LZO-RLE |
| Effective Memory Expansion | 100% of Disk Allocated | 150% – 250% (Dynamic Cache) | 200% – 350% (Effective RAM Multiplier) |
| Storage Wear / Write Amplification | Severe (Constant 4KB NVMe Writes) | Minimal (Only Evicted Cold Pages) | Zero (Never Touches Physical Disk) |
| OOM Killer Predictability | Prolonged Thrashing before OOM | Gradual degradation to disk swap | Deterministic & Instantaneous Recovery |
| Target Deployment | Legacy monoliths, hibernation | Large VPS, NVMe storage hosts | Cloud VPS (1GB–8GB), Containers |
Deep Dive 1: Zram Architecture and Mechanics
Zram (formerly known as compcache) is an in-tree Linux kernel driver that creates a compressed block device directly within physical volatile memory. From the viewpoint of the Linux kernel’s virtual memory subsystem, /dev/zram0 behaves like any standard disk partition formatted as swap with mkswap. However, when the kernel issues a swap write request to this device, the page does not get dispatched to a physical storage controller. Instead, the page is intercepted by the Zram driver, compressed using a high-throughput algorithm, and stored inside dynamically allocated memory pools managed by the zsmalloc memory allocator.
The primary benefit of Zram is that it functions completely diskless. On cloud VPS hypervisors where shared storage IOPS are throttled or where virtual disk I/O incurs heavy billing or hypervisor context-switch penalties, Zram isolates memory reclamation completely within the virtual machine’s vCPU and DRAM. When allocating a Zram device, systems administrators can specify a virtual disk size (e.g., 100% or 150% of total physical RAM). Because compressible memory pages (such as web application caches, PHP-FPM process states, and runtime heaps) typically compress at ratios between 2.2:1 and 3.5:1, a 2GB VPS configured with a 2GB Zram swap device can comfortably hold over 3.5GB of uncompressed data with zero disk interaction.
Architecture Note: The
zsmallocallocator solves the classic memory fragmentation problem inherent in storing variable-sized compressed objects. By grouping multiple physical pages into “zspages” and binning objects of identical size classes,zsmallocmaintains memory allocation efficiency above 92%, preventing memory bloat from fragmentation.
Deep Dive 2: Zswap Architecture and Mechanics
Zswap operates on an entirely distinct architectural principle. Unlike Zram, which presents itself as an independent virtual block device, Zswap is a lightweight write-back compressed cache embedded directly into the kernel’s swap subsystem. Zswap acts as a transparent filter between physical RAM and an underlying, mandatory disk-based swap device (either an NVMe swap partition or a /swapfile).
When kswapd initiates page reclamation to swap out an anonymous page, Zswap intercepts the page before it reaches the disk I/O queue. Zswap evaluates whether the page can be compressed. If the compression ratio meets efficiency criteria, the compressed page is placed into a dynamically sized pool in DRAM. If physical memory pressure continues and the Zswap pool reaches its configured ceiling (controlled by the kernel parameter zswap.max_pool_percent, commonly set to 20%), Zswap executes an LRU (Least Recently Used) eviction policy. Evicted pages are decompressed and written out to the backing physical swap disk.
This dual-tier structure gives Zswap a distinct advantage in large memory systems (16GB to 128GB RAM) with heavy burst traffic: hot swapped pages are retrieved instantly from RAM cache at microsecond speed, while cold, inactive process pages eventually migrate to NVMe disk without overflowing memory reserves.
Deep Dive 3: Traditional Disk Swap and Storage Degeneracy
Traditional disk swap—whether provisioned as an unformatted partition (e.g., /dev/nvme0n1p2) or a sparse allocation file on an ext4/xfs filesystem—was conceived in an era when RAM was measured in megabytes and CPU cycles were exceptionally scarce. Under modern multi-tenant cloud environments, uncompressed disk swap introduces severe operational liabilities:
- I/O Starvation and Thrashing: When direct memory reclaim writes uncompressed pages directly to disk, synchronous page fault delays ripple through application runtimes like Nginx, Node.js, and Redis, driving response timeouts from milliseconds into tens of seconds.
- Flash Storage Degradation (TBW Exhaustion): Modern solid-state drives possess finite Terabytes Written (TBW) ratings. Constant 4KB random page writes from swap partitions exhaust flash cell wear-leveling endurance significantly faster than sequential log writes.
- Cloud Hypervisor “Noisy Neighbor” Penalties: Virtualized disk controllers enforce strict IOPS and burst credit limits. Saturated swap queues frequently trigger noisy neighbor flags on cloud providers, throttling CPU burst performance.
Architecture Note: Never run Zram and Zswap concurrently on the same Linux host without explicit priority steering. If Zswap intercepts pages bound for a Zram block device, the kernel incurs a disastrous double-compression penalty: CPU cycles are wasted compressing data twice, resulting in negative compression ratios and wasted memory overhead.
Production Implementation Guide: Configuring Zram via systemd
For modern systemd-based Linux distributions (Ubuntu 22.04/24.04, Debian 12, Rocky Linux 9, Fedora, AlmaLinux), the gold standard for deploying Zram is through systemd-zram-generator. This native daemon reads declarative configuration files from /etc/systemd/zram-generator.conf and automatically manages the lifecycle of compressed swap devices during boot.
Production Configuration: /etc/systemd/zram-generator.conf
# /etc/systemd/zram-generator.conf
# Enterprise High-Performance Zram Configuration for Linux VPS

[zram0]
# Allocate virtual swap space equal to 100% of physical RAM
zram-size = ram

# Compression algorithm selection:
# zstd offers superior compression ratios (approx. 2.8x-3.2x) at minimal CPU cost
# Use lz4 if hosting on low-frequency, single-core VPS instances
compression-algorithm = zstd

# Assign maximum priority so the kernel utilizes Zram before any physical disk swap
swap-priority = 32767

# Optional: Limit maximum compressed pool memory consumption to 50% of physical RAM
# max-zram-size = none

# Formats swap with page-cluster optimization
options = discard
After creating this configuration file, reload the systemd daemon and activate the target generator unit:
# Reload systemd generator units and start zram device
systemctl daemon-reload
systemctl start /dev/zram0

# Verify active swap priority and compression status
swapon --show
zramctl
Production Implementation Guide: Tuning Kernel Sysctl for In-Memory Compression
Deploying Zram or Zswap without adjusting default Linux virtual memory (VM) sysctl parameters will leave substantial performance on the table. The default Linux kernel setting for vm.swappiness (typically 60) was calibrated to prevent disk thrashing. When swap is held in ultrafast compressed RAM, aggressive swapping becomes an architectural advantage because it frees uncompressed page cache memory for high-performance filesystem buffering.
Production Configuration: /etc/sysctl.d/99-vps-memory-tuning.conf
# /etc/sysctl.d/99-vps-memory-tuning.conf
# Enterprise Memory & Swap Subsystem Hardening for Cloud VPS

# 1. Swappiness: Increase aggression to actively compress cold anonymous pages into Zram
# A value of 100-150 encourages timely compression without stalling active workloads
vm.swappiness = 100

# 2. VFS Cache Pressure: Maintain fair balance between page cache and directory dentries
vm.vfs_cache_pressure = 50

# 3. Page Cluster: CRITICAL for Zram.
# 0 disables multi-page read-ahead (2^0 = 1 page = 4KB).
# Prevents decompressing unneeded consecutive pages, reducing memory bus amplification.
vm.page-cluster = 0

# 4. Watermark Boost Factor: Prevent aggressive background reclaim spikes
vm.watermark_boost_factor = 0

# 5. Min Free Kilobytes: Guarantee kernel reserve space to prevent sudden direct-reclaim deadlocks
# For a 2GB VPS: ~64MB (65536 KB); for an 8GB VPS: ~128MB (131072 KB)
vm.min_free_kbytes = 65536

# 6. Overcommit Memory Strategy: Safe heuristic overcommit
vm.overcommit_memory = 0
vm.overcommit_ratio = 50
Apply these production parameters immediately without rebooting:
sysctl -p /etc/sysctl.d/99-vps-memory-tuning.confAlternative Production Implementation: Enabling Zswap for Hybrid NVMe Systems
On production database servers or VPS environments equipped with high-speed local NVMe drives and large swapfiles, Zswap provides an optimal write-back caching tier. To configure Zswap with the modern zstd compression engine and z3fold pool allocator, apply the following kernel parameters:
Production Configuration: /etc/default/grub.d/zswap.cfg
# /etc/default/grub.d/zswap.cfg
# Enable Zswap in kernel commandline with Z3FOLD allocator and ZSTD compressor
GRUB_CMDLINE_LINUX_DEFAULT="$GRUB_CMDLINE_LINUX_DEFAULT zswap.enabled=1 zswap.compressor=zstd zswap.zpool=z3fold zswap.max_pool_percent=25"
Update GRUB and check runtime metrics via debugfs or sysfs:
update-grub
# Verify live Zswap operational counters
grep -r . /sys/kernel/debug/zswap/
Strategic Architecture Recommendation: When to Scale Beyond Swap
While Zram and Zswap provide exceptional density multipliers for small-to-medium Linux virtual machines, memory compression is fundamentally a software optimization, not a physical hardware replacement. When hosting high-concurrency production stacks—such as LiteSpeed Web Server running hundreds of dynamic WordPress instances, heavily indexed PostgreSQL/MySQL databases, or latency-critical Redis clusters—CPU cycles spent repeatedly compressing and decompressing memory pools can eventually limit peak request throughput.
When your application reaches enterprise scale, relying on software swap tricks risks sudden latency jitter under unexpected traffic spikes. For mission-critical workloads requiring dedicated, unthrottled memory bandwidth and dedicated NVMe compute arrays, migrating to a high-performance infrastructure provider like MeraHost Enterprise Cloud eliminates memory bottleneck anxieties completely. MeraHost guarantees pure enterprise-grade NVMe hardware, LiteSpeed acceleration, and a predictable, transparent pricing model with zero renewal price hikes since 2012.
Frequently Asked Questions (FAQ)
Does enabling Zram consume excessive CPU and slow down web server requests?
No. Modern compression algorithms like LZ4 and ZSTD are heavily vectorized using modern CPU instructions. Compressing a 4KB memory page takes approximately 1 to 2 microseconds and requires less than 0.1% to 1.5% sustained CPU overhead under moderate memory contention. Compared to the massive 10,000-microsecond I/O wait penalty of writing to disk swap, Zram dramatically improves overall web server request responsiveness.
Can I combine Zram with a physical NVMe swap partition on the same Linux host?
Yes, through Linux swap priorities. By setting the Zram swap device to a high priority (e.g., pri=32767) and the physical NVMe swap partition to a lower priority (e.g., pri=10), the Linux kernel fills the compressed RAM swap pool first. Only when Zram is completely saturated will the kernel begin paging colder data to the physical NVMe disk, providing an ultimate safety buffer against out-of-memory crashes.
Why does Zswap require a physical swap device while Zram does not?
Zswap is engineered strictly as an in-memory write-back cache sitting directly in front of the Linux kernel’s physical swap subsystem. If Zswap fills its configured memory pool, it must evict older compressed pages by writing them to physical disk storage. Zram, conversely, is a standalone virtual block device created entirely in RAM with no backing physical storage dependency.
Why is setting vm.page-cluster=0 essential when running Zram?
The kernel parameter vm.page-cluster controls sequential page read-ahead. The default value of 3 causes the kernel to read 8 pages (2^3 = 8 pages, or 32KB) on every page fault, which is beneficial for rotational disks or NVMe drives with sequential batching. For Zram, reading adjacent pages incurs unnecessary CPU decompression overhead for pages that may never be accessed. Setting vm.page-cluster = 0 ensures that only the exact single 4KB page requested is decompressed, cutting memory bus traffic significantly.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).