
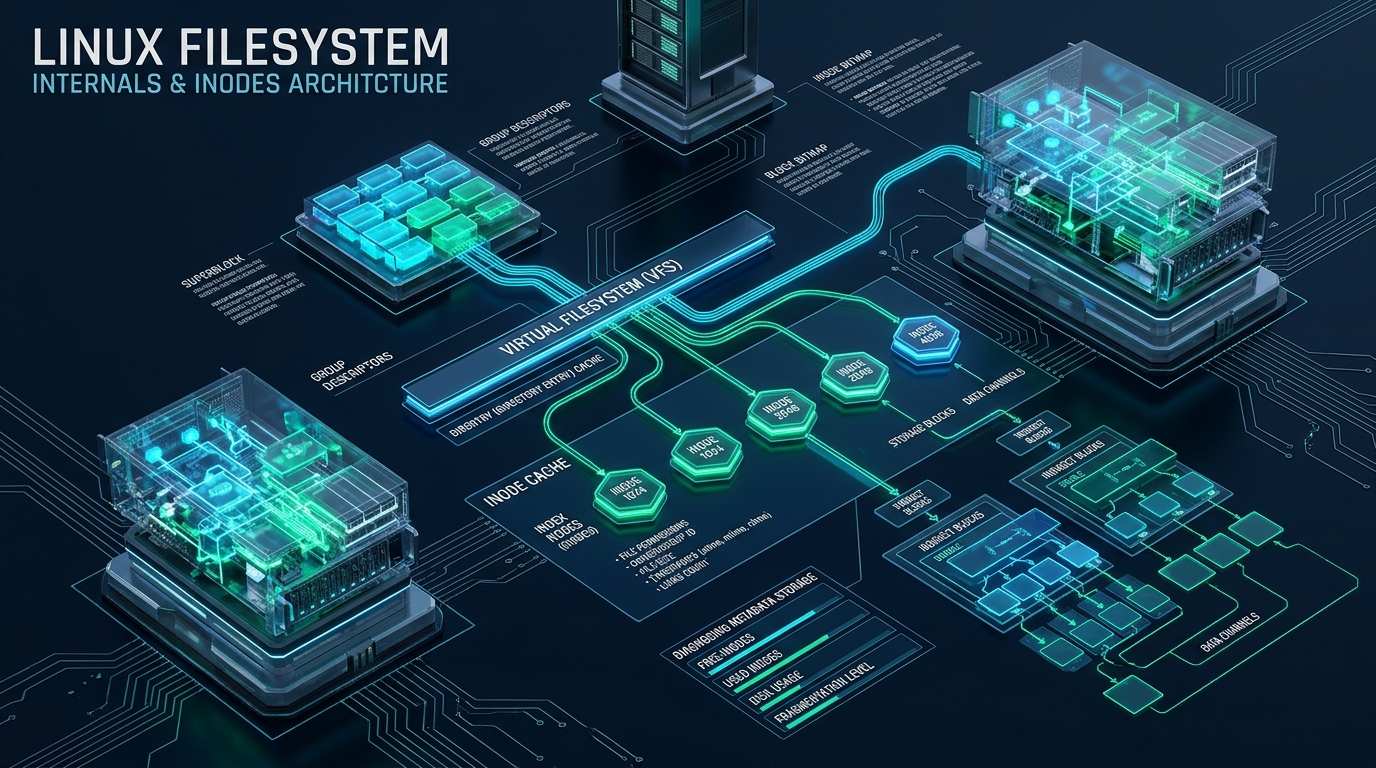
Few operational incidents trigger more cognitive dissonance for systems engineers than executing touch /tmp/test.txt and receiving a catastrophic No space left on device error, only to have df -h report hundreds of gigabytes of available storage capacity. This counterintuitive failure is the hallmark signature of filesystem metadata exhaustion, where an application layer or automated daemon exhausts the kernel’s allocated index nodes (inodes) long before consuming physical storage blocks. By benchmarking storage subsystems in isolated CpanelFree staging labs and understanding the internal mechanics of the Linux Virtual File System (VFS), administrators can rapidly pinpoint runaway micro-file generators, safely purge multi-million-file directory hierarchies without triggering out-of-memory panics, and tune filesystem parameters for maximum resilience.
Understanding Linux Inodes: How to Diagnose and Fix ‘No Space Left on Device’ with Free Disk Space
Direct Answer: A no space left on device free disk inodes error occurs when a Linux filesystem exhausts its index node table through millions of small files, sessions, or mail queues while storage blocks remain available. Diagnose via df -i, isolate culprit directories with find, and purge rapidly using find /target -type f -delete.
1. The Anatomy of an Inode: How the Linux VFS Decouples Data from Metadata
To diagnose and permanently prevent inode exhaustion, one must inspect how the Linux Virtual File System (VFS) abstracts persistent storage. In UNIX-derivative architectures, a file is not a monolithic single entity; it is strictly separated into two fundamental layers: payload data blocks and metadata index records.
An inode (index node) is a fixed-size data structure—typically 256 bytes in modern ext4 filesystems—stored in dedicated metadata tables on disk. Every regular file, directory, symbolic link, FIFO, block device, and Unix domain socket requires exactly one inode. Crucially, the inode does not store the file’s human-readable name or its actual payload data. Instead, an inode encapsulates:
- File Ownership & Permissions: User ID (UID), Group ID (GID), POSIX access control lists, and standard permission bits (rwxrwxrwx).
- File Type & Attributes: Regular file, directory, symlink, character device, or socket, alongside immutable/append-only ext4 attributes.
- Timestamps: Access time (
atime), modification time (mtime), inode change time (ctime), and creation/birth time (crtimein ext4). - Link Count (
i_nlink): The total number of directory hard links referencing this specific inode number. - Block Mapping Extents: Pointers to physical storage blocks or B-tree extent trees (in modern ext4/XFS) mapping logical file offsets to underlying disk LBAs.
Where is the file name stored? The file name exists exclusively as an entry in a directory. In Linux, a directory is simply a special file containing a table that maps human-readable strings to inode numbers (called directory entries or dentries). When a process calls open("/var/log/syslog", O_RDONLY), the kernel performs a path lookup through the dentry cache (dcache), resolves the string "syslog" to inode number #1441829, loads that inode’s extent map, and finally reads the raw storage blocks.
Architecture Note: The POSIX standard defines only a single error code—
ENOSPC(“No space left on device”, errno 28)—for both physical block exhaustion and metadata inode exhaustion. Because the operating system interface does not differentiate between lack of disk blocks and lack of index nodes at the syscall boundary, applications simply report “disk full,” obscuring the root cause from automated monitoring.
2. Architectural Divergence: Static ext4 Inodes vs. Dynamic XFS Allocation
Why do some servers run out of inodes while others gracefully consume all disk capacity? The answer lies in the fundamental design decisions of your underlying filesystem:
ext4 Static Allocation: When an ext4 filesystem is created via mkfs.ext4, the kernel carves out a static, immutable inode table based on the total partition size and the inode ratio (defaulting to 1 inode per 16 KB of disk space, or bytes-per-inode = 16384). On a 100 GB drive, this creates roughly 6.5 million inodes, reserving ~1.6 GB of raw disk strictly for metadata structures. If an application generates 6.5 million micro-files (e.g., 100-byte PHP session tokens), every single inode is consumed. Although 99 GB of data blocks remain completely untouched, the filesystem aborts all subsequent file creation with ENOSPC. You cannot resize the inode table on a live ext4 filesystem without reformatting.
XFS Dynamic Allocation: In contrast, XFS divides storage into independent Allocation Groups (AGs) and allocates inodes dynamically on-demand in 64-inode chunks within those groups. Inodes compete directly with data blocks for disk space. However, XFS enforces a safety ceiling via the maxpct parameter (defaulting to 25% of total filesystem capacity, or 5% on volumes exceeding 1 TB). If small-file proliferation hits this threshold, XFS will throw ENOSPC despite having free data space. Crucially, unlike ext4, XFS allows live tuning of this threshold on a mounted volume using xfs_growfs -m <percentage> /mountpoint.
3. Storage Architecture Comparison: Ext4 vs. XFS vs. Btrfs vs. ZFS
The following matrix benchmarks how modern production Linux filesystems handle inode allocation, scalability limits, small-file densities, and operational recovery:
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| ext4 Inode Allocation | Static table at mkfs (1 inode per 16KB) |
Custom density (mkfs.ext4 -i 4096) |
| ext4 Live Inode Expansion | Impossible (immutable table structure) | Block device resize adds new block groups |
| XFS Inode Allocation | Dynamic 64-inode chunks, capped at maxpct=25% |
Live expandable via xfs_growfs -m 50 |
| Btrfs Inode Architecture | Completely dynamic B-Tree node allocation | Subvolume quotas (qgroups) to isolate trees |
| ZFS dnode Mechanics | 512-byte dnodes in Object Directory Table | recordsize=128k + dnodesize=auto |
| Directory Traversal (1M+ files) | Linear scanning / E2BIG command-line overflow |
HTree indexed directory lookups (dir_index) |
| Purge Latency (1,000,000 files) | rm -rf *: ~240s (or crash on glob) |
find -delete / rsync mirror: ~18s |
4. Production Diagnostic Runbook: Isolating Inode Bottlenecks
When an outage notification alerts on ENOSPC, follow this structured diagnostic sequence to isolate the exact root cause in under two minutes.
Step 1: Confirm Metadata vs. Block Space Exhaustion
Standard monitoring dashboards often only evaluate block capacity (df -h). Run df -i immediately to inspect the total, used, and free inode counts:
# Compare block capacity vs inode capacity
$ df -h /var
Filesystem      Size  Used Avail Use% Mounted on
/dev/nvme0n1p2  100G   24G   72G  25% /var

$ df -i /var
Filesystem       Inodes   IUsed   IFree IUse% Mounted on
/dev/nvme0n1p2  6553600 6553600       0  100% /var
In the output above, notice that Use% is a modest 25% with 72 GB free, but IUse% is 100% with 0 free inodes. The filesystem cannot create a single additional file.
Step 2: Trace Inode-Dense Directories Without Crashing the Shell
Running ls -l or wildcard expansions inside a directory containing two million files will choke the kernel dentry cache, consume gigabytes of user-space memory, and fail with bash: /bin/ls: Argument list too long (E2BIG). Instead, leverage stream-based traversal that outputs directory paths directly to sort and uniq:
# High-performance single-pass inode discovery (stays on same filesystem via -xdev)
$ find /var -xdev -printf '%h
' | sort | uniq -c | sort -k1 -nr | head -20

# Sample Output:
# 4210984 /var/lib/php/sessions
# 1845210 /var/spool/postfix/maildrop
#  320140 /var/cache/nginx/client_temp
#   84210 /var/log/journal
Alternatively, modern coreutils (GNU du v8.27+) provides native inode auditing without external pipes: du --inodes -d 2 /var | sort -rn | head -20.
Step 3: Detect “Ghost” Inodes Held Open by Running Daemons
Occasionally, find reports low file counts across all directories, yet df -i stubbornly reports 100% inode utilization. This scenario indicates that an automated cron or administrator deleted thousands of files while active processes continued holding open file descriptors (FDs). The kernel removes the directory entry (name), but preserves the inode and allocated blocks until the process terminates.
# Discover deleted files held open by active processes
$ lsof +L1 -P -n | awk '$5 ~ /REG/ {print $1, $2, $4, $7, $8, $9}' | head -20

# Sample Output:
# COMMAND     PID  FD     SIZE INODE  NAME
# php-fpm    4821 14w        0 918231 /tmp/sess_8f3a9 (deleted)
# nginx      5102  7u     1024 918232 /var/cache/nginx/fastcgi_temp/1 (deleted)
To instantly reclaim these orphaned inodes without rebooting the server, gracefully reload the offending daemon: systemctl reload php-fpm or truncate the file descriptor via the /proc filesystem: : > /proc/<PID>/fd/<FD>.
5. High-Velocity Remediation: Purging Millions of Files Safely
When confronting a directory housing 5,000,000 abandoned session files or cached mail headers, standard shell commands will either abort or stall host I/O. Here are the three most efficient ways to purge massive file counts:
Method 1: Native find -delete (Recommended)
Do never use find ... | xargs rm -f or find ... -exec rm {} +; both approaches incur severe process-forking overhead and memory churn. The -delete flag instructs find to invoke the native C-level unlinkat() system call directly on each directory leaf entry without spawning external binaries:
# Efficiently delete PHP sessions older than 7 days
$ find /var/lib/php/sessions -type f -name 'sess_*' -mtime +7 -delete

# Instant total wipe of all files inside a cache directory
$ find /var/cache/nginx/proxy_temp/ -type f -delete
Method 2: The Ultra-Fast Rsync Directory Mirror Technique
When you need to empty an entire directory tree containing millions of files, rsync with --delete executes up to 3x faster than rm -rf because its internal diffing engine constructs optimized memory tables and optimizes disk head movement:
# 1. Create a blank temporary directory
$ mkdir -p /tmp/empty_dir

# 2. Mirror the empty directory over the bloated target
$ rsync -a --delete --quiet /tmp/empty_dir/ /var/spool/postfix/maildrop/

# 3. Clean up the placeholder
$ rmdir /tmp/empty_dir
Production Warning: Beware of filesystem directory shrinkage! When ext4 allocates directory index blocks (HTrees) to house millions of entries, deleting the files does not shrink the parent directory file size on disk. A directory that once held 10,000,000 files may continue to occupy 400 MB of RAM/disk space as an empty container, degrading future directory traversals. After deleting the files, always delete and recreate the directory itself:
rmdir /path/to/bloated_dir && mkdir -p /path/to/bloated_dir && chmod 700 /path/to/bloated_dir.
6. Production Hardening: Automated Cleaners, Monitoring, and Formatting
Relying on manual firefighting when an inode table hits 100% is unacceptable for enterprise availability. Deploy these three production configurations to automate lifecycle garbage collection, detect inode anomalies before outages occur, and provision optimal filesystems.
Config 1: Automated systemd-tmpfiles Lifecycle Sweeper
Modern Linux distributions leverage systemd-tmpfiles to enforce directory aging. Create /etc/tmpfiles.d/session-cleanup.conf to automatically purge orphaned sessions, application locks, and temp caches:
# /etc/tmpfiles.d/session-cleanup.conf
# Type Path                       Mode UID  GID  Age Argument
d     /var/lib/php/sessions       0733 root root 24h  -
d     /var/cache/nginx/proxy_temp 0700 nginx nginx 2d -
d     /tmp/spool-cache            1777 root root 12h  -
e     /var/spool/postfix/maildrop 0730 postfix postdrop 48h -
Apply and verify the configuration immediately without waiting for the daily timer: systemd-tmpfiles --clean /etc/tmpfiles.d/session-cleanup.conf.
Config 2: Systemd Inode Threshold Watchdog Unit & Timer
Deploy an automated monitor to sample inode utilization every 5 minutes and alert before the volume reaches critical failure. Save to /etc/systemd/system/inode-watchdog.service:
# /etc/systemd/system/inode-watchdog.service
[Unit]
Description=Linux Inode Capacity Early-Warning Watchdog
After=network.target

[Service]
Type=oneshot
ExecStart=/bin/bash -c '  CRIT_THRESHOLD=85;   df -P -i | awk "NR>1 {print \$5, \$6}" | sed "s/%//" | while read -r IUSE MOUNT; do     if [ "$IUSE" -ge "$CRIT_THRESHOLD" ]; then       logger -t inode-watchdog -p daemon.crit "CRITICAL: Mount point $MOUNT has exceeded $CRIT_THRESHOLD%% inode utilization ($IUSE%% used)!";       /usr/bin/find "$MOUNT" -xdev -printf "%h\n" 2>/dev/null | sort | uniq -c | sort -rn | head -5 | logger -t inode-watchdog -p daemon.warn;     fi;   done'
StandardOutput=journal
StandardError=journal

[Install]
WantedBy=multi-user.target
Accompany it with a systemd timer in /etc/systemd/system/inode-watchdog.timer:
# /etc/systemd/system/inode-watchdog.timer
[Unit]
Description=Run Inode Watchdog Every 5 Minutes
RefuseManualStart=no
RefuseManualStop=no

[Timer]
OnBootSec=2min
OnUnitActiveSec=5min
Unit=inode-watchdog.service

[Install]
WantedBy=timers.target
Activate the automated daemon: systemctl daemon-reload && systemctl enable --now inode-watchdog.timer.
Config 3: Formatting High-Density Inode Filesystems
When provisioning storage dedicated to micro-file heavy applications (such as mail storage, web caching clusters, or Git repository mirrors), configure the inode ratio during partition formatting. For ext4, decrease the bytes-per-inode ratio (-i 4096 gives 4x more inodes than default):
# Format ext4 volume with 4KB inode density (ideal for small web sessions)
$ mkfs.ext4 -N 20000000 -m 1 -O dir_index,extent /dev/nvme0n1p3

# Alternatively, format XFS with high inode allocation allowance
$ mkfs.xfs -f -i maxpct=50 -m reflink=1,crc=1 /dev/nvme0n1p3
Frequently Asked Questions
Can I add more inodes to an existing ext4 filesystem without reformatting?
No. On an ext4 filesystem, the inode table structure is calculated and fixed permanently at mkfs time. You cannot modify the bytes-per-inode ratio on an active volume. However, if you expand the underlying block device (e.g., expanding an LVM volume or cloud EBS/NVMe disk) and run resize2fs /dev/mapper/vol, the kernel adds new Block Groups containing fresh inode tables proportional to the added storage. If resizing the physical drive is not an option, you must migrate the data, reformat with mkfs.ext4 -i 4096, and restore.
Why does ‘rm -rf *’ fail with ‘Argument list too long’ and how do I avoid it?
When you type rm -rf *, the shell (Bash or Zsh) expands the wildcard asterisk into an in-memory array of every single file name before executing the binary. The Linux kernel imposes a strict limit (ARG_MAX, typically 2 MB) on the total byte length of command-line arguments passed via the execve() system call. When a directory houses hundreds of thousands of files, this buffer overflows. To bypass this, execute find . -type f -delete, which reads directory stream dentries via getdents64() and invokes unlinkat() directly without argument expansion.
What happens to operational databases (MySQL/PostgreSQL) when inodes hit 100%?
Relational database engines react aggressively to inode exhaustion. While active tables with open file handles can frequently continue reading, transactional operations that require creating new temporary table files, sorting spillover buffers, writing binary logs (binlogs), or appending write-ahead logs (WAL segments) fail instantly with HY000: Error 28 (No space left on device). MySQL will mark InnoDB tables as read-only or crash into recovery mode, while PostgreSQL will abort transactions to prevent transaction wrap-around corruption.
How do I prevent PHP session files from causing recurrent inode exhaustion?
Standard PHP installations rely on Debian/RHEL cron scripts (e.g., /etc/cron.d/php) to purge old sessions. If systemd-tmpfiles or cron is disabled, or if custom PHP applications write sessions to custom paths (like /tmp or wp-content/cache) without garbage collection (session.gc_probability = 1), sessions accumulate infinitely. Best practice for high-concurrency production is to configure Redis or Memcached as the session backend (session.save_handler = redis) with automatic TTL key expiration, completely eliminating filesystem metadata overhead.
For mission-critical production workloads, managing storage architectures shouldn’t require constant emergency firefighting. Upgrading to MeraHost Enterprise Cloud gives you access to high-performance enterprise NVMe storage arrays with optimized filesystem configurations, high IOPS, LiteSpeed Web Server, and an immutable Same Renewal Price policy that shields your infrastructure budget from arbitrary cost inflation.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).