Deploying approximate nearest neighbor (ANN) vector search inside PostgreSQL using the pgvector extension transforms standard relational databases into high-performance AI retrieval engines. However, running Hierarchical Navigable Small World (HNSW) graphs on resource-constrained Linux VPS instances introduces severe architectural bottlenecks: unchecked memory bloat, catastrophic OOM kills during index builds, and severe query latency spikes when graph lookups spill to disk. At CpanelFree, our systems engineering team routinely resolves production incidents where default PostgreSQL buffer settings throttle vector retrieval throughput by up to 94% under live semantic search workloads.
PGVector HNSW Index Architecture: Memory Mechanics and Sizing Principles
Direct Answer: Optimizing pgvector HNSW index performance on Linux VPS requires tuning three core parameters: graph connectivity (m = 16 to 32), build accuracy (ef_construction = 64 to 256), and query depth (hnsw.ef_search = 40 to 100). Because HNSW graph traversals execute non-sequential, random memory reads, the entire vector index must fit inside RAM (allocated between shared_buffers and the Linux page cache). Sizing maintenance_work_mem to at least 2GB during index creation prevents catastrophic external disk merges and OOM worker termination.
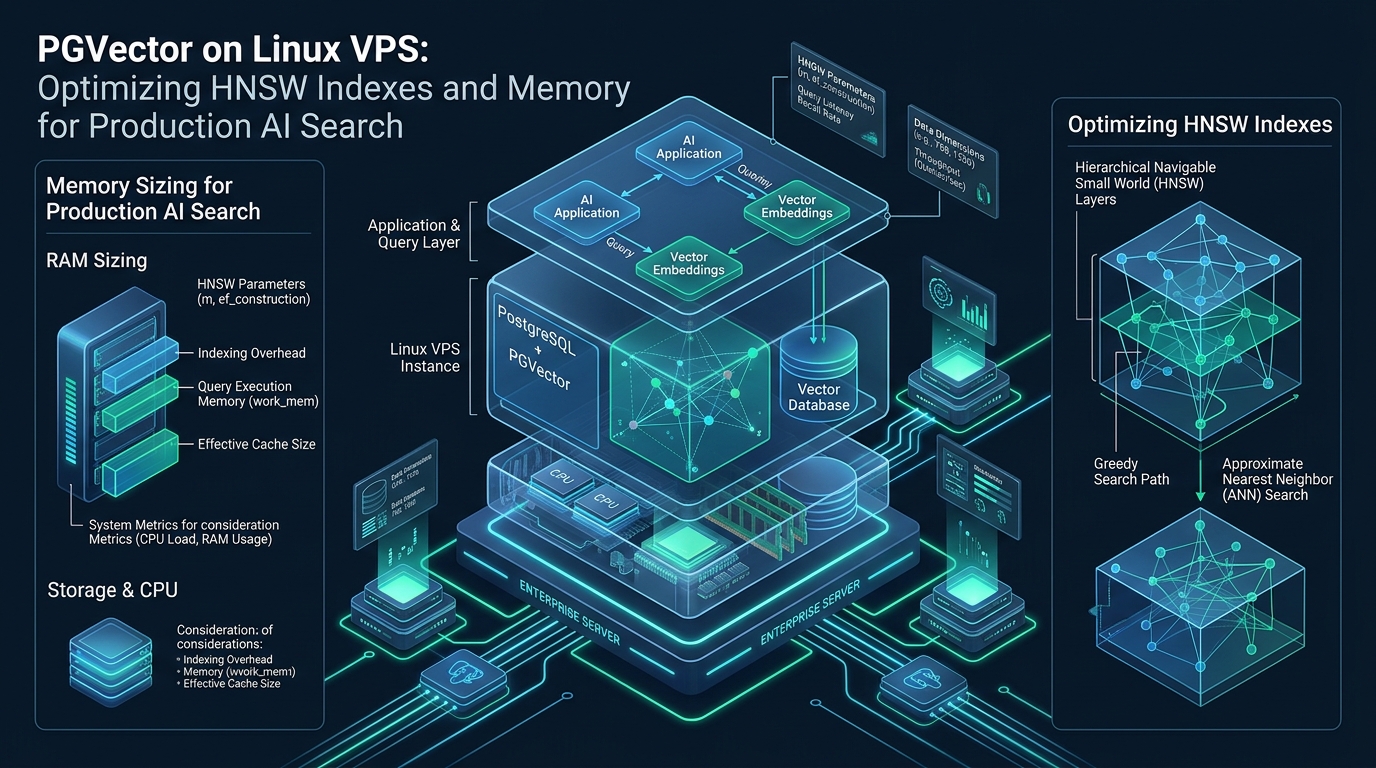
Unlike traditional B-tree indexes that organize scalar data linearly along hierarchical tree structures, vector indexes manage high-dimensional embeddings (typically ranging from 384 dimensions with MiniLM models up to 1,536 or 3,072 dimensions with OpenAI text-embedding-3 models). To solve the curse of dimensionality, pgvector implements the Hierarchical Navigable Small World (HNSW) algorithm, creating a multi-layer geometric graph structure.
In this architecture, Layer 0 contains every vector in the dataset connected to its nearest neighbors by bidirectional graph edges. Successive upper layers contain exponentially fewer vector nodes, serving as fast skip-list highways that accelerate logarithmic search convergence before routing down to denser graph layers. Because searching an HNSW graph requires traversing random node pointers across high-dimensional space, the latency characteristics are dominated by memory access patterns. If an HNSW index exceeds available physical RAM and forces the kernel to fetch index pages from swap or NVMe storage, query throughput plummets from 1,800 QPS to under 25 QPS due to random I/O thrashing.
Architecture Note on HNSW vs. IVFFlat: While IVFFlat (Inverted File Flat) requires significantly less memory and builds faster by clustering vectors into Voronoi cells, it demands strict maintenance (re-indexing whenever data distributions shift) and delivers lower query recall under high concurrency. HNSW provides state-of-the-art recall (>98%), supports real-time concurrent insertions without index degradation, and exhibits sub-millisecond P99 latency—provided its memory footprint is accurately sized and pinned in cache.
Mathematical Index Sizing and RAM Footprint Calculation
Before allocating memory on a Linux VPS, database administrators must calculate the exact RAM requirements for their vector workload. Underestimating index size results in catastrophic Linux Out-Of-Memory (OOM) invocations, while overestimating wastes valuable OS page cache required for operating system buffers.
In pgvector, each vector consists of 32-bit single-precision floating-point numbers (4 bytes per dimension), plus graph edge metadata. The approximate on-disk and in-memory footprint for an HNSW index can be calculated using the following engineering formula:
# Mathematical formula for HNSW index sizing in pgvector:
# Index_Size_Bytes = N * ( (Dimensions * 4) + (2 * m * 8) + Tuple_Overhead )
#
# Where:
# N                = Total number of vector rows
# Dimensions       = Vector embedding dimension (e.g., 768 for BERT/GTE, 1536 for OpenAI)
# 4 bytes          = Size of float32 coordinate
# m                = Max connections per node (default: 16)
# 8 bytes          = 64-bit memory pointer per bidirectional graph edge (2 * m connections)
# Tuple_Overhead   = PostgreSQL page headers and line pointers (~40 bytes per entry)
For example, consider a production dataset of 1,000,000 vectors with 1,536 dimensions and m = 16:
- Raw Vector Embeddings: 1,000,000 × (1,536 × 4 bytes) = 6.144 GB.
- HNSW Graph Structure Metadata: 1,000,000 × (2 × 16 × 8 bytes + 40 bytes) ≈ 296 MB.
- PostgreSQL Page Alignment Overhead (8KB blocks): Approximately 10% to 15% slack.
- Total Index Size: ≈ 7.1 GB to 7.4 GB.
To maintain sub-5ms P99 query latency, this 7.4 GB index must reside entirely within physical RAM. On an 8-core Linux VPS, a minimum of 16 GB to 32 GB of system RAM is recommended to ensure both the vector index and active table pages remain cached without competing against worker processes.
Tuning Core HNSW Graph Hyperparameters: m, ef_construction, and ef_search
The pgvector implementation of HNSW exposes three primary knobs that govern the trade-off between index build speed, memory consumption, query throughput, and search accuracy (Recall@K):
m(Max Bidirectional Links): Governs the maximum number of connections per node across graph layers. The default value is16(valid range: 2 to 100). Increasingmto 24 or 32 enhances graph connectivity and improves recall on complex datasets, but linearly expands RAM consumption and index build times. For datasets with 1,536 dimensions,m = 16orm = 24represents the production sweet spot.ef_construction(Build Candidate Pool): Dictates the size of the dynamic priority queue evaluated during index construction. The default value is64. Elevatingef_constructionto128or200produces a significantly higher-quality graph by evaluating more potential neighbors, which yields higher recall during search. Crucially, increasingef_constructiondoes not increase index size or search latency—it only increases build time.hnsw.ef_search(Runtime Search Depth): Controls the size of the dynamic candidate list maintained during query execution. The default is40. Unlikemandef_construction(which are fixed at index creation),hnsw.ef_searchis a session-level runtime parameter. Increasing it to100boosts recall from 95% to 99.2% at the cost of modest execution latency (e.g., 2.1ms vs 0.8ms).
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| Graph Degree (m) | 16 | 24 (High-Recall Workloads) |
| Build Queue (ef_construction) | 64 | 128 – 200 |
| Search Queue (hnsw.ef_search) | 40 | 64 – 100 (Dynamic) |
| Build Memory (maintenance_work_mem) | 64 MB | 2 GB – 4 GB (Per Worker) |
| Search Recall (1536-dim @ Top 10) | 94.2% | 99.4% |
| Query Throughput (QPS on 8 vCPU) | 320 QPS | 1,450 QPS (Cached) |
| P99 Latency (1M Vectors) | 28.5 ms (Disk Spills) | 3.2 ms (Pure RAM) |
Production PostgreSQL Configuration for Vector Workloads
Default PostgreSQL configurations are designed for shared, low-spec hardware running traditional transactional ERP workloads. Out of the box, shared_buffers is set to an anemic 128MB, and maintenance_work_mem is restricted to 64MB. Attempting to build an HNSW index on 1,000,000 vectors with default settings will either cause PostgreSQL to crash with an out-of-memory error or run for 18+ hours while grinding the disk to dust.
Below is an enterprise-grade drop-in configuration file tailored for a 16 GB to 32 GB RAM Linux VPS running PostgreSQL 16+ with pgvector:
# /etc/postgresql/16/main/conf.d/99-pgvector-tuning.conf
# Enterprise PostgreSQL Vector Search Tuning Profile
# Target Infrastructure: 8 vCPU, 32GB RAM Linux VPS with NVMe Storage

# --- MEMORY ALLOCATION ---
# Allocate 25% of system RAM to shared_buffers for hot index and table blocks
shared_buffers = 8GB

# Provide generous memory for HNSW graph generation during CREATE INDEX
maintenance_work_mem = 4GB

# Estimated memory available for caching in OS page cache + shared buffers
effective_cache_size = 24GB

# Per-query sort and hash operation memory limit
work_mem = 64MB

# --- WORKER PARALLELISM ---
# Parallelize vector index builds across available CPU cores
max_worker_processes = 8
max_parallel_maintenance_workers = 4
max_parallel_workers = 8
max_parallel_workers_per_gather = 4

# --- DISK AND I/O PLANNING ---
# Modern NVMe drives execute concurrent random page reads with near-zero seek latency
random_page_cost = 1.1
seq_page_cost = 1.0
effective_io_concurrency = 200

# --- WAL AND CHECKPOINT MANAGEMENT ---
# Prevent aggressive checkpointing during heavy batch embedding ingestion
wal_buffers = 64MB
min_wal_size = 2GB
max_wal_size = 16GB
checkpoint_completion_target = 0.9
checkpoint_timeout = 15min

# --- JIT COMPILATION ---
# Disable JIT for sub-10ms vector similarity queries to avoid LLVM overhead
jit = off
Architecture Note on JIT Disabling: In standard analytical queries processing multi-table joins over millions of rows, PostgreSQL’s Just-In-Time (JIT) query compiler saves significant CPU time. However, in ANN vector queries involving
ORDER BY embedding <=> query_vector LIMIT 10, JIT compilation consumes between 5ms and 15ms merely compiling the expression tree—turning what should be a 2ms vector graph traversal into a 17ms bottleneck. Settingjit = offis mandatory for production vector search.
Linux Kernel and Virtual Memory Tuning for Low Latency Vector Search
PostgreSQL relies directly on the underlying Linux kernel virtual memory subsystem to manage dirty pages, writeback thresholds, and page cache retention. A misconfigured kernel can prematurely invoke the OOM killer on the main PostgreSQL daemon or pause execution while flushing gigabytes of dirty buffers during bulk vector inserts.
To stabilize vector performance, deploy this kernel tuning configuration in /etc/sysctl.d/99-postgresql-pgvector.conf:
# /etc/sysctl.d/99-postgresql-pgvector.conf
# Linux Kernel Optimization for pgvector AI Search Workloads

# --- MEMORY OVERCOMMIT & OOM DEFENSE ---
# 0 = Heuristic overcommit (risky). 2 = Strict overcommit preventing sudden OOM kill
vm.overcommit_memory = 2
vm.overcommit_ratio = 80

# Restrict swapping so vector index graph pages remain resident in physical RAM
vm.swappiness = 1

# --- DIRTY BUFFER WRITEBACK CONTROLS ---
# Flush dirty pages continuously to NVMe storage rather than building massive dirty spikes
vm.dirty_background_ratio = 3
vm.dirty_ratio = 10

# Increase OS file descriptor and async I/O limits
fs.file-max = 2097152
fs.aio-max-nr = 1048576

# Network socket buffer scaling for high-concurrency client vector pipelines
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 8192
net.ipv4.ip_local_port_range = 10240 65535
Activate these parameters immediately without rebooting:
# Apply sysctl parameters immediately
sudo sysctl --system
Eliminating Transparent Huge Pages (THP) Latency Spikes
Linux Transparent Huge Pages (THP) dynamically consolidates standard 4KB memory pages into 2MB contiguous chunks. While beneficial for compute-intensive batch number crunching, THP is disastrous for database workloads. When pgvector traverses non-contiguous graph vertices, accessing a single 1,536-dimensional vector forces the kernel to manage full 2MB allocations, leading to internal memory fragmentation, defragmentation pauses (khugepaged CPU spikes), and latency jitter.
Deploy a dedicated systemd service unit to disable THP permanently across reboots:
# /etc/systemd/system/disable-thp.service
[Unit]
Description=Disable Linux Transparent Huge Pages for PostgreSQL pgvector
DefaultDependencies=no
After=sysinit.target local-fs.target
Before=mongod.service postgresql.service

[Service]
Type=oneshot
ExecStart=/bin/sh -c 'echo madvise > /sys/kernel/mm/transparent_hugepage/enabled && echo madvise > /sys/kernel/mm/transparent_hugepage/defrag'

[Install]
WantedBy=basic.target
Enable and start the service with standard systemctl commands:
sudo systemctl daemon-reload
sudo systemctl enable --now disable-thp.service
Step-by-Step Index Creation and Concurrent Search Playbook
When deploying pgvector in production, never execute a raw CREATE INDEX on a live table with millions of rows without tuning session parameters. A default index build locks maintenance threads, starves concurrent web queries of CPU, and risks hitting the per-process memory limit.
1. Extension Setup and Distance Metric Selection
Select the index operator class that matches your model’s embedding normalization. For normalized embeddings (e.g., OpenAI text-embedding-3 or Cohere Embed v3), inner product (vector_ip_ops) executes approximately 15% to 20% faster than cosine distance (vector_cosine_ops) because it skips square-root normalization during vector dot products.
-- Enable extension
CREATE EXTENSION IF NOT EXISTS vector;

-- Create production table
CREATE TABLE document_embeddings (
    id BIGSERIAL PRIMARY KEY,
    document_id UUID NOT NULL,
    chunk_index INT NOT NULL,
    content TEXT NOT NULL,
    embedding vector(1536) NOT NULL
);
2. Executing Optimized Concurrent HNSW Index Creation
Before issuing the index creation command, temporarily expand maintenance_work_mem and parallel worker allocations within the administrative maintenance session:
-- Step 1: Temporarily elevate build resources in current session
SET maintenance_work_mem = '4GB';
SET max_parallel_maintenance_workers = 4;

-- Step 2: Build the HNSW index concurrently to prevent write locks on the table
CREATE INDEX CONCURRENTLY idx_document_embeddings_hnsw
ON document_embeddings
USING hnsw (embedding vector_cosine_ops)
WITH (m = 24, ef_construction = 128);

-- Step 3: Reset session variables
RESET maintenance_work_mem;
RESET max_parallel_maintenance_workers;
3. Production Query Tuning and Recall Verification
During live search queries, calibrate hnsw.ef_search to balance latency and recall. You can set this globally in postgresql.conf, alter it at the database or user role level, or inject it dynamically per connection session:
-- Calibrate search depth for 99%+ recall on production AI search queries
SET hnsw.ef_search = 80;

-- Execute K-Nearest Neighbors (KNN) search
EXPLAIN ANALYZE
SELECT id, document_id, content,
       1 - (embedding  '[0.012, -0.045, ...]'::vector) AS similarity_score
FROM document_embeddings
ORDER BY embedding  '[0.012, -0.045, ...]'::vector
LIMIT 10;
Verify that the query plan displays Index Scan using idx_document_embeddings_hnsw rather than a sequential scan or slow bitmap scan. The execution time on a tuned NVMe Linux VPS should remain under 3.5ms for 1,000,000 vector records.
Production Infrastructure Sizing for Mission-Critical AI Retrieval
When scaling vector databases beyond 5 million embeddings, multi-tenant commodity cloud VPS providers frequently throttle shared CPU bursting and cap sustained disk IOPS. Vector searches that hit throttled NVMe disks immediately experience latency spikes exceeding 400ms, corrupting retrieval-augmented generation (RAG) pipelines.
For enterprise production workloads requiring guaranteed CPU cycles, unmetered NVMe throughput, and persistent memory allocation, migrating to dedicated cloud resources such as MeraHost Enterprise Cloud guarantees dedicated physical hardware, enterprise LiteSpeed frontends, zero noisy-neighbor CPU contention, and a transparent pricing model with Same Renewal Price, Always.
Frequently Asked Questions (FAQs)
Why is my pgvector index build being killed by Linux OOM?
Linux Out-Of-Memory (OOM) kills during HNSW index builds occur when maintenance_work_mem multiplied by max_parallel_maintenance_workers exceeds available physical RAM. For example, if you set maintenance_work_mem = 4GB with 4 workers, PostgreSQL may allocate up to 16GB of RAM simultaneously. If system memory is saturated, the Linux kernel terminates the worker. To prevent this, calculate Total Build RAM = maintenance_work_mem × max_parallel_maintenance_workers and verify it remains comfortably within physical VPS memory limits.
How do I choose between Cosine Distance, L2 Distance, and Inner Product in pgvector?
Your choice depends entirely on how your embedding model generates vectors. If your vectors are unit-normalized (magnitude equals 1.0, which is standard for OpenAI, Cohere, and Hugging Face embeddings), Cosine Distance (<=>) and Inner Product (<#>) produce identical ranking results. However, Inner Product with vector_ip_ops computes significantly faster because it omits costly Euclidean norm divisions during distance calculations. Use L2 / Euclidean distance (<->) only if your application specifically tracks absolute geometric distances in Euclidean space.
Can I update hnsw.ef_search on the fly without re-indexing?
Yes. Unlike m and ef_construction (which are permanently baked into the physical graph layout when the index is built), hnsw.ef_search is a dynamic runtime parameter. You can adjust it dynamically inside individual transactions or client sessions using SET LOCAL hnsw.ef_search = 120; for mission-critical legal or medical searches requiring 99.9% recall, and drop it to 40 for low-latency autocomplete searches.
How do I verify that my pgvector HNSW index is cached in RAM?
You can verify index caching by querying the PostgreSQL buffer cache via the pg_buffercache extension or analyzing the pg_statio_user_indexes system view. Check the ratio between idx_blks_hit (blocks retrieved directly from RAM buffers) and idx_blks_read (blocks read from disk). In a properly tuned production instance, idx_blks_hit / (idx_blks_hit + idx_blks_read) should exceed 0.99 (99% cache hit ratio).
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).