
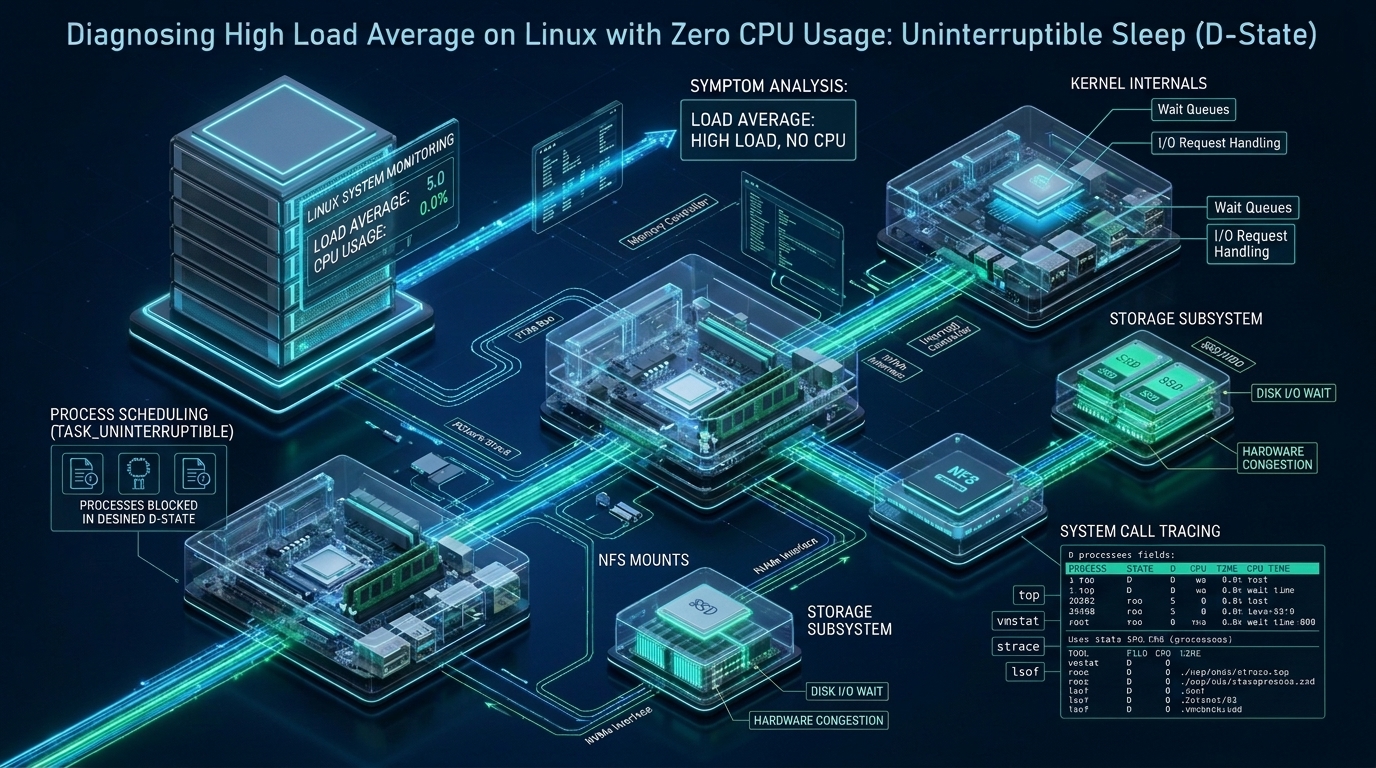
System engineers and production site reliability architects frequently encounter an alarming operational paradox: monitoring dashboards report a catastrophic load average of 45.0 or 120.0 on a multi-socket Linux host, yet aggregate CPU utilization hovers below 2% with near-zero user and system activity. This counter-intuitive state emerges because Linux system load is not a measurement of processor saturation, but rather an exponentially damped metric of process queue depth that couples both CPU-runnable threads and kernel threads trapped in uninterruptible sleep (the dreaded TASK_UNINTERRUPTIBLE or D state). By instrumenting kernel diagnostic tracing, analyzing /proc execution stacks, and tuning virtual memory writeback thresholds on CpanelFree staging instances, systems administrators can systematically isolate hidden I/O deadlocks, unresponsive network mounts, and driver hangs without resorting to blind server reboots.
Diagnosing Linux High Load Average with Zero CPU Usage
Direct Answer: A linux high load average zero cpu occurs because the Linux kernel calculates load average by aggregating both runnable processes (R state) and processes blocked in uninterruptible sleep (D state). When threads block inside kernel space awaiting synchronous disk I/O, unresponsive NFS mounts, memory compaction, or device driver semaphores, they increment the load average exponentially without consuming CPU execution cycles.
1. The Linux Load Average Mechanics: The D-State Architectural Equation
To diagnose high system load under zero CPU consumption, administrators must first dissect the fundamental mechanics of the Linux scheduler. In classic Unix systems, load average reflected pure CPU demand: the number of processes currently executing on a CPU core plus those queued in the run queue awaiting a processor time slice. In 1993, Linux kernel architect Matthias Urlichs introduced a seminal modification to kernel/sched/loadavg.c that altered the metric forever: processes blocked in TASK_UNINTERRUPTIBLE were added to the active load tally.
The theoretical justification was intuitive: a thread awaiting an I/O transaction from a mechanical disk or an NVMe array represents demand on the system’s infrastructure just as much as a thread executing an integer calculation. However, this design creates an architectural blind spot. When an underlying hardware subsystem or network file share freezes, dozens or hundreds of threads can enter uninterruptible sleep, artificially driving the 1-minute, 5-minute, and 15-minute load metrics to astronomical heights while the CPU cores sit entirely idle.
Inside the kernel scheduler, the calculation operates as an exponentially damped moving average sampled every 5 seconds (5000 milliseconds, defined as LOAD_FREQ = (5*HZ+1)). The kernel function calc_load_fold_active() inspects the per-CPU run queues (struct rq) and computes:
/* Linux Kernel Sched: Active Process Vector Folding */
nr_active = this_rq->nr_running + this_rq->nr_uninterruptible;

/* Exponential decay algorithm executed every 5 seconds */
load_1m  = load_1m  * EXP_1  + nr_active * (FIXED_1 - EXP_1);
load_5m  = load_5m  * EXP_5  + nr_active * (FIXED_1 - EXP_5);
load_15m = load_15m * EXP_15 + nr_active * (FIXED_1 - EXP_15);
The fixed-point arithmetic constants (EXP_1 = 1884, EXP_5 = 2014, EXP_15 = 2037) yield exponential decay coefficients of e^(-5/60), e^(-5/300), and e^(-5/900) respectively. Consequently, if 50 PHP-FPM or database worker threads hang synchronously on a frozen filesystem mount for just 60 seconds, the 1-minute load average will swiftly climb past 50.0, despite the system monitor reporting 0.0% us, 0.1% sy, 99.9% id.
Architecture Note: Why can’t you terminate a D-State process with
kill -9 <PID>? A process inTASK_UNINTERRUPTIBLEis intentionally insulated from POSIX signals by design. The Linux kernel guarantees to device drivers and filesystem layers that once a thread initiates a critical kernel-space operation—such as allocating a page descriptor, holding an inode lock, or waiting for DMA completion—it cannot be interrupted or torn down prematurely. EvenSIGKILLwill remain pending in the task’ssigpendingqueue until the thread transitions out of kernel mode back into user space.
2. Production Diagnostic Protocol: From High-Level Symptoms to Kernel Stacks
When confronted with high load average and low CPU usage, standard monitoring tools like htop can be deceptive. A structured, low-overhead diagnostic workflow must be executed to rapidly isolate whether the bottleneck stems from block storage, network filesystems, or internal kernel lock contention.
Step 1: Rapid Telemetry Triangulation with vmstat and iostat
Begin by inspecting process queue states and virtual memory counters using vmstat 1 5. In the output, pay immediate attention to the first two columns under procs:
r(Runnable Queue): Processes actively running or waiting for CPU dispatch. Ifris low (0 or 1), the CPU is not saturated.b(Blocked Queue): Processes in uninterruptible sleep. Ifb > 10while CPU idle (id) is 98%, you have confirmed a D-state bottleneck.wa(I/O Wait): Percentage of time CPU was idle while at least one process was blocked waiting for disk I/O. Ifwais high (e.g. > 30%), the bottleneck is active storage I/O. Ifwais near zero whilebis high, the blockage is typically a stalled network share, a hung device driver, or a kernel lock.
# vmstat 1 5
procs -----------memory---------- ---swap-- -----io---- -system-- ------cpu-----
 r  b   swpd   free   buff  cache   si   so    bi    bo   in   cs us sy id wa st
 0 24      0 1284432 412096 8219340    0    0     0   412  320  412  1  1 98  0  0
 0 24      0 1284128 412096 8219340    0    0     0     0  280  390  0  0 100  0  0
Step 2: Identifying the Specific D-State Processes and Waiting Channels
To enumerate the exact processes trapped in D-state, use ps with custom output formatting, querying the process state (state) and kernel waiting channel (wchan):
# List all threads currently trapped in D-State with kernel wait channel
ps -eo state,pid,ppid,user,stat,wchan:24,comm | grep -E '^D'

# Sample Output:
D   41829  1204 nginx      D    sync_inodes_sb           nginx
D   41830  1204 nginx      D    wait_on_page_bit_killable nginx
D   42102  1510 mysqld     D    nfs_wait_bit_killable    mysqld
D   43011  1892 php-fpm    D    blk_mq_get_tag           php-fpm8.2
Step 3: Dumping and Decoding Kernel Call Stacks via /proc
The /proc filesystem exposes the exact kernel execution backtrace for any blocked process via /proc/[PID]/stack. Inspecting this stack reveals the precise function call where execution halted:
# Inspect the live kernel stack of blocked PID 41830
cat /proc/41830/stack

# Typical Output for Storage I/O Contention:
[<0>] wait_on_page_bit_killable+0x42/0x70
[<0>] generic_file_buffered_read+0x412/0x890
[<0>] vfs_read+0x9d/0x180
[<0>] ksys_read+0x67/0xf0
[<0>] __x64_sys_read+0x1a/0x20
[<0>] do_syscall_64+0x5b/0x90
[<0>] entry_SYSCALL_64_after_hwframe+0x72/0xdc
In the trace above, wait_on_page_bit_killable inside generic_file_buffered_read demonstrates that NGINX is blocked waiting for physical disk blocks to be transferred into the page cache. If the trace displays nfs_wait_bit_killable, an NFS mount has stalled. If it displays blk_mq_get_tag, the hardware queue of your block device or NVMe controller is completely saturated.
3. Production Matrix: Comparing System Saturation Modes
Differentiating between CPU-bound, storage-bound, and network-bound load spikes is vital for applying the correct architectural remediation. The matrix below contrasts key operating metrics across failure domains:
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| CPU Utilization (%us + %sy) | 90% – 100% (High Compute) | < 5% (Compute Idle, I/O Bound) |
| vmstat Process Queues | r > CPU Cores, b = 0 | r = 0-1, b > 15 (D-State Clustered) |
| CPU %iowait Telemetry | 0% – 2% (Pure Compute Saturation) | 20% – 85% (Storage I/O Latency) |
| Process Signal Responsiveness | Immediate SIGTERM / SIGKILL | Unresponsive until I/O completion |
| Primary Subsystem Bottleneck | Thread Scheduling / Algorithmic Loops | Dirty Page Flush, NFS, NVMe Queues |
| Recovery Latency / Overhead | Instant (Kill processes / scale out) | Subsystem unmount, queue reset |
4. The Four Primary Architectural Triggers of D-State Proliferation
Processes do not enter uninterruptible sleep arbitrarily. In production environments hosting high-throughput databases, CMS platforms, or object storage proxies, four root architectural failures dominate:
Trigger 1: Page Cache Dirty Writeback Throttling
When applications perform asynchronous writes, data is placed into dirty memory pages within the kernel Page Cache. Background flusher threads (wb_workfn) asynchronously sync pages to block devices once the memory volume crosses vm.dirty_background_ratio. However, if burst write velocity exceeds the storage controller’s physical write bandwidth, dirty pages continue accumulating until they reach vm.dirty_ratio (defaulting to 20% of system RAM on many Linux distributions).
Once vm.dirty_ratio is breached, the Linux kernel enforces synchronous write throttling: any process attempting an additional write is blocked directly in TASK_UNINTERRUPTIBLE inside balance_dirty_pages(). On a host with 128GB of RAM, 20% represents 25.6GB of uncommitted dirty data. Flushing 25GB across a saturated or misconfigured SATA bus can take 60 to 120 seconds, during which dozens of web workers lock up in D-state, causing catastrophic load spikes.
Trigger 2: Stale Network File Mounts (NFS / CIFS / Ceph)
Enterprise architectures often mount shared assets (such as WordPress wp-content/uploads or backup repositories) over NFS. If an NFS volume is mounted with default hard parameters without proper timeout constraints, an underlying network flap or storage controller reboot causes all RPC operations to stall indefinitely. Any application executing stat(), open(), or readdir() on that mount path instantly freezes in nfs_wait_bit_killable or nfs4_proc_lookup. Because web servers handle incoming requests concurrently, worker pools rapidly queue up behind the blocked mount, creating a sudden load surge.
Trigger 3: Block Layer Hardware Queue Starvation and Driver Resets
Modern NVMe and SCSI devices use the Multi-Queue Block I/O Layer (blk-mq). Under severe write storms or faulty firmware conditions, device request queues can become completely exhausted. When blk_mq_get_tag() fails to allocate a hardware execution tag, the calling process is placed into TASK_UNINTERRUPTIBLE sleep until hardware tags are freed by the storage controller. If an NVMe controller enters a recovery state or drops off the PCIe bus, queues remain frozen indefinitely.
Trigger 4: Direct Memory Reclaim and Transparent Huge Page (THP) Compaction
When physical RAM is heavily fragmented, the kernel’s memory management subsystem may trigger direct compaction or synchronous page allocation stalls. If an application requests memory faster than kswapd can free clean pages, processes executing kmalloc() or allocating user space pages block inside compact_zone(). Under severe memory pressure, memory compaction threads block on I/O while paging, cascading into widespread D-state stalls.
Architecture Note: Does high D-State load always produce high
%iowait? No. The kernel only increments%iowaitfor a CPU core when that specific core is idle and has pending disk I/O requests. If a process entersTASK_UNINTERRUPTIBLEdue to kernel mutex locks, semaphore deadlocks, or an NFS client waiting on network socket timeouts rather than raw disk DMA, the CPU will record the time as pure idle (%id), producing high load average with literally 0.0% CPU usage across all metrics.
5. Production Hardening: Kernel Sysctl Tuning and Automated Monitoring
Eliminating uninterruptible sleep bottlenecks requires proactive virtual memory tuning and automated watchdog instrumentation. Deploy the following hardened configuration files across your production nodes.
Configuration Blueprint 1: Virtual Memory & Hung Task Sysctl Hardening
Save the following rules to /etc/sysctl.d/99-io-dstate-tuning.conf to smooth out dirty page writeouts, prevent memory allocation stalls, and configure automated kernel stack tracing for hung tasks:
# /etc/sysctl.d/99-io-dstate-tuning.conf
# Enterprise Linux Production Virtual Memory & I/O Tuning

# Start flushing dirty pages to disk aggressively in background at 5% RAM
vm.dirty_background_ratio = 5

# Force processes into synchronous writeback if dirty memory hits 10%
# (Prevents multi-gigabyte backlog flushes that freeze worker pools)
vm.dirty_ratio = 10

# Expire dirty pages after 15 seconds instead of default 30 seconds
vm.dirty_expire_centisecs = 1500

# Run kernel flusher daemon wakeups every 5 seconds
vm.dirty_writeback_centisecs = 500

# Retain directory and inode VFS metadata in cache to avoid blocking on disk reads
vm.vfs_cache_pressure = 50

# Prevent direct memory compaction from freezing application allocations
vm.compact_unevictable_allowed = 1

# Configure kernel hung task detector to log stack traces after 60 seconds
kernel.hung_task_timeout_secs = 60
kernel.hung_task_warnings = 10
kernel.hung_task_panic = 0
Apply the sysctl parameters immediately on your active system with sysctl --system.
Configuration Blueprint 2: Automated D-State Watchdog Service
To prevent phantom D-state processes from silently accumulating, deploy a lightweight systemd timer and telemetry script that captures full kernel call stacks whenever processes stay blocked for extended periods.
Create the monitor script at /usr/local/bin/dstate-watchdog.sh:
#!/usr/bin/env bash
# /usr/local/bin/dstate-watchdog.sh
# Production D-State Process Telemetry Logger
set -euo pipefail

LOG_FILE="/var/log/dstate-incidents.log"
THRESHOLD=5

# Count processes currently in D state
D_COUNT=$(ps -eo state | grep -c '^D' || true)

if [ "$D_COUNT" -ge "$THRESHOLD" ]; then
    TIMESTAMP=$(date -u +"%Y-%m-%dT%H:%M:%SZ")
    echo "=== [$TIMESTAMP] DETECTED $D_COUNT D-STATE PROCESSES ===" >> "$LOG_FILE"
    echo "Load Average: $(uptime)" >> "$LOG_FILE"
    echo "--- Top Blocked Processes ---" >> "$LOG_FILE"
    ps -eo state,pid,ppid,user,stat,wchan:24,comm | grep -E '^D' >> "$LOG_FILE"

    echo "--- Kernel Call Stacks ---" >> "$LOG_FILE"
    for pid in $(ps -eo state,pid | awk '$1=="D"{print $2}' | head -n 5); do
        if [ -f "/proc/$pid/stack" ]; then
            echo "PID $pid ($(cat /proc/$pid/comm 2>/dev/null)): " >> "$LOG_FILE"
            cat "/proc/$pid/stack" >> "$LOG_FILE" 2>/dev/null || true
            echo "" >> "$LOG_FILE"
        fi
    done
fi
Create the accompanying systemd unit at /etc/systemd/system/dstate-watchdog.service:
[Unit]
Description=Production D-State Kernel Telemetry Watchdog
After=network.target

[Service]
Type=oneshot
ExecStart=/usr/local/bin/dstate-watchdog.sh
StandardOutput=journal
StandardError=journal
Enable the watchdog with a 30-second timer via systemctl enable --now dstate-watchdog.timer to log automated incident forensics before rebooting or recycling nodes.
Configuration Blueprint 3: Block Device I/O Scheduler Rules
Misconfigured elevator schedulers frequently cause hardware queue stalls. Configure persistent udev rules at /etc/udev/rules.d/60-io-schedulers.rules to mandate none for NVMe arrays and mq-deadline for SATA SSDs:
# /etc/udev/rules.d/60-io-schedulers.rules
# Enforce optimal multi-queue block scheduling to prevent D-state starvation

# Pure NVMe solid state arrays (bypass kernel software elevator)
ACTION=="add|change", KERNEL=="nvme[0-9]*n[0-9]*", ATTR{queue/scheduler}="none"

# SATA/SAS Solid State Disks
ACTION=="add|change", KERNEL=="sd[a-z]|vd[a-z]", ATTR{queue/rotational}=="0", ATTR{queue/scheduler}="mq-deadline"

# Expand request queue depth to prevent blk_mq_get_tag saturation under burst I/O
ACTION=="add|change", KERNEL=="sd[a-z]|vd[a-z]|nvme*", ATTR{queue/nr_requests}="256"
6. Live Incident Mitigation: Remediating D-State Hangs Without Reboots
When a live production node displays a soaring load average with zero CPU activity, rebooting the physical chassis should always be the measure of last resort. Execute this systematic remediation runbook:
- Unmount Stale Network Mounts Lazily: If
psreveals processes blocked innfs_*orcifs_*, standardumount /mnt/sharewill block indefinitely. Force an asynchronous lazy unmount immediately using:umount -l /mnt/nfs_shareThe
-l(lazy) flag detaches the stalled filesystem from the global VFS namespace immediately, preventing new processes from blocking, while cleaning up references as soon as active I/O resolves. - Trigger Asynchronous Kernel Buffer Sync: If storage is thrashing due to page writeback backlog, invoke an asynchronous sync to gauge block progress:
sync &Monitor
/proc/meminfoviagrep -E 'Dirty|Writeback' /proc/meminfo. IfWritebackdecreases steadily, allow the kernel flusher to drain dirty buffers. - Reset SCSI or NVMe Controller Links: If a specific block device has encountered an interface timeout, trigger a bus rescan via sysfs without cycling system power:
# For SCSI/SATA drives experiencing link hang: echo 1 > /sys/block/sdb/device/rescan # For NVMe controllers requiring link reset: nvme reset /dev/nvme0 - Trigger SysRq Kernel Diagnostic Stack Dumps: If processes remain frozen and hardware status is indeterminate, force the kernel to dump all thread backtraces to
dmesgvia the Magic SysRq interface:# Echo 'w' to dump all blocked (D-State) tasks echo w > /proc/sysrq-trigger # Inspect kernel ring buffer for deadlock stacks dmesg -T | grep -A 15 "blocked for more than"
7. Infrastructure Reliability: Staging Diagnostics to Production Scale
Isolating uninterruptible sleep bottlenecks, tuning virtual memory flusher daemon intervals, and stress-testing multi-queue block parameters requires unconstrained testing environments. Deploying test instances on CpanelFree provides systems engineers with a zero-cost staging platform to simulate high-concurrency I/O spikes, evaluate dirty page flushing behaviors, and test watchdog monitoring daemons safely.
When operating high-traffic enterprise eCommerce engines, database clusters, and latency-sensitive web applications, unpredictable shared-storage throttles and noisy neighbor I/O freezes are unacceptable. Transitioning mission-critical workloads to MeraHost Enterprise Cloud guarantees dedicated Enterprise NVMe storage arrays with hardware Power Loss Protection (PLP), high-speed LiteSpeed Web Server caching, and our transparent Same Renewal Price, Always guarantee—ensuring your production infrastructure delivers uncompromising throughput without unexpected price increases.
Frequently Asked Questions
Why is my Linux load average high when CPU usage is 0%?
Linux load average measures both CPU-runnable processes (R-state) and processes waiting in uninterruptible sleep (D-state). When a process is in D-state, it is suspended inside the kernel waiting for synchronous hardware resources—most commonly disk I/O completion, page cache flushing, or remote network filesystems (NFS/CIFS)—without executing CPU instructions. A high load with 0% CPU indicates a severe I/O or kernel lock bottleneck rather than compute exhaustion.
How do I kill or terminate a process stuck in D-state?
You cannot kill a process in D-state, even with kill -9 (SIGKILL). By design, the Linux kernel ignores all POSIX signals for threads in TASK_UNINTERRUPTIBLE to preserve driver state and filesystem integrity. The process will only terminate after the pending I/O or kernel lock completes. If the underlying resource is permanently dead (such as a hung NFS server), you must unmount the filesystem lazily (umount -l), reset the device controller via sysfs, or reboot the host.
What is the difference between %iowait and D-state processes?
%iowait is a CPU state metric indicating the percentage of time a CPU was idle while at least one I/O request was in flight for that core. In contrast, D-state is a process state metric. While disk I/O bottlenecks typically cause both high D-state counts and elevated %iowait, processes waiting on kernel mutex locks, semaphore deadlocks, or network timeouts will enter D-state without triggering %iowait, displaying 100% CPU idle alongside high load average.
How can I permanently prevent D-state writeback freezes on Linux?
Tune the kernel virtual memory writeback thresholds in /etc/sysctl.d/99-io-dstate-tuning.conf. By default, Linux allows up to 20% of system RAM to fill with dirty pages before throttling writes. On large RAM systems, lower vm.dirty_background_ratio to 5% and vm.dirty_ratio to 10%, and set vm.dirty_expire_centisecs to 1500 (15 seconds). This forces smooth, continuous background flushing to storage, eliminating massive I/O sync stalls.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).