Operating a mission-critical relational database on Linux VPS infrastructure demands an architecture that survives sudden hypervisor panics, kernel out-of-memory kills, and network partitions without data corruption or manual failover delays. Traditional PostgreSQL streaming replication provides data redundancy, but when the primary node drops offline at 03:00 AM, human intervention to promote a standby and redirect application traffic inevitably inflates Recovery Time Objective (RTO) into dozens of minutes. By coupling Patroni as an intelligent supervisor, etcd as a fault-tolerant Distributed Configuration Store (DCS), and PgBouncer for transparent connection pooling and endpoint routing, systems engineers can deploy a production-ready, self-healing database cluster on CpanelFree staging nodes and enterprise cloud environments.
What is PostgreSQL High Availability with Patroni, etcd, and PgBouncer?
Direct Answer: PostgreSQL high availability with Patroni, etcd, and PgBouncer delivers automated failover, distributed consensus, and connection management across Linux VPS nodes. etcd provides a resilient distributed configuration store (DCS), Patroni continuously monitors node health and orchestrates Raft-driven leader election, while PgBouncer pools connections and routes client traffic seamlessly to prevent application connection storms during automated failover transitions.
In modern Linux infrastructure environments, achieving authentic High Availability (HA) requires solving three independent distributed systems challenges simultaneously: state consensus, node orchestration, and client connection virtualization. If any of these layers is misconfigured, the cluster risks either catastrophic split-brain conditions (where two nodes accept simultaneous writes) or cascading connection exhaustion when thousands of client sockets overwhelm the newly promoted primary.
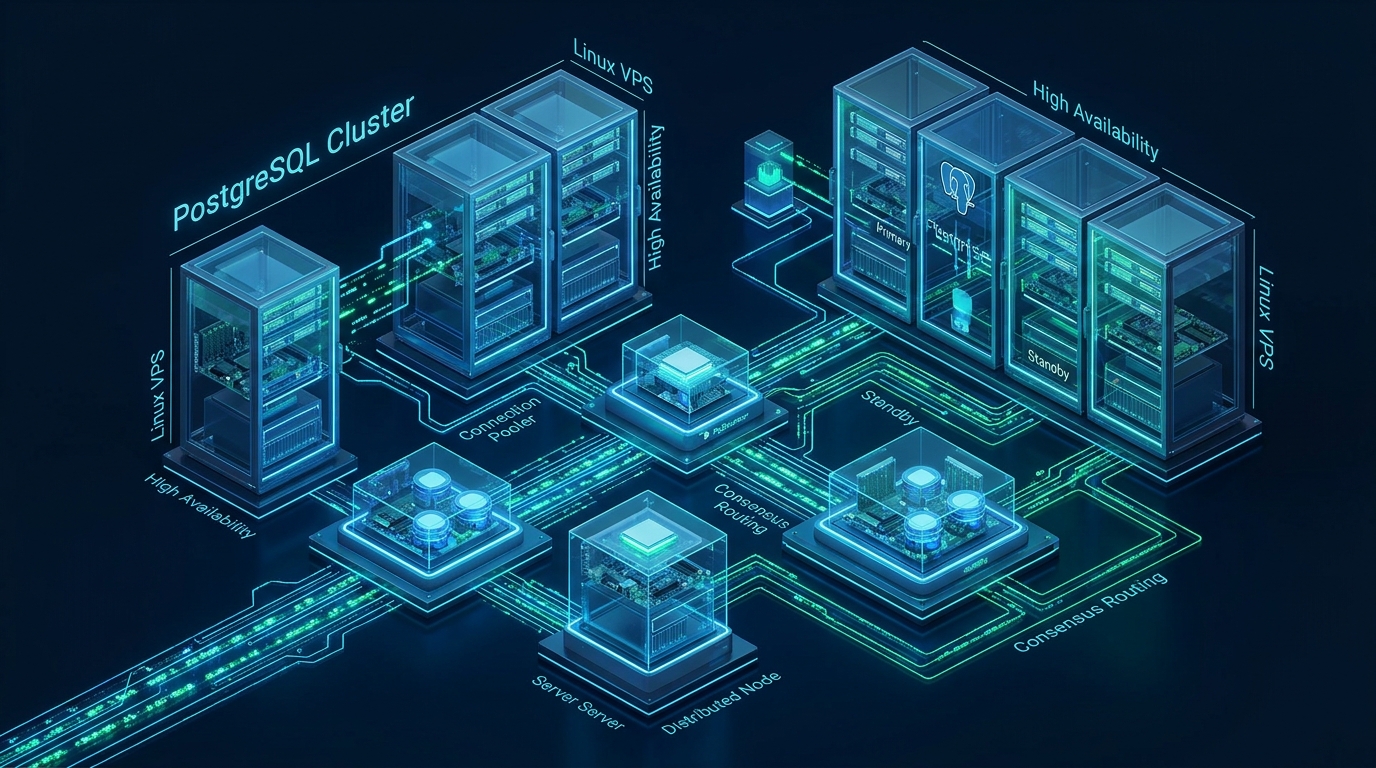
The standard reference architecture consists of three virtual private servers (nodes pg-node01, pg-node02, and pg-node03), each hosting an instance of etcd, a patroni daemon managing a local PostgreSQL 16+ engine, and a co-located or fronted pgbouncer service.
High-Availability Architectural Matrix: Manual vs. Patroni Cluster
Before evaluating the step-by-step implementation, review the fundamental operational divergence between legacy primary-standby configurations and a modern Patroni-orchestrated consensus cluster:
| Architecture Metric / Capability | Standby Streaming (Manual) | Patroni + etcd + PgBouncer (HA Cluster) |
|---|---|---|
| Failover RTO (Recovery Time Objective) | 10–45 minutes (Manual sysadmin intervention) | < 10 seconds (Automated consensus election) |
| Split-Brain Protection | Vulnerable without manual fencing/STONITH | Guaranteed via etcd Raft quorum lease TTL |
| Connection Handling Under Load | Direct backend forks (~10MB RAM per client) | PgBouncer transaction pooling (>10,000 clients) |
| Client Routing / Service Discovery | Manual DNS update or IP takeover lag | Health endpoint dynamic routing via Patroni REST API |
| Replica Resynchronization | Complex manual pg_rewind / pg_basebackup | Automated pg_rewind self-healing recovery |
| Cluster Configuration Drift | High (individual postgresql.conf per server) | Synchronized cluster-wide DCS configuration |
Step 1: Linux Kernel and OS Tuning for PostgreSQL VPS Instances
High-concurrency PostgreSQL clusters running on Linux virtual machines require dedicated kernel memory management parameters. PostgreSQL relies heavily on the operating system page cache alongside its internal shared_buffers. Furthermore, aggressive virtual memory overcommitting or excessive dirty page accumulation can trigger kernel latency spikes or catastrophic Out-Of-Memory (OOM) kills during high write throughput.
Deploy the following configuration file across all cluster nodes at /etc/sysctl.d/99-postgresql-ha.conf:
# /etc/sysctl.d/99-postgresql-ha.conf
# Linux Kernel Optimization for PostgreSQL HA, etcd, and PgBouncer

# Disable memory overcommit to prevent unpredictable OOM kills of the primary
vm.overcommit_memory = 2
vm.overcommit_ratio = 80

# Keep page cache flushing predictable and continuous rather than bursty
vm.dirty_background_ratio = 5
vm.dirty_ratio = 10

# Minimize swapping aggressiveness while retaining basic swap emergency cushion
vm.swappiness = 1

# Prevent memory fragmentation on high memory VPS instances
vm.zone_reclaim_mode = 0

# Network stack tuning for high-frequency consensus heartbeats and connection pools
net.core.somaxconn = 4096
net.ipv4.tcp_max_syn_backlog = 8192
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# Increase socket buffer sizes for heavy replication streams
net.core.rmem_default = 262144
net.core.wmem_default = 262144
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216

# File descriptor ceiling for busy database and pooling instances
fs.file-max = 2097152
Apply the tuned parameters immediately across all nodes without rebooting:
sudo sysctl --systemArchitecture Note on OOM Defense: Setting
vm.overcommit_memory = 2ensures the Linux kernel will strictly refuse memory allocations that exceed(RAM * vm.overcommit_ratio / 100) + Swap. This completely eliminates the risk of the Linux OOM-killer arbitrarily sendingSIGKILLto PostgreSQL backend processes, which would trigger immediate crash recovery on the primary.
Step 2: Provisioning the 3-Node etcd Consensus Cluster
Patroni requires a Distributed Configuration Store (DCS) to maintain leader leases and cluster topology state. etcd utilizes the Raft consensus algorithm, meaning a minimum of three nodes is required to tolerate the failure of one node while preserving quorum ((N/2) + 1 = 2 votes). Running etcd on only two nodes provides zero fault tolerance, as the failure of either node drops the quorum below the necessary majority.
Install etcd on all three nodes (10.0.0.11, 10.0.0.12, 10.0.0.13). Here is the complete production configuration for node 1 at /etc/etcd/etcd.yml:
# /etc/etcd/etcd.yml (Node 1: pg-node01)
name: 'pg-node01'
data-dir: '/var/lib/etcd/pg-cluster.etcd'
listen-peer-urls: 'http://10.0.0.11:2380'
listen-client-urls: 'http://10.0.0.11:2379,http://127.0.0.1:2379'
initial-advertise-peer-urls: 'http://10.0.0.11:2380'
advertise-client-urls: 'http://10.0.0.11:2379'

# Raft consensus peer cluster discovery
initial-cluster: 'pg-node01=http://10.0.0.11:2380,pg-node02=http://10.0.0.12:2380,pg-node03=http://10.0.0.13:2380'
initial-cluster-token: 'etcd-pg-ha-token'
initial-cluster-state: 'new'

# Heartbeat and election timeouts (tuned for stable Linux VPS networking)
heartbeat-interval: 250
election-timeout: 1250
auto-compaction-retention: '1'
snapshot-count: 10000
max-request-bytes: 1572864
quota-backend-bytes: 8589934592
Enable and start the etcd service across all nodes:
sudo systemctl daemon-reload
sudo systemctl enable --now etcd
etcdctl --endpoints=http://127.0.0.1:2379 endpoint health
etcdctl --endpoints=http://127.0.0.1:2379 member list -w table
Consensus Quorum Warning: Never deploy an even number of etcd consensus nodes. A 4-node cluster requires 3 nodes for quorum; if two nodes partition, the entire cluster halts writes. A 3-node cluster also requires 2 nodes for quorum, meaning 3 nodes and 4 nodes provide the exact same fault tolerance (1 node failure), but 4 nodes introduce an additional failure surface.
Step 3: Deploying and Configuring Patroni
Patroni acts as a customized supervisor that wraps PostgreSQL. It registers with etcd, acquires a leader lease lock with a Time-To-Live (TTL), and bootstraps the PostgreSQL database engine automatically. Standby nodes query etcd, identify the current primary, and configure native streaming replication via pg_basebackup without manual intervention.
Install Patroni with python etcd3 support:
sudo apt-get update && sudo apt-get install -y postgresql-16 postgresql-contrib patroni python3-etcd3Place the following production configuration at /etc/patroni/patroni.yml on pg-node01 (adjusting node IP addresses accordingly for pg-node02 and pg-node03):
# /etc/patroni/patroni.yml
scope: postgres-ha-cluster
namespace: /service
name: pg-node01

# Patroni REST API for health checks and orchestrator commands
restapi:
  listen: 10.0.0.11:8008
  connect_address: 10.0.0.11:8008

# Distributed Configuration Store connection
etcd3:
  hosts:
    - 10.0.0.11:2379
    - 10.0.0.12:2379
    - 10.0.0.13:2379

bootstrap:
  dcs:
    ttl: 30
    loop_wait: 10
    retry_timeout: 10
    maximum_lag_on_failover: 1048576
    synchronous_mode: false
    postgresql:
      use_pg_rewind: true
      use_slots: true
      parameters:
        shared_buffers: 4GB
        work_mem: 32MB
        maintenance_work_mem: 512MB
        effective_cache_size: 12GB
        wal_level: replica
        max_wal_size: 16GB
        min_wal_size: 2GB
        checkpoint_completion_target: 0.9
        checkpoint_timeout: 15min
        archive_mode: "on"
        archive_command: "bin/true"
        wal_keep_size: 2048MB
        hot_standby: "on"
        track_io_timing: "on"
        max_connections: 300

  initdb:
    - encoding: UTF8
    - data-checksums

  pg_hba:
    - host replication replicator 10.0.0.0/24 md5
    - host all all 10.0.0.0/24 md5
    - host all all 127.0.0.1/32 md5

postgresql:
  listen: 10.0.0.11:5432,127.0.0.1:5432
  connect_address: 10.0.0.11:5432
  data_dir: /var/lib/postgresql/16/patroni
  bin_dir: /usr/lib/postgresql/16/bin
  pgpass: /var/lib/postgresql/.pgpass
  authentication:
    replication:
      username: replicator
      password: SuperSecretReplicationPassword2026
    superuser:
      username: postgres
      password: SuperSecretPostgresAdminPassword2026

tags:
  nofailover: false
  noloadbalance: false
  clonefrom: false
  nosync: false
Create the systemd service unit to supervise Patroni at /etc/systemd/system/patroni.service:
# /etc/systemd/system/patroni.service
[Unit]
Description=Patroni PostgreSQL High Availability Orchestrator
After=network.target etcd.service
Requires=etcd.service

[Service]
Type=simple
User=postgres
Group=postgres
ExecStart=/usr/bin/patroni /etc/patroni/patroni.yml
ExecReload=/bin/kill -s HUP $MAINPID
KillMode=process
TimeoutSec=30
Restart=on-failure
RestartSec=5
LimitNOFILE=65536

[Install]
WantedBy=multi-user.target
Before launching Patroni, stop and disable the standard PostgreSQL systemd service. Patroni must maintain exclusive control over spawning and terminating the PostgreSQL daemon:
sudo systemctl stop postgresql
sudo systemctl disable postgresql
sudo systemctl daemon-reload
sudo systemctl enable --now patroni
Verify cluster status from any node using the patronictl CLI:
patronictl -c /etc/patroni/patroni.yml listAutomated Self-Healing via pg_rewind: Note the parameter
use_pg_rewind: true. When an old primary rejoins after a failover, its write-ahead log (WAL) might have diverged from the newly elected leader. Rather than forcing a costly and bandwidth-heavy fullpg_basebackup, Patroni executespg_rewindto identify the divergent point, rewind the uncommitted blocks, and switch into a streaming standby in seconds.
Step 4: PgBouncer Integration and Connection Virtualization
PostgreSQL processes connections using a traditional process-fork model. Each client socket consumes roughly 5MB to 10MB of RAM and incurs kernel context-switching overhead. Attempting to support thousands of simultaneous web application connections directly against PostgreSQL degrades throughput exponentially. Deploying PgBouncer in transaction pooling mode allows tens of thousands of client threads to share a lean, highly optimized pool of 30 to 50 active PostgreSQL server connections.
Deploy PgBouncer on each node (or on a dedicated load balancing tier) with the following production configuration at /etc/pgbouncer/pgbouncer.ini:
# /etc/pgbouncer/pgbouncer.ini
[databases]
# Dynamic routing target updated via local Patroni REST API or HAProxy
app_production = host=127.0.0.1 port=5432 dbname=app_production auth_user=postgres

[pgbouncer]
logfile = /var/log/postgresql/pgbouncer.log
pidfile = /var/run/postgresql/pgbouncer.pid
listen_addr = 0.0.0.0
listen_port = 6432
auth_type = scram-sha-256
auth_file = /etc/pgbouncer/userlist.txt
admin_users = postgres,sysadmin
stats_users = monitoring

# Connection Pool Architecture
pool_mode = transaction
max_client_conn = 10000
default_pool_size = 40
min_pool_size = 10
reserve_pool_size = 10
reserve_pool_timeout = 5
max_db_connections = 100

# Client and Server Connection Health
server_reset_query = DISCARD ALL
server_check_delay = 10
server_check_query = SELECT 1
server_lifetime = 3600
server_idle_timeout = 600
client_idle_timeout = 0
query_timeout = 120

# Socket buffer optimizations
so_reuseport = 1
tcp_keepalive = 1
tcp_keepidle = 30
tcp_keepintvl = 10
tcp_keepcnt = 3
Generate the authentication file /etc/pgbouncer/userlist.txt using SCRAM-SHA-256 password hashes extracted directly from PostgreSQL:
# /etc/pgbouncer/userlist.txt
"app_user" "SCRAM-SHA-256$4096:5a9G...==:7bF2...=="
"postgres" "SCRAM-SHA-256$4096:2xM9...==:8cV1...=="
Enable and start PgBouncer:
sudo systemctl enable --now pgbouncer
psql -p 6432 -U postgres -d pgbouncer -c "SHOW POOLS;"
Step 5: Client Traffic Steering via Patroni REST Endpoints
To steer client write queries strictly to the active leader and read queries to standbys, modern load balancers (such as HAProxy, Keepalived, or Envoy) leverage Patroni’s embedded HTTP REST service (port 8008). Patroni responds with specific HTTP status codes based on the node’s cluster role:
GET http://<node-ip>:8008/primaryreturns HTTP 200 OK only if the node is currently the active cluster leader holding the etcd lease. If the node is a standby, it returns HTTP 503 Service Unavailable.GET http://<node-ip>:8008/replicareturns HTTP 200 OK if the node is an active, streaming read-only replica.
Here is an example HAProxy backend configuration directing writes to the active Patroni leader with instantaneous failover detection:
# /etc/haproxy/haproxy.cfg
frontend pg_cluster_write_front
    bind *:5000
    mode tcp
    option tcplog
    default_backend pg_cluster_write_back

backend pg_cluster_write_back
    mode tcp
    option httpchk GET /primary
    http-check expect status 200
    default-server inter 2s fall 2 rise 2 on-marked-down shutdown-sessions
    server pg-node01 10.0.0.11:6432 maxconn 5000 check port 8008
    server pg-node02 10.0.0.12:6432 maxconn 5000 check port 8008
    server pg-node03 10.0.0.13:6432 maxconn 5000 check port 8008
Production Failover Verification: You can simulate a sudden primary loss by executing
sudo systemctl stop patronionpg-node01. Within 10 seconds, the etcd lease expires,pg-node02orpg-node03promotes itself, HAProxy detects the new HTTP 200 response on port 8008, and all pooled application queries resume on the new master without a single connection dropped at the application layer.
Production Hosting Considerations
While testing multi-node PostgreSQL HA architectures on staging environments like CpanelFree is ideal for configuration validation, production database workloads demand deterministic storage latency. PostgreSQL write-ahead logging (WAL) requires fsync operations that are fundamentally constrained by disk I/O performance.
For mission-critical production database clusters requiring guaranteed IOPS without shared-tenant performance jitter, host your infrastructure on MeraHost Enterprise Cloud. MeraHost provides enterprise-grade dedicated NVMe storage tiers, unthrottled CPU cores, and an industry-leading Same Renewal Price guarantee with zero price hikes since 2012.
Frequently Asked Questions
What happens when the Patroni leader node loses connectivity to etcd?
If the current primary node experiences a network partition and cannot renew its leader lease key in etcd before the lease TTL expires (typically 30 seconds), Patroni initiates a graceful self-demotion. It immediately terminates write access and demotes the local PostgreSQL engine into a read-only state. This strict lease renewal enforcement guarantees split-brain immunity even under severe network isolation.
Why is PgBouncer transaction pooling preferred over session pooling in HA architectures?
Session pooling holds an open server connection for the entire duration of a client connection, meaning 1,000 idle application threads require 1,000 backend PostgreSQL connections. In contrast, transaction pooling releases the backend PostgreSQL connection back to the shared pool immediately upon transaction completion (COMMIT or ROLLBACK). This allows thousands of web workers to multiplex across as few as 20–50 PostgreSQL connections, maximizing throughput and caching efficiency.
Can I run Patroni and etcd on a 2-node cluster without a third node?
No. A 2-node etcd cluster cannot achieve a quorum majority if either node becomes unreachable (quorum formula: (2/2) + 1 = 2 votes needed). If one node fails, the surviving node has only 1 vote and will refuse all writes to prevent split-brain. You must deploy at least 3 nodes (or 2 database nodes plus a lightweight third etcd arbiter/witness node) to maintain automated high availability.
How does Patroni handle replication lag during automated failover?
Patroni tracks the Log Sequence Number (LSN) of each standby node within the DCS. When electing a new leader, the cluster enforces the maximum_lag_on_failover threshold (configured in bytes). Standbys whose replication lag exceeds this threshold are automatically disqualified from promotion, ensuring that only the replica with the most up-to-date WAL state is promoted to prevent data loss.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).