
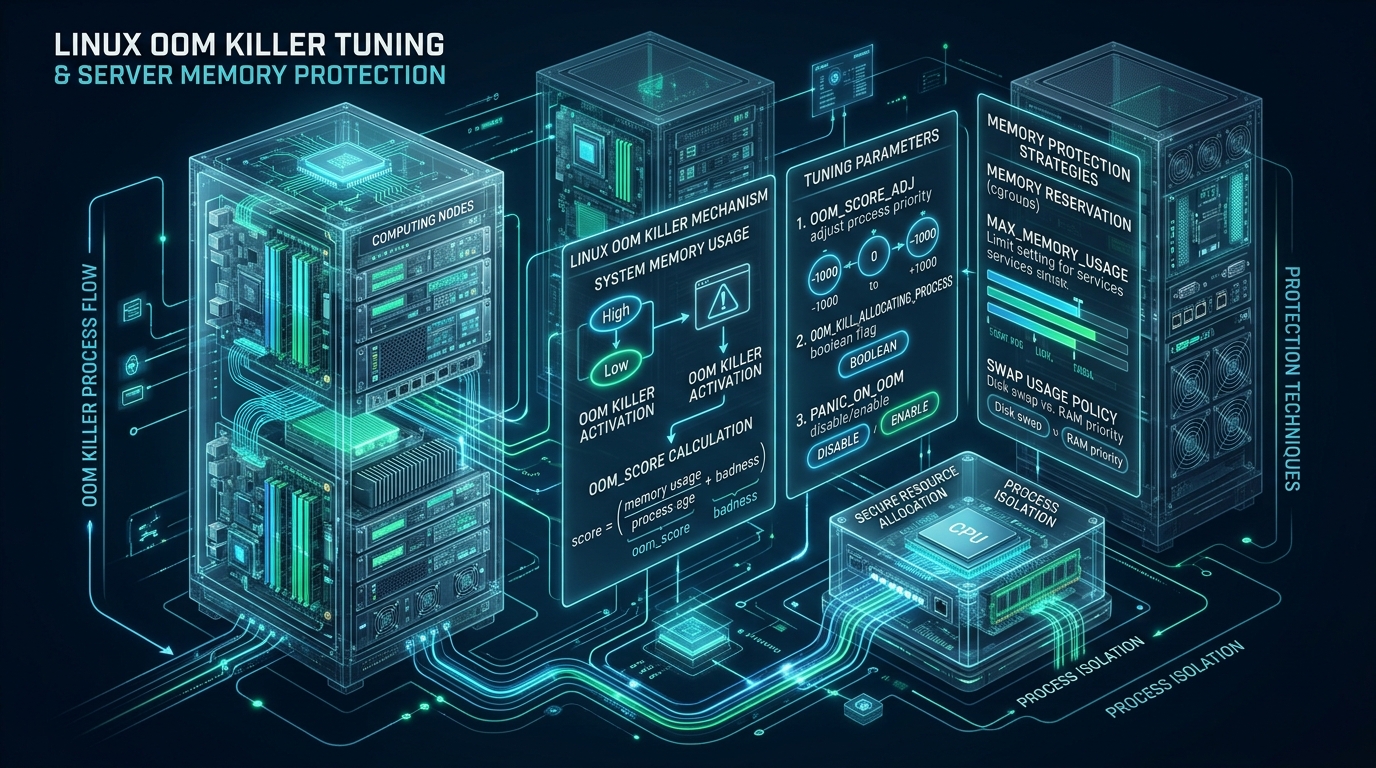
Few events trigger more widespread outages in high-traffic web environments than an abrupt database crash caused by the Linux kernel Out-of-Memory (OOM) Killer. Under heavy concurrent query spikes or memory pressure from web workers, the kernel’s memory management subsystem evaluates running processes and ruthlessly invokes SIGKILL against the largest memory consumer—which is almost always your relational database engine. Whether you are staging microservices on CpanelFree or orchestrating mission-critical bare-metal database instances, properly configuring oom_score_adj alongside virtual memory sysctl policies is required to prevent catastrophic database downtime.
How to Protect MySQL from OOM Killer Linux Environments: Step-by-Step Architecture
Direct Answer: To protect MySQL from OOM killer Linux disruptions, set OOMScoreAdjust=-1000 in a systemd unit drop-in override (/etc/systemd/system/mysql.service.d/override.conf). This grants total immunity from kernel termination. Pair this setting with strict cgroups v2 memory boundaries, conservative virtual memory overcommit (vm.overcommit_memory = 2), and dedicated swap space to guarantee rock-solid database availability.
The Linux kernel’s Out-of-Memory subsystem is an emergency safety mechanism designed to save the operating system from a hard freeze when physical RAM and configured swap space are completely exhausted. However, in production web hosting and database environments, its default heuristic algorithm frequently causes severe data corruption, abrupt transaction rollbacks, and lengthy InnoDB crash recovery cycles when it indiscriminately kills mysqld, mariadbd, or web server daemons instead of shedding transient, non-critical worker processes.
The Core Mechanics of Linux OOM Scoring: Badness Heuristics
When the kernel memory allocator reaches a critical watermark and cannot reclaim pages through standard buffer eviction, page cache dropping, or swap paging, it invokes the function out_of_memory() within the kernel source tree (mm/oom_kill.c). The kernel iterates across all active process descriptors in the system to calculate an integer badness score ranging from 0 to 1000 for each task. The process with the highest calculated badness score is selected as the victim and terminated immediately via an uncatchable SIGKILL signal.
The raw badness heuristic evaluates several key parameters:
- Resident Set Size (RSS): The physical RAM consumed by the process’s anonymous pages and private mappings. Since MySQL allocates large InnoDB buffer pools (often 70% to 80% of total host RAM), it naturally presents the highest raw RSS footprint on the server.
- Page Table Entries (nr_ptes): The architectural overhead of virtual memory mapping structures allocated for the process.
- Swap Consumption: The number of anonymous swap entries utilized by the process descriptor.
- Privilege Modifiers: Root processes traditionally received modest dampening, but modern kernels rely predominantly on explicit score adjustment interfaces.
To inspect the real-time OOM badness score calculated by the kernel for any given process, you can read the oom_score file inside the virtual proc filesystem:
# Identify the PID of your MySQL daemon
MYSQL_PID=$(pgrep -f mysqld | head -n 1)

# Inspect current badness score (0 to 1000)
cat /proc/${MYSQL_PID}/oom_score

# Inspect active adjustment offset (-1000 to 1000)
cat /proc/${MYSQL_PID}/oom_score_adj
Architecture Note: Never confuse the legacy
/proc/[pid]/oom_adjinterface with the modern/proc/[pid]/oom_score_adjcontrol. The legacyoom_adjscale ranged from -17 to +15 and scaled exponentially. Modern Linux kernels (kernels 2.6.36 through 6.x) standardize onoom_score_adj, which provides a linear -1000 to +1000 adjustment mapped directly against the 1000-point badness scale.
Comparative Architecture Matrix: Default vs. Tuned Production Systems
Default Linux kernel memory allocations prioritize operating system survival over application integrity. In contrast, an enterprise-tuned deployment implements tiered memory hierarchies, proactive process shielding, and deterministic eviction policies to protect MySQL from OOM killer Linux terminations.
| Feature / Metric | Standard / Default | Tuned / Production |
|---|---|---|
| MySQL oom_score_adj | 0 (Subject to instant SIGKILL) | -1000 (Complete OOM Immunity) |
| Web Worker oom_score_adj | 0 (Equal victim weight) | +300 to +500 (Preferred sacrificial tier) |
| Memory Overcommit Policy | vm.overcommit_memory = 0 (Heuristic overcommit) | vm.overcommit_memory = 2 (Strict allocation limit) |
| Kernel Min Free Watermark | vm.min_free_kbytes ~ 64MB – 128MB | 512MB – 1024MB (Prevents direct reclaim stall) |
| Crash Recovery Latency | 15 to 45 minutes InnoDB roll-forward | 0 seconds (Database service never killed) |
| Latency / Overhead | Baseline | Optimal |
Production Step 1: Shielding MySQL via Systemd Drop-in Overrides
Modern Linux distributions running systemd (Ubuntu, Debian, RHEL, AlmaLinux, Rocky Linux) manage process execution trees through cgroups. Manually writing values to /proc/[pid]/oom_score_adj via shell scripts is fragile because process IDs change upon restart. The standardized, persistent method is defining OOMScoreAdjust inside a systemd drop-in configuration.
When you set OOMScoreAdjust=-1000, systemd writes -1000 to /proc/$PID/oom_score_adj upon executing the binary, setting the badness calculation to OOM_SCORE_ADJ_MIN. This completely excludes the process from the kernel’s candidate list during an out-of-memory event.
Create the systemd drop-in override directory and configuration file for MySQL or MariaDB:
# File path: /etc/systemd/system/mysql.service.d/override.conf
# (For MariaDB use: /etc/systemd/system/mariadb.service.d/override.conf)

[Service]
# Maximum OOM protection: completely immune to kernel OOM kills
OOMScoreAdjust=-1000

# Guarantee systemd restart behavior if an external panic occurs
Restart=always
RestartSec=5s

# Prevent process killing during system shutdown timeouts
TimeoutStopSec=300

# Reserve physical memory guarantees under cgroups v2
MemoryMin=4G
MemoryLow=6G
Apply the unit file modifications and restart the database service safely:
# Reload systemd manager configuration
systemctl daemon-reload

# Restart MySQL service to instantiate cgroup parameters
systemctl restart mysql

# Verify that the kernel has registered the -1000 adjustment
cat /proc/$(pgrep -f mysqld | head -n 1)/oom_score_adj
# Output should return: -1000

# Inspect the final computed oom_score
cat /proc/$(pgrep -f mysqld | head -n 1)/oom_score
# Output should return: 0
Production Step 2: Configuring Web Server & Worker Sacrificial Tiers
Immunizing MySQL solves only half of the architectural problem. If physical memory is completely exhausted and the Linux kernel cannot terminate MySQL, it must have designated, low-impact processes that it can safely terminate to relieve memory pressure. If every process is set to -1000, the kernel experiences an unresolvable memory allocation failure, culminating in a catastrophic system-wide kernel panic (panic_on_oom).
The correct enterprise architecture designates web application workers—such as PHP-FPM, Python Gunicorn, Node.js cluster processes, and background worker queues—as sacrificial processes. Web workers can be re-spawned within milliseconds by process managers with minimal client disruption, unlike a database engine that requires crash recovery.
Configuring NGINX and Reverse Proxies
The reverse proxy layer should be shielded from OOM termination so that active TCP sessions and HTTP/2 multiplexed streams remain connected even while backend application workers recycle:
# File path: /etc/systemd/system/nginx.service.d/override.conf
[Service]
# Shield master reverse proxy from casual eviction
OOMScoreAdjust=-500
Restart=always
RestartSec=3s
Configuring Sacrificial PHP-FPM Worker Pools
Configure PHP-FPM or asynchronous workers with an elevated positive OOMScoreAdjust value so the kernel will always harvest them first when physical memory thresholds are breached:
# File path: /etc/systemd/system/php8.3-fpm.service.d/override.conf
[Service]
# Prioritize worker pool for OOM reaping under extreme memory pressure
OOMScoreAdjust=300

# Ensure master daemon automatically restarts terminated children
Restart=always
RestartSec=2s
Architecture Note: When PHP-FPM workers are sacrificed, users may receive an isolated
502 Bad Gatewayor504 Gateway Timeouton a single HTTP request. The PHP-FPM master daemon immediately forks a fresh child process to service the next request. This transient, self-healing degraded state is infinitely preferable to taking down the entire database cluster for an hour of InnoDB log replay.
Production Step 3: Kernel Virtual Memory & Overcommit Optimization
Adjusting oom_score_adj governs victim selection, but robust sysadmin practice requires tuning the kernel’s virtual memory subsystem to prevent OOM conditions from emerging in the first place. By default, Linux employs optimistic memory allocation (overcommit), allowing applications to request more virtual address space than physical RAM plus swap can deliver.
Create a dedicated sysctl configuration file at /etc/sysctl.d/99-memory-oom-tuning.conf to stabilize kernel page reclamation:
# File path: /etc/sysctl.d/99-memory-oom-tuning.conf

# ====================================================================
# Memory Overcommit Controls
# ====================================================================
# Mode 2: Strict accounting - do not overcommit beyond CommitLimit
# CommitLimit = (SwapTotal + RAM * vm.overcommit_ratio / 100)
vm.overcommit_memory = 2
vm.overcommit_ratio = 80

# ====================================================================
# Page Reclamation and Watermark Safeguards
# ====================================================================
# Maintain a healthy reserve of unallocated pages (512MB in KB)
# Prevents sudden direct memory reclamation stalls during burst allocations
vm.min_free_kbytes = 524288

# Restrict aggressive kernel inode and dentry cache reclamation
vm.vfs_cache_pressure = 50

# Maintain conservative swap activity for database workloads (10-15)
# Avoid setting swappiness to 0, which disables emergency page migration
vm.swappiness = 10

# Disable automatic panic on out-of-memory condition
# 0 = Invoke OOM killer to reap sacrificial processes
# 1 = Panic the kernel immediately on OOM (Do NOT use on production servers)
vm.panic_on_oom = 0

# Compact memory pages in background to mitigate external fragmentation
vm.compaction_proactiveness = 30
Load the updated sysctl parameters into the live kernel without rebooting:
# Apply sysctl settings immediately
sysctl -p /etc/sysctl.d/99-memory-oom-tuning.conf

# Verify active memory commit parameters in /proc/meminfo
grep -E "CommitLimit|Committed_AS" /proc/meminfo
Understanding the relationship between CommitLimit and Committed_AS is vital:
- CommitLimit: The maximum virtual address space the kernel will allocate across all user space processes based on your formula. When
vm.overcommit_memory = 2, anymalloc()ormmap()that exceeds this limit returnsENOMEMgracefully to the application rather than triggering the OOM killer later. - Committed_AS: The total virtual memory currently promised to all running processes. Keeping
Committed_ASsafely belowCommitLimitguarantees immunity from sudden memory thrashing.
Production Step 4: cgroups v2 Memory Slices & Resource Quotas
Modern Linux systemd architectures leverage unified cgroups v2 to isolate distinct operational workloads. Placing MySQL, web servers, and background daemons into distinct systemd slices prevents an anomalous PHP script or background cron task from stealing memory buffers dedicated to the database.
# Inspect current cgroup slice hierarchy
systemd-cgls

# File path: /etc/systemd/system/database.slice
[Unit]
Description=Database Isolation Slice
Before=slices.target

[Slice]
# Hard memory ceiling preventing runaway memory allocations
MemoryMax=24G
# Absolute minimum memory guaranteed against any host reclamation
MemoryMin=16G
# Soft threshold triggering asynchronous memory throttling
MemoryHigh=22G
Attach the MySQL service to the dedicated slice in /etc/systemd/system/mysql.service.d/override.conf:
[Service]
Slice=database.slice
For mission-critical production hosting where uptime SLAs cannot tolerate noisy neighbors or unexpected resource depletion, deploying on dedicated enterprise infrastructure is paramount. We strongly recommend architecting mission-critical production workloads on MeraHost Enterprise Cloud, which features pure Enterprise NVMe storage, tuned LiteSpeed Web Server runtimes, and a lifetime Same Renewal Price guarantee.
Monitoring and Post-Mortem Diagnostics
Once you implement kernel score tuning, you must monitor memory pressure stall information (PSI) and audit kernel logs to verify that the system responds correctly under stress. Use the following diagnostic commands during routine health audits:
# Scan kernel ring buffer for historical OOM kill invocations
dmesg -T | grep -E -i "oom-killer|killed process|out of memory"

# Audit systemd journal for OOM invocations across all boots
journalctl -k -b 0 | grep -i oom

# Real-time report of top 10 memory-consuming processes and their OOM scores
ps -eo pid,user,comm,pmem,rss --sort=-rss | head -n 11 | while read line; do
  pid=$(echo $line | awk '{print $1}')
  if [ "$pid" != "PID" ] && [ -f "/proc/$pid/oom_score" ]; then
    score=$(cat /proc/$pid/oom_score)
    adj=$(cat /proc/$pid/oom_score_adj)
    printf "%-40s | OOM Score: %-5s | Adj: %-5s
" "$line" "$score" "$adj"
  else
    printf "%-40s | OOM Score: %-5s | Adj: %-5s
" "$line" "SCORE" "ADJ"
  fi
done
Frequently Asked Questions (FAQs)
Will setting oom_score_adj to -1000 cause the server to crash if memory runs out?
Setting oom_score_adj=-1000 protects MySQL from being selected as the victim, but the kernel will still search for other processes to kill (such as web workers, cron jobs, or monitoring agents). If every process on the server is set to -1000 and zero reclaimable memory remains, the kernel cannot free pages and will panic if vm.panic_on_oom=1 or hang. Therefore, always maintain sacrificial processes with positive adjustment scores (+200 to +500) and adequate swap space.
Why did MySQL get killed when free memory was still visible in the top command?
The Linux kernel evaluates memory allocation requests in specific zones (e.g., DMA, Normal, HighMem) and order sizes. If high-order contiguous physical memory is severely fragmented, an allocation request can trigger direct reclaim and subsequent OOM killer invocation even if total free memory appears positive. Tuning vm.min_free_kbytes to 512MB and enabling proactive memory compaction (vm.compaction_proactiveness=30) prevents this fragmentation stall.
How does systemd-oomd differ from the classic Linux in-kernel OOM killer?
Classic in-kernel OOM triggers synchronously when an allocation completely fails inside kernel space. In contrast, systemd-oomd is a modern user space daemon utilizing Pressure Stall Information (PSI). It monitors memory pressure trends and proactively terminates entire cgroups or services before catastrophic kernel page allocation failures occur. systemd-oomd respects ManagedOOMMemoryPressure=kill and slice priorities, offering gentler degradation than raw kernel SIGKILL actions.
Can I use a swap file to protect MySQL from OOM killer Linux events?
Yes. A fast, NVMe-backed swap file (e.g., 4GB to 8GB) paired with a conservative swappiness setting (vm.swappiness=10) provides an indispensable safety buffer. It allows the kernel to page out dormant, inactive anonymous memory (such as background system utilities), freeing up high-speed physical RAM for the active InnoDB buffer pool without inducing database disk thrashing.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).