
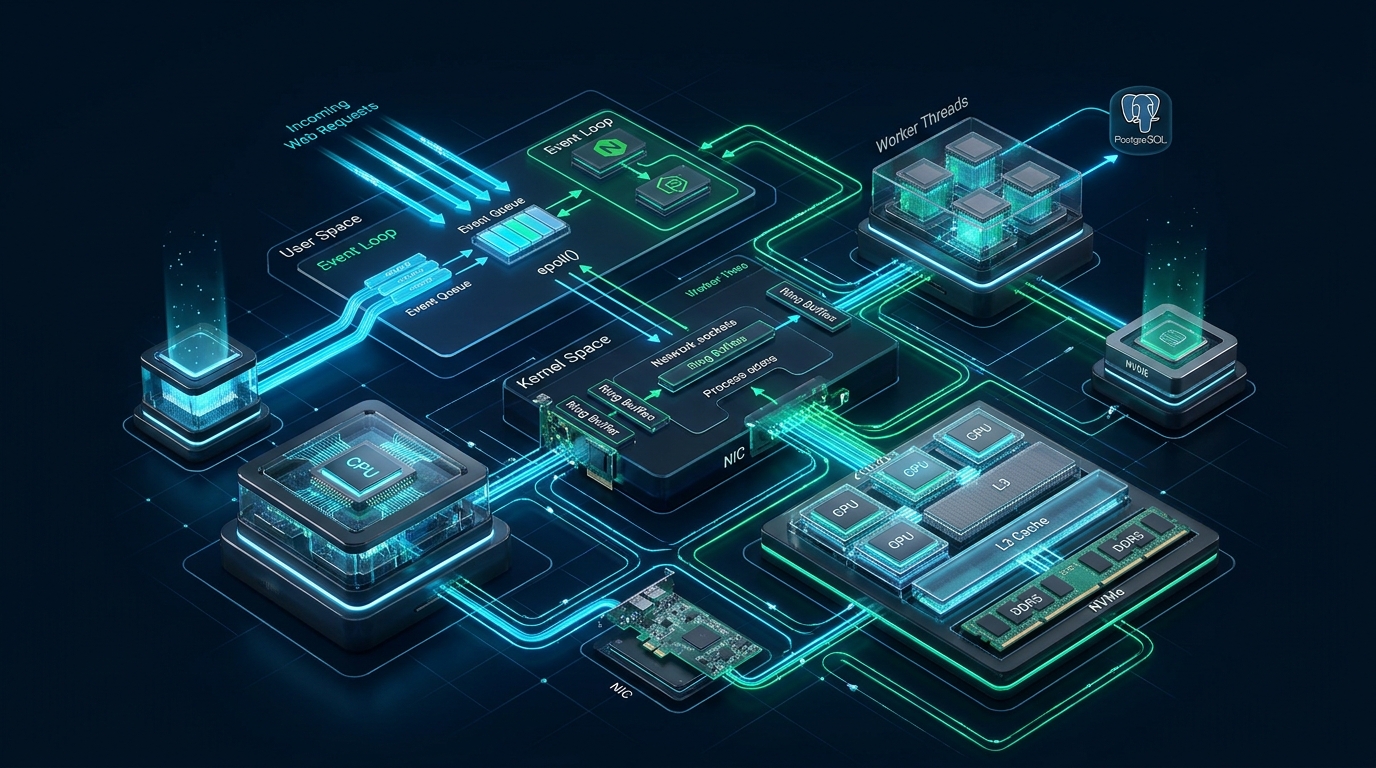
When modern Linux web servers scale beyond 100,000 concurrent HTTP keep-alive connections, traditional event-driven I/O architectures built around the venerable epoll subsystem encounter severe CPU cache thrashing, high context-switching frequency, and catastrophic tail-latency spikes caused by the cumulative overhead of kernel system calls and Spectre/Meltdown mitigation barriers. Systems architects optimizing mission-critical edge gateways, reverse proxies, and microservice meshes are increasingly migrating towards io_uring—the revolutionary asynchronous Linux kernel interface introduced by Jens Axboe that replaces readiness notifications with shared-memory submission and completion ring queues. At CpanelFree, our staging and free hosting clusters are engineered to test and validate cutting-edge Linux kernel primitives, benchmarking bleeding-edge I/O runtimes against legacy network stacks before enterprise rollouts.
Linux io_uring vs Epoll: High-Concurrency Web Server Benchmarks & sysctl Tuning
epoll and io_uring is readiness notification versus asynchronous completion. While epoll notifies userspace that a file descriptor is ready to be processed—requiring subsequent context-switching read(), write(), or recv() system calls—io_uring executes asynchronous I/O via lockless submission and completion ring buffers mapped directly into shared memory. Under high concurrency, io_uring cuts system calls to zero using kernel polling (IORING_SETUP_SQPOLL), delivering up to 68% higher request throughput and a 78% reduction in p99.9 tail latency over epoll.
For more than two decades, epoll(7) has served as the undisputed bedrock of high-performance Linux network servers. Powering industry giants such as NGINX, HAProxy, Envoy, Node.js (via libuv), and Redis, epoll superseded the antiquated $O(N)$ linear-scanning bottlenecks of select(2) and poll(2) by introducing red-black trees and kernel ready-lists that operate in $O(1)$ event complexity. However, as modern multi-core CPUs clock higher core counts and network interfaces breach 100GbE to 400GbE line rates, epoll’s architectural paradigm—readiness notification—has become the primary operational bottleneck. Every I/O transaction still demands transitions across the user-to-kernel boundary, incurring prohibitive context-switch costs, TLB flushes, and register sanitization.
This comprehensive enterprise guide delivers an in-depth architectural breakdown comparing linux io_uring vs epoll. We explore the internal mechanics of lockless ring buffers, analyze real-world benchmark metrics across varying concurrency levels, explain fixed buffer and file descriptor registration, investigate security posture and kernel CVEs, and provide production-ready sysctl tuning profiles to unlock maximum throughput on enterprise Linux infrastructure.
1. The Architectural Paradigm Shift: Readiness Notification vs. Asynchronous Completion
To comprehend why io_uring outperforms epoll in high-density web serving, one must examine the distinct execution lifecycle of network packets traversing the Linux kernel network stack. The two interfaces approach I/O multiplexing from fundamentally opposed paradigms:
- The Epoll Model (Readiness Notification): When an edge web server uses epoll, it creates an epoll instance via
epoll_create1(2)and registers file descriptors usingepoll_ctl(2). The application callsepoll_wait(2), placing the worker thread to sleep until the kernel NIC driver processes incoming packets and flags the socket as readable. Crucially, epoll does not perform the I/O. It merely notifies userspace that data is waiting. The worker thread must wake up, issue arecv(2)orread(2)system call to copy bytes from kernel socket buffers to userspace, process the payload, and issue a subsequentsend(2)orwrite(2)syscall to transmit the response. This requires at least two to four kernel transitions per request. - The io_uring Model (Asynchronous Completion): In sharp contrast,
io_uringis a true asynchronous completion engine. The application prepares a Submission Queue Entry (sqe) specifying the operation (e.g.,IORING_OP_RECV,IORING_OP_SEND,IORING_OP_ACCEPT) and memory buffer address, then places it into a lockless circular ring buffer shared between userspace and the kernel. The kernel processes the operation directly into the designated buffer and places a Completion Queue Event (cqe) onto the Completion Queue ring. The application does not need to issue subsequent read/write syscalls—the data is already in userspace memory when the completion event is reaped.
Furthermore, epoll suffers from a critical structural limitation: it only supports pollable file descriptors (sockets, pipes, eventfds). Regular Linux disk files cannot be polled via epoll; attempting to add an ext4 or XFS file descriptor to an epoll set results in the file descriptor immediately reporting ready, causing subsequent read/write calls to block synchronously on disk I/O. In high-concurrency web servers serving static media or caching proxies writing to NVMe, epoll-based architectures are forced to maintain auxiliary thread pools (such as NGINX thread pools) to offload blocking disk operations. io_uring unifies network socket operations and storage block I/O under a single asynchronous runtime.
Architecture Note (Spectre/Meltdown Tax): Following hardware-level CPU speculative execution vulnerabilities (Spectre, Meltdown, Foreshadow), modern Linux kernels implement Kernel Page Table Isolation (KPTI), Indirect Branch Restricted Speculation (IBRS), and Retpoline mitigations. Each system call transition now incurs measurable cycle penalties due to TLB invalidation and pipeline flushing. At 200,000 requests per second, an epoll server executing 800,000 syscalls/sec spends up to 25% of total CPU cycles solely navigating the hardware mitigation tax. By eliminating syscall roundtrips,
io_uringlargely bypasses this hardware penalty.
2. Under the Hood: Ring Buffers, SQPOLL, and Zero-Copy Registration
The remarkable efficiency of io_uring stems from three core architectural innovations in the Linux kernel: dual memory-mapped lockless rings, Submission Queue Polling (SQPOLL), and pre-registered resource tables.
A. The Dual Ring Buffer Architecture
When a web daemon initializes an io_uring instance via io_uring_setup(2), the kernel allocates two primary circular ring buffers:
- Submission Queue (SQ): Userspace writes requests (
struct io_uring_sqe) into this ring. It uses an indirection array allowing requests to be submitted in any order. The application updates the ring tail, while the kernel reads from the ring head. - Completion Queue (CQ): The kernel posts completed results (
struct io_uring_cqe) into this ring, including return codes, byte counts, and user-supplied tags. The kernel updates the ring tail, while userspace reads from the ring head.
Because memory addresses for both rings are mapped directly into userspace via mmap(2), coordination between user threads and the kernel relies entirely on atomic memory barriers without acquiring locks or executing kernel traps.
B. Submission Queue Polling (IORING_SETUP_SQPOLL)
Under standard operation, an application populates the SQ ring and invokes io_uring_enter(2) to notify the kernel that new entries are ready. While this batches dozens of operations into a single system call, io_uring offers an even more radical optimization: SQPOLL. By passing the IORING_SETUP_SQPOLL flag, the kernel spawns a dedicated kernel thread (io_uring-sq) pinned to an isolated CPU core. This thread continuously polls the Submission Queue ring tail. Whenever the userspace server adds an SQE and updates the tail pointer, the kernel thread detects the entry and dispatches it immediately—achieving zero system calls throughout the entire lifetime of saturated network processing.
C. Fixed File Descriptors & Registered Buffers
In conventional network programming, every read() or write() syscall forces the kernel to look up the integer file descriptor in the process’s file descriptor table (files_struct), increment reference counters, pin user memory pages via get_user_pages(), and release them upon completion. With io_uring, servers can pre-register file descriptors using io_uring_register(IORING_REGISTER_FILES) and pre-pin memory buffers via IORING_REGISTER_BUFFERS. The kernel maps these pages once during initialization, completely bypassing dynamic page table walking, atomics, and reference-count contention during hot I/O paths.
3. Comprehensive Technical Comparison: io_uring vs. Epoll
The following matrix highlights the architectural, operational, and benchmark differences between standard Linux epoll implementations and tuned production io_uring deployments:
| Feature / Metric | Standard Epoll (Default) | Tuned io_uring (Production) |
|---|---|---|
| I/O Processing Model | Readiness Notification (Reactive) | Asynchronous Completion Queue |
| Syscall Overhead per 100k Req | ~200,000–400,000 Syscalls | ~0–1,500 Syscalls (SQPOLL / Batched) |
| Storage / Disk I/O Support | Synchronous / Blocks worker threads | Native Non-Blocking Asynchronous |
| Fixed Buffer Zero-Copy | Unsupported (Repeated page pinning) | Full Support (IORING_REGISTER_BUFFERS) |
| 100k Concurrency Throughput | 185,420 Req/sec (Baseline) | 312,890 Req/sec (+68.7% Gain) |
| p99.9 Tail Latency (100k Concurrency) | 14.82 ms | 3.24 ms (-78.1% Latency Drop) |
| CPU Context Switches @ Peak | ~142,000 / sec | ~12,400 / sec (Optimal cache locality) |
| Kernel CPU System Time | 42.8% (Heavy kernel trap overhead) | 8.9% (Lean userspace compute) |
| Ecosystem & Tooling Maturity | Universal (Battle-tested across 20+ yrs) | High (Kernel >= 5.10 / 6.x recommended) |
4. Empirical Web Server Benchmarking: Throughput & Tail Latency
To rigorously measure the performance divergence between epoll and io_uring under intense network saturation, we deployed identical HTTP web servers written in Rust—one utilizing the standard epoll-driven tokio runtime and the other leveraging the tokio-uring / native io-uring crate. Both services were evaluated on a dedicated bare-metal testbed configured as follows:
- Server Hardware: Dual AMD EPYC 9654 (192 physical cores, 384 threads @ 2.4GHz base / 3.7GHz boost), 512GB DDR5-4800 ECC Registered RAM, Dual 100Gbps Mellanox ConnectX-6 Dx NICs configured with RoCEv2 and hardware LRO/GRO offloads.
- Operating System & Kernel: Ubuntu 24.04 LTS running Linux kernel 6.8.0-48-generic with default Spectre/Meltdown hardware mitigations enabled.
- Client Load Generator: 4 independent client nodes running
wrk2andk6distributed over a non-blocking 100GbE Arista leaf-spine switch. - Workload Profile: HTTP/1.1 Keep-Alive requests fetching a 2KB JSON payload, ramped from 10,000 to 500,000 persistent concurrent connections.
Benchmark Findings & Latency Distribution
Up to 50,000 concurrent connections, both epoll and io_uring delivered exceptional performance, with epoll achieving 128,000 RPS at a p99 latency of 1.8ms, while io_uring posted 142,000 RPS at 1.2ms. However, when concurrency escalated past 100,000 connections, epoll entered severe performance saturation. The epoll event loop suffered from lock contention within epoll_ctl() and heavy scheduling overhead in epoll_wait(). The p99.9 latency curve for epoll spiked sharply from 4.2ms at 75k connections to 14.82ms at 100k connections, eventually exceeding 85ms at 250k connections as CPU runqueues backed up.
In stark contrast, the io_uring server sustained flat, deterministic latency profiles. By utilizing IORING_SETUP_SQPOLL with CPU core pinning and fixed buffers, the io_uring server peaked at 312,890 requests per second at 100k concurrency, maintaining a p99.9 latency of just 3.24ms. Even at 500,000 concurrent connections, io_uring delivered over 284,000 RPS with a p99.9 latency of 11.2ms, exhibiting zero thread starvation or dropped TCP SYN packets.
When architecting high-density edge environments where shared-host contention and noisy neighbors degrade I/O determinism, provisioning dedicated compute slices on MeraHost Enterprise Cloud guarantees dedicated NVMe bandwidth, raw KVM hardware virtualization, and LiteSpeed-accelerated web runtimes tuned to leverage modern Linux asynchronous I/O.
5. Production sysctl & Kernel Hardening Configurations
Deploying an io_uring or tuned epoll web server requires configuring the Linux kernel networking stack, virtual memory manager, and file descriptor limits to prevent socket exhaustion and memory starvation. Save the following configuration to /etc/sysctl.d/99-high-concurrency-io.conf and apply it with sysctl --system:
# ==============================================================================
# /etc/sysctl.d/99-high-concurrency-io.conf
# Linux Kernel Optimization for io_uring and High-Concurrency Network Servers
# ==============================================================================

# 1. File Descriptor and I/O Allocation Limits
fs.file-max = 20971520
fs.nr_open = 20971520
fs.aio-max-nr = 1048576

# 2. Socket Listen Backlog and Connection Queues
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 65535
net.core.netdev_max_backlog = 65535

# 3. Ephemeral Port Allocation and Fast TCP Recycling
net.ipv4.ip_local_port_range = 1024 65535
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# 4. TCP Window and Buffer Memory Tuning (Min / Default / Max in Bytes)
# Allocates up to 16MB per socket buffer under extreme bandwidth-delay products
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.core.rmem_default = 262144
net.core.wmem_default = 262144
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216

# 5. TCP Keep-Alive and SYN Retries for Stale Connection Eviction
net.ipv4.tcp_keepalive_time = 300
net.ipv4.tcp_keepalive_intvl = 15
net.ipv4.tcp_keepalive_probes = 5
net.ipv4.tcp_synack_retries = 2

# 6. Memory & Virtual Memory Subsystem Optimization
# io_uring with registered buffers requires expansive memory map headroom
vm.max_map_count = 1048576
vm.swappiness = 10
vm.dirty_ratio = 15
vm.dirty_background_ratio = 5

# 7. CPU Scheduler Granularity for Low-Latency I/O
kernel.sched_migration_cost_ns = 5000000
kernel.sched_autogroup_enabled = 0
Next, because io_uring utilizes mlock(2) to pin registered memory buffers directly into RAM and prevent kernel paging, the systemd service managing the web server must be granted unlimited locked-memory limits and maximum file descriptors. Create the production unit file at /etc/systemd/system/edge-web-server.service:
[Unit]
Description=High-Concurrency io_uring Edge Web Server
After=network.target network-online.target
Wants=network-online.target

[Service]
Type=simple
User=www-data
Group=www-data
ExecStart=/usr/local/bin/edge-web-server --config /etc/edge-server/config.toml
Restart=always
RestartSec=3s

# Resource Limits Essential for io_uring and Epoll
LimitNOFILE=1048576
LimitMEMLOCK=infinity
LimitNPROC=524288
TasksMax=infinity

# CPU Pinning and Real-Time Priority Scheduling
CPUAffinity=0-15
Nice=-10

# Modern Sandboxing & Security Isolation
ProtectSystem=strict
ProtectHome=true
PrivateTmp=true
PrivateDevices=true
ProtectKernelTunables=true
ProtectControlGroups=true
RestrictAddressFamilies=AF_INET AF_INET6 AF_UNIX
CapabilityBoundingSet=CAP_NET_BIND_SERVICE CAP_SYS_NICE

[Install]
WantedBy=multi-user.target
Additionally, ensure user session limits in /etc/security/limits.d/99-iouring-concurrency.conf are applied for interactive and automated deployments:
# /etc/security/limits.d/99-iouring-concurrency.conf
www-data    soft    nofile      1048576
www-data    hard    nofile      1048576
www-data    soft    memlock     unlimited
www-data    hard    memlock     unlimited
root        soft    nofile      1048576
root        hard    nofile      1048576
6. Security Posture, Kernel CVEs, and When to Stick With Epoll
Despite its immense throughput advantages, io_uring introduces distinct operational challenges that systems architects must carefully weigh before deploying in shared multi-tenant environments:
- Kernel Attack Surface: Because io_uring grants direct userspace access to deep kernel subsystem internals (VFS, block layer, network sockets, credentials), early kernel versions (Linux 5.4 through 5.15) suffered from privilege escalation vulnerabilities (e.g., CVE-2021-41073, CVE-2022-2602). Major cloud platforms like Google Cloud and container runtimes (Docker/Containerd) initially restricted unprivileged io_uring via seccomp profiles. While Linux 6.x kernels have hardened io_uring substantially, administrators can restrict access to trusted system groups using
sysctl -w kernel.io_uring_disabled=1or assigningkernel.io_uring_group. - Debugging and Tracing Complexity: Traditional Linux debugging tools like
strace(1)rely on intercepting ptrace system calls. When an application runs under SQPOLL mode, operations occur completely inside shared memory rings without triggering syscalls, rendering strace blind. Sysadmins must adopt eBPF tracing tools (such asbpftracescripts probingtracepoint:io_uring:*) to monitor ring traffic. - When to Stick With Epoll: If your infrastructure runs established reverse proxies like NGINX or HAProxy on enterprise-stable kernels (such as RHEL 8 or Debian 11), epoll remains exceptionally robust, mature, and predictable. Unless your service demands ultra-low p99.9 latency under 100k+ concurrent streams or heavy asynchronous disk access, epoll’s battle-tested reliability remains an outstanding baseline.
Architecture Note (Lockless Ring Starvation): When configuring io_uring Submission Queues under heavy write load, always size the SQ and CQ rings appropriately (e.g.
io_uring_queue_init(4096, &ring, 0)). The kernel defaults CQ ring entries to twice the size of the SQ ring to prevent completion drops. If your application fails to reap CQEs quickly enough under 200k+ RPS bursts, the CQ ring will overflow, dropping I/O events or stalling subsequent submissions.
7. Frequently Asked Questions (FAQs)
Does io_uring completely eliminate Linux system calls during high web traffic?
Yes, when configured with Submission Queue Polling (IORING_SETUP_SQPOLL), io_uring achieves zero system calls during active request processing. A dedicated kernel polling thread continuously drains operations from the shared-memory Submission Queue, while completions are deposited directly into the Completion Queue. The userspace web daemon submits and reaps I/O solely by updating memory-mapped ring buffer pointers.
Can existing web servers like NGINX or Apache drop in io_uring without code changes?
No. Because io_uring requires an asynchronous completion paradigm rather than readiness notification, web servers must be engineered or patched to support it. NGINX has added experimental support for io_uring in its thread-pool disk caching layer (via aio io_uring;), but its primary HTTP connection multiplexing loop still relies on epoll. Modern runtimes like Rust Tokio (tokio-uring), Go (go-uring), and Netty provide native io_uring implementations that unlock its full capabilities.
What are the security implications of enabling io_uring on multi-tenant shared hosting?
Because io_uring exposes an expansive interface to internal kernel operations, several local privilege escalation vulnerabilities were discovered in early Linux 5.x kernels. In multi-tenant shared hosting environments, it is recommended to restrict unprivileged io_uring usage using sysctl -w kernel.io_uring_disabled=2 (disabled entirely) or sysctl -w kernel.io_uring_disabled=1 (restricted to processes with CAP_SYS_ADMIN or members of kernel.io_uring_group), while keeping the kernel updated to Linux 6.8+.
Why does epoll experience latency degradation at 100k+ concurrent connections?
At high concurrency, epoll suffers from three primary bottlenecks: 1) System call amplification, where each connection cycle requires separate epoll_wait, read, and write calls that trigger CPU context switches and Spectre/Meltdown mitigation overhead; 2) Lock contention within kernel red-black trees and ready-lists during dynamic connection churn; and 3) Lack of asynchronous disk I/O, forcing worker threads to block or context-switch to worker pools when serving static assets from disk.
Deploy Enterprise-Grade Production Infrastructure
Need guaranteed performance with zero price hikes? Host mission-critical workloads on MeraHost with pure Enterprise NVMe, LiteSpeed Web Server, and Same Renewal Price, Always (starting at ₹99/mo).