
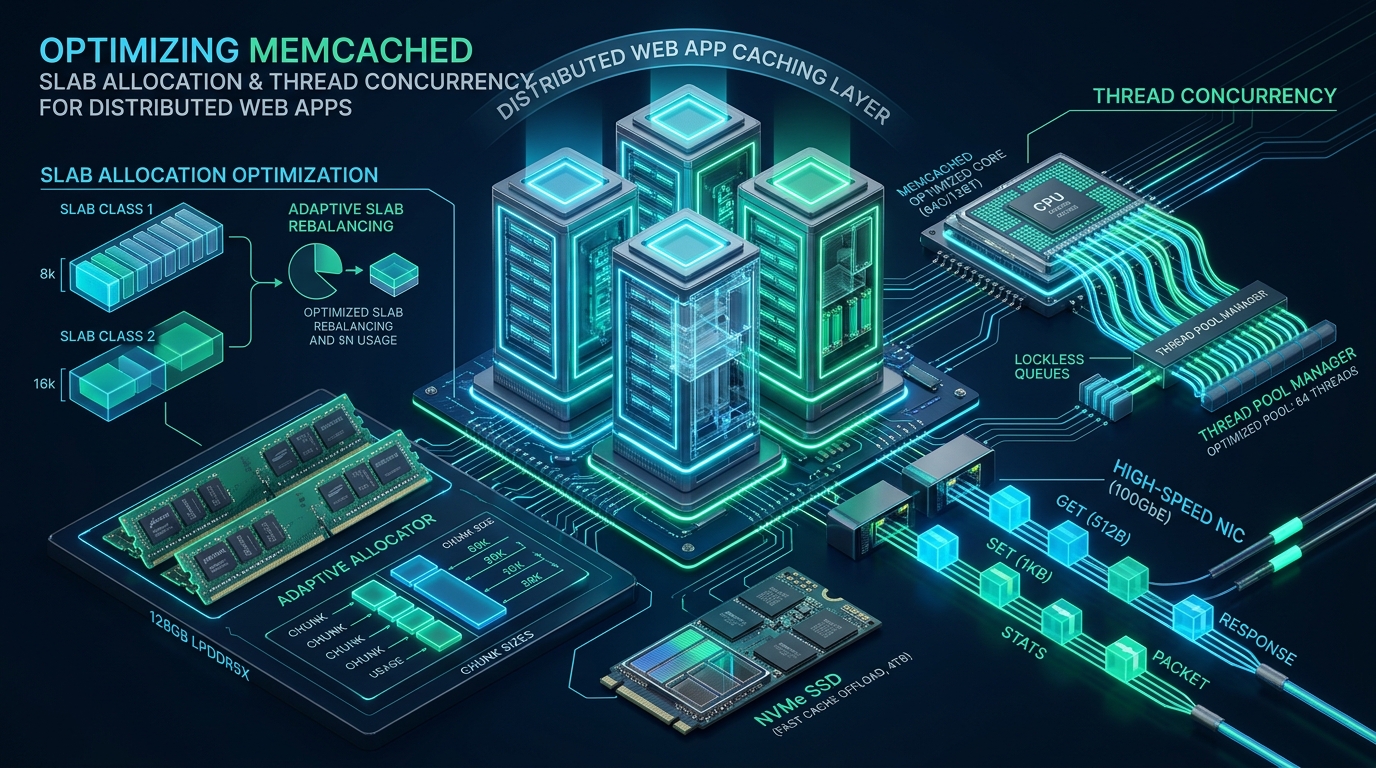
At hyper-scale traffic spikes, distributed web applications frequently experience catastrophic cache evictions and latency degradation not from overall RAM exhaustion, but from internal memory fragmentation and lock serialization. When Memcached’s slab allocator assigns fixed 1MB memory pages to rigid chunk classes, sub-optimal growth factors trigger premature evictions and cache churn while available memory lies idle in adjacent slab classes. High-throughput platforms hosted on modern cloud infrastructure like CpanelFree demand meticulous low-level kernel tuning, slab class rebalancing, and thread affinity optimization to sustain sub-millisecond retrieval under millions of concurrent operations.
Understanding Memcached Slab Allocation and Thread Concurrency
The Anatomy of the Memcached Slab Allocator
Unlike conventional runtime memory allocators like glibc’s malloc, which suffer from severe heap fragmentation when handling millions of short-lived, variable-sized objects, Memcached employs an internal slab memory management subsystem. Upon initialization, Memcached allocates a continuous contiguous memory pool (defined by the -m parameter). This arena is partitioned into 1MB memory blocks known as Pages.
Pages are assigned to specific Slab Classes, where each class is sliced into uniform slots called Chunks. When an item is stored via a SET or ADD command, Memcached computes the item’s total serialized footprint (key length + flags + expiration time + CAS token + payload bytes) and locates the smallest available chunk that can accommodate the data.
- Slab Class 1: Typically begins with chunks sized by
-n(default 48 bytes + 48-byte overhead = 96 bytes). A 1MB page yields approximately 10,922 chunks. - Slab Class 2: Scaled by the growth factor
-f(default 1.25). Chunk size equals 96 × 1.25 = 120 bytes. - Subsequent Classes: Each class increases chunk size by factor
-funtil reaching the maximum item limit (default 1MB, configurable via-I).
The Slab Calcification Bottleneck
In classical Memcached versions (< 1.4.11), page allocation was strictly one-way: once a 1MB page was assigned to Slab Class 12, it remained permanently anchored to Class 12. If application traffic shifted—for example, switching from caching compact 200-byte token strings to caching 4KB JSON document responses—Slab Class 28 would run out of pages and aggressively evict active, non-expired keys under heavy LRU pressure. Meanwhile, Slab Class 12 might hold hundreds of idle pages that were never recycled. This pathology is known in systems engineering as Slab Calcification.
Modern Memcached engines resolve this through the slab_reassign and slab_automove subsystems, which dynamically detect eviction imbalances and transfer underutilized 1MB pages from donor slab classes to starved receiver classes.
Comparative Benchmark: Default vs. Production-Tuned Architecture
The following benchmark comparison illustrates the measurable operational differences between an unoptimized default Memcached deployment and a fully tuned production instance under a simulated workload of 25,000 requests per second with mixed payload distributions (64 bytes to 16 KB).
Thread Concurrency Architecture and Mutex Serialization
Memcached utilizes a multi-threaded, event-driven network architecture built upon libevent. Understanding how connections and requests traverse the internal thread hierarchy is critical to eliminating latency spikes at scale.
- The Dispatcher Thread: Listens on the configured network socket (TCP port 11211). When a client establishes a connection, the dispatcher accepts the socket descriptor and assigns it round-robin to a worker thread via an internal pipe.
- Worker Threads (
-t): Each worker thread manages its assigned connections using an epoll event loop, reading client packets, parsing the ASCII or binary Memcached protocol, and executing cache reads and writes. - Locking Hierarchy: Early versions of Memcached utilized a single global cache lock (
cache_lock). Under high concurrency, worker threads spent the majority of their CPU cycles spinning on pthread mutexes. Modern Memcached implements Item Hash Table Locks and Slab Locks, distributing locking across multiple granular mutexes.
-t) higher than the physical CPU core count severely harms throughput. When thread count exceeds physical vCPUs, CPU core switching, cache line invalidation, and cross-thread mutex bouncing degrade throughput exponentially. A 16-core server performs best with -t 14 or -t 16, reserving 2 cores for network IRQs and kernel packet processing.NUMA Awareness and CPU Pinning
On dual-socket enterprise servers with Non-Uniform Memory Access (NUMA), a worker thread executing on Socket 0 attempting to read memory allocated on Socket 1 incurs an interconnect penalty across the Intel UPI or AMD Infinity Fabric. To eliminate memory bus latency, bind Memcached to a single NUMA node or pin worker threads directly using numactl or systemd CPU affinity masks.
Production Configuration Files
Below are battle-tested, enterprise-grade configuration files designed for high-concurrency Linux nodes running Memcached.
1. Production Memcached Configuration: /etc/memcached.conf
# /etc/memcached.conf - High-Performance Production Profile
# Service daemonization
-d

# Logging configuration
logfile /var/log/memcached.log
-v

# Memory Allocation (e.g. 16 GB dedicated cache pool)
-m 16384

# Default connection listening port and interface
-p 11211
-u memcache
-l 127.0.0.1,10.0.0.15

# Limit maximum simultaneous connections (scaled for web app pools)
-c 32768

# Worker threads (matched to dedicated CPU cores)
-t 16

# Slab Allocation Optimization:
# Minimum chunk size (allocate 80 bytes for key + header metadata)
-n 80

# Growth Factor: granular 1.09 step ratio to minimize slack space
-f 1.09

# Maximum item size (default 1m; increase only if caching large objects)
-I 2m

# Advanced Engine Tuning:
# - modern: enables modern automove algorithm
# - slab_reassign: dynamic 1MB page reallocation between slab classes
# - slab_automove=2: aggressive continuous rebalancing based on evictions
# - lru_crawler: background thread that clears expired items from RAM
# - lru_maintainer: split LRU (HOT, WARM, COLD queues)
# - maxconns_fast: immediate drop on connection pool saturation
-o modern,slab_reassign,slab_automove=2,lru_crawler,lru_maintainer,maxconns_fast
2. Linux Kernel Network & Memory Tuning: /etc/sysctl.d/99-memcached.conf
# /etc/sysctl.d/99-memcached.conf - Low-Latency Kernel Tuning
# Prevent swapping: Memcached must remain resident in physical RAM
vm.swappiness = 0
vm.overcommit_memory = 1

# Socket listen backlog queue depth for high connection bursts
net.core.somaxconn = 65535
net.ipv4.tcp_max_syn_backlog = 32768

# TCP socket memory and buffer tuning
net.core.rmem_default = 262144
net.core.wmem_default = 262144
net.core.rmem_max = 16777216
net.core.wmem_max = 16777216
net.ipv4.tcp_rmem = 4096 87380 16777216
net.ipv4.tcp_wmem = 4096 65536 16777216

# Rapid recycling of TIME_WAIT sockets under heavy connection churn
net.ipv4.tcp_tw_reuse = 1
net.ipv4.tcp_fin_timeout = 15

# Disable slow-start after idle to maintain high TCP window sizes
net.ipv4.tcp_slow_start_after_idle = 0

# Enable TCP BBR Congestion Control
net.core.default_qdisc = fq
net.ipv4.tcp_congestion_control = bbr
3. Systemd Service Hardening & Affinity: /etc/systemd/system/memcached.service.d/override.conf
# /etc/systemd/system/memcached.service.d/override.conf
[Service]
# Raise file descriptor limits to accommodate 32k concurrent sockets
LimitNOFILE=65536
LimitMEMLOCK=infinity

# CPU core affinity binding (pinning to Cores 0-15 on NUMA Node 0)
CPUAffinity=0-15

# Set elevated process scheduling priority
Nice=-10

# Memory locking to guarantee zero page faults into swap
Environment="MEMCACHED_PARAMS=-k"
Diagnostic Instrumentation: Inspecting Slabs and Evictions
Continuous telemetry is vital to verify that your growth factor matches live application payloads. The command-line utility memcached-tool provides direct visibility into slab allocation efficiency.
# Inspect live slab distribution and chunk utilization
memcached-tool 127.0.0.1:11211 display

# Query slab statistics directly via raw telnet/netcat socket
(echo "stats slabs"; sleep 1) | nc 127.0.0.1 11211 | grep -E '(chunk_size|used_chunks|free_chunks|total_pages)'

# Monitor eviction counters across all slab classes
(echo "stats items"; sleep 1) | nc 127.0.0.1 11211 | grep 'evicted'
memcached-tool display, pay strict attention to the Waste column. If a slab class shows Waste > 20%, your growth factor is too aggressive. Decrease -f (e.g. from 1.25 down to 1.09) to compress the delta between consecutive slab chunk dimensions.Step-by-Step Benchmarking with memtier_benchmark
Before deploying tuned configurations to production clusters, validate latency and throughput using Redis Labs’ memtier_benchmark:
# Install benchmark suite on Debian/Ubuntu
apt-get install -y memtier-benchmark

# Execute 100 concurrent clients over 16 threads with 1:9 SET:GET ratio
memtier_benchmark \
  --server=127.0.0.1 \
  --port=11211 \
  --protocol=memcache_text \
  --clients=100 \
  --threads=16 \
  --ratio=1:9 \
  --data-size-range=64-2048 \
  --data-size-pattern=S \
  --requests=100000 \
  --distinct-client-seed
During the benchmark run, monitor worker thread CPU saturation using htop. A well-tuned Memcached instance will exhibit balanced CPU core utilization across all assigned worker threads without any single thread locking at 100% kernel time (which indicates mutex contention).
Frequently Asked Questions
How do I calculate the optimal growth factor (-f) for my workload?
Log a sample of 100,000 serialized cache object sizes from your application layer. Plot their cumulative distribution frequency. If your object sizes cluster tightly between 200 and 800 bytes, use a lower growth factor like 1.08 or 1.10. This creates closely spaced slab classes (e.g., 200B, 218B, 237B, 258B) rather than large leaps, reducing internal slack space below 5%.
Why shouldn’t I allocate more worker threads (-t) than physical CPU cores?
Memcached worker threads synchronize state using granular mutex locks around item hash tables and slab allocators. When the number of threads exceeds physical execution pipelines, the Linux kernel scheduler is forced to perform preemptive context switching. This causes CPU cache lines to bounce between cores and leads to mutex convoying, which increases P99 retrieval latency by up to 300%.
What is the difference between slab_automove=1 and slab_automove=2?
slab_automove=1 is the legacy rebalancer that moves one page per second if a slab class has seen evictions for 3 consecutive intervals while another class has free pages. slab_automove=2 (modern automove) is a far more aggressive, intelligent algorithm that analyzes hit rates, eviction age ratios, and memory pressure across all classes, dynamically reallocating pages before evictions can cause application-facing cache misses.
When should I choose Memcached over Redis for distributed web caching?
Memcached’s multi-threaded architecture outperforms single-threaded Redis engines when caching simple, uniform key-value pairs across high core-count servers (32+ vCPUs) handling millions of requests per second. Redis is preferable when you need complex data structures (sets, sorted sets, hashes, streams), pub/sub messaging, or on-disk persistence. For pure high-throughput memory caching, a tuned Memcached instance provides unmatched raw compute efficiency.
Ready to Deploy High-Performance Infrastructure?
Experience blazing-fast NVMe storage, unmetered bandwidth, and enterprise LiteSpeed caching on CpanelFree.